 tzhouamandClaude Opus 5
a51461c131
`parallel_stage_init` was structurally impossible on a CPU deployment.
`resolve_stage_physical_devices` returns None for `devices: "cpu"`, and the
admission resolver fails closed on None -- correctly, for a GPU replica whose
devices cannot be accounted -- so every CPU pipeline raised
StageAdmissionError and fell back to sequential stage startup. The edge
profile sets parallel_stage_init: true, so that profile was broken on CPU
rather than merely slower.

Measured on Qwen3-TTS 0.6B (Xeon 8480C, 24 threads, init only):

    sequential   64.57 s
    parallel     30.54 s      2.1x

The fix is not to skip admission. The per-device ledger is vacuous on CPU --
there is no device to overcommit -- but the resource concurrent CPU init
contends for is host memory, and two stages allocating KV caches at once can
exhaust it exactly as two GPU stages exhaust a card. So there is now a host
ledger with the same discipline: sum the declared KV budgets, compare against
available RAM with a margin, refuse to start if it does not fit, and fail
closed on a stage that declares no budget at all. The arithmetic is pure
(`evaluate_host`) so it is testable without a device, matching the existing
design.

Which ledger applies is decided by where the stages are *placed*, not by what
platform the process reports: a first version keyed on
`current_platform.is_cpu()` and broke five existing GPU-path tests, because a
CPU-only test host still has to admit GPU-shaped plans correctly. It now
routes on the replicas' own `devices`.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Easy, fast, and cheap omni-modality model serving for everyone
| Documentation | DeepWiki | User Forum | Developer Slack | WeChat | Paper | Slides |

Latest News 🔥
- [2026/08] We released 0.28.0, featuring production-ready MiniMax H3 serving on GPU and NPU, a unified AR/DiT paged KV cache runtime, and enhanced realtime full-duplex serving for the MiniCPM-o series.
- [2026/08] VeRL-Omni
v0.2.0is released: faster diffusion RL powered by vLLM-Omni (request-level/step-wise batching with FA3), rebuilt Qwen3-Omni multimodal training (DPO & GSPO), plus LTX-2.3, Qwen-Image-Edit support and more. See the release notes. - [2026/08] We released 0.26.0 - aligned with the vLLM 0.26 release line, featuring MiniMax H3 joint video/audio generation, an experimental full-duplex realtime runtime for MiniCPM-o 4.5, distributed layerwise diffusion offload, and broader model, hardware, streaming, TTS, and quantization support.
- [2026/07] We released 0.24.0 - aligned with the vLLM 0.24 release line, expanding production-ready coverage across TTS, speech, diffusion, image/video generation, and robot-policy serving, with major Omni stage runtime refactoring, diffusion request-level batching, async output materialization, quantization/cache/memory improvements, and broad CUDA/ROCm/XPU/NPU support.
- [2026/06] Starting with 0.14.0, vLLM-Omni publishes a stable release aligned with every even-numbered upstream vLLM minor version. 0.16.0, 0.18.0, 0.20.0, and 0.22.0 continued this cadence, expanding omni and world-model support with NVIDIA Cosmos3 and DreamZero, adding models such as MiniCPM-o 4.5, MOSS-TTS, and Lance, and advancing TTS, diffusion, distributed execution, quantization, RL integration through VeRL-Omni, and CUDA/ROCm/MUSA/NPU/XPU coverage.
- [2026/03] Check out our first public project deepdive at the vLLM Hong Kong Meetup!
- [2025/11] vLLM community officially released vllm-project/vllm-omni in order to support omni-modality models serving.
About
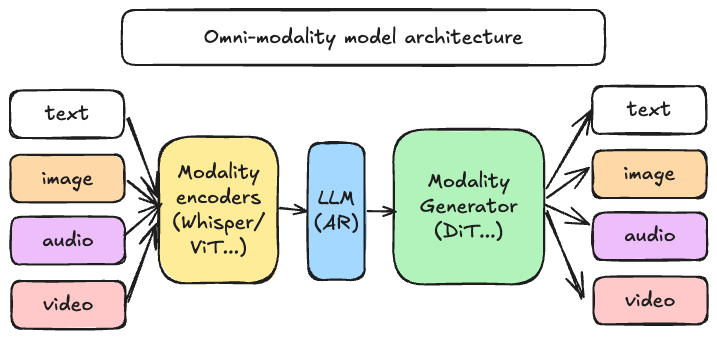
vLLM was originally designed to support large language models for text-based autoregressive generation tasks. vLLM-Omni is a framework that extends its support for omni-modality model inference and serving:
- Omni-modality: Text, image, audio, video, and action data processing
- Non-autoregressive Architectures: extend the AR support of vLLM to Diffusion Transformers (DiT) and other parallel generation models
- Heterogeneous outputs: from traditional text generation to multimodal and action outputs
vLLM-Omni is fast with:
- State-of-the-art AR support by leveraging efficient KV cache management from vLLM
- Pipelined stage execution overlapping for high throughput performance
- Fully disaggregation based on OmniConnector and dynamic resource allocation across stages
vLLM-Omni is flexible and easy to use with:
- Heterogeneous pipeline abstraction to manage complex model workflows
- Seamless integration with popular Hugging Face models
- Tensor, pipeline, data and expert parallelism support for distributed inference
- Streaming outputs
- OpenAI-compatible API server
- Full-duplex realtime serving with streaming audio input and output
vLLM-Omni seamlessly supports most popular open-source models on HuggingFace, including:
- Omni-modality models (e.g. Qwen3-Omni, MiniCPM-o 4.5, Cosmos3, HunyuanImage, BAGEL)
- TTS models (e.g. Qwen3-TTS, IndexTTS 2.5, dots.tts, CosyVoice3)
- Diffusion models — image, video, and audio generation (e.g. MiniMax H3, LTX-2.5, SANA-Video, Wan2.2)
- Robot-policy and action models (e.g. π0, GR00T-N1.7, DreamZero-DROID, InternVLA-A1)
Getting Started
Visit our documentation to learn more.
- Installation
- Quickstart
- Nightly CUDA Docker images built from the latest
main - List of Supported Models
- Deployment Recipes for vLLM-Omni model serving
Contributing
We welcome and value any contributions and collaborations. Please check out Contributing to vLLM-Omni for how to get involved.
Citation
If you use vLLM-Omni for your research, please cite our paper:
@article{yin2026vllmomni,
  title={vLLM-Omni: Fully Disaggregated Serving for Any-to-Any Multimodal Models},
  author={Peiqi Yin, Jiangyun Zhu, Han Gao, Chenguang Zheng, Yongxiang Huang, Taichang Zhou, Ruirui Yang, Weizhi Liu, Weiqing Chen, Canlin Guo, Didan Deng, Zifeng Mo, Cong Wang, James Cheng, Roger Wang, Hongsheng Liu},
  journal={arXiv preprint arXiv:2602.02204},
  year={2026}
}
Join the Community
Feel free to ask questions, provide feedbacks and discuss with fellow users of vLLM-Omni in #sig-omni slack channel at slack.vllm.ai or vLLM user forum at discuss.vllm.ai.
Star History
License
Apache License 2.0, as found in the LICENSE file.