 lishunyang12
a326cd0d57
After merging main into ``lance-model-support`` (commit c15f51a2),
Bagel's internal API was aggressively trimmed: ``forward_cache_update_text``,
``forward_cache_update_vit``, ``generate_image``, ``generate_text``, and
``Qwen2MoTForCausalLM.forward`` no longer accept ``packed_text_indexes`` /
``packed_key_value_indexes`` / ``key_values_lens`` / ``packed_query_indexes``
— they're now derived from ``past_key_values``.  Lance's pipeline was
still passing those kwargs and crashed on every task.

Changes:

- ``vllm_omni/deploy/lance.yaml`` (restored): Lance's HF ``config.json``
  is descriptive metadata with no ``model_type`` field, so the loader
  can't auto-detect the pipeline.  This YAML is the minimal hook that
  tells the loader "use the Lance pipeline" — one stage, no multi-stage
  orchestration.
- ``examples/offline_inference/lance/gradio_demo.py``: pass
  ``deploy_config`` again so ``Omni`` picks up the YAML.
- ``vllm_omni/diffusion/models/bagel/bagel_transformer.py``: in the
  batched CFG setup, concat ``branches_pid`` along ``dim=-1`` (the
  sequence axis) instead of the default ``dim=0`` so Lance's 3-D mRoPE
  position ids ``(3, S)`` aren't collapsed into ``(6, S)`` —
  ``BagelRotaryEmbedding`` enforces exactly 3 axes for mRoPE.
- ``vllm_omni/diffusion/models/bagel/pipeline_bagel.py``: mirror the
  generated PIL image into ``custom_output["image"]`` so callers reading
  through the orchestrator IPC boundary (which strips the bare
  ``output`` field) can still recover it.  ``video_frames`` already used
  this pattern.
- ``vllm_omni/diffusion/models/lance/lance_transformer.py``: drop
  ``packed_query_indexes`` / ``key_values_lens`` /
  ``packed_key_value_indexes`` from the ``language_model.forward`` call
  inside ``forward_cache_update_vae`` — derived now.
- ``vllm_omni/diffusion/models/lance/pipeline_lance.py``:
    * drop the same 3 fields from the inline ``inp`` dicts that build
      ``forward_cache_update_text`` arguments in ``_forward_image_edit``,
      ``_forward_i2v``, ``_forward_video_edit``, and
      ``_x2t_raw_text_prefill``.
    * drop the 6 ``cfg_text_packed_query_indexes`` /
      ``cfg_text_key_values_lens`` / ``cfg_text_packed_key_value_indexes``
      (+ ``cfg_img_*`` triple) kwargs from the four ``generate_image``
      call sites.
    * filter ``key_values_lens`` / ``packed_indexes`` /
      ``packed_key_value_indexes`` out of the ``gen_input_lat`` /
      ``gen_input_vit`` dicts before unpacking into ``generate_image``
      and ``forward_cache_update_vit`` (the ``prepare_*_latent`` /
      ``prepare_vit_*`` helpers still return them for the
      backwards-compatible parent-class path).
    * drop ``key_values_lens`` / ``packed_key_value_indexes`` from
      ``_x2t_prepare_assistant_start``'s returned dict so
      ``Bagel.generate_text`` doesn't reject them.

Verification (local online inference, single GPU pair, CFG=4, 10 steps):

| Task          | Status                                          |
|---------------|-------------------------------------------------|
| t2i           | OK  (~2 s)                                      |
| image_edit    | OK  (~2.5 s)                                    |
| i2v           | OK  (~8 s @ 25 frames)                          |
| t2v           | OK  (~7 s @ 25 frames)                          |
| video_edit    | OK  (~60 s)                                     |
| x2t_image     | RUNS but generates degenerate token repetition  |
| x2t_video     | RUNS but generates degenerate token repetition  |

x2t degeneration is a deeper semantic mismatch with main's new
``past_key_values``-derived cache layout: Lance's x2t prefill stitches
the chat template across multiple ``forward_cache_update_*`` calls
(system → ViT → question → ``assistant\\n``), but the new API expects a
single contiguous KV layout.  Fixing requires reworking the segmented
prefill to match main's new cache contract — left as a follow-up since
the 5 generative tasks now work.

Signed-off-by: lishunyang12 <lishunyang12@163.com>
Easy, fast, and cheap omni-modality model serving for everyone
| Documentation | DeepWiki | User Forum | Developer Slack | WeChat | Paper | Slides |

Latest News 🔥
- [2026/05] We released 0.20.0 - refreshes the serving/runtime stack for large-scale omni workloads, and improves diffusion model performance, quantization, and hardware readiness across CUDA, ROCm, MUSA, NPU, and XPU backends.
- [2026/03] We released 0.18.0 - strengthens the core runtime through a large entrypoint refactor and scheduler/runtime cleanups, expands unified quantization and diffusion execution, broadens multimodal model coverage, and improves production readiness across audio, omni, image, video, RL, and multi-platform deployments.
- [2026/03] Check out our first public project deepdive at the vLLM Hong Kong Meetup!
- [2026/03] vllm-omni-skills is a community-driven collection of AI assistant skills that help developers work with vLLM-Omni more effectively. These skills can be used with popular agentic AI coding assistants like Cursor IDE, Claude, Codex, and more.
- [2026/02] We released 0.16.0 - A major alignment + capability release that rebases onto upstream vLLM v0.16.0 and significantly expands performance, distributed execution, and production readiness across Qwen3-Omni / Qwen3-TTS, Bagel, MiMo-Audio, GLM-Image and the Diffusion (DiT) image/video stack—while also improving platform coverage (CUDA / ROCm / NPU / XPU), CI quality, and documentation.
- [2026/02] We released 0.14.0 - This is the first stable release of vLLM-Omni that expands Omni’s diffusion / image-video generation and audio / TTS stack, improves distributed execution and memory efficiency, and broadens platform/backend coverage (GPU/ROCm/NPU/XPU). It also brings meaningful upgrades to serving APIs, profiling & benchmarking, and overall stability. Please check our latest paper for architecture design and performance results.
- [2025/11] vLLM community officially released vllm-project/vllm-omni in order to support omni-modality models serving.
About
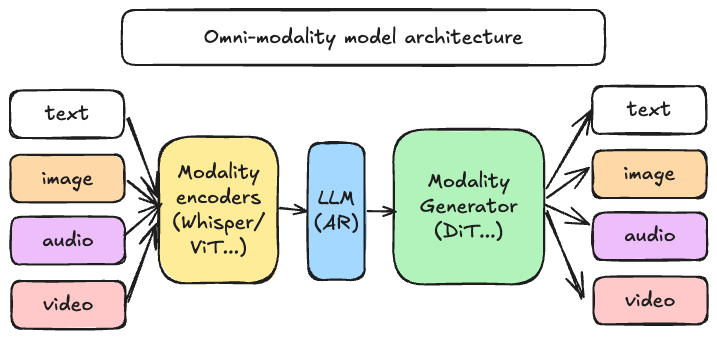
vLLM was originally designed to support large language models for text-based autoregressive generation tasks. vLLM-Omni is a framework that extends its support for omni-modality model inference and serving:
- Omni-modality: Text, image, video, and audio data processing
- Non-autoregressive Architectures: extend the AR support of vLLM to Diffusion Transformers (DiT) and other parallel generation models
- Heterogeneous outputs: from traditional text generation to multimodal outputs
vLLM-Omni is fast with:
- State-of-the-art AR support by leveraging efficient KV cache management from vLLM
- Pipelined stage execution overlapping for high throughput performance
- Fully disaggregation based on OmniConnector and dynamic resource allocation across stages
vLLM-Omni is flexible and easy to use with:
- Heterogeneous pipeline abstraction to manage complex model workflows
- Seamless integration with popular Hugging Face models
- Tensor, pipeline, data and expert parallelism support for distributed inference
- Streaming outputs
- OpenAI-compatible API server
vLLM-Omni seamlessly supports most popular open-source models on HuggingFace, including:
- Omni-modality models (e.g. Qwen-Omni)
- Multi-modality generation models (e.g. Qwen-Image)
Getting Started
Visit our documentation to learn more.
Contributing
We welcome and value any contributions and collaborations. Please check out Contributing to vLLM-Omni for how to get involved.
Citation
If you use vLLM-Omni for your research, please cite our paper:
@article{yin2026vllmomni,
  title={vLLM-Omni: Fully Disaggregated Serving for Any-to-Any Multimodal Models},
  author={Peiqi Yin, Jiangyun Zhu, Han Gao, Chenguang Zheng, Yongxiang Huang, Taichang Zhou, Ruirui Yang, Weizhi Liu, Weiqing Chen, Canlin Guo, Didan Deng, Zifeng Mo, Cong Wang, James Cheng, Roger Wang, Hongsheng Liu},
  journal={arXiv preprint arXiv:2602.02204},
  year={2026}
}
Join the Community
Feel free to ask questions, provide feedbacks and discuss with fellow users of vLLM-Omni in #sig-omni slack channel at slack.vllm.ai or vLLM user forum at discuss.vllm.ai.
Star History
License
Apache License 2.0, as found in the LICENSE file.