 776c3a794e
Signed-off-by: JaredforReal <w13431838023@gmail.com>
Signed-off-by: root <root@hk01dgx039.cm.cluster>
Signed-off-by: tzhouam <tzhouam@connect.ust.hk>
Signed-off-by: Taichang Zhou <tzhouam@connect.ust.hk>
Signed-off-by: TangPeng <85704592@qq.com>
Signed-off-by: XU Mingshi <91017482+mxuax@users.noreply.github.com>
Signed-off-by: mxuax <mxuax@connect.ust.hk>
Signed-off-by: Sihyeon Jang <sihyeon.jang@navercorp.com>
Signed-off-by: zjy0516 <riverclouds.zhu@qq.com>
Signed-off-by: iwzbi <wzbi@zju.edu.cn>
Signed-off-by: ZeldaHuang <hzm414167@alibaba-inc.com>
Signed-off-by: Yuhan Liu <30294295+liuyuhanalex@users.noreply.github.com>
Signed-off-by: Alicia <115451386+congw729@users.noreply.github.com>
Signed-off-by: samithuang <285365963@qq.com>
Signed-off-by: linyueqian <linyueqian@outlook.com>
Signed-off-by: David Chen <530634352@qq.com>
Signed-off-by: yinpeiqi <yinpeiqi809@gmail.com>
Signed-off-by: Didan Deng <33117903+wtomin@users.noreply.github.com>
Signed-off-by: Hongsheng Liu <liuhongsheng4@huawei.com>
Signed-off-by: wangyu31577 <wangyu31577@hundsun.com>
Signed-off-by: princepride <wangzhipeng628@gmail.com>
Signed-off-by: John Liu BUAA <liukecheng97@gmail.com>
Signed-off-by: Dinesh G <G.Dinesh@ibm.com>
Signed-off-by: gDINESH13 <dinesh13g@gmail.com>
Signed-off-by: root <root@hk01dgx028.cm.cluster>
Signed-off-by: Zhou Taichang <tzhouam@connect.ust.hk>
Co-authored-by: JaredforReal <w13431838023@gmail.com>
Co-authored-by: root <root@hk01dgx039.cm.cluster>
Co-authored-by: JustQJ <37905360+JustQJ@users.noreply.github.com>
Co-authored-by: XU Mingshi <91017482+mxuax@users.noreply.github.com>
Co-authored-by: Sihyeon Jang <uneedsihyeon@gmail.com>
Co-authored-by: Jiangyun Zhu <riverclouds.zhu@qq.com>
Co-authored-by: catcat <108673086+iwzbi@users.noreply.github.com>
Co-authored-by: Ziming Huang <hzm414167@alibaba-inc.com>
Co-authored-by: Yuhan Liu <30294295+liuyuhanalex@users.noreply.github.com>
Co-authored-by: Alicia <115451386+congw729@users.noreply.github.com>
Co-authored-by: Samit <285365963@qq.com>
Co-authored-by: Yueqian Lin <70319226+linyueqian@users.noreply.github.com>
Co-authored-by: WeiQing Chen <40507679+david6666666@users.noreply.github.com>
Co-authored-by: Peiqi Yin <60515999+yinpeiqi@users.noreply.github.com>
Co-authored-by: Didan Deng <33117903+wtomin@users.noreply.github.com>
Co-authored-by: Hongsheng Liu <liuhongsheng4@huawei.com>
Co-authored-by: wangyu <53896905+yenuo26@users.noreply.github.com>
Co-authored-by: wangyu31577 <wangyu31577@hundsun.com>
Co-authored-by: 汪志鹏 <wangzhipeng628@gmail.com>
Co-authored-by: John Liu BUAA <liukecheng97@gmail.com>
Co-authored-by: D!NE$H <67671800+gDINESH13@users.noreply.github.com>
Co-authored-by: root <root@hk01dgx028.cm.cluster>
Easy, fast, and cheap omni-modality model serving for everyone
| Documentation | User Forum | Developer Slack | WeChat |

Latest News 🔥
- [2026/01] We released 0.14.0rc1.
- [2026/01] We released 0.12.0rc1 - a major RC milestone focused on maturing the diffusion stack, strengthening OpenAI-compatible serving, expanding omni-model coverage, and improving stability across platforms (GPU/NPU/ROCm), please check our latest design.
- [2025/11] vLLM community officially released vllm-project/vllm-omni in order to support omni-modality models serving.
About
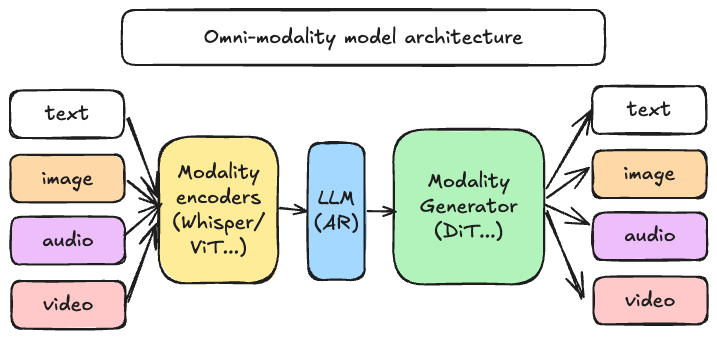
vLLM was originally designed to support large language models for text-based autoregressive generation tasks. vLLM-Omni is a framework that extends its support for omni-modality model inference and serving:
- Omni-modality: Text, image, video, and audio data processing
- Non-autoregressive Architectures: extend the AR support of vLLM to Diffusion Transformers (DiT) and other parallel generation models
- Heterogeneous outputs: from traditional text generation to multimodal outputs
vLLM-Omni is fast with:
- State-of-the-art AR support by leveraging efficient KV cache management from vLLM
- Pipelined stage execution overlapping for high throughput performance
- Fully disaggregation based on OmniConnector and dynamic resource allocation across stages
vLLM-Omni is flexible and easy to use with:
- Heterogeneous pipeline abstraction to manage complex model workflows
- Seamless integration with popular Hugging Face models
- Tensor, pipeline, data and expert parallelism support for distributed inference
- Streaming outputs
- OpenAI-compatible API server
vLLM-Omni seamlessly supports most popular open-source models on HuggingFace, including:
- Omni-modality models (e.g. Qwen-Omni)
- Multi-modality generation models (e.g. Qwen-Image)
Getting Started
Visit our documentation to learn more.
Contributing
We welcome and value any contributions and collaborations. Please check out Contributing to vLLM-Omni for how to get involved.
Join the Community
Feel free to ask questions, provide feedbacks and discuss with fellow users of vLLM-Omni in #sig-omni slack channel at slack.vllm.ai or vLLM user forum at discuss.vllm.ai.
Star History
License
Apache License 2.0, as found in the LICENSE file.