 tzhouamandClaude Opus 5
3dac97e0bd
Four changes, each measured on a Xeon 8480C with Spark-X2.5-1.7B at 24
threads. Numbers are best-of-interleaved-passes; this host is shared and a
single sequential grid swung the llama.cpp control 30%, so anything under
~8% is not treated as a result.

**vLLM's CPU backend does have a 4-bit kernel.** An earlier note in this
tree said it did not, on the strength of `woq_int4_linear`,
`int4_scaled_mm_with_quant` and `da8w4_linear` all being absent. Those are
simply not the names it uses: `CPUWNA16LinearKernel` dispatches GPTQ/AWQ
checkpoints to `int4_scaled_mm_cpu`, an AMX W4A8 GEMM, whenever activations
are bf16 and the checkpoint carries no act-order. Four-bit weights times
eight-bit activations is the arithmetic llama.cpp's Q4_K_M already does.
`gptq_cpu_export` builds checkpoints for it; the kernel pins the zero point
at 8, so the grid must be symmetric, and a per-group scale search recovers
most of what that costs.

**A per-device weight path** (`edge/weight_path.py`). The fast kernel on each
device needs a different, mutually exclusive weight layout, so the choice has
to come from a probe rather than a flag: AMX x86 -> W4A8/GPTQ; x86 without
AMX, or priority="fidelity" -> W4A16/tinygemm (bf16 activations, the more
faithful of the two); ARM -> W4A16 but flagged unverified, because PyTorch's
4-bit CPU GEMM dispatches a different kernel there than the AVX-512 one
measured here; phone -> runs_in_vllm=False, the deliverable is an exported
graph with calibrated w8a16.

**The CPU compile cache never loaded.** `_try_load_aot_compiled_fn` finishes
with `compiled_fn.finalize_loading(cfg)`, which the CUDA wrapper object has
and the inductor CPU backend's plain function does not. The AttributeError
was swallowed as a cache miss, so every engine start recompiled the model:
warm start 49.8 s against 14.9 s with the missing no-op attached. Self-
disabling if upstream gives the CPU path a real one.

**The head gate stops being a GEMM.** A 2048x8 projection cannot amortize a
thread fan-out: dispatched as `aten::mm` it costs 1.155 ms of a decode step,
nearly all barrier. As an eager reduction behind an opaque op it costs 0.444
ms. It has to be opaque -- written inline the reduction is traced, and
inductor's loop made the whole step 1.8x slower (78.8 -> 44.5 tok/s).

Also included and *off by default*: `cpu_ir_ops` registers the fused
`_C::rms_norm` / `_C::fused_add_rms_norm` kernels that vLLM's CPU build ships
but gates on `GPGPU_DEVICE`. In isolation they are 3.6x and 4.5x faster than
the native path; end to end they are slightly slower (72.7 vs 74.0 tok/s),
because inductor was already fusing the native norm into its neighbours and
an opaque call breaks that fusion. Kept with the measurement recorded so the
next person does not repeat it. `gelu_and_mul` is deliberately not registered:
its fused CPU kernel is 2.7x slower at Spark's GEGLU shape.

Decode, W4A16 g64 -> W4A8 g128 with the gate fix: 69.1 -> 84.5 tok/s (+22%),
against llama.cpp Q4_K_M's 90.0; prefill 3347 against 1121 (3.0x). The two
4-bit paths are not equally faithful: against each build's own bf16 over 12
greedy prompts, Q4_K_M reproduces 4/12, W4A16 2/12 and W4A8 1/12.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Easy, fast, and cheap omni-modality model serving for everyone
| Documentation | DeepWiki | User Forum | Developer Slack | WeChat | Paper | Slides |

Latest News 🔥
- [2026/08] We released 0.28.0, featuring production-ready MiniMax H3 serving on GPU and NPU, a unified AR/DiT paged KV cache runtime, and enhanced realtime full-duplex serving for the MiniCPM-o series.
- [2026/08] VeRL-Omni
v0.2.0is released: faster diffusion RL powered by vLLM-Omni (request-level/step-wise batching with FA3), rebuilt Qwen3-Omni multimodal training (DPO & GSPO), plus LTX-2.3, Qwen-Image-Edit support and more. See the release notes. - [2026/08] We released 0.26.0 - aligned with the vLLM 0.26 release line, featuring MiniMax H3 joint video/audio generation, an experimental full-duplex realtime runtime for MiniCPM-o 4.5, distributed layerwise diffusion offload, and broader model, hardware, streaming, TTS, and quantization support.
- [2026/07] We released 0.24.0 - aligned with the vLLM 0.24 release line, expanding production-ready coverage across TTS, speech, diffusion, image/video generation, and robot-policy serving, with major Omni stage runtime refactoring, diffusion request-level batching, async output materialization, quantization/cache/memory improvements, and broad CUDA/ROCm/XPU/NPU support.
- [2026/06] Starting with 0.14.0, vLLM-Omni publishes a stable release aligned with every even-numbered upstream vLLM minor version. 0.16.0, 0.18.0, 0.20.0, and 0.22.0 continued this cadence, expanding omni and world-model support with NVIDIA Cosmos3 and DreamZero, adding models such as MiniCPM-o 4.5, MOSS-TTS, and Lance, and advancing TTS, diffusion, distributed execution, quantization, RL integration through VeRL-Omni, and CUDA/ROCm/MUSA/NPU/XPU coverage.
- [2026/03] Check out our first public project deepdive at the vLLM Hong Kong Meetup!
- [2025/11] vLLM community officially released vllm-project/vllm-omni in order to support omni-modality models serving.
About
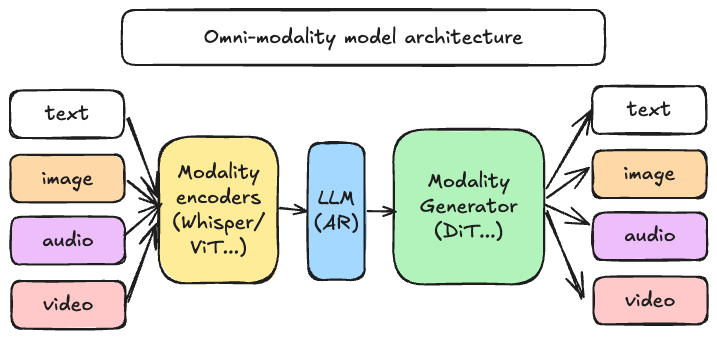
vLLM was originally designed to support large language models for text-based autoregressive generation tasks. vLLM-Omni is a framework that extends its support for omni-modality model inference and serving:
- Omni-modality: Text, image, audio, video, and action data processing
- Non-autoregressive Architectures: extend the AR support of vLLM to Diffusion Transformers (DiT) and other parallel generation models
- Heterogeneous outputs: from traditional text generation to multimodal and action outputs
vLLM-Omni is fast with:
- State-of-the-art AR support by leveraging efficient KV cache management from vLLM
- Pipelined stage execution overlapping for high throughput performance
- Fully disaggregation based on OmniConnector and dynamic resource allocation across stages
vLLM-Omni is flexible and easy to use with:
- Heterogeneous pipeline abstraction to manage complex model workflows
- Seamless integration with popular Hugging Face models
- Tensor, pipeline, data and expert parallelism support for distributed inference
- Streaming outputs
- OpenAI-compatible API server
- Full-duplex realtime serving with streaming audio input and output
vLLM-Omni seamlessly supports most popular open-source models on HuggingFace, including:
- Omni-modality models (e.g. Qwen3-Omni, MiniCPM-o 4.5, Cosmos3, HunyuanImage, BAGEL)
- TTS models (e.g. Qwen3-TTS, IndexTTS 2.5, dots.tts, CosyVoice3)
- Diffusion models — image, video, and audio generation (e.g. MiniMax H3, LTX-2.5, SANA-Video, Wan2.2)
- Robot-policy and action models (e.g. π0, GR00T-N1.7, DreamZero-DROID, InternVLA-A1)
Getting Started
Visit our documentation to learn more.
- Installation
- Quickstart
- Nightly CUDA Docker images built from the latest
main - List of Supported Models
- Deployment Recipes for vLLM-Omni model serving
Contributing
We welcome and value any contributions and collaborations. Please check out Contributing to vLLM-Omni for how to get involved.
Citation
If you use vLLM-Omni for your research, please cite our paper:
@article{yin2026vllmomni,
  title={vLLM-Omni: Fully Disaggregated Serving for Any-to-Any Multimodal Models},
  author={Peiqi Yin, Jiangyun Zhu, Han Gao, Chenguang Zheng, Yongxiang Huang, Taichang Zhou, Ruirui Yang, Weizhi Liu, Weiqing Chen, Canlin Guo, Didan Deng, Zifeng Mo, Cong Wang, James Cheng, Roger Wang, Hongsheng Liu},
  journal={arXiv preprint arXiv:2602.02204},
  year={2026}
}
Join the Community
Feel free to ask questions, provide feedbacks and discuss with fellow users of vLLM-Omni in #sig-omni slack channel at slack.vllm.ai or vLLM user forum at discuss.vllm.ai.
Star History
License
Apache License 2.0, as found in the LICENSE file.