 tzhouamandClaude Opus 5
27b9400750
An independent review (gpt-6-astra via the Codex hook) found that two modules
still ship claims this study had already withdrawn or that the vLLM source
contradicts. Documentation in executable files is how a retracted number gets
quoted again, so these are corrected at the source:

kv_budget.py claimed right-sizing the cache saved 8329 -> 5254 MB. That was
read from VmRSS (which counts the mmap'd checkpoint and moved 1-2 GB between
identical runs) and the two arms were different model files. On RssAnon the
saving is 188 MB. The retraction is now stated in the docstring, together with
why the number is small -- the benchmark generated 8 tokens, so no cache was
filled -- and the 1323 MiB flat-vs-hybrid difference at 32k that makes this
worth re-measuring on a benchmark that does fill it.

weight_path.py:
- bits_per_weight 4.16 -> 4.25 in all three 4-bit paths. 4 bits plus a bf16
  scale and zero per 128-weight group is 4 + 32/128; 4.16 matched no
  arithmetic and made the llama.cpp fidelity comparison look budget-matched
  when it is not (Q4_K is 4.5 bits over groups of 32, Q4_K_M promotes some
  tensors further).
- fused_cpu_norms True -> False in all three. Fused CPU RMSNorm is 3.6-4.5x
  faster in isolation and slower in situ; VLLM_OMNI_CPU_FUSED_NORMS already
  defaults to "0" for that reason, so the metadata contradicted the default.
- "tinygemm is the only option without AMX" is false: vLLM 0.28 selects
  ops.cpu_gemm_wna16 whenever use_w4a8 is off (mixed_precision/cpu.py:202).
  Unmeasured here, so the selector is unchanged, but the claim is not.
- W4A8's symmetric grid is our exporter's "sym": true, not a kernel limit --
  _process_gptq_weights_w4a8 uses checkpoint zero points when
  config.zero_points is set (same file, :98). An asymmetric export is a config
  change and the cheapest untried fidelity experiment.
- kv_budget's flat-accounting observation is flagged for re-checking, since
  CpuPlatform.support_hybrid_kv_cache() returns True (platforms/cpu.py:545).

Both fields now carry docstrings saying what they mean, so they cannot drift
back silently. tests/edge: 18 passed.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>

Easy, fast, and cheap omni-modality model serving for everyone
| Documentation | DeepWiki | User Forum | Developer Slack | WeChat | Paper | Slides |

Latest News 🔥
- [2026/08] We released 0.28.0, featuring production-ready MiniMax H3 serving on GPU and NPU, a unified AR/DiT paged KV cache runtime, and enhanced realtime full-duplex serving for the MiniCPM-o series.
- [2026/08] VeRL-Omni
v0.2.0is released: faster diffusion RL powered by vLLM-Omni (request-level/step-wise batching with FA3), rebuilt Qwen3-Omni multimodal training (DPO & GSPO), plus LTX-2.3, Qwen-Image-Edit support and more. See the release notes. - [2026/08] We released 0.26.0 - aligned with the vLLM 0.26 release line, featuring MiniMax H3 joint video/audio generation, an experimental full-duplex realtime runtime for MiniCPM-o 4.5, distributed layerwise diffusion offload, and broader model, hardware, streaming, TTS, and quantization support.
- [2026/07] We released 0.24.0 - aligned with the vLLM 0.24 release line, expanding production-ready coverage across TTS, speech, diffusion, image/video generation, and robot-policy serving, with major Omni stage runtime refactoring, diffusion request-level batching, async output materialization, quantization/cache/memory improvements, and broad CUDA/ROCm/XPU/NPU support.
- [2026/06] Starting with 0.14.0, vLLM-Omni publishes a stable release aligned with every even-numbered upstream vLLM minor version. 0.16.0, 0.18.0, 0.20.0, and 0.22.0 continued this cadence, expanding omni and world-model support with NVIDIA Cosmos3 and DreamZero, adding models such as MiniCPM-o 4.5, MOSS-TTS, and Lance, and advancing TTS, diffusion, distributed execution, quantization, RL integration through VeRL-Omni, and CUDA/ROCm/MUSA/NPU/XPU coverage.
- [2026/03] Check out our first public project deepdive at the vLLM Hong Kong Meetup!
- [2025/11] vLLM community officially released vllm-project/vllm-omni in order to support omni-modality models serving.
About
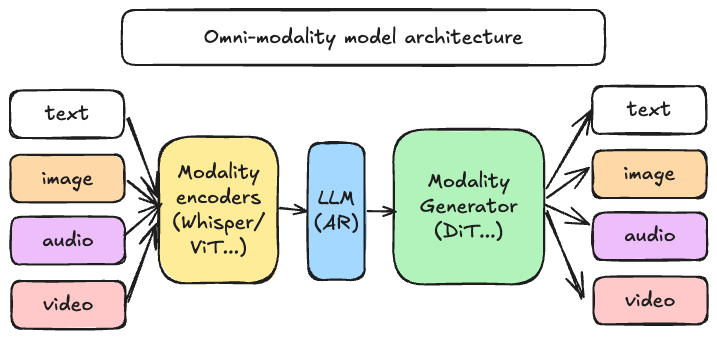
vLLM was originally designed to support large language models for text-based autoregressive generation tasks. vLLM-Omni is a framework that extends its support for omni-modality model inference and serving:
- Omni-modality: Text, image, audio, video, and action data processing
- Non-autoregressive Architectures: extend the AR support of vLLM to Diffusion Transformers (DiT) and other parallel generation models
- Heterogeneous outputs: from traditional text generation to multimodal and action outputs
vLLM-Omni is fast with:
- State-of-the-art AR support by leveraging efficient KV cache management from vLLM
- Pipelined stage execution overlapping for high throughput performance
- Fully disaggregation based on OmniConnector and dynamic resource allocation across stages
vLLM-Omni is flexible and easy to use with:
- Heterogeneous pipeline abstraction to manage complex model workflows
- Seamless integration with popular Hugging Face models
- Tensor, pipeline, data and expert parallelism support for distributed inference
- Streaming outputs
- OpenAI-compatible API server
- Full-duplex realtime serving with streaming audio input and output
vLLM-Omni seamlessly supports most popular open-source models on HuggingFace, including:
- Omni-modality models (e.g. Qwen3-Omni, MiniCPM-o 4.5, Cosmos3, HunyuanImage, BAGEL)
- TTS models (e.g. Qwen3-TTS, IndexTTS 2.5, dots.tts, CosyVoice3)
- Diffusion models — image, video, and audio generation (e.g. MiniMax H3, LTX-2.5, SANA-Video, Wan2.2)
- Robot-policy and action models (e.g. π0, GR00T-N1.7, DreamZero-DROID, InternVLA-A1)
Getting Started
Visit our documentation to learn more.
- Installation
- Quickstart
- Nightly CUDA Docker images built from the latest
main - List of Supported Models
- Deployment Recipes for vLLM-Omni model serving
Contributing
We welcome and value any contributions and collaborations. Please check out Contributing to vLLM-Omni for how to get involved.
Citation
If you use vLLM-Omni for your research, please cite our paper:
@article{yin2026vllmomni,
  title={vLLM-Omni: Fully Disaggregated Serving for Any-to-Any Multimodal Models},
  author={Peiqi Yin, Jiangyun Zhu, Han Gao, Chenguang Zheng, Yongxiang Huang, Taichang Zhou, Ruirui Yang, Weizhi Liu, Weiqing Chen, Canlin Guo, Didan Deng, Zifeng Mo, Cong Wang, James Cheng, Roger Wang, Hongsheng Liu},
  journal={arXiv preprint arXiv:2602.02204},
  year={2026}
}
Join the Community
Feel free to ask questions, provide feedbacks and discuss with fellow users of vLLM-Omni in #sig-omni slack channel at slack.vllm.ai or vLLM user forum at discuss.vllm.ai.
Star History
License
Apache License 2.0, as found in the LICENSE file.