Compare commits
62
Commits
| Author | SHA1 | Date | |
|---|---|---|---|
 copilot-swe-agent[bot]andhsliuustc0106 |
8afbc59636 | ||
|
copilot-swe-agent[bot]andhsliuustc0106
|
3dd27e4365 | ||
|
copilot-swe-agent[bot]andhsliuustc0106
|
f227f28d19 | ||
|
copilot-swe-agent[bot]andhsliuustc0106
|
b4775d52fe | ||
|
copilot-swe-agent[bot]andhsliuustc0106
|
be7d524326 | ||
|
copilot-swe-agent[bot]andhsliuustc0106
|
c7bdfb2934 | ||
|
copilot-swe-agent[bot]
|
b8c080d848 | ||
|
汪志鹏
|
36c28767cd | ||
|
John Liu BUAA
|
bb24e07a7a | ||
|
汪志鹏
|
0888520875 | ||
|
wangyuandwangyu31577
|
4e23bfff9e | ||
|
Yueqian LinandHongsheng Liu
|
3fb6adc40a | ||
|
WeiQing Chen
|
a7f9926013 | ||
|
Didan Deng
|
43ec7f701b | ||
|
Peiqi Yin
|
35f994e255 | ||
|
Ziming Huang
|
b5cf8806f0 | ||
|
WeiQing Chen
|
4203bfa350 | ||
|
Yueqian Lin
|
aaea77a180 | ||
|
Samit
|
2d5faf3634 | ||
|
Alicia
|
314bb4e324 | ||
|
Alicia
|
1fe64e85a6 | ||
|
Yuhan Liu
|
e213bdd0a4 | ||
|
Ziming Huang
|
1444e1fc45 | ||
|
catcat
|
e9a1beec77 | ||
|
Jiangyun Zhu
|
d7cd00e26c | ||
|
Sihyeon Jang
|
f7611198ae | ||
|
XU Mingshi
|
8e20b33b38 | ||
|
JustQJ
|
9cdf592782 | ||
|
Chenguang Zheng
|
7e14c943d5 | ||
|
Prajwal Aandzjy0516
|
779f5987d9 | ||
|
Zhou Taichangandroot
|
2e13bddf87 | ||
|
XU Mingshi
|
8c7f704c23 | ||
|
Sihao LiandHongsheng Liu
|
2c92b63cce | ||
|
Hongsheng Liu
|
61ddeef9f9 | ||
|
wangyuandwangyu31577
|
19887997eb | ||
|
Hongsheng Liu
|
36c7b0148f | ||
|
TJian
|
f25cd37f93 | ||
|
Junhong Liu
|
d0836d8459 | ||
|
dongbo910220andJiangyun Zhu
|
67c0a17a0e | ||
|
Canlin Guo
|
dde96c2468 | ||
|
汪志鹏
|
0ec2da08de | ||
|
|
f3741ac2b9 | ||
|
Canlin GuoandIsotr0py
|
9c2f7467a0 | ||
|
Hongsheng Liu
|
65b55d1c83 | ||
|
TsuKKIandasumaska
|
f26219162b | ||
|
Ziming Huang
|
978e3ad7d4 | ||
|
dongbo910220
|
1467b3e2c7 | ||
|
Jiangyun Zhu
|
c784b3e07d | ||
|
Ziming Huang
|
cddcc400d3 | ||
|
Yuanheng Zhao
|
4c72b67444 | ||
|
Junhong Liu
|
bb13467adc | ||
|
dsinghvi
|
8c1259383c | ||
|
Didan Deng
|
4df794bdaa | ||
|
ApsarasX
|
89f47c910a | ||
|
TJian
|
27b804cea7 | ||
|
Yueqian LinandHongsheng Liu
|
0cb7ec62da | ||
|
Gao Han
|
75cdf1cb4e | ||
|
Chenguang Zheng
|
aaba243832 | ||
|
Didan Deng
|
14c04d0fd4 | ||
|
knlnguyen1802andJiangyun Zhu
|
c32235c4e0 | ||
|
Samit
|
b7e63e07d7 | ||
|
Roger Wang
|
aa5b628b6a |
No files matched your search
+37
-2
@@ -42,6 +42,40 @@ steps:
|
||||
volumes:
|
||||
- "/fsx/hf_cache:/fsx/hf_cache"
|
||||
|
||||
- label: "Diffusion Model CPU offloading Test"
|
||||
timeout_in_minutes: 20
|
||||
depends_on: image-build
|
||||
commands:
|
||||
- pytest -s -v tests/e2e/offline_inference/test_diffusion_cpu_offload.py
|
||||
agents:
|
||||
queue: "gpu_1_queue" # g6.4xlarge instance on AWS, has 1 L4 GPU
|
||||
plugins:
|
||||
- docker#v5.2.0:
|
||||
image: public.ecr.aws/q9t5s3a7/vllm-ci-test-repo:$BUILDKITE_COMMIT
|
||||
always-pull: true
|
||||
propagate-environment: true
|
||||
environment:
|
||||
- "HF_HOME=/fsx/hf_cache"
|
||||
volumes:
|
||||
- "/fsx/hf_cache:/fsx/hf_cache"
|
||||
|
||||
- label: "Audio Generation Model Test"
|
||||
timeout_in_minutes: 20
|
||||
depends_on: image-build
|
||||
commands:
|
||||
- pytest -s -v tests/e2e/offline_inference/test_stable_audio_model.py
|
||||
agents:
|
||||
queue: "gpu_1_queue" # g6.4xlarge instance on AWS, has 1 L4 GPU
|
||||
plugins:
|
||||
- docker#v5.2.0:
|
||||
image: public.ecr.aws/q9t5s3a7/vllm-ci-test-repo:$BUILDKITE_COMMIT
|
||||
always-pull: true
|
||||
propagate-environment: true
|
||||
environment:
|
||||
- "HF_HOME=/fsx/hf_cache"
|
||||
volumes:
|
||||
- "/fsx/hf_cache:/fsx/hf_cache"
|
||||
|
||||
- label: "Diffusion Cache Backend Test"
|
||||
timeout_in_minutes: 15
|
||||
depends_on: image-build
|
||||
@@ -60,10 +94,11 @@ steps:
|
||||
- "/fsx/hf_cache:/fsx/hf_cache"
|
||||
|
||||
- label: "Diffusion Parallelism Test"
|
||||
timeout_in_minutes: 15
|
||||
timeout_in_minutes: 25
|
||||
depends_on: image-build
|
||||
commands:
|
||||
- pytest -s -v tests/e2e/offline_inference/test_sequence_parallel.py
|
||||
- pytest -s -v tests/e2e/offline_inference/test_zimage_tensor_parallel.py
|
||||
agents:
|
||||
queue: "gpu_4_queue" # g6.12xlarge instance on AWS, has 4 L4 GPU
|
||||
plugins:
|
||||
@@ -81,7 +116,7 @@ steps:
|
||||
timeout_in_minutes: 20
|
||||
depends_on: image-build
|
||||
commands:
|
||||
- pytest -s -v tests/diffusion/test_gpu_worker.py
|
||||
- pytest -s -v tests/diffusion/test_gpu_diffusion_worker.py
|
||||
agents:
|
||||
queue: "gpu_4_queue" # g6.12xlarge instance on AWS, has 4 L4 GPU
|
||||
plugins:
|
||||
|
||||
+73
@@ -0,0 +1,73 @@
|
||||
#!/bin/bash
|
||||
# Helper function to safely login to ECR Public with per-job config isolation
|
||||
# Uses DOCKER_CONFIG environment variable to prevent race conditions
|
||||
#
|
||||
# This script prevents the "device or resource busy" error by giving each
|
||||
# Buildkite job its own isolated Docker config directory.
|
||||
#
|
||||
# Usage:
|
||||
# source docker_login_ecr_public.sh && safe_docker_login_ecr_public
|
||||
|
||||
set -euo pipefail
|
||||
|
||||
# Configuration
|
||||
ECR_REGISTRY="public.ecr.aws"
|
||||
|
||||
setup_isolated_docker_config() {
|
||||
# Use BUILDKITE_JOB_ID for job-specific isolation
|
||||
# Fallback to PID if running outside Buildkite
|
||||
local job_id="${BUILDKITE_JOB_ID:-$$}"
|
||||
|
||||
# Set Docker config to job-specific directory
|
||||
export DOCKER_CONFIG="/tmp/docker-config-${job_id}"
|
||||
|
||||
# Create directory if it doesn't exist
|
||||
mkdir -p "$DOCKER_CONFIG"
|
||||
|
||||
echo "[docker-config] Using isolated Docker config: $DOCKER_CONFIG"
|
||||
}
|
||||
|
||||
check_docker_auth() {
|
||||
# Check if already authenticated to the given registry
|
||||
# Returns 0 if authenticated, 1 if not
|
||||
local registry="$1"
|
||||
|
||||
# Check if credentials exist in the isolated config
|
||||
if [[ -f "$DOCKER_CONFIG/config.json" ]]; then
|
||||
# Check if registry is present in config
|
||||
if grep -q "$registry" "$DOCKER_CONFIG/config.json" 2>/dev/null; then
|
||||
return 0
|
||||
fi
|
||||
fi
|
||||
|
||||
return 1
|
||||
}
|
||||
|
||||
safe_docker_login_ecr_public() {
|
||||
# Setup isolated config first
|
||||
setup_isolated_docker_config
|
||||
|
||||
local registry="$ECR_REGISTRY"
|
||||
|
||||
# Check if already authenticated (within this job)
|
||||
if check_docker_auth "$registry"; then
|
||||
echo "[docker-login] Already authenticated to $registry in this job"
|
||||
return 0
|
||||
fi
|
||||
|
||||
# Perform login to isolated config directory
|
||||
echo "[docker-login] Logging in to $ECR_REGISTRY (isolated config)..."
|
||||
if aws ecr-public get-login-password --region us-east-1 | docker login --username AWS --password-stdin "$ECR_REGISTRY"; then
|
||||
echo "[docker-login] Login successful (config: $DOCKER_CONFIG)"
|
||||
return 0
|
||||
else
|
||||
local exit_code=$?
|
||||
echo "[docker-login] ERROR: Login failed with exit code $exit_code" >&2
|
||||
return $exit_code
|
||||
fi
|
||||
}
|
||||
|
||||
# Execute if run as script (not sourced)
|
||||
if [[ "${BASH_SOURCE[0]}" == "${0}" ]]; then
|
||||
safe_docker_login_ecr_public
|
||||
fi
|
||||
@@ -66,6 +66,14 @@ done
|
||||
echo "--- Pulling container"
|
||||
image_name="public.ecr.aws/q9t5s3a7/vllm-ci-test-repo:${BUILDKITE_COMMIT}-rocm-omni"
|
||||
container_name="rocm_${BUILDKITE_COMMIT}_$(tr -dc A-Za-z0-9 < /dev/urandom | head -c 10; echo)"
|
||||
|
||||
# Install AWS CLI to authenticate to ECR Public Gallery to get higher rate limit for pulling images
|
||||
sudo apt-get update && sudo apt-get install -y awscli
|
||||
# Use safe docker login helper to prevent race conditions
|
||||
source "$(dirname "${BASH_SOURCE[0]}")/../docker_login_ecr_public.sh"
|
||||
safe_docker_login_ecr_public
|
||||
# Pull the container from ECR Public Gallery
|
||||
|
||||
docker pull "${image_name}"
|
||||
|
||||
remove_docker_container() {
|
||||
|
||||
@@ -52,3 +52,4 @@ VENV_PYTHON="${VENV_DIR}/bin/python"
|
||||
"${VENV_PYTHON}" -m pytest -v -s tests/entrypoints/
|
||||
"${VENV_PYTHON}" -m pytest -v -s tests/diffusion/cache/
|
||||
"${VENV_PYTHON}" -m pytest -v -s tests/model_executor/models/qwen2_5_omni/test_audio_length.py
|
||||
"${VENV_PYTHON}" -m pytest -v -s tests/worker/
|
||||
@@ -1,10 +1,10 @@
|
||||
steps:
|
||||
|
||||
- label: "Diffusion Model Test"
|
||||
timeout_in_minutes: 15
|
||||
timeout_in_minutes: 20
|
||||
agent_pool: mi325_2
|
||||
depends_on: amd-build
|
||||
mirror_hardwares: [amdexperimental, amdproduction, amdtentative]
|
||||
mirror_hardwares: [amdproduction]
|
||||
grade: Blocking
|
||||
commands:
|
||||
- export GPU_ARCHS=gfx942
|
||||
@@ -20,7 +20,7 @@ steps:
|
||||
timeout_in_minutes: 15
|
||||
agent_pool: mi325_1
|
||||
depends_on: amd-build
|
||||
mirror_hardwares: [amdexperimental, amdproduction, amdtentative]
|
||||
mirror_hardwares: [amdproduction]
|
||||
grade: Blocking
|
||||
commands:
|
||||
- export GPU_ARCHS=gfx942
|
||||
@@ -34,11 +34,33 @@ steps:
|
||||
- export VLLM_ROCM_USE_AITER_RMSNORM=0
|
||||
- pytest -s -v tests/e2e/offline_inference/test_cache_dit.py tests/e2e/offline_inference/test_teacache.py
|
||||
|
||||
- label: "Diffusion Parallelism Test"
|
||||
timeout_in_minutes: 15
|
||||
agent_pool: mi325_2
|
||||
depends_on: amd-build
|
||||
mirror_hardwares: [amdproduction]
|
||||
grade: Blocking
|
||||
commands:
|
||||
- export MIOPEN_DEBUG_CONV_DIRECT=0
|
||||
- export MIOPEN_DEBUG_CONV_GEMM=0
|
||||
- pytest -s -v tests/e2e/offline_inference/test_sequence_parallel.py
|
||||
|
||||
- label: "Diffusion GPU Worker Test"
|
||||
timeout_in_minutes: 20
|
||||
agent_pool: mi325_2
|
||||
depends_on: amd-build
|
||||
mirror_hardwares: [amdproduction]
|
||||
grade: Blocking
|
||||
commands:
|
||||
- export MIOPEN_DEBUG_CONV_DIRECT=0
|
||||
- export MIOPEN_DEBUG_CONV_GEMM=0
|
||||
- pytest -s -v tests/diffusion/test_gpu_diffusion_worker.py
|
||||
|
||||
- label: "Omni Model Test Qwen2-5-Omni"
|
||||
timeout_in_minutes: 15
|
||||
agent_pool: mi325_2
|
||||
depends_on: amd-build
|
||||
mirror_hardwares: [amdexperimental, amdproduction, amdtentative]
|
||||
mirror_hardwares: [amdproduction]
|
||||
grade: Blocking
|
||||
commands:
|
||||
- export GPU_ARCHS=gfx942
|
||||
@@ -51,3 +73,34 @@ steps:
|
||||
- export VLLM_ROCM_USE_AITER_LINEAR=0
|
||||
- export VLLM_ROCM_USE_AITER_RMSNORM=0
|
||||
- pytest -s -v tests/e2e/offline_inference/test_qwen2_5_omni.py
|
||||
|
||||
- label: "Omni Model Test Qwen3-Omni"
|
||||
timeout_in_minutes: 15
|
||||
agent_pool: mi325_2
|
||||
depends_on: amd-build
|
||||
mirror_hardwares: [amdproduction]
|
||||
grade: Blocking
|
||||
commands:
|
||||
- export VLLM_LOGGING_LEVEL=DEBUG
|
||||
- export VLLM_WORKER_MULTIPROC_METHOD=spawn
|
||||
- export MIOPEN_DEBUG_CONV_DIRECT=0
|
||||
- export MIOPEN_DEBUG_CONV_GEMM=0
|
||||
- pytest -s -v tests/e2e/offline_inference/test_qwen3_omni.py tests/e2e/online_serving/test_qwen3_omni.py
|
||||
|
||||
- label: "Diffusion Image Edit Test"
|
||||
timeout_in_minutes: 15
|
||||
agent_pool: mi325_1
|
||||
depends_on: amd-build
|
||||
mirror_hardwares: [amdproduction]
|
||||
grade: Blocking
|
||||
commands:
|
||||
- export GPU_ARCHS=gfx942
|
||||
- export VLLM_LOGGING_LEVEL=DEBUG
|
||||
- export VLLM_WORKER_MULTIPROC_METHOD=spawn
|
||||
- export MIOPEN_DEBUG_CONV_DIRECT=0
|
||||
- export MIOPEN_DEBUG_CONV_GEMM=0
|
||||
- export VLLM_ROCM_USE_AITER=1
|
||||
- export VLLM_ROCM_USE_AITER_MHA=1
|
||||
- export VLLM_ROCM_USE_AITER_LINEAR=0
|
||||
- export VLLM_ROCM_USE_AITER_RMSNORM=0
|
||||
- pytest -s -v tests/e2e/online_serving/test_i2i_multi_image_input.py
|
||||
@@ -13,7 +13,7 @@
|
||||
depends_on: ~
|
||||
soft_fail: false
|
||||
commands:
|
||||
- "aws ecr-public get-login-password --region us-east-1 | docker login --username AWS --password-stdin public.ecr.aws/q9t5s3a7"
|
||||
- "source .buildkite/scripts/docker_login_ecr_public.sh && safe_docker_login_ecr_public"
|
||||
- "docker build -f docker/Dockerfile.rocm -t {{ docker_image_amd }} --progress plain ."
|
||||
- "docker push {{ docker_image_amd }}"
|
||||
key: "amd-build"
|
||||
|
||||
@@ -40,6 +40,31 @@ body:
|
||||
</details>
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: textarea
|
||||
attributes:
|
||||
label: Your code version
|
||||
description: |
|
||||
Please provide a description of which commit id or version the code is.
|
||||
|
||||
value: |
|
||||
<details>
|
||||
<summary>The commit id or version of vllm</summary>
|
||||
|
||||
```text
|
||||
|
||||
```
|
||||
</details>
|
||||
<details>
|
||||
<summary>The commit id or version of vllm-omni</summary>
|
||||
|
||||
```text
|
||||
|
||||
```
|
||||
</details>
|
||||
validations:
|
||||
required: true
|
||||
|
||||
- type: textarea
|
||||
attributes:
|
||||
label: 🐛 Describe the bug
|
||||
|
||||
@@ -20,6 +20,8 @@ body:
|
||||
label: Proposed Change.
|
||||
description: >
|
||||
The proposed change of the RFC.
|
||||
value: |
|
||||
Please provide the detailed design document of the RFC using the [template](https://docs.google.com/document/d/12YxSsVeD1jvL-InClkeAEnZyWFDndz_65JmXvsamuV4/edit?tab=t.0#heading=h.4ef4szrsgspp).
|
||||
validations:
|
||||
required: true
|
||||
- type: textarea
|
||||
|
||||
@@ -9,14 +9,14 @@ Easy, fast, and cheap omni-modality model serving for everyone
|
||||
</h3>
|
||||
|
||||
<p align="center">
|
||||
| <a href="https://vllm-omni.readthedocs.io/en/latest/"><b>Documentation</b></a> | <a href="https://discuss.vllm.ai"><b>User Forum</b></a> | <a href="https://slack.vllm.ai"><b>Developer Slack</b></a> |
|
||||
| <a href="https://vllm-omni.readthedocs.io/en/latest/"><b>Documentation</b></a> | <a href="https://discuss.vllm.ai"><b>User Forum</b></a> | <a href="https://slack.vllm.ai"><b>Developer Slack</b></a> | <a href="docs/assets/WeChat.jpg"><b>WeChat</b></a> |
|
||||
</p>
|
||||
|
||||
---
|
||||
|
||||
*Latest News* 🔥
|
||||
|
||||
- [2026/01] We released [0.12.0rc1](https://github.com/vllm-project/vllm-omni/releases/tag/v0.12.0rc1) - a major RC milestone focused on maturing the diffusion stack, strengthening OpenAI-compatible serving, expanding omni-model coverage, and improving stability across platforms (GPU/NPU/ROCm).
|
||||
- [2026/01] We released [0.12.0rc1](https://github.com/vllm-project/vllm-omni/releases/tag/v0.12.0rc1) - a major RC milestone focused on maturing the diffusion stack, strengthening OpenAI-compatible serving, expanding omni-model coverage, and improving stability across platforms (GPU/NPU/ROCm), please check our latest [design](https://docs.google.com/presentation/d/1qv4qMW1rKAqDREMXiUDLIgqqHQe7TDPj/edit?usp=sharing&ouid=110473603432222024453&rtpof=true&sd=true).
|
||||
- [2025/11] vLLM community officially released [vllm-project/vllm-omni](https://github.com/vllm-project/vllm-omni) in order to support omni-modality models serving.
|
||||
|
||||
---
|
||||
@@ -70,6 +70,10 @@ Please check out [Contributing to vLLM-Omni](https://vllm-omni.readthedocs.io/en
|
||||
## Join the Community
|
||||
Feel free to ask questions, provide feedbacks and discuss with fellow users of vLLM-Omni in `#sig-omni` slack channel at [slack.vllm.ai](https://slack.vllm.ai) or vLLM user forum at [discuss.vllm.ai](https://discuss.vllm.ai).
|
||||
|
||||
## Star History
|
||||
|
||||
[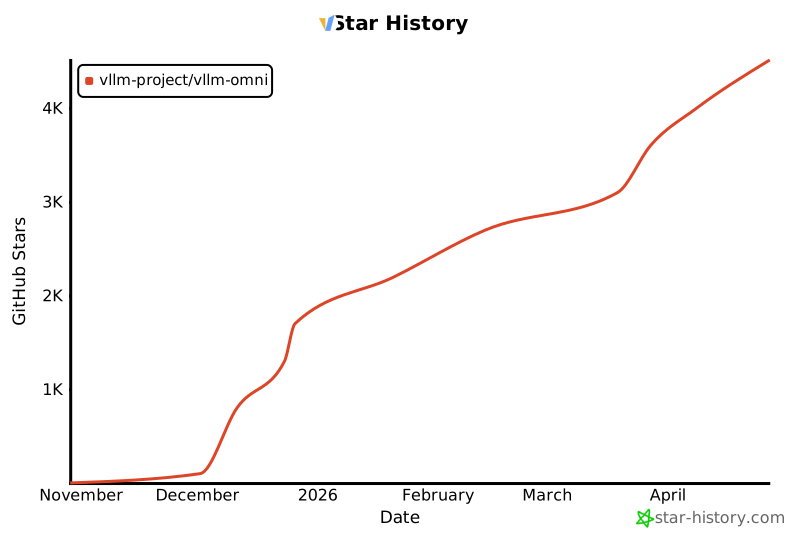](https://www.star-history.com/#vllm-project/vllm-omni&type=date&legend=top-left)
|
||||
|
||||
## License
|
||||
|
||||
Apache License 2.0, as found in the [LICENSE](./LICENSE) file.
|
||||
@@ -0,0 +1,117 @@
|
||||
|
||||
# Diffusion Serving Benchmark (Image/Video)
|
||||
|
||||
This folder contains an online-serving benchmark script for diffusion models.
|
||||
It sends requests to a vLLM OpenAI-compatible endpoint and reports throughput,
|
||||
latency percentiles, and optional SLO attainment.
|
||||
|
||||
The main entrypoint is:
|
||||
|
||||
- `benchmarks/diffusion/diffusion_benchmark_serving.py`
|
||||
|
||||
## 1. Quick Start
|
||||
|
||||
1. Start the server:
|
||||
|
||||
```bash
|
||||
vllm serve Qwen/Qwen-Image --omni --port 8099
|
||||
```
|
||||
|
||||
2. Run a minimal benchmark:
|
||||
|
||||
```bash
|
||||
python3 benchmarks/diffusion/diffusion_benchmark_serving.py \
|
||||
--base-url http://localhost:8099 \
|
||||
--model Qwen/Qwen-Image \
|
||||
--task t2i \
|
||||
--dataset vbench \
|
||||
--num-prompts 5
|
||||
```
|
||||
|
||||
**Notes**
|
||||
|
||||
- The benchmark talks to `http://<host>:<port>/v1/chat/completions`.
|
||||
- If you run the server on another host or port, pass `--base-url` accordingly.
|
||||
|
||||
## 2. Supported Datasets
|
||||
|
||||
The benchmark supports three dataset modes via `--dataset`:
|
||||
|
||||
- `vbench`: Built-in prompt/data loader.
|
||||
- `trace`: Heterogeneous request traces (each request can have different resolution/frames/steps).
|
||||
- `random`: Synthetic prompts for quick smoke tests.
|
||||
|
||||
### VBench dataset
|
||||
|
||||
If you use i2v/i2i bench datasets and need auto-download support, you may need:
|
||||
|
||||
```bash
|
||||
uv pip install gdown
|
||||
```
|
||||
|
||||
### Trace dataset
|
||||
|
||||
Use `--dataset trace` to replay a trace file. The trace can specify per-request fields such as:
|
||||
|
||||
- `width`, `height`
|
||||
- `num_frames` (video)
|
||||
- `num_inference_steps`
|
||||
- `seed`, `fps`
|
||||
- optional `slo_ms` (per-request SLO target)
|
||||
|
||||
By default (when `--dataset-path` is not provided), the script downloads a default trace from
|
||||
the HuggingFace dataset repo `asukaqaqzz/Dit_Trace`. The default filename can depend on `--task`
|
||||
(e.g., `t2v` uses a video trace).
|
||||
|
||||
Current defaults:
|
||||
|
||||
- `--task t2i` -> `sd3_trace.txt`
|
||||
- `--task t2v` -> `cogvideox_trace.txt`
|
||||
|
||||
You can point to your own trace using `--dataset-path`.
|
||||
|
||||
## 3. Benchmark Parameters
|
||||
|
||||
### Basic flags
|
||||
|
||||
- `--base-url`: Server address (the script calls `.../v1/chat/completions`).
|
||||
- `--model`: The OpenAI-compatible `model` field.
|
||||
- `--task`: Task type (e.g., `t2i`, `t2v`, `i2i`, `i2v`).
|
||||
- `--dataset`: Dataset mode (`vbench` / `trace` / `random`).
|
||||
- `--num-prompts`: Number of requests to send.
|
||||
|
||||
Common optional flags:
|
||||
|
||||
- `--output-file`: Write metrics to a JSON file.
|
||||
- `--disable-tqdm`: Disable the progress bar.
|
||||
|
||||
### Resolution / frames / steps: CLI defaults vs dataset fields
|
||||
|
||||
Related flags: `--width`, `--height`, `--num-frames`, `--fps`, `--num-inference-steps`.
|
||||
|
||||
- For `vbench` / `random`: these CLI flags act as global defaults for all generated requests.
|
||||
- For `trace`: each request can carry its own fields (e.g., `width/height/num_frames/num_inference_steps`).
|
||||
|
||||
Precedence rules for `trace` (i.e., what actually gets sent):
|
||||
|
||||
- `width/height`: if either `--width` or `--height` is explicitly set, it overrides per-request values from the trace; otherwise per-request values are used when present.
|
||||
- `num_frames`: per-request `num_frames` takes precedence; otherwise fall back to `--num-frames`.
|
||||
- `num_inference_steps`: per-request `num_inference_steps` takes precedence; otherwise fall back to `--num-inference-steps`.
|
||||
|
||||
### SLO, warmup, and max concurrency
|
||||
|
||||
Enable SLO evaluation with `--slo`.
|
||||
|
||||
- If a request in the trace already has `slo_ms`, that value is used.
|
||||
- Otherwise, the script runs warmup requests to infer a base unit time, estimates `expected_ms` by linearly scaling with area/frames/steps, and then sets `slo_ms = expected_ms * --slo-scale`.
|
||||
|
||||
Warmup flags:
|
||||
|
||||
- `--warmup-requests`: Number of warmup requests.
|
||||
- `--warmup-num-inference-steps`: Steps used during warmup.
|
||||
- For `--task t2v`: warmup requests are forced to use `num_frames=1` to make warmup faster and less noisy.
|
||||
|
||||
Traffic / concurrency flags:
|
||||
|
||||
- `--request-rate`: Target request rate (requests/second). If set to `inf`, the script sends all requests immediately.
|
||||
- `--max-concurrency`: Max number of in-flight requests (default: `1`). This can hard-cap the achieved QPS: if it is too small, requests will queue behind the semaphore, and both achieved throughput and observed SLO attainment can be skewed.
|
||||
+422
-15
@@ -9,28 +9,29 @@ If you want to use i2v, i2i dataset, you should `uv pip install gdown` first
|
||||
Usage:
|
||||
# Video
|
||||
t2v:
|
||||
python3 benchmarks/diffusion_benchmark_serving.py \
|
||||
python3 benchmarks/diffusion/diffusion_benchmark_serving.py \
|
||||
--dataset vbench --task t2v --num-prompts 10 \
|
||||
--height 480 --width 640 --fps 16 --num-frames 80
|
||||
|
||||
i2v:
|
||||
python3 benchmarks/diffusion_benchmark_serving.py \
|
||||
python3 benchmarks/diffusion/diffusion_benchmark_serving.py \
|
||||
--dataset vbench --task i2v --num-prompts 10
|
||||
|
||||
|
||||
# Image
|
||||
t2i:
|
||||
python3 benchmarks/diffusion_benchmark_serving.py \
|
||||
python3 benchmarks/diffusion/diffusion_benchmark_serving.py \
|
||||
--dataset vbench --task t2i --num-prompts 10 \
|
||||
--height 1024 --width 1024
|
||||
|
||||
i2i:
|
||||
python3 benchmarks/diffusion_benchmark_serving.py \
|
||||
python3 benchmarks/diffusion/diffusion_benchmark_serving.py \
|
||||
--dataset vbench --task i2i --num-prompts 10
|
||||
|
||||
"""
|
||||
|
||||
import argparse
|
||||
import ast
|
||||
import asyncio
|
||||
import base64
|
||||
import glob
|
||||
@@ -40,6 +41,7 @@ import os
|
||||
import time
|
||||
import uuid
|
||||
from abc import ABC, abstractmethod
|
||||
from collections.abc import AsyncGenerator
|
||||
from dataclasses import dataclass, field, replace
|
||||
from typing import Any
|
||||
|
||||
@@ -60,6 +62,8 @@ class RequestFuncInput:
|
||||
num_inference_steps: int | None = None
|
||||
seed: int | None = None
|
||||
fps: int | None = None
|
||||
timestamp: float | None = None
|
||||
slo_ms: float | None = None
|
||||
extra_body: dict[str, Any] = field(default_factory=dict)
|
||||
image_paths: list[str] | None = None
|
||||
request_id: str = field(default_factory=lambda: str(uuid.uuid4()))
|
||||
@@ -73,6 +77,7 @@ class RequestFuncOutput:
|
||||
start_time: float = 0.0
|
||||
response_body: dict[str, Any] = field(default_factory=dict)
|
||||
peak_memory_mb: float = 0.0
|
||||
slo_achieved: bool | None = None
|
||||
|
||||
|
||||
class BaseDataset(ABC):
|
||||
@@ -310,6 +315,226 @@ class VBenchDataset(BaseDataset):
|
||||
return [self[i] for i in range(len(self))]
|
||||
|
||||
|
||||
class TraceDataset(BaseDataset):
|
||||
"""Trace-based dataset loader for heterogeneous diffusion requests."""
|
||||
|
||||
DEFAULT_REPO_ID = "asukaqaqzz/Dit_Trace"
|
||||
DEFAULT_FILENAME = "sd3_trace.txt"
|
||||
DEFAULT_FILENAME_BY_TASK: dict[str, str] = {
|
||||
# Text-to-image traces (e.g., SD3)
|
||||
"t2i": "sd3_trace.txt",
|
||||
# Text-to-video traces (e.g., CogVideoX)
|
||||
"t2v": "cogvideox_trace.txt",
|
||||
}
|
||||
|
||||
def __init__(self, args, api_url: str, model: str):
|
||||
super().__init__(args, api_url, model)
|
||||
self.cache_dir = os.path.join(os.path.expanduser("~"), ".cache", "vllm-omni", "trace")
|
||||
self.default_filename = self.DEFAULT_FILENAME_BY_TASK.get(getattr(args, "task", ""), self.DEFAULT_FILENAME)
|
||||
dataset_root = args.dataset_path
|
||||
if not dataset_root:
|
||||
dataset_root = self._download_default_trace()
|
||||
self.items = self._load_items(dataset_root)
|
||||
|
||||
@staticmethod
|
||||
def _coerce_int(x: Any) -> int | None:
|
||||
if x is None:
|
||||
return None
|
||||
if isinstance(x, bool):
|
||||
return None
|
||||
if isinstance(x, int):
|
||||
return x
|
||||
try:
|
||||
s = str(x).strip()
|
||||
if not s:
|
||||
return None
|
||||
return int(float(s))
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
@staticmethod
|
||||
def _coerce_float(x: Any) -> float | None:
|
||||
if x is None:
|
||||
return None
|
||||
if isinstance(x, float):
|
||||
return x
|
||||
if isinstance(x, int):
|
||||
return float(x)
|
||||
try:
|
||||
s = str(x).strip()
|
||||
if not s:
|
||||
return None
|
||||
return float(s)
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
def _download_default_trace(self) -> str:
|
||||
"""Download default trace file from HuggingFace Hub if not provided."""
|
||||
|
||||
try:
|
||||
from huggingface_hub import hf_hub_download
|
||||
except ImportError as exc:
|
||||
raise ImportError(
|
||||
"huggingface_hub is required to download the default trace dataset. "
|
||||
"Install via `pip install huggingface_hub`."
|
||||
) from exc
|
||||
|
||||
os.makedirs(self.cache_dir, exist_ok=True)
|
||||
return hf_hub_download(
|
||||
repo_id=self.DEFAULT_REPO_ID,
|
||||
filename=self.default_filename,
|
||||
repo_type="dataset",
|
||||
local_dir=self.cache_dir,
|
||||
local_dir_use_symlinks=False,
|
||||
)
|
||||
|
||||
def _expand_paths(self, dataset_path: str | None) -> list[str]:
|
||||
if not dataset_path:
|
||||
return []
|
||||
|
||||
parts = [p.strip() for p in str(dataset_path).split(",") if p.strip()]
|
||||
paths: list[str] = []
|
||||
for p in parts:
|
||||
if any(ch in p for ch in ["*", "?", "["]):
|
||||
paths.extend(sorted(glob.glob(p)))
|
||||
elif os.path.isdir(p):
|
||||
paths.extend(sorted(glob.glob(os.path.join(p, "**", "*.txt"), recursive=True)))
|
||||
else:
|
||||
paths.append(p)
|
||||
|
||||
seen = set()
|
||||
unique_paths = []
|
||||
for p in paths:
|
||||
if p not in seen:
|
||||
seen.add(p)
|
||||
unique_paths.append(p)
|
||||
return unique_paths
|
||||
|
||||
def _parse_trace_file(self, path: str) -> list[dict[str, Any]]:
|
||||
rows: list[dict[str, Any]] = []
|
||||
|
||||
def parse_request_repr_line(line: str) -> dict[str, Any] | None:
|
||||
text = line.strip()
|
||||
if not text:
|
||||
return None
|
||||
if not (text.startswith("Request(") and text.endswith(")")):
|
||||
return None
|
||||
inner = text[len("Request(") : -1]
|
||||
try:
|
||||
expr = ast.parse(f"f({inner})", mode="eval")
|
||||
if not isinstance(expr.body, ast.Call):
|
||||
return None
|
||||
call = expr.body
|
||||
out: dict[str, Any] = {}
|
||||
for kw in call.keywords:
|
||||
if kw.arg is None:
|
||||
continue
|
||||
out[kw.arg] = ast.literal_eval(kw.value)
|
||||
return out
|
||||
except Exception:
|
||||
return None
|
||||
|
||||
# detect first non-empty line to pick parser
|
||||
first_non_empty = None
|
||||
with open(path, encoding="utf-8") as f:
|
||||
for _ in range(50):
|
||||
pos = f.tell()
|
||||
line = f.readline()
|
||||
if not line:
|
||||
break
|
||||
if line.strip():
|
||||
first_non_empty = line.strip()
|
||||
f.seek(pos)
|
||||
break
|
||||
|
||||
if first_non_empty is None:
|
||||
return rows
|
||||
|
||||
if first_non_empty.startswith("Request("):
|
||||
with open(path, encoding="utf-8") as f:
|
||||
for line in f:
|
||||
parsed = parse_request_repr_line(line)
|
||||
if isinstance(parsed, dict):
|
||||
rows.append(parsed)
|
||||
return rows
|
||||
|
||||
# txt fallback: parse Request(...) lines only
|
||||
with open(path, encoding="utf-8") as f:
|
||||
for line in f:
|
||||
parsed = parse_request_repr_line(line)
|
||||
if isinstance(parsed, dict):
|
||||
rows.append(parsed)
|
||||
return rows
|
||||
|
||||
def _load_items(self, dataset_root: str) -> list[dict[str, Any]]:
|
||||
paths = self._expand_paths(dataset_root)
|
||||
if not paths:
|
||||
raise ValueError("No trace files found. Provide --dataset-path or rely on default HuggingFace download.")
|
||||
|
||||
items: list[dict[str, Any]] = []
|
||||
for p in paths:
|
||||
if not os.path.exists(p):
|
||||
continue
|
||||
for row in self._parse_trace_file(p):
|
||||
if isinstance(row, dict):
|
||||
row = dict(row)
|
||||
row.setdefault("_source", p)
|
||||
items.append(row)
|
||||
|
||||
if not items:
|
||||
raise ValueError("Trace dataset is empty after parsing provided paths.")
|
||||
|
||||
if self.args.num_prompts is not None:
|
||||
items = items[: self.args.num_prompts]
|
||||
|
||||
return items
|
||||
|
||||
def __len__(self) -> int:
|
||||
return len(self.items)
|
||||
|
||||
def __getitem__(self, idx: int) -> RequestFuncInput:
|
||||
row = self.items[idx]
|
||||
prompt = row.get("prompt") or row.get("text") or ""
|
||||
|
||||
row_height = self._coerce_int(row.get("height"))
|
||||
row_width = self._coerce_int(row.get("width"))
|
||||
num_frames = self._coerce_int(row.get("num_frames"))
|
||||
num_steps = self._coerce_int(row.get("num_inference_steps"))
|
||||
seed = self._coerce_int(row.get("seed"))
|
||||
fps = self._coerce_int(row.get("fps"))
|
||||
timestamp = self._coerce_float(row.get("timestamp"))
|
||||
slo_ms = self._coerce_float(row.get("slo_ms"))
|
||||
image_paths = row.get("image_paths")
|
||||
|
||||
override_w = self.args.width
|
||||
override_h = self.args.height
|
||||
if override_w is not None or override_h is not None:
|
||||
width = override_w
|
||||
height = override_h
|
||||
else:
|
||||
width = row_width
|
||||
height = row_height
|
||||
|
||||
return RequestFuncInput(
|
||||
prompt=str(prompt),
|
||||
api_url=self.api_url,
|
||||
model=self.model,
|
||||
width=width,
|
||||
height=height,
|
||||
num_frames=num_frames if num_frames is not None else self.args.num_frames,
|
||||
num_inference_steps=num_steps if num_steps is not None else self.args.num_inference_steps,
|
||||
seed=seed if seed is not None else self.args.seed,
|
||||
fps=fps if fps is not None else self.args.fps,
|
||||
timestamp=timestamp,
|
||||
slo_ms=slo_ms,
|
||||
image_paths=image_paths,
|
||||
request_id=str(row.get("request_id")) if row.get("request_id") is not None else str(uuid.uuid4()),
|
||||
)
|
||||
|
||||
def get_requests(self) -> list[RequestFuncInput]:
|
||||
return [self[i] for i in range(len(self))]
|
||||
|
||||
|
||||
class RandomDataset(BaseDataset):
|
||||
def __init__(self, args, api_url: str, model: str):
|
||||
self.args = args
|
||||
@@ -337,6 +562,128 @@ class RandomDataset(BaseDataset):
|
||||
return [self[i] for i in range(len(self))]
|
||||
|
||||
|
||||
def _compute_expected_latency_ms_from_base(req: RequestFuncInput, args, base_time_ms: float | None) -> float | None:
|
||||
"""Compute expected execution time (ms) based on a base per-step-per-frame unit time.
|
||||
|
||||
Assumes linear scaling with pixel area, frame count, and num_inference_steps.
|
||||
The base unit represents latency for a 16x16 resolution, single frame, single step.
|
||||
"""
|
||||
|
||||
if base_time_ms is None:
|
||||
return None
|
||||
|
||||
width = req.width if req.width is not None else args.width
|
||||
height = req.height if req.height is not None else args.height
|
||||
if width is None or height is None:
|
||||
return None
|
||||
|
||||
frames = req.num_frames if req.num_frames is not None else args.num_frames
|
||||
steps = req.num_inference_steps if req.num_inference_steps is not None else args.num_inference_steps
|
||||
|
||||
frame_scale = frames if isinstance(frames, int) and frames > 0 else 1
|
||||
step_scale = steps if isinstance(steps, int) and steps > 0 else 1
|
||||
|
||||
area_units = max((float(width) * float(height)) / float(16 * 16), 1.0)
|
||||
return float(base_time_ms) * area_units * frame_scale * step_scale
|
||||
|
||||
|
||||
def _infer_slo_base_time_ms_from_warmups(
|
||||
warmup_pairs: list[tuple[RequestFuncInput, RequestFuncOutput]],
|
||||
args,
|
||||
) -> float | None:
|
||||
"""Infer base SLO unit time from warmup requests.
|
||||
|
||||
Returns the median base latency (ms) for a 16x16 resolution, single-frame,
|
||||
single-step request. Only uses warmups that succeeded and have resolvable
|
||||
width/height.
|
||||
"""
|
||||
|
||||
candidates_ms: list[float] = []
|
||||
for req, out in warmup_pairs:
|
||||
if not out.success or out.latency <= 0:
|
||||
continue
|
||||
|
||||
width = req.width if req.width is not None else args.width
|
||||
height = req.height if req.height is not None else args.height
|
||||
if width is None or height is None:
|
||||
continue
|
||||
|
||||
frames = req.num_frames if req.num_frames is not None else args.num_frames
|
||||
steps = req.num_inference_steps if req.num_inference_steps is not None else args.num_inference_steps
|
||||
|
||||
frame_scale = int(frames) if isinstance(frames, int) and frames > 0 else 1
|
||||
step_scale = int(steps) if isinstance(steps, int) and steps > 0 else 1
|
||||
|
||||
area_units = max((float(width) * float(height)) / float(16 * 16), 1.0)
|
||||
denom = area_units * float(frame_scale) * float(step_scale)
|
||||
if denom <= 0:
|
||||
continue
|
||||
|
||||
candidates_ms.append((out.latency * 1000.0) / denom)
|
||||
|
||||
if not candidates_ms:
|
||||
return None
|
||||
return float(np.median(candidates_ms))
|
||||
|
||||
|
||||
def _populate_slo_ms_from_warmups(
|
||||
requests_list: list[RequestFuncInput],
|
||||
warmup_pairs: list[tuple[RequestFuncInput, RequestFuncOutput]],
|
||||
args,
|
||||
) -> list[RequestFuncInput]:
|
||||
"""Populate missing RequestFuncInput.slo_ms using warmup outputs.
|
||||
|
||||
- If a request already has slo_ms (e.g., trace-provided), it is kept as-is.
|
||||
- If any request has slo_ms is None and we can infer base time from warmups,
|
||||
we estimate each missing request's expected execution time and set:
|
||||
req.slo_ms = expected_latency_ms * args.slo_scale
|
||||
|
||||
Returns updated requests_list.
|
||||
"""
|
||||
|
||||
if not any(req.slo_ms is None for req in requests_list):
|
||||
return requests_list
|
||||
|
||||
base_time_ms = _infer_slo_base_time_ms_from_warmups(warmup_pairs, args)
|
||||
if base_time_ms is None:
|
||||
return requests_list
|
||||
|
||||
slo_scale = float(getattr(args, "slo_scale", 3.0))
|
||||
if slo_scale <= 0:
|
||||
raise ValueError(f"slo_scale must be positive, got {slo_scale}.")
|
||||
|
||||
updated: list[RequestFuncInput] = []
|
||||
for req in requests_list:
|
||||
if req.slo_ms is not None:
|
||||
updated.append(req)
|
||||
continue
|
||||
expected_ms = _compute_expected_latency_ms_from_base(req, args, base_time_ms)
|
||||
updated.append(replace(req, slo_ms=(expected_ms * slo_scale) if expected_ms is not None else None))
|
||||
|
||||
return updated
|
||||
|
||||
|
||||
async def iter_requests(
|
||||
requests_list: list[RequestFuncInput],
|
||||
request_rate: float,
|
||||
) -> AsyncGenerator[RequestFuncInput, None]:
|
||||
"""Yield requests using a fixed interval if request_rate is set.
|
||||
|
||||
- If request_rate is inf, all requests are yielded immediately (no sleep).
|
||||
- Otherwise, requests are emitted at a fixed cadence of 1 / request_rate seconds.
|
||||
"""
|
||||
|
||||
if request_rate != float("inf"):
|
||||
if request_rate <= 0:
|
||||
raise ValueError(f"request_rate must be positive or inf, got {request_rate}.")
|
||||
interval_s = 1.0 / float(request_rate)
|
||||
|
||||
for i, req in enumerate(requests_list):
|
||||
if request_rate != float("inf") and i > 0:
|
||||
await asyncio.sleep(interval_s)
|
||||
yield req
|
||||
|
||||
|
||||
def _guess_mime_type(path: str) -> str:
|
||||
mime, _ = mimetypes.guess_type(path)
|
||||
return mime or "application/octet-stream"
|
||||
@@ -415,12 +762,21 @@ async def async_request_chat_completions(
|
||||
|
||||
output.latency = time.perf_counter() - output.start_time
|
||||
|
||||
if output.success and input.slo_ms is not None:
|
||||
output.slo_achieved = (output.latency * 1000.0) <= float(input.slo_ms)
|
||||
|
||||
if pbar:
|
||||
pbar.update(1)
|
||||
return output
|
||||
|
||||
|
||||
def calculate_metrics(outputs: list[RequestFuncOutput], total_duration: float):
|
||||
def calculate_metrics(
|
||||
outputs: list[RequestFuncOutput],
|
||||
total_duration: float,
|
||||
requests_list: list[RequestFuncInput],
|
||||
args,
|
||||
slo_enabled: bool,
|
||||
):
|
||||
success_outputs = [o for o in outputs if o.success]
|
||||
error_outputs = [o for o in outputs if not o.success]
|
||||
|
||||
@@ -442,6 +798,29 @@ def calculate_metrics(outputs: list[RequestFuncOutput], total_duration: float):
|
||||
"peak_memory_mb_median": np.median(peak_memories) if peak_memories else 0,
|
||||
}
|
||||
|
||||
if slo_enabled:
|
||||
slo_defined_total = 0
|
||||
slo_met_success = 0
|
||||
|
||||
for req, out in zip(requests_list, outputs):
|
||||
if req.slo_ms is None:
|
||||
continue
|
||||
slo_defined_total += 1
|
||||
if out.slo_achieved is None:
|
||||
continue
|
||||
if out.slo_achieved:
|
||||
slo_met_success += 1
|
||||
|
||||
slo_attain_all = (slo_met_success / slo_defined_total) if slo_defined_total > 0 else 0.0
|
||||
|
||||
metrics.update(
|
||||
{
|
||||
"slo_attainment_rate": slo_attain_all,
|
||||
"slo_met_success": slo_met_success,
|
||||
"slo_scale": getattr(args, "slo_scale", 3.0),
|
||||
}
|
||||
)
|
||||
|
||||
return metrics
|
||||
|
||||
|
||||
@@ -475,6 +854,8 @@ async def benchmark(args):
|
||||
|
||||
if args.dataset == "vbench":
|
||||
dataset = VBenchDataset(args, api_url, args.model)
|
||||
elif args.dataset == "trace":
|
||||
dataset = TraceDataset(args, api_url, args.model)
|
||||
elif args.dataset == "random":
|
||||
dataset = RandomDataset(args, api_url, args.model)
|
||||
else:
|
||||
@@ -501,6 +882,7 @@ async def benchmark(args):
|
||||
pbar = tqdm(total=len(requests_list), disable=args.disable_tqdm)
|
||||
|
||||
async with aiohttp.ClientSession() as session:
|
||||
warmup_pairs: list[tuple[RequestFuncInput, RequestFuncOutput]] = []
|
||||
if args.warmup_requests and requests_list:
|
||||
print(
|
||||
f"Running {args.warmup_requests} warmup request(s) \
|
||||
@@ -513,16 +895,20 @@ async def benchmark(args):
|
||||
warm_req,
|
||||
num_inference_steps=args.warmup_num_inference_steps,
|
||||
)
|
||||
await limited_request_func(warm_req, session, None)
|
||||
warm_out = await limited_request_func(warm_req, session, None)
|
||||
warmup_pairs.append((warm_req, warm_out))
|
||||
|
||||
if args.slo:
|
||||
# Prefer trace-provided per-request slo_ms. Only populate when missing.
|
||||
requests_list = _populate_slo_ms_from_warmups(
|
||||
requests_list=requests_list,
|
||||
warmup_pairs=warmup_pairs,
|
||||
args=args,
|
||||
)
|
||||
|
||||
start_time = time.perf_counter()
|
||||
tasks = []
|
||||
for req in requests_list:
|
||||
if args.request_rate != float("inf"):
|
||||
# Poisson process: inter-arrival times follow exponential distribution
|
||||
interval = np.random.exponential(1.0 / args.request_rate)
|
||||
await asyncio.sleep(interval)
|
||||
|
||||
async for req in iter_requests(requests_list=requests_list, request_rate=args.request_rate):
|
||||
task = asyncio.create_task(limited_request_func(req, session, pbar))
|
||||
tasks.append(task)
|
||||
|
||||
@@ -532,7 +918,7 @@ async def benchmark(args):
|
||||
pbar.close()
|
||||
|
||||
# Calculate metrics
|
||||
metrics = calculate_metrics(outputs, total_duration)
|
||||
metrics = calculate_metrics(outputs, total_duration, requests_list, args, args.slo)
|
||||
|
||||
print("\n{s:{c}^{n}}".format(s=" Serving Benchmark Result ", n=60, c="="))
|
||||
|
||||
@@ -561,6 +947,12 @@ async def benchmark(args):
|
||||
print("{:<40} {:<15.4f}".format("Latency Median (s):", metrics["latency_median"]))
|
||||
print("{:<40} {:<15.4f}".format("Latency P99 (s):", metrics["latency_p99"]))
|
||||
|
||||
if args.slo:
|
||||
print(f"{'-' * 50}")
|
||||
print("{:<40} {:<15.2%}".format("SLO Attainment Rate (all):", metrics.get("slo_attainment_rate", 0.0)))
|
||||
print("{:<40} {:<15}".format("SLO Met (success count):", str(metrics.get("slo_met_success", 0))))
|
||||
print("{:<40} {:<15}".format("SLO Scale:", str(metrics.get("slo_scale", 3.0))))
|
||||
|
||||
if metrics["peak_memory_mb_max"] > 0:
|
||||
print(f"{'-' * 50}")
|
||||
print("{:<40} {:<15.2f}".format("Peak Memory Max (MB):", metrics["peak_memory_mb_max"]))
|
||||
@@ -590,7 +982,7 @@ if __name__ == "__main__":
|
||||
"--dataset",
|
||||
type=str,
|
||||
default="vbench",
|
||||
choices=["vbench", "random"],
|
||||
choices=["vbench", "trace", "random"],
|
||||
help="Dataset to use.",
|
||||
)
|
||||
parser.add_argument(
|
||||
@@ -645,7 +1037,7 @@ if __name__ == "__main__":
|
||||
parser.add_argument(
|
||||
"--num-inference-steps",
|
||||
type=int,
|
||||
default=None,
|
||||
default=50,
|
||||
help="Number of inference steps (for diffusion models).",
|
||||
)
|
||||
parser.add_argument(
|
||||
@@ -656,6 +1048,21 @@ if __name__ == "__main__":
|
||||
)
|
||||
parser.add_argument("--fps", type=int, default=None, help="FPS (for video).")
|
||||
parser.add_argument("--output-file", type=str, default=None, help="Output JSON file for metrics.")
|
||||
parser.add_argument(
|
||||
"--slo",
|
||||
action="store_true",
|
||||
help=(
|
||||
"Enable SLO calculation and reporting. If trace provides per-request slo_ms, it is used. "
|
||||
"Otherwise, warmup request(s) are used to infer expected execution time assuming linear "
|
||||
"scaling by resolution, frames, and steps, then slo_ms = expected_time * --slo-scale."
|
||||
),
|
||||
)
|
||||
parser.add_argument(
|
||||
"--slo-scale",
|
||||
type=float,
|
||||
default=3.0,
|
||||
help="SLO target multiplier: slo_ms = estimated_exec_time_ms * slo_scale (default: 3).",
|
||||
)
|
||||
parser.add_argument("--disable-tqdm", action="store_true", help="Disable progress bar.")
|
||||
|
||||
args = parser.parse_args()
|
||||
@@ -57,6 +57,7 @@ SystemEnv = namedtuple(
|
||||
"cpu_info",
|
||||
"rocm_version", # vllm specific field
|
||||
"vllm_version", # vllm specific field
|
||||
"vllm_omni_version", # vllm-omni specific field
|
||||
"vllm_build_flags", # vllm specific field
|
||||
"gpu_topo", # vllm specific field
|
||||
"env_vars",
|
||||
@@ -289,6 +290,31 @@ def get_vllm_version():
|
||||
return __version__
|
||||
|
||||
|
||||
def get_vllm_omni_version(run_lambda):
|
||||
try:
|
||||
import vllm_omni
|
||||
from vllm_omni import __version__, __version_tuple__
|
||||
|
||||
version_str = __version_tuple__[-1]
|
||||
if isinstance(version_str, str) and version_str.startswith("g"):
|
||||
if "." in version_str:
|
||||
git_sha = version_str.split(".")[0][1:]
|
||||
date = version_str.split(".")[-1][1:]
|
||||
return f"{__version__} (git sha: {git_sha}, date: {date})"
|
||||
else:
|
||||
git_sha = version_str[1:]
|
||||
return f"{__version__} (git sha: {git_sha})"
|
||||
|
||||
package_dir = os.path.dirname(os.path.abspath(vllm_omni.__file__))
|
||||
git_sha = run_and_read_all(run_lambda, f"git -C {package_dir} rev-parse --short HEAD")
|
||||
if git_sha:
|
||||
return f"{__version__} (git sha: {git_sha})"
|
||||
|
||||
return __version__
|
||||
except ImportError:
|
||||
return "N/A (vllm_omni not installed)"
|
||||
|
||||
|
||||
def summarize_vllm_build_flags():
|
||||
# This could be a static method if the flags are constant, or dynamic if you need to check environment variables, etc.
|
||||
return "CUDA Archs: {}; ROCm: {}".format(
|
||||
@@ -524,6 +550,7 @@ def get_env_info():
|
||||
|
||||
rocm_version = get_rocm_version(run_lambda)
|
||||
vllm_version = get_vllm_version()
|
||||
vllm_omni_version = get_vllm_omni_version(run_lambda)
|
||||
vllm_build_flags = summarize_vllm_build_flags()
|
||||
gpu_topo = get_gpu_topo(run_lambda)
|
||||
|
||||
@@ -555,6 +582,7 @@ def get_env_info():
|
||||
cpu_info=get_cpu_info(run_lambda),
|
||||
rocm_version=rocm_version,
|
||||
vllm_version=vllm_version,
|
||||
vllm_omni_version=vllm_omni_version,
|
||||
vllm_build_flags=vllm_build_flags,
|
||||
gpu_topo=gpu_topo,
|
||||
env_vars=get_env_vars(),
|
||||
@@ -621,6 +649,7 @@ env_info_fmt += """
|
||||
==============================
|
||||
ROCM Version : {rocm_version}
|
||||
vLLM Version : {vllm_version}
|
||||
vLLM-Omni Version : {vllm_omni_version}
|
||||
vLLM Build Flags:
|
||||
{vllm_build_flags}
|
||||
GPU Topology:
|
||||
|
||||
@@ -6,6 +6,12 @@ WORKDIR ${APP_DIR}
|
||||
|
||||
COPY . .
|
||||
|
||||
# Install system dependencies
|
||||
RUN apt-get update && \
|
||||
apt-get install -y ffmpeg && \
|
||||
apt-get clean && \
|
||||
rm -rf /var/lib/apt/lists/*
|
||||
|
||||
# Install vllm-omni into the same uv-managed Python environment used by the base image.
|
||||
RUN uv pip install --python "$(python3 -c 'import sys; print(sys.executable)')" --no-cache-dir ".[dev]"
|
||||
|
||||
|
||||
+10
-8
@@ -3,7 +3,7 @@ nav:
|
||||
- User Guide:
|
||||
- Getting Started:
|
||||
- getting_started/quickstart.md
|
||||
- getting_started/installation
|
||||
- getting_started/installation/*
|
||||
- Serving:
|
||||
- OpenAI-Compatible API:
|
||||
- Image Generation: serving/image_generation_api.md
|
||||
@@ -11,6 +11,7 @@ nav:
|
||||
- examples/README.md
|
||||
- Offline Inference:
|
||||
- Image-To-Image: user_guide/examples/offline_inference/image_to_image.md
|
||||
- Image-To-Video: user_guide/examples/offline_inference/image_to_video.md
|
||||
- Qwen2.5-Omni: user_guide/examples/offline_inference/qwen2_5_omni.md
|
||||
- Qwen3-Omni: user_guide/examples/offline_inference/qwen3_omni.md
|
||||
- Text-To-Image: user_guide/examples/offline_inference/text_to_image.md
|
||||
@@ -25,14 +26,16 @@ nav:
|
||||
- Configuration:
|
||||
- configuration/README.md
|
||||
- configuration/*
|
||||
- Diffusion Acceleration:
|
||||
- Overview: user_guide/diffusion_acceleration.md
|
||||
- Acceleration Methods:
|
||||
- TeaCache: user_guide/acceleration/teacache.md
|
||||
- Cache-DiT: user_guide/acceleration/cache_dit_acceleration.md
|
||||
- Parallelism Acceleration: user_guide/acceleration/parallelism_acceleration.md
|
||||
- Models:
|
||||
- models/supported_models.md
|
||||
- Features:
|
||||
- Sleep Mode: features/sleep_mode.md
|
||||
- Diffusion Features:
|
||||
- Overview: user_guide/diffusion_acceleration.md
|
||||
- TeaCache: user_guide/diffusion/teacache.md
|
||||
- Cache-DiT: user_guide/diffusion/cache_dit_acceleration.md
|
||||
- Parallelism Acceleration: user_guide/diffusion/parallelism_acceleration.md
|
||||
- CPU Offloading: user_guide/diffusion/cpu_offload_diffusion.md
|
||||
- Developer Guide:
|
||||
- General:
|
||||
- contributing/README.md
|
||||
@@ -43,7 +46,6 @@ nav:
|
||||
- contributing/model/adding_omni_model.md
|
||||
- contributing/model/adding_diffusion_model.md
|
||||
- CI: contributing/ci
|
||||
- Tests: contributing/tests
|
||||
- Design Documents:
|
||||
- design/index.md
|
||||
- design/architecture_overview.md
|
||||
|
||||
+1
-1
@@ -60,5 +60,5 @@ vLLM-Omni seamlessly supports most popular open-source models on HuggingFace, in
|
||||
|
||||
For more information, checkout the following:
|
||||
|
||||
- [vllm-omni architecture design and recent roadmaps](https://docs.google.com/presentation/d/1Y7t2Zm3BIISPN-_X_sDpxZMNCWir2rAx/edit?usp=drive_link&ouid=110473603432222024453&rtpof=true&sd=true)
|
||||
- [vllm-omni architecture design and recent roadmaps](https://docs.google.com/presentation/d/1qv4qMW1rKAqDREMXiUDLIgqqHQe7TDPj/edit?usp=sharing&ouid=110473603432222024453&rtpof=true&sd=true)
|
||||
- [vllm-omni announcement blogpost](https://blog.vllm.ai/2025/11/30/vllm-omni.html)
|
||||
+4
-2
@@ -82,6 +82,7 @@ Model execution components.
|
||||
- [vllm_omni.model_executor.models.qwen3_omni.qwen3_omni_moe_code_predictor_mtp.Qwen3OmniMoeTalkerCodePredictor][]
|
||||
- [vllm_omni.model_executor.models.qwen3_omni.qwen3_omni_moe_talker.Qwen3OmniMoeModel][]
|
||||
- [vllm_omni.model_executor.models.qwen3_omni.qwen3_omni_moe_talker.Qwen3OmniMoeTalkerForConditionalGeneration][]
|
||||
- [vllm_omni.model_executor.models.qwen3_omni.qwen3_omni_moe_talker.Qwen3OmniMoeTalkerSharedExpertWrapper][]
|
||||
- [vllm_omni.model_executor.models.qwen3_omni.qwen3_omni_moe_thinker.Qwen3MoeLLMForCausalLM][]
|
||||
- [vllm_omni.model_executor.models.qwen3_omni.qwen3_omni_moe_thinker.Qwen3MoeLLMModel][]
|
||||
- [vllm_omni.model_executor.models.qwen3_omni.qwen3_omni_moe_thinker.Qwen3OmniMoeConditionalGenerationMixin][]
|
||||
@@ -102,8 +103,9 @@ Configuration classes.
|
||||
|
||||
Worker classes and model runners for distributed inference.
|
||||
|
||||
- [vllm_omni.diffusion.worker.gpu_worker.GPUWorker][]
|
||||
- [vllm_omni.diffusion.worker.gpu_worker.WorkerProc][]
|
||||
- [vllm_omni.diffusion.worker.gpu_diffusion_model_runner.GPUDiffusionModelRunner][]
|
||||
- [vllm_omni.diffusion.worker.gpu_diffusion_worker.GPUDiffusionWorker][]
|
||||
- [vllm_omni.diffusion.worker.gpu_diffusion_worker.WorkerProc][]
|
||||
- [vllm_omni.diffusion.worker.npu.npu_worker.NPUWorker][]
|
||||
- [vllm_omni.diffusion.worker.npu.npu_worker.NPUWorkerProc][]
|
||||
- [vllm_omni.worker.gpu_ar_model_runner.ExecuteModelState][]
|
||||
|
||||

Binary file not shown.
|
After Width: | Height: | Size: 226 KiB |
@@ -16,6 +16,6 @@ For introduction, please check [Introduction for stage config](./stage_configs.m
|
||||
|
||||
## Optimization Features
|
||||
|
||||
- **[TeaCache Configuration](../user_guide/acceleration/teacache.md)** - Enable TeaCache adaptive caching for DiT models to achieve 1.5x-2.0x speedup with minimal quality loss
|
||||
- **[Cache-DiT Configuration](../user_guide/acceleration/cache_dit_acceleration.md)** - Enable Cache-DiT as cache acceleration backends for DiT models
|
||||
- **[Parallelism Configuration](../user_guide/acceleration/parallelism_acceleration.md)** - Enable parallelism (e.g., sequence parallelism) for for DiT models
|
||||
- **[TeaCache Configuration](../user_guide/diffusion/teacache.md)** - Enable TeaCache adaptive caching for DiT models to achieve 1.5x-2.0x speedup with minimal quality loss
|
||||
- **[Cache-DiT Configuration](../user_guide/diffusion/cache_dit_acceleration.md)** - Enable Cache-DiT as cache acceleration backends for DiT models
|
||||
- **[Parallelism Configuration](../user_guide/diffusion/parallelism_acceleration.md)** - Enable parallelism (e.g., sequence parallelism) for for DiT models
|
||||
@@ -0,0 +1,160 @@
|
||||
# Markers for Tests
|
||||
|
||||
By adding markers before test functions, tests can later be executed uniformly by simply declaring the corresponding marker type.
|
||||
|
||||
## Current Markers
|
||||
Defined in `pyproject.toml`:
|
||||
|
||||
| Marker | Description |
|
||||
| ------------------ | ------------------------------------------------------- |
|
||||
| `core_model` | Core model tests (run in each PR) |
|
||||
| `diffusion` | Diffusion model tests |
|
||||
| `omni` | Omni model tests |
|
||||
| `cache` | Cache backend tests |
|
||||
| `parallel` | Parallelism/distributed tests |
|
||||
| `cpu` | Tests that run on CPU |
|
||||
| `gpu` | Tests that run on GPU (auto-added) |
|
||||
| `cuda` | Tests that run on CUDA (auto-added) |
|
||||
| `rocm` | Tests that run on AMD/ROCm (auto-added) |
|
||||
| `npu` | Tests that run on NPU/Ascend (auto-added) |
|
||||
| `H100` | Tests that require H100 GPU |
|
||||
| `L4` | Tests that require L4 GPU |
|
||||
| `MI325` | Tests that require MI325 GPU (AMD/ROCm) |
|
||||
| `A2` | Tests that require A2 NPU |
|
||||
| `A3` | Tests that require A3 NPU |
|
||||
| `distributed_cuda` | Tests that require multi cards on CUDA platform |
|
||||
| `distributed_rocm` | Tests that require multi cards on ROCm platform |
|
||||
| `distributed_npu` | Tests that require multi cards on NPU platform |
|
||||
| `skipif_cuda` | Skip if the num of CUDA cards is less than the required |
|
||||
| `skipif_rocm` | Skip if the num of ROCm cards is less than the required |
|
||||
| `skipif_npu` | Skip if the num of NPU cards is less than the required |
|
||||
| `slow` | Slow tests (may skip in quick CI) |
|
||||
| `benchmark` | Benchmark tests |
|
||||
|
||||
For those markers shown as auto-added, they will be added by the `@hardware_test` decorator.
|
||||
|
||||
### Example usage for markers
|
||||
|
||||
```python
|
||||
from tests.utils import hardware_test
|
||||
|
||||
@pytest.mark.core_model
|
||||
@pytest.mark.omni
|
||||
@hardware_test(
|
||||
res={"cuda": "L4", "rocm": "MI325", "npu": "A2"},
|
||||
num_cards=2,
|
||||
)
|
||||
@pytest.mark.parametrize("omni_server", test_params, indirect=True)
|
||||
def test_video_to_audio()
|
||||
...
|
||||
```
|
||||
### Decorator: `@hardware_test`
|
||||
|
||||
This decorator is intended to make hardware-aware, cross-platform test authoring easier and more robust for CI/CD environments. The `hardware_test` decorator in `vllm-omni/tests/utils.py` performs the following actions:
|
||||
|
||||
1. **Applies platform and resource markers**
|
||||
Adds the appropriate pytest markers for each specified hardware platform (e.g., `cuda`, `rocm`, `npu`) and resource type (e.g., `L4`, `H100`, `MI325`, `A2`, `A3`).
|
||||
```
|
||||
@pytest.mark.cuda
|
||||
@pytest.mark.L4
|
||||
```
|
||||
2. **Handles multi-card (distributed) scenarios**
|
||||
For tests requiring multiple cards, it automatically adds distributed markers such as `distributed_cuda`, `distributed_rocm`, or `distributed_npu`.
|
||||
```
|
||||
@pytest.mark.distributed_cuda(num_cards=num_cards)
|
||||
```
|
||||
3. **Supports flexible card requirements**
|
||||
Accepts `num_cards` as either a single integer for all platforms or as a dictionary with per-platform values. If not specified, defaults to 1 card per platform.
|
||||
|
||||
4. **Integrates resource validation**
|
||||
On CUDA, adds a skip marker (`skipif_cuda`) if the system does not have the required number of devices.
|
||||
Support for `skipif_rocm` and `skipif_npu` will be implemented later.
|
||||
|
||||
|
||||
5. **Runs each test in a new process**
|
||||
Automatically wraps the distributed test with a decorator (`@create_new_process_for_each_test`) to ensure isolation and compatibility with multi-process hardware backends.
|
||||
|
||||
6. **Works with pytest filtering**
|
||||
Allows tests to be filtered and selected at runtime using standard pytest marker expressions (e.g., `-m "distributed_cuda and L4"`).
|
||||
|
||||
#### Example usage for decorator
|
||||
- Single call for multiple platforms:
|
||||
```python
|
||||
@hardware_test(
|
||||
res={"cuda": "L4", "rocm": "MI325", "npu": "A2"},
|
||||
num_cards={"cuda": 2, "rocm": 2, "npu": 2},
|
||||
)
|
||||
```
|
||||
or
|
||||
```python
|
||||
@hardware_test(
|
||||
res={"cuda": "L4", "rocm": "MI325", "npu": "A2"},
|
||||
num_cards=2,
|
||||
)
|
||||
```
|
||||
- `res` must be a dict; supported resources: CUDA (L4/H100), ROCm (MI325), NPU (A2/A3)
|
||||
- `num_cards` can be int (all platforms) or dict (per platform); defaults to 1 when missing
|
||||
- `hardware_test` automatically applies `@create_new_process_for_each_test` for distributed tests.
|
||||
- Distributed markers (`distributed_cuda`, `distributed_rocm`, `distributed_npu`) are auto-added for multi-card cases
|
||||
- Filtering examples:
|
||||
- CUDA only: `pytest -m "distributed_cuda and L4"`
|
||||
- ROCm only: `pytest -m "distributed_rocm and MI325"`
|
||||
- NPU only: `pytest -m "distributed_npu"`
|
||||
|
||||
## Add Support for a New Platform
|
||||
|
||||
If you want to add support for a new platform (e.g., "tpu" for a new accelerator), follow these steps:
|
||||
|
||||
1. **Extend the marker list in your pytest config** so that platform/resource markers are defined:
|
||||
```toml
|
||||
# In pyproject.toml or pytest.ini
|
||||
[tool.pytest.ini_options]
|
||||
markers = [
|
||||
# ... existing markers ...
|
||||
"tpu: Tests that require TPU device",
|
||||
"TPU_V3: Tests that require TPU v3 hardware",
|
||||
"distributed_tpu: Tests that require multiple TPU devices",
|
||||
]
|
||||
```
|
||||
2. **Implement a marker construction function for your platform** in `vllm-omni/tests/utils.py`:
|
||||
```python
|
||||
# In vllm-omni/tests/utils.py
|
||||
|
||||
def tpu_marks(*, res: str, num_cards: int):
|
||||
test_platform = pytest.mark.tpu
|
||||
if res == "TPU_V3":
|
||||
test_resource = pytest.mark.TPU_V3
|
||||
else:
|
||||
raise ValueError(
|
||||
f"Invalid TPU resource type: {res}. Supported: TPU_V3")
|
||||
|
||||
if num_cards == 1:
|
||||
return [test_platform, test_resource]
|
||||
else:
|
||||
test_distributed = pytest.mark.distributed_tpu(num_cards=num_cards)
|
||||
# Optionally: add skipif_tpu when implemented
|
||||
return [test_platform, test_resource, test_distributed]
|
||||
```
|
||||
3. **Update `hardware_test` to recognize your new platform**:
|
||||
In the relevant place (see the `hardware_test` implementation), add:
|
||||
```python
|
||||
if platform == "tpu":
|
||||
marks = tpu_marks(res=resource, num_cards=cards)
|
||||
```
|
||||
4. **(Recommended) Add a test using your new markers**:
|
||||
```python
|
||||
@hardware_test(
|
||||
res={"tpu": "TPU_V3"},
|
||||
num_cards=2,
|
||||
)
|
||||
def test_my_tpu_feature():
|
||||
...
|
||||
```
|
||||
|
||||
**Summary**:
|
||||
- Add pytest markers for your new platform/resources
|
||||
- Implement a marker function (`xxx_marks`)
|
||||
- Plug into `hardware_test`
|
||||
- You're done: tests decorated with `@hardware_test` using your platform now automatically get the correct markers, distribution, and isolation!
|
||||
|
||||
See code in `vllm-omni/tests/utils.py` for existing examples (`cuda_marks`, `rocm_marks`, `npu_marks`).
|
||||
@@ -113,7 +113,7 @@ vllm_omni/ tests/
|
||||
|
||||
### Naming Conventions
|
||||
|
||||
- **Unit/System Tests**: Use `test_<module_name>.py` format. Example: `omni_llm.py` → `test_omni_llm.py`
|
||||
- **Unit Tests**: Use `test_<module_name>.py` format. Example: `omni_llm.py` → `test_omni_llm.py`
|
||||
|
||||
- **E2E Tests**: Place in `tests/e2e/offline_inference/` or `tests/e2e/online_serving/` with descriptive names. Example: `tests/e2e/offline_inference/test_qwen3_omni.py`, `tests/e2e/offline_inference/test_diffusion_model.py`
|
||||
|
||||
@@ -139,7 +139,7 @@ vllm_omni/ tests/
|
||||
4. **Documentation**: Add docstrings to all test functions
|
||||
5. **Environment variables**: Set uniformly in `conftest.py` or at the top of files
|
||||
6. **Type annotations**: Add type annotations to all test function parameters
|
||||
7. **Resources**, Using pytest tag to specify the computation resources the test required.
|
||||
7. **Pytest Markers**: Add necessary markers like `@pytest.mark.core_model` and use `@hardware_test` to declare hardware requirements (check detailed in [Markers for Tests](../ci/tests_markers.md)).
|
||||
|
||||
### Template
|
||||
#### E2E - Online serving
|
||||
@@ -155,6 +155,7 @@ from pathlib import Path
|
||||
import pytest
|
||||
import openai
|
||||
|
||||
from tests.utils import hardware_test
|
||||
|
||||
# Optional: set process start method for workers
|
||||
os.environ["VLLM_WORKER_MULTIPROC_METHOD"] = "spawn"
|
||||
@@ -184,6 +185,12 @@ def base64_encoded_video() -> str:
|
||||
def dummy_messages_from_video_data(video_data_url: str, content_text: str) -> str:
|
||||
xxx
|
||||
|
||||
@pytest.mark.core_model
|
||||
@pytest.mark.omni
|
||||
@hardware_test(
|
||||
res={"cuda": "L4", "rocm": "MI325", "npu": "A2"},
|
||||
num_cards={"cuda": 2, "rocm": 2, "npu": 4},
|
||||
)
|
||||
@pytest.mark.parametrize("omni_server", test_params, indirect=True)
|
||||
def test_video_to_audio(
|
||||
client: openai.OpenAI,
|
||||
@@ -226,6 +233,7 @@ from pathlib import Path
|
||||
import pytest
|
||||
from vllm.assets.video import VideoAsset
|
||||
|
||||
from tests.utils import hardware_test
|
||||
from ..multi_stages.conftest import OmniRunner
|
||||
|
||||
# Optional: set process start method for workers
|
||||
@@ -239,7 +247,12 @@ test_params = [(model, stage_config) for model in models for stage_config in sta
|
||||
|
||||
# function name: test_{input_modality}_to_{output_modality}
|
||||
# modality candidate: text, image, audio, video, mixed_modalities
|
||||
@pytest.mark.gpu_mem_high # requires high-memory GPU node
|
||||
@pytest.mark.core_model
|
||||
@pytest.mark.omni
|
||||
@hardware_test(
|
||||
res={"cuda": "L4", "rocm": "MI325", "npu": "A2"},
|
||||
num_cards=2,
|
||||
)
|
||||
@pytest.mark.parametrize("test_config", test_params)
|
||||
def test_video_to_audio(omni_runner: type[OmniRunner], model: str) -> None:
|
||||
"""Offline inference: video input, audio output."""
|
||||
@@ -263,4 +276,5 @@ def test_video_to_audio(omni_runner: type[OmniRunner], model: str) -> None:
|
||||
|
||||
1. The file is saved in an appropriate place and the file name is clear.
|
||||
2. The coding style follows the requirements outlined above.
|
||||
3. For e2e model test, please ensure the test is configured under the `./buildkite/` folder.
|
||||
3. **All test functions have appropriate pytest markers**
|
||||
4. For tests that need run in CI, please ensure the test is configured under the `./buildkite/` folder.
|
||||
@@ -140,7 +140,7 @@ Key point for writing the example:
|
||||
+ Save or display the generated results so users can validate the integration.
|
||||
|
||||
# Testing
|
||||
For comprehensive testing guidelines, please refer to the [Test File Structure and Style Guide](../tests/tests_style.md).
|
||||
For comprehensive testing guidelines, please refer to the [Test File Structure and Style Guide](../ci/tests_style.md).
|
||||
|
||||
|
||||
## Adding a Model Recipe
|
||||
|
||||
@@ -572,7 +572,7 @@ def talker2code2wav(
|
||||
|
||||
## Testing
|
||||
|
||||
For comprehensive testing guidelines, please refer to the [Test File Structure and Style Guide](../tests/tests_style.md).
|
||||
For comprehensive testing guidelines, please refer to the [Test File Structure and Style Guide](../ci/tests_style.md).
|
||||
|
||||
## Adding a Model Recipe
|
||||
|
||||
|
||||
@@ -64,13 +64,13 @@ According to analysis for current popular open-source models, most of them have
|
||||
|
||||
## Key Components
|
||||
|
||||
| Component | Description |
|
||||
|-----------|-------------|
|
||||
| **OmniRouter** | provide an intelligent router for Omni-modality requests dispatch |
|
||||
| **EntryPoints** | define the APIs for offline/online serving (APIServer, Omni/AsyncOmni) and provide the OmniStage abstraction for different AR/DiT stages |
|
||||
| **AR** | adapted for omni-modality models while inheriting efficient features from vLLM, such as cache management |
|
||||
| **Diffusion** | natively implemented and optimized using acceleration components |
|
||||
| **OmniConnector** | supports fully disaggregation based on E/P/D/G (Encoding/Processing/Decoding/Generation) disaggregation across stages |
|
||||
| Component | Description |
|
||||
| ----------------- | ---------------------------------------------------------------------------------------------------------------------------------------- |
|
||||
| **OmniRouter** | provide an intelligent router for Omni-modality requests dispatch |
|
||||
| **EntryPoints** | define the APIs for offline/online serving (APIServer, Omni/AsyncOmni) and provide the OmniStage abstraction for different AR/DiT stages |
|
||||
| **AR** | adapted for omni-modality models while inheriting efficient features from vLLM, such as cache management |
|
||||
| **Diffusion** | natively implemented and optimized using acceleration components |
|
||||
| **OmniConnector** | supports fully disaggregation based on E/P/D/G (Encoding/Processing/Decoding/Generation) disaggregation across stages |
|
||||
|
||||
Disaggregated stages are managed through configuration, such as in the Qwen3-Omni example, where stages like Thinker, Talker, and Code2wav are defined as separate OmniStage instances with specific resources and input/output type.
|
||||
|
||||
@@ -192,4 +192,4 @@ curl -sS -X POST http://localhost:8091/v1/chat/completions \
|
||||
}
|
||||
```
|
||||
|
||||
For more usages, please refer to [examples](../user_guide/examples/).
|
||||
For more usages, please refer to [examples](../examples/README.md).
|
||||
@@ -0,0 +1,39 @@
|
||||
# Sleep Mode
|
||||
|
||||
vLLM-Omni’s **Sleep Mode** allows you to temporarily release most GPU memory used by a model—such as model weights and key-value (KV) caches (for autoregressive models)—**without stopping the server or unloading the Docker container**.
|
||||
|
||||
This feature is inherited from [vLLM’s Sleep Mode](https://blog.vllm.ai/2025/10/26/sleep-mode.html), which provides zero-reload model switching for multi-model serving.
|
||||
|
||||
It is especially useful in **RLHF**, **training**, or **cost-saving scenarios**, where GPU resources must be freed between inference workloads.
|
||||
|
||||
---
|
||||
|
||||
## Omni Model
|
||||
|
||||
Omni model inherit the feature from vLLM' Sleep Mode
|
||||
|
||||
This means:
|
||||
|
||||
- Support both Level 1 and Level 2 sleep, allow to release and reset both model weights and KV Cache
|
||||
|
||||
## Diffusion Model Extension
|
||||
|
||||
We added Sleep Mode support for **diffusion models**, which previously lacked this functionality.
|
||||
In diffusion pipelines, this currently only offloads **model weight memory**, as these models typically do not use KV caches.
|
||||
|
||||
This means:
|
||||
|
||||
- Diffusion models can now enter Level 1 sleep.
|
||||
- Pipeline states (e.g., noise schedulers, buffers) remain intact after waking.
|
||||
- Useful for releasing VRAM between image generation or training cycles.
|
||||
|
||||
---
|
||||
|
||||
## Enable sleep mode
|
||||
To enable sleep mode, set the `enable_sleep_mode` in `engine_args` to `True`
|
||||
|
||||
|
||||
Example:
|
||||
```python
|
||||
omni = Omni(model=...,enable_sleep_mode=True)
|
||||
```
|
||||
@@ -49,15 +49,18 @@ vLLM-Omni is a Python library that supports the following GPU variants. The libr
|
||||
|
||||
## Set up using Docker
|
||||
|
||||
### Pre-built images
|
||||
|
||||
=== "NVIDIA CUDA"
|
||||
|
||||
--8<-- "docs/getting_started/installation/gpu/cuda.inc.md:pre-built-images"
|
||||
|
||||
=== "AMD ROCm"
|
||||
|
||||
--8<-- "docs/getting_started/installation/gpu/rocm.inc.md:pre-built-images"
|
||||
|
||||
### Build your own docker image
|
||||
|
||||
=== "AMD ROCm"
|
||||
|
||||
--8<-- "docs/getting_started/installation/gpu/rocm.inc.md:build-docker"
|
||||
|
||||
### Pre-built images
|
||||
|
||||
=== "NVIDIA CUDA"
|
||||
|
||||
--8<-- "docs/getting_started/installation/gpu/cuda.inc.md:pre-built-images"
|
||||
@@ -52,4 +52,42 @@ bash
|
||||
|
||||
# --8<-- [start:pre-built-images]
|
||||
|
||||
vLLM-Omni offers an official docker image for deployment. These images are built on top of vLLM docker images and available on Docker Hub as [vllm/vllm-omni-rocm](https://hub.docker.com/r/vllm/vllm-omni-rocm/tags). The version of vLLM-Omni indicates which release of vLLM it is based on.
|
||||
|
||||
#### Launch vLLM-Omni Server
|
||||
Here's an example deployment command that has been verified on 2 x MI300's:
|
||||
```bash
|
||||
docker run -it \
|
||||
--network=host \
|
||||
--group-add=video \
|
||||
--ipc=host \
|
||||
--cap-add=SYS_PTRACE \
|
||||
--security-opt seccomp=unconfined \
|
||||
--device /dev/kfd \
|
||||
--device /dev/dri \
|
||||
-v <path/to/model>:/app/model \
|
||||
-v ~/.cache/huggingface:/root/.cache/huggingface \
|
||||
--env "HF_TOKEN=$HF_TOKEN" \
|
||||
vllm/vllm-omni-rocm:v0.12.0rc1 \
|
||||
vllm serve --model Qwen/Qwen3-Omni-30B-A3B-Instruct --omni --port 8091
|
||||
```
|
||||
|
||||
#### Launch an interactive terminal with prebuilt docker image.
|
||||
If you want to run in dev environment you can launch the docker image as follows:
|
||||
```bash
|
||||
docker run -it \
|
||||
--network=host \
|
||||
--group-add=video \
|
||||
--ipc=host \
|
||||
--cap-add=SYS_PTRACE \
|
||||
--security-opt seccomp=unconfined \
|
||||
--device /dev/kfd \
|
||||
--device /dev/dri \
|
||||
-v <path/to/model>:/app/model \
|
||||
-v ~/.cache/huggingface:/root/.cache/huggingface \
|
||||
--env "HF_TOKEN=$HF_TOKEN" \
|
||||
vllm/vllm-omni-rocm:v0.12.0rc1 \
|
||||
bash
|
||||
```
|
||||
|
||||
# --8<-- [end:pre-built-images]
|
||||
@@ -21,6 +21,7 @@ th {
|
||||
| `Qwen2_5OmniForConditionalGeneration` | Qwen2.5-Omni | `Qwen/Qwen2.5-Omni-7B`, `Qwen/Qwen2.5-Omni-3B` |
|
||||
| `BagelForConditionalGeneration` | BAGEL (DiT-only) | `ByteDance-Seed/BAGEL-7B-MoT` |
|
||||
| `QwenImagePipeline` | Qwen-Image | `Qwen/Qwen-Image` |
|
||||
| `QwenImagePipeline` | Qwen-Image-2512 | `Qwen/Qwen-Image-2512` |
|
||||
| `QwenImageEditPipeline` | Qwen-Image-Edit | `Qwen/Qwen-Image-Edit` |
|
||||
| `QwenImageEditPlusPipeline` | Qwen-Image-Edit-2509 | `Qwen/Qwen-Image-Edit-2509` |
|
||||
| `QwenImageLayeredPipeline` | Qwen-Image-Layered | `Qwen/Qwen-Image-Layered` |
|
||||
@@ -31,6 +32,8 @@ th {
|
||||
|`LongcatImagePipeline` | LongCat-Image | `meituan-longcat/LongCat-Image` |
|
||||
|`LongCatImageEditPipeline` | LongCat-Image-Edit | `meituan-longcat/LongCat-Image-Edit` |
|
||||
|`StableDiffusion3Pipeline` | Stable-Diffusion-3 | `stabilityai/stable-diffusion-3.5-medium` |
|
||||
|`Flux2KleinPipeline` | FLUX.2-klein | `black-forest-labs/FLUX.2-klein-4B`, `black-forest-labs/FLUX.2-klein-9B` |
|
||||
|`StableAudioPipeline` | Stable-Audio-Open | `stabilityai/stable-audio-open-1.0` |
|
||||
|
||||
|
||||
## List of Supported Models for NPU
|
||||
|
||||
File renamed without changes.
@@ -0,0 +1,29 @@
|
||||
# CPU Offloading for Diffusion Model
|
||||
|
||||
## Overview
|
||||
CPU offload lets the diffusion worker move large model components between GPU and CPU memory on demand. It keeps the DiT transformer resident on GPU only while it is actively running, and swaps it out when encoders modules need the device. This reduces peak VRAM usage so bigger checkpoints run on smaller GPUs, or multiple requests can share the same GPU.
|
||||
|
||||
## Execution Model
|
||||
1. Text encoders run on GPU while the DiT transformer is offloaded to CPU.
|
||||
2. Before denoising, weights are prefetched back to GPU, honoring pinned-memory copies for speed.
|
||||
3. After the diffusion step, the transformer returns to CPU and the process repeats as needed.
|
||||
|
||||
Transfers use pinned host buffers, and the worker coordinates swaps via mutex-style hooks so components never compete for memory.
|
||||
|
||||
## Configuration
|
||||
You can enable CPU offload in two ways:
|
||||
|
||||
- **Python API**: set `enable_cpu_offload=True`.
|
||||
|
||||
```python
|
||||
from vllm_omni import Omni
|
||||
|
||||
if __name__ == "__main__":
|
||||
|
||||
m = Omni(model="Qwen/Qwen-Image",enable_cpu_offload=True)
|
||||
```
|
||||
|
||||
- **CLI**: pass `--enable-cpu-offload` to the diffusion service entrypoint.
|
||||
|
||||
## Known Limitations
|
||||
- Cold start latency increases for over one minute for some models(e.g., Qwen-Image)
|
||||
+143
-13
@@ -10,27 +10,58 @@ The following parallelism methods are currently supported in vLLM-Omni:
|
||||
|
||||
2. [Ring-Attention](#ring-attention) - splits the input along the sequence dimension and uses ring-based P2P communication to accumulate attention results, keeping the sequence dimension sharded
|
||||
|
||||
3. Classifier-Free-Guidance Parallel (CFG-Parallel): CFG-Parallel runs the positive/negative prompts of classifier-free guidance (CFG) on different devices, then merges on a single device to perform the scheduler step.
|
||||
|
||||
4. [Tensor Parallelism](#tensor-parallelism): Tensor parallelism shards model weights across devices. This can reduce per-GPU memory usage. Note that for diffusion models we currently shard the majority of layers within the DiT.
|
||||
|
||||
The following table shows which models are currently supported by parallelism method:
|
||||
|
||||
### ImageGen
|
||||
|
||||
| Model | Model Identifier | Ulysses-SP | Ring-SP |
|
||||
|-------|------------------|-----------|---------|
|
||||
| **LongCat-Image** | `meituan-longcat/LongCat-Image` | ❌ | ❌ |
|
||||
| **LongCat-Image-Edit** | `meituan-longcat/LongCat-Image-Edit` | ❌ | ❌ |
|
||||
| **Ovis-Image** | `OvisAI/Ovis-Image` | ❌ | ❌ |
|
||||
| **Qwen-Image** | `Qwen/Qwen-Image` | ✅ | ✅ |
|
||||
| **Qwen-Image-Edit** | `Qwen/Qwen-Image-Edit` | ✅ | ✅ |
|
||||
| **Qwen-Image-Edit-2509** | `Qwen/Qwen-Image-Edit-2509` | ✅ | ✅ |
|
||||
| **Qwen-Image-Layered** | `Qwen/Qwen-Image-Layered` | ✅ | ✅ |
|
||||
| **Z-Image** | `Tongyi-MAI/Z-Image-Turbo` | ❌ | ❌ |
|
||||
| Model | Model Identifier | Ulysses-SP | Ring-SP | CFG-Parallel | Tensor-Parallel |
|
||||
|-------|------------------|------------|---------|--------------|--------------------------|
|
||||
| **LongCat-Image** | `meituan-longcat/LongCat-Image` | ✅ | ✅ | ❌ | ❌ |
|
||||
| **LongCat-Image-Edit** | `meituan-longcat/LongCat-Image-Edit` | ✅ | ✅ | ❌ | ❌ |
|
||||
| **Ovis-Image** | `OvisAI/Ovis-Image` | ❌ | ❌ | ❌ | ❌ |
|
||||
| **Qwen-Image** | `Qwen/Qwen-Image` | ✅ | ✅ | ✅ | ❌ |
|
||||
| **Qwen-Image-Edit** | `Qwen/Qwen-Image-Edit` | ✅ | ✅ | ✅ | ❌ |
|
||||
| **Qwen-Image-Edit-2509** | `Qwen/Qwen-Image-Edit-2509` | ✅ | ✅ | ✅ | ❌ |
|
||||
| **Qwen-Image-Layered** | `Qwen/Qwen-Image-Layered` | ✅ | ✅ | ✅ | ❌ |
|
||||
| **Z-Image** | `Tongyi-MAI/Z-Image-Turbo` | ❌ | ❌ | ❌ | ✅ (TP=2 only) |
|
||||
| **Stable-Diffusion3.5** | `stabilityai/stable-diffusion-3.5` | ❌ | ❌ | ❌ | ❌ |
|
||||
|
||||
!!! note "Why Z-Image is TP=2 only"
|
||||
Z-Image Turbo is currently limited to `tensor_parallel_size` of **1 or 2** due to model shape divisibility constraints.
|
||||
For example, the model has `n_heads=30` and a final projection out dimension of `64`, so valid TP sizes must divide both 30 and 64; the only common divisors are **1 and 2**.
|
||||
|
||||
### VideoGen
|
||||
|
||||
| Model | Model Identifier | Ulysses-SP | Ring-SP |
|
||||
|-------|------------------|-----------|---------|
|
||||
| **Wan2.2** | `Wan-AI/Wan2.2-T2V-A14B-Diffusers` | ❌ | ❌ |
|
||||
| Model | Model Identifier | Ulysses-SP | Ring-SP | Tensor-Parallel |
|
||||
|-------|------------------|------------|---------|--------------------------|
|
||||
| **Wan2.2** | `Wan-AI/Wan2.2-T2V-A14B-Diffusers` | ❌ | ❌ | ❌ |
|
||||
|
||||
### Tensor Parallelism
|
||||
|
||||
Tensor parallelism splits model parameters across GPUs. In vLLM-Omni, tensor parallelism is configured via `DiffusionParallelConfig.tensor_parallel_size`.
|
||||
|
||||
#### Offline Inference
|
||||
|
||||
```python
|
||||
from vllm_omni import Omni
|
||||
from vllm_omni.diffusion.data import DiffusionParallelConfig
|
||||
|
||||
omni = Omni(
|
||||
model="Tongyi-MAI/Z-Image-Turbo",
|
||||
parallel_config=DiffusionParallelConfig(tensor_parallel_size=2),
|
||||
)
|
||||
|
||||
outputs = omni.generate(
|
||||
prompt="a cat reading a book",
|
||||
num_inference_steps=9,
|
||||
width=512,
|
||||
height=512,
|
||||
)
|
||||
```
|
||||
|
||||
### Sequence Parallelism
|
||||
|
||||
@@ -181,6 +212,7 @@ To measure the parallelism methods, we run benchmarks with **Qwen/Qwen-Image** m
|
||||
|
||||
If a diffusion model has been deployed in vLLM-Omni and supports single-card inference, you can refer to the following instructions to parallelize it with [Ulysses-SP](https://arxiv.org/pdf/2309.14509).
|
||||
|
||||
|
||||
This section uses **Qwen-Image** (`QwenImageTransformer2DModel`) as the reference implementation. Qwen-Image is a **dual-stream** transformer (text + image) that performs **joint attention** across the concatenated sequences. Because of that, when enabling sequence parallel you typically:
|
||||
|
||||
- Chunk **image tokens** (`hidden_states`) across SP ranks along the **sequence dimension**.
|
||||
@@ -272,3 +304,101 @@ omni = Omni(
|
||||
|
||||
outputs = omni.generate(prompt="A cat sitting on a windowsill", num_inference_steps=50)
|
||||
```
|
||||
|
||||
|
||||
### CFG-Parallel
|
||||
|
||||
##### Offline Inference
|
||||
|
||||
CFG-Parallel is enabled through `DiffusionParallelConfig(cfg_parallel_size=...)`. The recommended configuration is `cfg_parallel_size=2` (one rank for the positive branch and one rank for the negative branch).
|
||||
|
||||
An example of offline inference using CFG-Parallel (image-to-image) is shown below:
|
||||
|
||||
```python
|
||||
from vllm_omni import Omni
|
||||
from vllm_omni.diffusion.data import DiffusionParallelConfig
|
||||
|
||||
omni = Omni(
|
||||
model="Qwen/Qwen-Image-Edit",
|
||||
parallel_config=DiffusionParallelConfig(cfg_parallel_size=2),
|
||||
)
|
||||
|
||||
outputs = omni.generate(
|
||||
prompt="turn this cat to a dog",
|
||||
negative_prompt="low quality, blurry",
|
||||
true_cfg_scale=4.0,
|
||||
pil_image=input_image,
|
||||
num_inference_steps=50,
|
||||
)
|
||||
```
|
||||
|
||||
Notes:
|
||||
|
||||
- CFG-Parallel is only effective when **true CFG** is enabled (i.e., `true_cfg_scale > 1` and a `negative_prompt` is provided).
|
||||
|
||||
#### How to parallelize a pipeline
|
||||
|
||||
This section describes how to add CFG-Parallel to a diffusion **pipeline**. We use the Qwen-Image pipeline (`vllm_omni/diffusion/models/qwen_image/pipeline_qwen_image.py`) as the reference implementation.
|
||||
|
||||
In `QwenImagePipeline`, each diffusion step runs two denoiser forward passes sequentially:
|
||||
|
||||
- positive (prompt-conditioned)
|
||||
- negative (negative-prompt-conditioned)
|
||||
|
||||
CFG-Parallel assigns these two branches to different ranks in the **CFG group** and synchronizes the results.
|
||||
|
||||
Below is an example of CFG-Parallel implementation:
|
||||
|
||||
```python
|
||||
def diffuse(
|
||||
self,
|
||||
...
|
||||
):
|
||||
# Enable CFG-parallel: rank0 computes positive, rank1 computes negative.
|
||||
cfg_parallel_ready = do_true_cfg and get_classifier_free_guidance_world_size() > 1
|
||||
|
||||
self.transformer.do_true_cfg = do_true_cfg
|
||||
|
||||
if cfg_parallel_ready:
|
||||
cfg_group = get_cfg_group()
|
||||
cfg_rank = get_classifier_free_guidance_rank()
|
||||
|
||||
if cfg_rank == 0:
|
||||
local_pred = self.transformer(
|
||||
hidden_states=latents,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=prompt_embeds_mask,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
else:
|
||||
local_pred = self.transformer(
|
||||
hidden_states=latents,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=negative_prompt_embeds_mask,
|
||||
encoder_hidden_states=negative_prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=negative_txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
|
||||
gathered = cfg_group.all_gather(local_pred, separate_tensors=True)
|
||||
if cfg_rank == 0:
|
||||
noise_pred = gathered[0]
|
||||
neg_noise_pred = gathered[1]
|
||||
comb_pred = neg_noise_pred + true_cfg_scale * (noise_pred - neg_noise_pred)
|
||||
cond_norm = torch.norm(noise_pred, dim=-1, keepdim=True)
|
||||
noise_norm = torch.norm(comb_pred, dim=-1, keepdim=True)
|
||||
noise_pred = comb_pred * (cond_norm / noise_norm)
|
||||
latents = self.scheduler.step(noise_pred, t, latents, return_dict=False)[0]
|
||||
cfg_group.broadcast(latents, src=0)
|
||||
else:
|
||||
# fallback: run positive then negative sequentially on one rank
|
||||
...
|
||||
```
|
||||
File renamed without changes.
@@ -6,18 +6,21 @@ vLLM-Omni supports various cache acceleration methods to speed up diffusion mode
|
||||
|
||||
vLLM-Omni currently supports two main cache acceleration backends:
|
||||
|
||||
1. **[TeaCache](acceleration/teacache.md)** - Hook-based adaptive caching that caches transformer computations when consecutive timesteps are similar
|
||||
2. **[Cache-DiT](acceleration/cache_dit_acceleration.md)** - Library-based acceleration using multiple techniques:
|
||||
1. **[TeaCache](diffusion/teacache.md)** - Hook-based adaptive caching that caches transformer computations when consecutive timesteps are similar
|
||||
2. **[Cache-DiT](diffusion/cache_dit_acceleration.md)** - Library-based acceleration using multiple techniques:
|
||||
- **DBCache** (Dual Block Cache): Caches intermediate transformer block outputs based on residual differences
|
||||
- **TaylorSeer**: Uses Taylor expansion-based forecasting for faster inference
|
||||
- **SCM** (Step Computation Masking): Selectively computes steps based on adaptive masking
|
||||
|
||||
Both methods can provide significant speedups (typically **1.5x-2.0x**) while maintaining high output quality.
|
||||
|
||||
vLLM-Omni also supports the sequence parallelism (SP) for the diffusion model, that includes:
|
||||
vLLM-Omni also supports parallelism methods for diffusion models, including:
|
||||
|
||||
1. [Ulysses-SP](acceleration/parallelism_acceleration.md#ulysses-sp) - splits the input along the sequence dimension and uses all-to-all communication to allow each device to compute only a subset of attention heads.
|
||||
2. [Ring-Attention](acceleration/parallelism_acceleration.md#ring-attention) - splits the input along the sequence dimension and uses ring-based P2P communication to accumulate attention results, keeping the sequence dimension sharded.
|
||||
1. [Ulysses-SP](diffusion/parallelism_acceleration.md#ulysses-sp) - splits the input along the sequence dimension and uses all-to-all communication to allow each device to compute only a subset of attention heads.
|
||||
|
||||
2. [Ring-Attention](diffusion/parallelism_acceleration.md#ring-attention) - splits the input along the sequence dimension and uses ring-based P2P communication to accumulate attention results, keeping the sequence dimension sharded.
|
||||
|
||||
3. [CFG-Parallel](diffusion/parallelism_acceleration.md#cfg-parallel) - runs the positive/negative prompts of classifier-free guidance (CFG) on different devices, then merges on a single device to perform the scheduler step.
|
||||
|
||||
## Quick Comparison
|
||||
|
||||
@@ -34,26 +37,25 @@ The following table shows which models are currently supported by each accelerat
|
||||
|
||||
### ImageGen
|
||||
|
||||
| Model | Model Identifier | TeaCache | Cache-DiT | Ulysses-SP | Ring-Attention |
|
||||
|-------|------------------|----------|-----------|-----------|----------------|
|
||||
| **LongCat-Image** | `meituan-longcat/LongCat-Image` | ❌ | ✅ | ❌ | ❌ |
|
||||
| **LongCat-Image-Edit** | `meituan-longcat/LongCat-Image-Edit` | ❌ | ✅ | ❌ | ❌ |
|
||||
| **Ovis-Image** | `OvisAI/Ovis-Image` | ❌ | ✅ | ❌ | ❌ |
|
||||
| **Qwen-Image** | `Qwen/Qwen-Image` | ✅ | ✅ | ✅ | ✅ |
|
||||
| **Qwen-Image-Edit** | `Qwen/Qwen-Image-Edit` | ✅ | ✅ | ✅ | ✅ |
|
||||
| **Qwen-Image-Edit-2509** | `Qwen/Qwen-Image-Edit-2509` | ❌ | ✅ | ✅ | ✅ |
|
||||
| **Qwen-Image-Layered** | `Qwen/Qwen-Image-Layered` | ❌ | ✅ | ✅ | ✅ |
|
||||
| **Z-Image** | `Tongyi-MAI/Z-Image-Turbo` | ❌ | ✅ |❌ | ❌ |
|
||||
| **LongCat-Image** | `meituan-longcat/LongCat-Image` | ❌ | ✅ | ❌ | ❌ |
|
||||
| **LongCat-Image-Edit** | `meituan-longcat/LongCat-Image-Edit` | ❌ | ✅ | ❌ | ❌ |
|
||||
| **Ovis-Image** | `OvisAI/Ovis-Image` | ❌ | ✅ | ❌ | ❌ |
|
||||
| **Stable-Diffusion3.5** | `stabilityai/stable-diffusion-3.5` | ❌ | ✅ | ❌ | ❌ |
|
||||
| Model | Model Identifier | TeaCache | Cache-DiT | Ulysses-SP | Ring-Attention | CFG-Parallel |
|
||||
|-------|------------------|:----------:|:-----------:|:-----------:|:----------------:|:----------------:|
|
||||
| **LongCat-Image** | `meituan-longcat/LongCat-Image` | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| **LongCat-Image-Edit** | `meituan-longcat/LongCat-Image-Edit` | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| **Ovis-Image** | `OvisAI/Ovis-Image` | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| **Qwen-Image** | `Qwen/Qwen-Image` | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| **Qwen-Image-2512** | `Qwen/Qwen-Image-2512` | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| **Qwen-Image-Edit** | `Qwen/Qwen-Image-Edit` | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| **Qwen-Image-Edit-2509** | `Qwen/Qwen-Image-Edit-2509` | ✅ | ✅ | ✅ | ✅ | ✅ |
|
||||
| **Qwen-Image-Layered** | `Qwen/Qwen-Image-Layered` | ❌ | ✅ | ✅ | ✅ | ✅ |
|
||||
| **Z-Image** | `Tongyi-MAI/Z-Image-Turbo` | ❌ | ✅ |❌ | ❌ | ❌ |
|
||||
| **Stable-Diffusion3.5** | `stabilityai/stable-diffusion-3.5` | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
| **Bagel** | `ByteDance-Seed/BAGEL-7B-MoT` | ❌ | ✅ | ❌ | ❌ | ❌ |
|
||||
|
||||
### VideoGen
|
||||
|
||||
| Model | Model Identifier | TeaCache | Cache-DiT | Ulysses-SP |
|
||||
|-------|------------------|----------|-----------|-----------|
|
||||
| **Wan2.2** | `Wan-AI/Wan2.2-T2V-A14B-Diffusers` | ❌ | ✅ | ❌ |
|
||||
| Model | Model Identifier | TeaCache | Cache-DiT | Ulysses-SP | Ring-Attention |
|
||||
|-------|------------------|:--------:|:---------:|:----------:|:--------------:|
|
||||
| **Wan2.2** | `Wan-AI/Wan2.2-T2V-A14B-Diffusers` | ❌ | ✅ | ❌ | ❌ |
|
||||
|
||||
|
||||
## Performance Benchmarks
|
||||
@@ -134,7 +136,7 @@ ulysses_degree = 2
|
||||
|
||||
omni = Omni(
|
||||
model="Qwen/Qwen-Image",
|
||||
parallel_config=DiffusionParallelConfig(ulysses_degree=2)
|
||||
parallel_config=DiffusionParallelConfig(ulysses_degree=ulysses_degree)
|
||||
)
|
||||
|
||||
outputs = omni.generate(prompt="A cat sitting on a windowsill", num_inference_steps=50, width=2048, height=2048)
|
||||
@@ -149,7 +151,7 @@ ulysses_degree = 2
|
||||
|
||||
omni = Omni(
|
||||
model="Qwen/Qwen-Image-Edit",
|
||||
parallel_config=DiffusionParallelConfig(ulysses_degree=2)
|
||||
parallel_config=DiffusionParallelConfig(ulysses_degree=ulysses_degree)
|
||||
)
|
||||
|
||||
outputs = omni.generate(prompt="turn this cat to a dog",
|
||||
@@ -172,10 +174,31 @@ omni = Omni(
|
||||
outputs = omni.generate(prompt="A cat sitting on a windowsill", num_inference_steps=50, width=2048, height=2048)
|
||||
```
|
||||
|
||||
### Using CFG-Parallel
|
||||
|
||||
Run image-to-image:
|
||||
|
||||
CFG-Parallel splits the CFG positive/negative branches across GPUs. Use it when you set a non-trivial `true_cfg_scale`.
|
||||
|
||||
```python
|
||||
from vllm_omni import Omni
|
||||
from vllm_omni.diffusion.data import DiffusionParallelConfig
|
||||
cfg_parallel_size = 2
|
||||
|
||||
omni = Omni(
|
||||
model="Qwen/Qwen-Image-Edit",
|
||||
parallel_config=DiffusionParallelConfig(cfg_parallel_size=cfg_parallel_size)
|
||||
)
|
||||
|
||||
outputs = omni.generate(prompt="turn this cat to a dog",
|
||||
pil_image=input_image, num_inference_steps=50, true_cfg_scale=4.0)
|
||||
```
|
||||
|
||||
## Documentation
|
||||
|
||||
For detailed information on each acceleration method:
|
||||
|
||||
- **[TeaCache Guide](acceleration/teacache.md)** - Complete TeaCache documentation, configuration options, and best practices
|
||||
- **[Cache-DiT Acceleration Guide](acceleration/cache_dit_acceleration.md)** - Comprehensive Cache-DiT guide covering DBCache, TaylorSeer, SCM, and configuration parameters
|
||||
- **[Sequence Parallelism](acceleration/parallelism_acceleration.md#sequence-parallelism)** - Guidance on how to set sequence parallelism with configuration.
|
||||
- **[TeaCache Guide](diffusion/teacache.md)** - Complete TeaCache documentation, configuration options, and best practices
|
||||
- **[Cache-DiT Acceleration Guide](diffusion/cache_dit_acceleration.md)** - Comprehensive Cache-DiT guide covering DBCache, TaylorSeer, SCM, and configuration parameters
|
||||
- **[Sequence Parallelism](diffusion/parallelism_acceleration.md#sequence-parallelism)** - Guidance on how to set sequence parallelism with configuration.
|
||||
- **[CFG-Parallel](diffusion/parallelism_acceleration.md#cfg-parallel)** - Guidance on how to set CFG-Parallel to run positive/negative branches across ranks.
|
||||
@@ -0,0 +1,66 @@
|
||||
# Image-To-Video
|
||||
|
||||
Source <https://github.com/vllm-project/vllm-omni/tree/main/examples/offline_inference/image_to_video>.
|
||||
|
||||
|
||||
This example demonstrates how to generate videos from images using Wan2.2 Image-to-Video models with vLLM-Omni's offline inference API.
|
||||
|
||||
## Local CLI Usage
|
||||
|
||||
### Wan2.2-I2V-A14B-Diffusers (MoE)
|
||||
```bash
|
||||
python image_to_video.py \
|
||||
--model Wan-AI/Wan2.2-I2V-A14B-Diffusers \
|
||||
--image input.png \
|
||||
--prompt "A cat playing with yarn, smooth motion" \
|
||||
--negative_prompt "<optional quality filter>" \
|
||||
--height 480 \
|
||||
--width 832 \
|
||||
--num_frames 48 \
|
||||
--guidance_scale 5.0 \
|
||||
--guidance_scale_high 6.0 \
|
||||
--num_inference_steps 40 \
|
||||
--boundary_ratio 0.875 \
|
||||
--flow_shift 12.0 \
|
||||
--fps 16 \
|
||||
--output i2v_output.mp4
|
||||
```
|
||||
|
||||
### Wan2.2-TI2V-5B-Diffusers (Unified)
|
||||
```bash
|
||||
python image_to_video.py \
|
||||
--model Wan-AI/Wan2.2-TI2V-5B-Diffusers \
|
||||
--image input.png \
|
||||
--prompt "A cat playing with yarn, smooth motion" \
|
||||
--negative_prompt "<optional quality filter>" \
|
||||
--height 480 \
|
||||
--width 832 \
|
||||
--num_frames 48 \
|
||||
--guidance_scale 4.0 \
|
||||
--num_inference_steps 40 \
|
||||
--flow_shift 12.0 \
|
||||
--fps 16 \
|
||||
--output i2v_output.mp4
|
||||
```
|
||||
|
||||
Key arguments:
|
||||
|
||||
- `--model`: Model ID (I2V-A14B for MoE, TI2V-5B for unified T2V+I2V).
|
||||
- `--image`: Path to input image (required).
|
||||
- `--prompt`: Text description of desired motion/animation.
|
||||
- `--height/--width`: Output resolution (auto-calculated from image if not set). Dimensions should be multiples of 16.
|
||||
- `--num_frames`: Number of frames (default 81).
|
||||
- `--guidance_scale` and `--guidance_scale_high`: CFG scale (applied to low/high-noise stages for MoE).
|
||||
- `--negative_prompt`: Optional list of artifacts to suppress.
|
||||
- `--boundary_ratio`: Boundary split ratio for two-stage MoE models.
|
||||
- `--flow_shift`: Scheduler flow shift (5.0 for 720p, 12.0 for 480p).
|
||||
- `--num_inference_steps`: Number of denoising steps (default 50).
|
||||
- `--fps`: Frames per second for the saved MP4 (requires `diffusers` export_to_video).
|
||||
- `--output`: Path to save the generated video.
|
||||
|
||||
## Example materials
|
||||
|
||||
??? abstract "image_to_video.py"
|
||||
``````py
|
||||
--8<-- "examples/offline_inference/image_to_video/image_to_video.py"
|
||||
``````
|
||||
@@ -2,6 +2,7 @@
|
||||
|
||||
Source <https://github.com/vllm-project/vllm-omni/tree/main/examples/offline_inference/qwen2_5_omni>.
|
||||
|
||||
|
||||
## Setup
|
||||
Please refer to the [stage configuration documentation](https://docs.vllm.ai/projects/vllm-omni/en/latest/configuration/stage_configs/) to configure memory allocation appropriately for your hardware setup.
|
||||
|
||||
|
||||
@@ -2,6 +2,7 @@
|
||||
|
||||
Source <https://github.com/vllm-project/vllm-omni/tree/main/examples/offline_inference/qwen3_omni>.
|
||||
|
||||
|
||||
## Setup
|
||||
Please refer to the [stage configuration documentation](https://docs.vllm.ai/projects/vllm-omni/en/latest/configuration/stage_configs/) to configure memory allocation appropriately for your hardware setup.
|
||||
|
||||
|
||||
@@ -1,7 +0,0 @@
|
||||
# Gradio Demo
|
||||
|
||||
Source <https://github.com/vllm-project/vllm-omni/blob/main/examples/online_serving/gradio_demo.py>.
|
||||
|
||||
``````py
|
||||
--8<-- "examples/online_serving/gradio_demo.py"
|
||||
``````
|
||||
@@ -230,6 +230,10 @@ Provide multiple images in `content` (order matters):
|
||||
``````py
|
||||
--8<-- "examples/online_serving/image_to_image/openai_chat_client.py"
|
||||
``````
|
||||
??? abstract "run_curl_image_edit.sh"
|
||||
``````sh
|
||||
--8<-- "examples/online_serving/image_to_image/run_curl_image_edit.sh"
|
||||
``````
|
||||
??? abstract "run_server.sh"
|
||||
``````sh
|
||||
--8<-- "examples/online_serving/image_to_image/run_server.sh"
|
||||
|
||||
-7
@@ -1,7 +0,0 @@
|
||||
# OpenAI Chat Completion Client For Multimodal Generation
|
||||
|
||||
Source <https://github.com/vllm-project/vllm-omni/blob/main/examples/online_serving/openai_chat_completion_client_for_multimodal_generation.py>.
|
||||
|
||||
``````py
|
||||
--8<-- "examples/online_serving/openai_chat_completion_client_for_multimodal_generation.py"
|
||||
``````
|
||||
@@ -137,6 +137,7 @@ response = client.chat.completions.create(
|
||||
# Response contains two choices: one with text, one with audio
|
||||
print(response.choices[0].message.content) # Text response
|
||||
print(response.choices[1].message.audio) # Audio response
|
||||
```
|
||||
|
||||
## Streaming Output
|
||||
If you want to enable streaming output, please set the argument as below. The final output will be obtained just after generated by corresponding stage. Now we only support text streaming output. Other modalities can output normally.
|
||||
|
||||
@@ -145,6 +145,7 @@ response = client.chat.completions.create(
|
||||
# Response contains two choices: one with text, one with audio
|
||||
print(response.choices[0].message.content) # Text response
|
||||
print(response.choices[1].message.audio) # Audio response
|
||||
```
|
||||
|
||||
## Streaming Output
|
||||
If you want to enable streaming output, please set the argument as below. The final output will be obtained just after generated by corresponding stage. Now we only support text streaming output. Other modalities can output normally.
|
||||
|
||||
@@ -12,6 +12,8 @@ This example demonstrates how to deploy Qwen-Image model for online image genera
|
||||
```bash
|
||||
vllm serve Qwen/Qwen-Image --omni --port 8091
|
||||
```
|
||||
!!! note
|
||||
If you encounter Out-of-Memory (OOM) issues or have limited GPU memory, you can enable VAE slicing and tiling to reduce memory usage, --vae-use-slicing --vae-use-tiling
|
||||
|
||||
### Start with Parameters
|
||||
|
||||
@@ -43,7 +45,7 @@ curl -s http://localhost:8091/v1/chat/completions \
|
||||
"true_cfg_scale": 4.0,
|
||||
"seed": 42
|
||||
}
|
||||
}' | jq -r '.choices[0].message.content[0].image_url.url' | cut -d',' -f2 | base64 -d > output.png
|
||||
}' | jq -r '.choices[0].message.content[0].image_url.url' | cut -d',' -f2- | base64 -d > output.png
|
||||
```
|
||||
|
||||
### Method 2: Using Python Client
|
||||
@@ -146,7 +148,7 @@ Use `extra_body` to pass generation parameters:
|
||||
|
||||
```bash
|
||||
# Extract base64 from response and decode to image
|
||||
cat response.json | jq -r '.choices[0].message.content[0].image_url.url' | cut -d',' -f2 | base64 -d > output.png
|
||||
cat response.json | jq -r '.choices[0].message.content[0].image_url.url' | cut -d',' -f2- | base64 -d > output.png
|
||||
```
|
||||
|
||||
## File Description
|
||||
|
||||
@@ -49,6 +49,22 @@ Usage (layered):
|
||||
--layers 4 \
|
||||
--color-format "RGBA"
|
||||
|
||||
Usage (with CFG Parallel):
|
||||
python image_edit.py \
|
||||
--image input.png \
|
||||
--prompt "Edit description" \
|
||||
--cfg_parallel_size 2 \
|
||||
--num_inference_steps 50 \
|
||||
--cfg_scale 4.0
|
||||
|
||||
Usage (disable torch.compile):
|
||||
python image_edit.py \
|
||||
--image input.png \
|
||||
--prompt "Edit description" \
|
||||
--enforce_eager \
|
||||
--num_inference_steps 50 \
|
||||
--cfg_scale 4.0
|
||||
|
||||
For more options, run:
|
||||
python image_edit.py --help
|
||||
"""
|
||||
@@ -245,7 +261,18 @@ def parse_args() -> argparse.Namespace:
|
||||
default=0.2,
|
||||
help="[tea_cache] Threshold for accumulated relative L1 distance.",
|
||||
)
|
||||
|
||||
parser.add_argument(
|
||||
"--cfg_parallel_size",
|
||||
type=int,
|
||||
default=1,
|
||||
choices=[1, 2],
|
||||
help="Number of GPUs used for classifier free guidance parallel size.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--enforce_eager",
|
||||
action="store_true",
|
||||
help="Disable torch.compile and force eager execution.",
|
||||
)
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
@@ -273,7 +300,10 @@ def main():
|
||||
# Enable VAE memory optimizations on NPU
|
||||
vae_use_slicing = is_npu()
|
||||
vae_use_tiling = is_npu()
|
||||
parallel_config = DiffusionParallelConfig(ulysses_degree=args.ulysses_degree, ring_degree=args.ring_degree)
|
||||
parallel_config = DiffusionParallelConfig(
|
||||
ulysses_degree=args.ulysses_degree, ring_degree=args.ring_degree, cfg_parallel_size=args.cfg_parallel_size
|
||||
)
|
||||
|
||||
# Configure cache based on backend type
|
||||
cache_config = None
|
||||
if args.cache_backend == "cache_dit":
|
||||
@@ -304,6 +334,7 @@ def main():
|
||||
cache_backend=args.cache_backend,
|
||||
cache_config=cache_config,
|
||||
parallel_config=parallel_config,
|
||||
enforce_eager=args.enforce_eager,
|
||||
)
|
||||
print("Pipeline loaded")
|
||||
|
||||
@@ -319,7 +350,9 @@ def main():
|
||||
print(f" Image {idx + 1} size: {img.size}")
|
||||
else:
|
||||
print(f" Input image size: {input_image.size}")
|
||||
print(f" Parallel configuration: ulysses_degree={args.ulysses_degree}, ring_degree={args.ring_degree}")
|
||||
print(
|
||||
f" Parallel configuration: ulysses_degree={args.ulysses_degree}, ring_degree={args.ring_degree}, cfg_parallel_size={args.cfg_parallel_size}"
|
||||
)
|
||||
print(f"{'=' * 60}\n")
|
||||
|
||||
generation_start = time.perf_counter()
|
||||
|
||||
@@ -0,0 +1,200 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
|
||||
"""
|
||||
Example script for text-to-audio generation using Stable Audio Open.
|
||||
|
||||
This script demonstrates how to generate audio from text prompts using
|
||||
the Stable Audio Open model with vLLM-Omni.
|
||||
|
||||
Usage:
|
||||
python text_to_audio.py --prompt "The sound of a dog barking"
|
||||
python text_to_audio.py --prompt "A piano playing a gentle melody" --audio_length 10.0
|
||||
python text_to_audio.py --prompt "Thunder and rain sounds" --negative_prompt "Low quality"
|
||||
"""
|
||||
|
||||
import argparse
|
||||
import time
|
||||
from pathlib import Path
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
|
||||
from vllm_omni.entrypoints.omni import Omni
|
||||
from vllm_omni.utils.platform_utils import detect_device_type
|
||||
|
||||
|
||||
def parse_args() -> argparse.Namespace:
|
||||
parser = argparse.ArgumentParser(description="Generate audio with Stable Audio Open.")
|
||||
parser.add_argument(
|
||||
"--model",
|
||||
default="stabilityai/stable-audio-open-1.0",
|
||||
help="Stable Audio model name or local path.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--prompt",
|
||||
default="The sound of a hammer hitting a wooden surface.",
|
||||
help="Text prompt for audio generation.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--negative_prompt",
|
||||
default="Low quality.",
|
||||
help="Negative prompt for classifier-free guidance.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--seed",
|
||||
type=int,
|
||||
default=42,
|
||||
help="Random seed for deterministic results.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--guidance_scale",
|
||||
type=float,
|
||||
default=7.0,
|
||||
help="Classifier-free guidance scale.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--audio_start",
|
||||
type=float,
|
||||
default=0.0,
|
||||
help="Audio start time in seconds.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--audio_length",
|
||||
type=float,
|
||||
default=10.0,
|
||||
help="Audio length in seconds (max ~47s for stable-audio-open-1.0).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--num_inference_steps",
|
||||
type=int,
|
||||
default=100,
|
||||
help="Number of denoising steps for the diffusion sampler.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--num_waveforms",
|
||||
type=int,
|
||||
default=1,
|
||||
help="Number of audio waveforms to generate for the given prompt.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--output",
|
||||
type=str,
|
||||
default="stable_audio_output.wav",
|
||||
help="Path to save the generated audio (WAV format).",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--sample_rate",
|
||||
type=int,
|
||||
default=44100,
|
||||
help="Sample rate for output audio (Stable Audio uses 44100 Hz).",
|
||||
)
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
def save_audio(audio_data: np.ndarray, output_path: str, sample_rate: int = 44100):
|
||||
"""Save audio data to a WAV file."""
|
||||
try:
|
||||
import soundfile as sf
|
||||
|
||||
sf.write(output_path, audio_data, sample_rate)
|
||||
except ImportError:
|
||||
try:
|
||||
import scipy.io.wavfile as wav
|
||||
|
||||
# Ensure audio is in the correct format for scipy
|
||||
if audio_data.dtype == np.float32 or audio_data.dtype == np.float64:
|
||||
# Normalize to int16 range
|
||||
audio_data = np.clip(audio_data, -1.0, 1.0)
|
||||
audio_data = (audio_data * 32767).astype(np.int16)
|
||||
wav.write(output_path, sample_rate, audio_data)
|
||||
except ImportError:
|
||||
raise ImportError(
|
||||
"Either 'soundfile' or 'scipy' is required to save audio files. "
|
||||
"Install with: pip install soundfile or pip install scipy"
|
||||
)
|
||||
|
||||
|
||||
def main():
|
||||
args = parse_args()
|
||||
device = detect_device_type()
|
||||
generator = torch.Generator(device=device).manual_seed(args.seed)
|
||||
|
||||
print(f"\n{'=' * 60}")
|
||||
print("Stable Audio Open - Text-to-Audio Generation")
|
||||
print(f"{'=' * 60}")
|
||||
print(f" Model: {args.model}")
|
||||
print(f" Prompt: {args.prompt}")
|
||||
print(f" Negative prompt: {args.negative_prompt}")
|
||||
print(f" Audio length: {args.audio_length}s")
|
||||
print(f" Inference steps: {args.num_inference_steps}")
|
||||
print(f" Guidance scale: {args.guidance_scale}")
|
||||
print(f" Seed: {args.seed}")
|
||||
print(f"{'=' * 60}\n")
|
||||
|
||||
# Initialize Omni with Stable Audio model
|
||||
omni = Omni(model=args.model)
|
||||
|
||||
# Calculate audio end time
|
||||
audio_end_in_s = args.audio_start + args.audio_length
|
||||
|
||||
# Time profiling for generation
|
||||
generation_start = time.perf_counter()
|
||||
|
||||
# Generate audio
|
||||
audio = omni.generate(
|
||||
args.prompt,
|
||||
negative_prompt=args.negative_prompt,
|
||||
generator=generator,
|
||||
guidance_scale=args.guidance_scale,
|
||||
num_inference_steps=args.num_inference_steps,
|
||||
num_outputs_per_prompt=args.num_waveforms,
|
||||
extra={
|
||||
"audio_start_in_s": args.audio_start,
|
||||
"audio_end_in_s": audio_end_in_s,
|
||||
},
|
||||
)
|
||||
|
||||
generation_end = time.perf_counter()
|
||||
generation_time = generation_end - generation_start
|
||||
|
||||
print(f"Total generation time: {generation_time:.2f} seconds")
|
||||
|
||||
# Process and save audio
|
||||
output_path = Path(args.output)
|
||||
output_path.parent.mkdir(parents=True, exist_ok=True)
|
||||
suffix = output_path.suffix or ".wav"
|
||||
stem = output_path.stem or "stable_audio_output"
|
||||
|
||||
# Handle different output formats
|
||||
if isinstance(audio, torch.Tensor):
|
||||
audio = audio.cpu().float().numpy()
|
||||
|
||||
# Audio shape is typically [batch, channels, samples] or [channels, samples]
|
||||
if audio.ndim == 3:
|
||||
# [batch, channels, samples]
|
||||
if args.num_waveforms <= 1:
|
||||
audio_data = audio[0].T # [samples, channels]
|
||||
save_audio(audio_data, str(output_path), args.sample_rate)
|
||||
print(f"Saved generated audio to {output_path}")
|
||||
else:
|
||||
for idx in range(audio.shape[0]):
|
||||
audio_data = audio[idx].T # [samples, channels]
|
||||
save_path = output_path.parent / f"{stem}_{idx}{suffix}"
|
||||
save_audio(audio_data, str(save_path), args.sample_rate)
|
||||
print(f"Saved generated audio to {save_path}")
|
||||
elif audio.ndim == 2:
|
||||
# [channels, samples]
|
||||
audio_data = audio.T # [samples, channels]
|
||||
save_audio(audio_data, str(output_path), args.sample_rate)
|
||||
print(f"Saved generated audio to {output_path}")
|
||||
else:
|
||||
# [samples] - mono audio
|
||||
save_audio(audio, str(output_path), args.sample_rate)
|
||||
print(f"Saved generated audio to {output_path}")
|
||||
|
||||
print(f"\nGenerated {args.audio_length}s of audio at {args.sample_rate} Hz")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
main()
|
||||
@@ -81,6 +81,24 @@ def parse_args() -> argparse.Namespace:
|
||||
default=1,
|
||||
help="Number of GPUs used for ring sequence parallelism.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--cfg_parallel_size",
|
||||
type=int,
|
||||
default=1,
|
||||
choices=[1, 2],
|
||||
help="Number of GPUs used for classifier free guidance parallel size.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--enforce_eager",
|
||||
action="store_true",
|
||||
help="Disable torch.compile and force eager execution.",
|
||||
)
|
||||
parser.add_argument(
|
||||
"--tensor_parallel_size",
|
||||
type=int,
|
||||
default=1,
|
||||
help="Number of GPUs used for tensor parallelism (TP) inside the DiT.",
|
||||
)
|
||||
return parser.parse_args()
|
||||
|
||||
|
||||
@@ -123,7 +141,13 @@ def main():
|
||||
}
|
||||
|
||||
# assert args.ring_degree == 1, "Ring attention is not supported yet"
|
||||
parallel_config = DiffusionParallelConfig(ulysses_degree=args.ulysses_degree, ring_degree=args.ring_degree)
|
||||
parallel_config = DiffusionParallelConfig(
|
||||
ulysses_degree=args.ulysses_degree,
|
||||
ring_degree=args.ring_degree,
|
||||
cfg_parallel_size=args.cfg_parallel_size,
|
||||
tensor_parallel_size=args.tensor_parallel_size,
|
||||
)
|
||||
|
||||
omni = Omni(
|
||||
model=args.model,
|
||||
vae_use_slicing=vae_use_slicing,
|
||||
@@ -131,6 +155,7 @@ def main():
|
||||
cache_backend=args.cache_backend,
|
||||
cache_config=cache_config,
|
||||
parallel_config=parallel_config,
|
||||
enforce_eager=args.enforce_eager,
|
||||
)
|
||||
|
||||
# Time profiling for generation
|
||||
@@ -139,7 +164,10 @@ def main():
|
||||
print(f" Model: {args.model}")
|
||||
print(f" Inference steps: {args.num_inference_steps}")
|
||||
print(f" Cache backend: {args.cache_backend if args.cache_backend else 'None (no acceleration)'}")
|
||||
print(f" Parallel configuration: ulysses_degree={args.ulysses_degree}, ring_degree={args.ring_degree}")
|
||||
print(
|
||||
f" Parallel configuration: tensor_parallel_size={args.tensor_parallel_size}, "
|
||||
f"ulysses_degree={args.ulysses_degree}, ring_degree={args.ring_degree}, cfg_parallel_size={args.cfg_parallel_size}"
|
||||
)
|
||||
print(f" Image size: {args.width}x{args.height}")
|
||||
print(f"{'=' * 60}\n")
|
||||
|
||||
|
||||
@@ -127,7 +127,7 @@ def main():
|
||||
parser.add_argument("--width", type=int, default=1024, help="Output image width")
|
||||
parser.add_argument("--steps", type=int, default=50, help="Inference steps")
|
||||
parser.add_argument("--guidance", type=float, default=7.5, help="Guidance scale")
|
||||
parser.add_argument("--seed", type=int, help="Random seed")
|
||||
parser.add_argument("--seed", type=int, default=0, help="Random seed")
|
||||
parser.add_argument("--negative", help="Negative prompt")
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
@@ -134,6 +134,7 @@ response = client.chat.completions.create(
|
||||
# Response contains two choices: one with text, one with audio
|
||||
print(response.choices[0].message.content) # Text response
|
||||
print(response.choices[1].message.audio) # Audio response
|
||||
```
|
||||
|
||||
## Streaming Output
|
||||
If you want to enable streaming output, please set the argument as below. The final output will be obtained just after generated by corresponding stage. Now we only support text streaming output. Other modalities can output normally.
|
||||
|
||||
@@ -142,6 +142,7 @@ response = client.chat.completions.create(
|
||||
# Response contains two choices: one with text, one with audio
|
||||
print(response.choices[0].message.content) # Text response
|
||||
print(response.choices[1].message.audio) # Audio response
|
||||
```
|
||||
|
||||
## Streaming Output
|
||||
If you want to enable streaming output, please set the argument as below. The final output will be obtained just after generated by corresponding stage. Now we only support text streaming output. Other modalities can output normally.
|
||||
|
||||
@@ -9,6 +9,8 @@ This example demonstrates how to deploy Qwen-Image model for online image genera
|
||||
```bash
|
||||
vllm serve Qwen/Qwen-Image --omni --port 8091
|
||||
```
|
||||
!!! note
|
||||
If you encounter Out-of-Memory (OOM) issues or have limited GPU memory, you can enable VAE slicing and tiling to reduce memory usage, --vae-use-slicing --vae-use-tiling
|
||||
|
||||
### Start with Parameters
|
||||
|
||||
@@ -40,7 +42,7 @@ curl -s http://localhost:8091/v1/chat/completions \
|
||||
"true_cfg_scale": 4.0,
|
||||
"seed": 42
|
||||
}
|
||||
}' | jq -r '.choices[0].message.content[0].image_url.url' | cut -d',' -f2 | base64 -d > output.png
|
||||
}' | jq -r '.choices[0].message.content[0].image_url.url' | cut -d',' -f2- | base64 -d > output.png
|
||||
```
|
||||
|
||||
### Method 2: Using Python Client
|
||||
@@ -143,7 +145,7 @@ Use `extra_body` to pass generation parameters:
|
||||
|
||||
```bash
|
||||
# Extract base64 from response and decode to image
|
||||
cat response.json | jq -r '.choices[0].message.content[0].image_url.url' | cut -d',' -f2 | base64 -d > output.png
|
||||
cat response.json | jq -r '.choices[0].message.content[0].image_url.url' | cut -d',' -f2- | base64 -d > output.png
|
||||
```
|
||||
|
||||
## File Description
|
||||
|
||||
@@ -100,7 +100,7 @@ def main():
|
||||
parser.add_argument("--width", type=int, default=1024, help="Image width")
|
||||
parser.add_argument("--steps", type=int, default=50, help="Inference steps")
|
||||
parser.add_argument("--cfg-scale", type=float, default=4.0, help="True CFG scale")
|
||||
parser.add_argument("--seed", type=int, default=42, help="Random seed")
|
||||
parser.add_argument("--seed", type=int, default=0, help="Random seed")
|
||||
parser.add_argument("--negative", help="Negative prompt")
|
||||
|
||||
args = parser.parse_args()
|
||||
|
||||
@@ -60,6 +60,10 @@ hooks:
|
||||
- docs/mkdocs/hooks/url_schemes.py
|
||||
- docs/mkdocs/hooks/generate_examples.py
|
||||
|
||||
# Exclude include files from navigation warnings
|
||||
exclude_docs: |
|
||||
**/*.inc.md
|
||||
|
||||
# Plugins
|
||||
plugins:
|
||||
- meta
|
||||
|
||||
+30
-4
@@ -38,6 +38,7 @@ dependencies = [
|
||||
"soundfile>=0.13.1",
|
||||
"cache-dit==1.1.8",
|
||||
"tqdm>=4.66.0",
|
||||
"torchsde>=0.2.6", # Required for Stable Audio scheduler
|
||||
# "vllm==0.12.0", # TODO: fix the entrypoints overwrite problem
|
||||
]
|
||||
|
||||
@@ -49,6 +50,8 @@ dev = [
|
||||
"pytest-cov>=4.0.0",
|
||||
"mypy==1.11.1",
|
||||
"pre-commit==4.0.1",
|
||||
"openai-whisper>=20250625",
|
||||
"psutil>=7.2.0"
|
||||
]
|
||||
|
||||
docs = [
|
||||
@@ -150,11 +153,34 @@ addopts = [
|
||||
"--cov-report=xml",
|
||||
]
|
||||
markers = [
|
||||
"unit: Unit tests",
|
||||
"integration: Integration tests",
|
||||
# ci/cd required
|
||||
"core_model: Core model tests (run in each PR)",
|
||||
# function module markers
|
||||
"diffusion: Diffusion model tests",
|
||||
"omni: Omni model tests",
|
||||
"cache: Cache backend tests",
|
||||
"parallel: Parallelism/distributed tests",
|
||||
# platform markers
|
||||
"cpu: Tests that run on CPU",
|
||||
"gpu: Tests that run on GPU (auto-added)",
|
||||
"cuda: Tests that run on CUDA (auto-added)",
|
||||
"rocm: Tests that run on AMD/ROCm (auto-added)",
|
||||
"npu: Tests that run on NPU/Ascend (auto-added)",
|
||||
# specified computation resources marks (auto-added)
|
||||
"H100: Tests that require H100 GPU",
|
||||
"L4: Tests that require L4 GPU",
|
||||
"MI325: Tests that require MI325 GPU (AMD/ROCm)",
|
||||
"A2: Tests that require A2 NPU",
|
||||
"A3: Tests that require A3 NPU",
|
||||
"distributed_cuda: Tests that require multi cards on CUDA platform",
|
||||
"distributed_rocm: Tests that require multi cards on ROCm platform",
|
||||
"distributed_npu: Tests that require multi cards on NPU platform",
|
||||
"skipif_cuda: Skip if the num of CUDA cards is less than the required",
|
||||
"skipif_rocm: Skip if the num of ROCm cards is less than the required",
|
||||
"skipif_npu: Skip if the num of NPU cards is less than the required",
|
||||
# more detailed markers
|
||||
"slow: Slow tests (may skip in quick CI)",
|
||||
"benchmark: Benchmark tests",
|
||||
"slow: Slow tests",
|
||||
"core_model: enable this model test in each PR instead of only nightly",
|
||||
]
|
||||
|
||||
[tool.typos.default]
|
||||
|
||||
@@ -1,3 +0,0 @@
|
||||
[pytest]
|
||||
markers =
|
||||
gpu_mem_high: needs high VRAM
|
||||
@@ -1,8 +1,19 @@
|
||||
import base64
|
||||
import os
|
||||
import socket
|
||||
import subprocess
|
||||
import sys
|
||||
import time
|
||||
from pathlib import Path
|
||||
from typing import Any
|
||||
|
||||
import psutil
|
||||
import pytest
|
||||
import torch
|
||||
import whisper
|
||||
import yaml
|
||||
from vllm.logger import init_logger
|
||||
from vllm.utils import get_open_port
|
||||
|
||||
logger = init_logger(__name__)
|
||||
|
||||
@@ -34,3 +45,286 @@ def clean_gpu_memory_between_tests():
|
||||
if torch.cuda.is_available():
|
||||
torch.cuda.empty_cache()
|
||||
gc.collect()
|
||||
|
||||
|
||||
def dummy_messages_from_mix_data(
|
||||
system_prompt: dict[str, Any] = None,
|
||||
video_data_url: Any = None,
|
||||
audio_data_url: Any = None,
|
||||
image_data_url: Any = None,
|
||||
content_text: str = None,
|
||||
):
|
||||
"""Create messages with video、image、audio data URL for OpenAI API."""
|
||||
|
||||
if content_text is not None:
|
||||
content = [{"type": "text", "text": content_text}]
|
||||
else:
|
||||
content = []
|
||||
|
||||
media_items = []
|
||||
if isinstance(video_data_url, list):
|
||||
for video_url in video_data_url:
|
||||
media_items.append((video_url, "video"))
|
||||
else:
|
||||
media_items.append((video_data_url, "video"))
|
||||
|
||||
if isinstance(image_data_url, list):
|
||||
for url in image_data_url:
|
||||
media_items.append((url, "image"))
|
||||
else:
|
||||
media_items.append((image_data_url, "image"))
|
||||
|
||||
if isinstance(audio_data_url, list):
|
||||
for url in audio_data_url:
|
||||
media_items.append((url, "audio"))
|
||||
else:
|
||||
media_items.append((audio_data_url, "audio"))
|
||||
|
||||
content.extend(
|
||||
{"type": f"{media_type}_url", f"{media_type}_url": {"url": url}}
|
||||
for url, media_type in media_items
|
||||
if url is not None
|
||||
)
|
||||
messages = [{"role": "user", "content": content}]
|
||||
if system_prompt is not None:
|
||||
messages = [system_prompt] + messages
|
||||
return messages
|
||||
|
||||
|
||||
def cosine_similarity_text(s1, s2):
|
||||
"""
|
||||
Calculate cosine similarity between two text strings.
|
||||
Notes:
|
||||
------
|
||||
- Higher score means more similar texts
|
||||
- Score of 1.0 means identical word composition (bag-of-words)
|
||||
- Score of 0.0 means completely different vocabulary
|
||||
"""
|
||||
from sklearn.feature_extraction.text import CountVectorizer
|
||||
from sklearn.metrics.pairwise import cosine_similarity
|
||||
|
||||
vectorizer = CountVectorizer().fit_transform([s1, s2])
|
||||
vectors = vectorizer.toarray()
|
||||
return cosine_similarity([vectors[0]], [vectors[1]])[0][0]
|
||||
|
||||
|
||||
def convert_audio_to_text(audio_data):
|
||||
"""
|
||||
Convert base64 encoded audio data to text using speech recognition.
|
||||
"""
|
||||
|
||||
audio_data = base64.b64decode(audio_data)
|
||||
output_path = f"./test_{int(time.time())}"
|
||||
with open(output_path, "wb") as audio_file:
|
||||
audio_file.write(audio_data)
|
||||
|
||||
print(f"audio data is saved: {output_path}")
|
||||
model = whisper.load_model("base")
|
||||
text = model.transcribe(output_path)["text"]
|
||||
if text:
|
||||
return text
|
||||
else:
|
||||
return ""
|
||||
|
||||
|
||||
def modify_stage_config(
|
||||
yaml_path: str,
|
||||
stage_updates: dict[int, dict[str, Any]],
|
||||
) -> str:
|
||||
"""
|
||||
Batch modify configurations for multiple stages in a YAML file.
|
||||
|
||||
Args:
|
||||
yaml_path: Path to the YAML configuration file.
|
||||
stage_updates: Dictionary where keys are stage IDs and values are dictionaries of
|
||||
modifications for that stage. Each modification dictionary uses
|
||||
dot-separated paths as keys and new configuration values as values.
|
||||
Example: {
|
||||
0: {'engine_args.max_model_len': 5800},
|
||||
1: {'runtime.max_batch_size': 2}
|
||||
}
|
||||
|
||||
Returns:
|
||||
str: Path to the newly created modified YAML file with timestamp suffix.
|
||||
|
||||
Example:
|
||||
>>> output_file = modify_stage_config(
|
||||
... 'config.yaml',
|
||||
... {
|
||||
... 0: {'engine_args.max_model_len': 5800},
|
||||
... 1: {'runtime.max_batch_size': 2}
|
||||
... }
|
||||
... )
|
||||
>>> print(f"Modified configuration saved to: {output_file}")
|
||||
Modified configuration saved to: config_1698765432.yaml
|
||||
"""
|
||||
path = Path(yaml_path)
|
||||
if not path.exists():
|
||||
raise FileNotFoundError(f"yaml does not exist: {path}")
|
||||
try:
|
||||
with open(yaml_path, encoding="utf-8") as f:
|
||||
config = yaml.safe_load(f) or {}
|
||||
except Exception as e:
|
||||
raise ValueError(f"Cannot parse YAML file: {e}")
|
||||
|
||||
stage_args = config.get("stage_args", [])
|
||||
if not stage_args:
|
||||
raise ValueError("the stage_args does not exist")
|
||||
|
||||
for stage_id, config_dict in stage_updates.items():
|
||||
target_stage = None
|
||||
for stage in stage_args:
|
||||
if stage.get("stage_id") == stage_id:
|
||||
target_stage = stage
|
||||
break
|
||||
|
||||
if target_stage is None:
|
||||
available_ids = [s.get("stage_id") for s in stage_args if "stage_id" in s]
|
||||
raise KeyError(f"Stage ID {stage_id} is not exist, available IDs: {available_ids}")
|
||||
|
||||
for key_path, value in config_dict.items():
|
||||
current = target_stage
|
||||
keys = key_path.split(".")
|
||||
for i in range(len(keys) - 1):
|
||||
key = keys[i]
|
||||
if key not in current:
|
||||
raise KeyError(f"the {'.'.join(keys[: i + 1])} does not exist")
|
||||
|
||||
elif not isinstance(current[key], dict) and i < len(keys) - 2:
|
||||
raise ValueError(f"{'.'.join(keys[: i + 1])}' cannot continue deeper because it's not a dict")
|
||||
current = current[key]
|
||||
current[keys[-1]] = value
|
||||
|
||||
output_path = f"{yaml_path.split('.')[0]}_{int(time.time())}.yaml"
|
||||
with open(output_path, "w", encoding="utf-8") as f:
|
||||
yaml.dump(config, f, default_flow_style=False, sort_keys=False, allow_unicode=True, indent=2)
|
||||
|
||||
return output_path
|
||||
|
||||
|
||||
class OmniServer:
|
||||
"""Omniserver for vLLM-Omni tests."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
model: str,
|
||||
serve_args: list[str],
|
||||
*,
|
||||
env_dict: dict[str, str] | None = None,
|
||||
) -> None:
|
||||
self.model = model
|
||||
self.serve_args = serve_args
|
||||
self.env_dict = env_dict
|
||||
self.proc: subprocess.Popen | None = None
|
||||
self.host = "127.0.0.1"
|
||||
self.port = get_open_port()
|
||||
|
||||
def _start_server(self) -> None:
|
||||
"""Start the vLLM-Omni server subprocess."""
|
||||
env = os.environ.copy()
|
||||
env["VLLM_WORKER_MULTIPROC_METHOD"] = "spawn"
|
||||
if self.env_dict is not None:
|
||||
env.update(self.env_dict)
|
||||
|
||||
cmd = [
|
||||
sys.executable,
|
||||
"-m",
|
||||
"vllm_omni.entrypoints.cli.main",
|
||||
"serve",
|
||||
self.model,
|
||||
"--omni",
|
||||
"--host",
|
||||
self.host,
|
||||
"--port",
|
||||
str(self.port),
|
||||
] + self.serve_args
|
||||
|
||||
print(f"Launching OmniServer with: {' '.join(cmd)}")
|
||||
self.proc = subprocess.Popen(
|
||||
cmd,
|
||||
env=env,
|
||||
cwd=os.path.dirname(os.path.dirname(os.path.abspath(__file__))), # Set working directory to vllm-omni root
|
||||
)
|
||||
|
||||
# Wait for server to be ready
|
||||
max_wait = 600 # 10 minutes
|
||||
start_time = time.time()
|
||||
while time.time() - start_time < max_wait:
|
||||
try:
|
||||
with socket.socket(socket.AF_INET, socket.SOCK_STREAM) as sock:
|
||||
sock.settimeout(1)
|
||||
result = sock.connect_ex((self.host, self.port))
|
||||
if result == 0:
|
||||
print(f"Server ready on {self.host}:{self.port}")
|
||||
return
|
||||
except Exception:
|
||||
pass
|
||||
time.sleep(2)
|
||||
|
||||
raise RuntimeError(f"Server failed to start within {max_wait} seconds")
|
||||
|
||||
def _kill_process_tree(self, pid):
|
||||
"""kill process and its children"""
|
||||
try:
|
||||
parent = psutil.Process(pid)
|
||||
children = parent.children(recursive=True)
|
||||
for child in children:
|
||||
try:
|
||||
child.terminate()
|
||||
except psutil.NoSuchProcess:
|
||||
pass
|
||||
|
||||
gone, still_alive = psutil.wait_procs(children, timeout=10)
|
||||
|
||||
for child in still_alive:
|
||||
try:
|
||||
child.kill()
|
||||
except psutil.NoSuchProcess:
|
||||
pass
|
||||
|
||||
try:
|
||||
parent.terminate()
|
||||
parent.wait(timeout=10)
|
||||
except (psutil.NoSuchProcess, psutil.TimeoutExpired):
|
||||
try:
|
||||
parent.kill()
|
||||
except psutil.NoSuchProcess:
|
||||
pass
|
||||
|
||||
except psutil.NoSuchProcess:
|
||||
pass
|
||||
|
||||
def __enter__(self):
|
||||
self._start_server()
|
||||
return self
|
||||
|
||||
def __exit__(self, exc_type, exc_val, exc_tb):
|
||||
if self.proc:
|
||||
try:
|
||||
parent = psutil.Process(self.proc.pid)
|
||||
children = parent.children(recursive=True)
|
||||
for child in children:
|
||||
try:
|
||||
child.terminate()
|
||||
except psutil.NoSuchProcess:
|
||||
pass
|
||||
|
||||
gone, still_alive = psutil.wait_procs(children, timeout=10)
|
||||
|
||||
for child in still_alive:
|
||||
try:
|
||||
child.kill()
|
||||
except psutil.NoSuchProcess:
|
||||
pass
|
||||
|
||||
try:
|
||||
parent.terminate()
|
||||
parent.wait(timeout=10)
|
||||
except (psutil.NoSuchProcess, psutil.TimeoutExpired):
|
||||
try:
|
||||
parent.kill()
|
||||
except psutil.NoSuchProcess:
|
||||
pass
|
||||
|
||||
except psutil.NoSuchProcess:
|
||||
pass
|
||||
@@ -0,0 +1,290 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
|
||||
"""
|
||||
Test script for FlashAttention backend with padding handling.
|
||||
|
||||
This script tests two main scenarios:
|
||||
1. Case 1: Comparing padded vs unpadded inputs for batch_size=1
|
||||
2. Case 2: Comparing FlashAttention and SDPA backends for batch_size=2 with padding
|
||||
"""
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
from vllm_omni.diffusion.attention.backends.abstract import AttentionMetadata
|
||||
from vllm_omni.diffusion.attention.backends.flash_attn import FlashAttentionImpl
|
||||
from vllm_omni.diffusion.attention.backends.sdpa import SDPAImpl
|
||||
|
||||
|
||||
def create_attention_mask(batch_size: int, seq_len: int, valid_len: int, device: torch.device) -> torch.Tensor:
|
||||
"""
|
||||
Create attention mask where first valid_len tokens are valid (1) and rest are padding (0).
|
||||
|
||||
Args:
|
||||
batch_size: Batch size
|
||||
seq_len: Total sequence length (including padding)
|
||||
valid_len: Number of valid (non-padded) tokens
|
||||
|
||||
Returns:
|
||||
Attention mask of shape (batch_size, seq_len)
|
||||
"""
|
||||
mask = torch.zeros(batch_size, seq_len, dtype=torch.bool, device=device)
|
||||
mask[:, :valid_len] = True
|
||||
return mask
|
||||
|
||||
|
||||
def pad_tensor(tensor: torch.Tensor, target_seq_len: int, pad_value: float = 0.0) -> torch.Tensor:
|
||||
"""
|
||||
Pad tensor along sequence dimension (dim=1).
|
||||
|
||||
Args:
|
||||
tensor: Input tensor of shape (batch_size, seq_len, num_heads, head_dim)
|
||||
target_seq_len: Target sequence length after padding
|
||||
pad_value: Value to use for padding
|
||||
|
||||
Returns:
|
||||
Padded tensor of shape (batch_size, target_seq_len, num_heads, head_dim)
|
||||
"""
|
||||
batch_size, seq_len, num_heads, head_dim = tensor.shape
|
||||
if target_seq_len <= seq_len:
|
||||
return tensor
|
||||
|
||||
padding = torch.full(
|
||||
(batch_size, target_seq_len - seq_len, num_heads, head_dim), pad_value, dtype=tensor.dtype, device=tensor.device
|
||||
)
|
||||
return torch.cat([tensor, padding], dim=1)
|
||||
|
||||
|
||||
@pytest.mark.skipif(not torch.cuda.is_available(), reason="FlashAttention requires CUDA")
|
||||
def test_padding_equivalence():
|
||||
"""
|
||||
Case 1: Test that padded and unpadded inputs produce similar outputs.
|
||||
|
||||
- Input A: batch_size=1, hidden_states (1, 48), encoder_hidden_states (1, 16)
|
||||
Concatenated length: 64, NO attention_mask
|
||||
- Input B: Same data but padded: hidden_states (1, 58), encoder_hidden_states (1, 26)
|
||||
Concatenated length: 84, WITH attention_mask
|
||||
|
||||
Expected: Output A and Output B should be very close.
|
||||
"""
|
||||
device = torch.device("cuda")
|
||||
dtype = torch.bfloat16
|
||||
|
||||
# Configuration
|
||||
batch_size = 1
|
||||
hidden_seq_len = 48
|
||||
encoder_seq_len = 16
|
||||
pad_length = 10
|
||||
num_heads = 8
|
||||
head_dim = 64
|
||||
|
||||
# Initialize FlashAttention
|
||||
fa_impl = FlashAttentionImpl(
|
||||
num_heads=num_heads, head_size=head_dim, softmax_scale=1.0 / (head_dim**0.5), causal=False
|
||||
)
|
||||
|
||||
# Create base tensors with random values (same for both A and B)
|
||||
torch.manual_seed(42)
|
||||
hidden_states_base = torch.randn(batch_size, hidden_seq_len, num_heads, head_dim, device=device, dtype=dtype)
|
||||
encoder_hidden_states_base = torch.randn(
|
||||
batch_size, encoder_seq_len, num_heads, head_dim, device=device, dtype=dtype
|
||||
)
|
||||
|
||||
# ========== Input A: Unpadded, no attention mask ==========
|
||||
query_a = torch.cat([hidden_states_base, encoder_hidden_states_base], dim=1)
|
||||
key_a = query_a.clone()
|
||||
value_a = query_a.clone()
|
||||
|
||||
attn_metadata_a = AttentionMetadata(attn_mask=None)
|
||||
|
||||
output_a = fa_impl.forward(query=query_a, key=key_a, value=value_a, attn_metadata=attn_metadata_a)
|
||||
|
||||
# ========== Input B: Padded with attention mask ==========
|
||||
hidden_states_padded = pad_tensor(hidden_states_base, hidden_seq_len + pad_length)
|
||||
encoder_hidden_states_padded = pad_tensor(encoder_hidden_states_base, encoder_seq_len + pad_length)
|
||||
|
||||
query_b = torch.cat([hidden_states_padded, encoder_hidden_states_padded], dim=1)
|
||||
key_b = query_b.clone()
|
||||
value_b = query_b.clone()
|
||||
|
||||
# Create attention mask
|
||||
attn_mask_b = torch.cat(
|
||||
[
|
||||
create_attention_mask(batch_size, hidden_seq_len + pad_length, hidden_seq_len, device),
|
||||
create_attention_mask(batch_size, encoder_seq_len + pad_length, encoder_seq_len, device),
|
||||
],
|
||||
dim=1,
|
||||
)
|
||||
|
||||
attn_metadata_b = AttentionMetadata(attn_mask=attn_mask_b)
|
||||
|
||||
output_b = fa_impl.forward(query=query_b, key=key_b, value=value_b, attn_metadata=attn_metadata_b)
|
||||
|
||||
# Extract non-padded portion from output_b
|
||||
output_b_unpadded = torch.cat(
|
||||
[
|
||||
output_b[:, :hidden_seq_len, :, :],
|
||||
output_b[:, hidden_seq_len + pad_length : hidden_seq_len + pad_length + encoder_seq_len, :, :],
|
||||
],
|
||||
dim=1,
|
||||
)
|
||||
|
||||
# Compare outputs
|
||||
max_diff = torch.max(torch.abs(output_a - output_b_unpadded)).item()
|
||||
mean_diff = torch.mean(torch.abs(output_a - output_b_unpadded)).item()
|
||||
|
||||
print("\n=== Case 1: Padding Equivalence Test ===")
|
||||
print(f"Output A shape: {output_a.shape}")
|
||||
print(f"Output B shape: {output_b.shape}")
|
||||
print(f"Output B unpadded shape: {output_b_unpadded.shape}")
|
||||
print(f"Max absolute difference: {max_diff:.6f}")
|
||||
print(f"Mean absolute difference: {mean_diff:.6f}")
|
||||
|
||||
# Assert that outputs are close
|
||||
# Using higher tolerance for bfloat16
|
||||
assert max_diff < 0.1, f"Max difference {max_diff} exceeds threshold 0.1"
|
||||
assert mean_diff < 0.01, f"Mean difference {mean_diff} exceeds threshold 0.01"
|
||||
|
||||
print("✓ Case 1 PASSED: Padded and unpadded outputs are very close!")
|
||||
|
||||
|
||||
@pytest.mark.skipif(not torch.cuda.is_available(), reason="FlashAttention requires CUDA")
|
||||
def test_fa_vs_sdpa():
|
||||
"""
|
||||
Case 2: Compare FlashAttention and SDPA backends with padding.
|
||||
|
||||
- batch_size=2
|
||||
- hidden_states: (2, 48) padded to (2, 58)
|
||||
- encoder_hidden_states: (2, 16) padded to (2, 26)
|
||||
- Concatenated length: 84
|
||||
- Compare FA and SDPA outputs
|
||||
|
||||
Expected: FA and SDPA outputs should be very close.
|
||||
"""
|
||||
device = torch.device("cuda")
|
||||
dtype = torch.bfloat16
|
||||
|
||||
# Configuration
|
||||
batch_size = 2
|
||||
hidden_seq_len = 48
|
||||
encoder_seq_len = 16
|
||||
pad_length = 10
|
||||
num_heads = 8
|
||||
head_dim = 64
|
||||
|
||||
# Initialize both backends
|
||||
fa_impl = FlashAttentionImpl(
|
||||
num_heads=num_heads, head_size=head_dim, softmax_scale=1.0 / (head_dim**0.5), causal=False
|
||||
)
|
||||
|
||||
sdpa_impl = SDPAImpl(num_heads=num_heads, head_size=head_dim, softmax_scale=1.0 / (head_dim**0.5), causal=False)
|
||||
|
||||
# Create base tensors
|
||||
torch.manual_seed(123)
|
||||
hidden_states_base = torch.randn(batch_size, hidden_seq_len, num_heads, head_dim, device=device, dtype=dtype)
|
||||
encoder_hidden_states_base = torch.randn(
|
||||
batch_size, encoder_seq_len, num_heads, head_dim, device=device, dtype=dtype
|
||||
)
|
||||
|
||||
# Pad tensors
|
||||
hidden_states_padded = pad_tensor(hidden_states_base, hidden_seq_len + pad_length)
|
||||
encoder_hidden_states_padded = pad_tensor(encoder_hidden_states_base, encoder_seq_len + pad_length)
|
||||
|
||||
# Concatenate
|
||||
query = torch.cat([hidden_states_padded, encoder_hidden_states_padded], dim=1)
|
||||
key = query.clone()
|
||||
value = query.clone()
|
||||
|
||||
# Create attention mask
|
||||
attn_mask = torch.cat(
|
||||
[
|
||||
create_attention_mask(batch_size, hidden_seq_len + pad_length, hidden_seq_len, device),
|
||||
create_attention_mask(batch_size, encoder_seq_len + pad_length, encoder_seq_len, device),
|
||||
],
|
||||
dim=1,
|
||||
)
|
||||
|
||||
attn_metadata = AttentionMetadata(attn_mask=attn_mask)
|
||||
|
||||
# Run FlashAttention
|
||||
output_fa = fa_impl.forward(query=query.clone(), key=key.clone(), value=value.clone(), attn_metadata=attn_metadata)
|
||||
|
||||
# Run SDPA
|
||||
# SDPA expects 4D attention mask: (batch_size, 1, seq_len, seq_len) or (batch_size, seq_len)
|
||||
# For causal=False, we need to convert 2D mask to 4D
|
||||
if attn_mask is not None:
|
||||
# Expand mask for SDPA: (batch_size, seq_len) -> (batch_size, 1, 1, seq_len)
|
||||
attn_mask_4d = attn_mask.unsqueeze(1).unsqueeze(2)
|
||||
# Convert bool to float: True -> 0.0, False -> -inf
|
||||
attn_mask_float = torch.zeros_like(attn_mask_4d, dtype=dtype)
|
||||
attn_mask_float.masked_fill_(~attn_mask_4d, float("-inf"))
|
||||
attn_metadata_sdpa = AttentionMetadata(attn_mask=attn_mask_float)
|
||||
else:
|
||||
attn_metadata_sdpa = AttentionMetadata(attn_mask=None)
|
||||
|
||||
output_sdpa = sdpa_impl.forward(
|
||||
query=query.clone(), key=key.clone(), value=value.clone(), attn_metadata=attn_metadata_sdpa
|
||||
)
|
||||
|
||||
# Compare outputs (only compare valid regions)
|
||||
output_fa_valid = torch.cat(
|
||||
[
|
||||
output_fa[:, :hidden_seq_len, :, :],
|
||||
output_fa[:, hidden_seq_len + pad_length : hidden_seq_len + pad_length + encoder_seq_len, :, :],
|
||||
],
|
||||
dim=1,
|
||||
)
|
||||
output_sdpa_valid = torch.cat(
|
||||
[
|
||||
output_sdpa[:, :hidden_seq_len, :, :],
|
||||
output_sdpa[:, hidden_seq_len + pad_length : hidden_seq_len + pad_length + encoder_seq_len, :, :],
|
||||
],
|
||||
dim=1,
|
||||
)
|
||||
|
||||
max_diff = torch.max(torch.abs(output_fa_valid - output_sdpa_valid)).item()
|
||||
mean_diff = torch.mean(torch.abs(output_fa_valid - output_sdpa_valid)).item()
|
||||
|
||||
print("\n=== Case 2: FA vs SDPA Comparison ===")
|
||||
print(f"Batch size: {batch_size}")
|
||||
print(f"FA output shape: {output_fa.shape}")
|
||||
print(f"SDPA output shape: {output_sdpa.shape}")
|
||||
print(f"Max absolute difference (valid region): {max_diff:.6f}")
|
||||
print(f"Mean absolute difference (valid region): {mean_diff:.6f}")
|
||||
|
||||
# Assert that outputs are close
|
||||
# Using higher tolerance for bfloat16 and different implementations
|
||||
assert max_diff < 0.01, f"Max difference {max_diff} exceeds threshold 0.01"
|
||||
assert mean_diff < 0.001, f"Mean difference {mean_diff} exceeds threshold 0.001"
|
||||
|
||||
print("✓ Case 2 PASSED: FA and SDPA outputs are very close!")
|
||||
|
||||
|
||||
if __name__ == "__main__":
|
||||
print("Running FlashAttention Padding Tests...")
|
||||
print("=" * 60)
|
||||
|
||||
# Try to run CUDA tests
|
||||
if torch.cuda.is_available():
|
||||
try:
|
||||
print("\n[Running Case 1: Padding Equivalence for FA]")
|
||||
test_padding_equivalence()
|
||||
except Exception as e:
|
||||
print(f"✗ Case 1 failed: {e}")
|
||||
import traceback
|
||||
|
||||
traceback.print_exc()
|
||||
|
||||
try:
|
||||
print("\n[Running Case 2: FA vs SDPA]")
|
||||
test_fa_vs_sdpa()
|
||||
except Exception as e:
|
||||
print(f"✗ Case 2 failed: {e}")
|
||||
import traceback
|
||||
|
||||
traceback.print_exc()
|
||||
else:
|
||||
raise RuntimeError("CUDA is not available")
|
||||
print("\n" + "=" * 60)
|
||||
print("Test suite completed!")
|
||||
@@ -0,0 +1,44 @@
|
||||
import pytest
|
||||
|
||||
from vllm_omni.diffusion.models.z_image.z_image_transformer import validate_zimage_tp_constraints
|
||||
|
||||
|
||||
def test_validate_zimage_tp_constraints_tp2_ok():
|
||||
ffn_hidden_dim, final_out_dims, supported_tp = validate_zimage_tp_constraints(
|
||||
dim=3840,
|
||||
n_heads=30,
|
||||
n_kv_heads=30,
|
||||
in_channels=16,
|
||||
all_patch_size=(2,),
|
||||
all_f_patch_size=(1,),
|
||||
tensor_parallel_size=2,
|
||||
)
|
||||
assert ffn_hidden_dim == 10240
|
||||
assert final_out_dims == [64]
|
||||
assert supported_tp == [1, 2]
|
||||
|
||||
|
||||
def test_validate_zimage_tp_constraints_tp4_fails_on_heads():
|
||||
with pytest.raises(ValueError, match=r"n_heads % tensor_parallel_size"):
|
||||
validate_zimage_tp_constraints(
|
||||
dim=3840,
|
||||
n_heads=30,
|
||||
n_kv_heads=30,
|
||||
in_channels=16,
|
||||
all_patch_size=(2,),
|
||||
all_f_patch_size=(1,),
|
||||
tensor_parallel_size=4,
|
||||
)
|
||||
|
||||
|
||||
def test_validate_zimage_tp_constraints_tp3_fails_on_ffn_hidden_dim():
|
||||
with pytest.raises(ValueError, match=r"ffn_hidden_dim % tensor_parallel_size"):
|
||||
validate_zimage_tp_constraints(
|
||||
dim=3840,
|
||||
n_heads=30,
|
||||
n_kv_heads=30,
|
||||
in_channels=16,
|
||||
all_patch_size=(2,),
|
||||
all_f_patch_size=(1,),
|
||||
tensor_parallel_size=3,
|
||||
)
|
||||
@@ -2,9 +2,9 @@
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
|
||||
"""
|
||||
Unit tests for GPUWorker class.
|
||||
Unit tests for GPUDiffusionWorker class.
|
||||
|
||||
This module tests the GPUWorker implementation:
|
||||
This module tests the GPUDiffusionWorker implementation:
|
||||
- load_weights: Loading model weights
|
||||
- sleep: Putting worker into sleep mode (levels 1 and 2)
|
||||
- wake_up: Waking worker from sleep mode
|
||||
@@ -15,7 +15,7 @@ from unittest.mock import Mock, patch
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
from vllm_omni.diffusion.worker.gpu_worker import GPUWorker
|
||||
from vllm_omni.diffusion.worker.gpu_diffusion_worker import GPUDiffusionWorker
|
||||
|
||||
|
||||
@pytest.fixture
|
||||
@@ -33,20 +33,21 @@ def mock_od_config():
|
||||
|
||||
@pytest.fixture
|
||||
def mock_gpu_worker(mock_od_config):
|
||||
"""Create a GPUWorker with mocked initialization."""
|
||||
with patch.object(GPUWorker, "init_device_and_model"):
|
||||
worker = GPUWorker(local_rank=0, rank=0, od_config=mock_od_config)
|
||||
# Mock the pipeline
|
||||
worker.pipeline = Mock()
|
||||
worker.cache_backend = None
|
||||
"""Create a GPUDiffusionWorker with mocked initialization."""
|
||||
with patch.object(GPUDiffusionWorker, "init_device"):
|
||||
worker = GPUDiffusionWorker(local_rank=0, rank=0, od_config=mock_od_config)
|
||||
# Mock the model_runner with pipeline
|
||||
worker.model_runner = Mock()
|
||||
worker.model_runner.pipeline = Mock()
|
||||
worker._sleep_saved_buffers = {}
|
||||
return worker
|
||||
|
||||
|
||||
class TestGPUWorkerLoadWeights:
|
||||
"""Test GPUWorker.load_weights method."""
|
||||
class TestGPUDiffusionWorkerLoadWeights:
|
||||
"""Test GPUDiffusionWorker.load_weights method."""
|
||||
|
||||
def test_load_weights_calls_pipeline(self, mock_gpu_worker):
|
||||
"""Test that load_weights delegates to pipeline.load_weights."""
|
||||
"""Test that load_weights delegates to model_runner.load_weights."""
|
||||
# Setup mock weights
|
||||
mock_weights = [
|
||||
("layer1.weight", torch.randn(10, 10)),
|
||||
@@ -54,30 +55,30 @@ class TestGPUWorkerLoadWeights:
|
||||
]
|
||||
expected_loaded = {"layer1.weight", "layer2.weight"}
|
||||
|
||||
# Configure pipeline mock
|
||||
mock_gpu_worker.pipeline.load_weights = Mock(return_value=expected_loaded)
|
||||
# Configure model_runner mock
|
||||
mock_gpu_worker.model_runner.load_weights = Mock(return_value=expected_loaded)
|
||||
|
||||
# Call load_weights
|
||||
result = mock_gpu_worker.load_weights(mock_weights)
|
||||
|
||||
# Verify pipeline.load_weights was called with the weights
|
||||
mock_gpu_worker.pipeline.load_weights.assert_called_once_with(mock_weights)
|
||||
# Verify model_runner.load_weights was called with the weights
|
||||
mock_gpu_worker.model_runner.load_weights.assert_called_once_with(mock_weights)
|
||||
assert result == expected_loaded
|
||||
|
||||
def test_load_weights_empty_iterable(self, mock_gpu_worker):
|
||||
"""Test load_weights with empty weights iterable."""
|
||||
mock_gpu_worker.pipeline.load_weights = Mock(return_value=set())
|
||||
mock_gpu_worker.model_runner.load_weights = Mock(return_value=set())
|
||||
|
||||
result = mock_gpu_worker.load_weights([])
|
||||
|
||||
mock_gpu_worker.pipeline.load_weights.assert_called_once_with([])
|
||||
mock_gpu_worker.model_runner.load_weights.assert_called_once_with([])
|
||||
assert result == set()
|
||||
|
||||
|
||||
class TestGPUWorkerSleep:
|
||||
"""Test GPUWorker.sleep method."""
|
||||
class TestGPUDiffusionWorkerSleep:
|
||||
"""Test GPUDiffusionWorker.sleep method."""
|
||||
|
||||
@patch("vllm_omni.diffusion.worker.gpu_worker.torch.cuda.mem_get_info")
|
||||
@patch("vllm_omni.diffusion.worker.gpu_diffusion_worker.torch.cuda.mem_get_info")
|
||||
@patch("vllm.device_allocator.cumem.CuMemAllocator")
|
||||
def test_sleep_level_1(self, mock_allocator_class, mock_mem_info, mock_gpu_worker):
|
||||
"""Test sleep mode level 1 (offload weights only)."""
|
||||
@@ -103,7 +104,7 @@ class TestGPUWorkerSleep:
|
||||
# Verify buffers were NOT saved (level 1 doesn't save buffers)
|
||||
assert len(mock_gpu_worker._sleep_saved_buffers) == 0
|
||||
|
||||
@patch("vllm_omni.diffusion.worker.gpu_worker.torch.cuda.mem_get_info")
|
||||
@patch("vllm_omni.diffusion.worker.gpu_diffusion_worker.torch.cuda.mem_get_info")
|
||||
@patch("vllm.device_allocator.cumem.CuMemAllocator")
|
||||
def test_sleep_level_2(self, mock_allocator_class, mock_mem_info, mock_gpu_worker):
|
||||
"""Test sleep mode level 2 (offload all, save buffers)."""
|
||||
@@ -121,7 +122,7 @@ class TestGPUWorkerSleep:
|
||||
# Mock pipeline buffers
|
||||
mock_buffer1 = torch.randn(10, 10)
|
||||
mock_buffer2 = torch.randn(20, 20)
|
||||
mock_gpu_worker.pipeline.named_buffers = Mock(
|
||||
mock_gpu_worker.model_runner.pipeline.named_buffers = Mock(
|
||||
return_value=[
|
||||
("buffer1", mock_buffer1),
|
||||
("buffer2", mock_buffer2),
|
||||
@@ -140,7 +141,7 @@ class TestGPUWorkerSleep:
|
||||
assert "buffer1" in mock_gpu_worker._sleep_saved_buffers
|
||||
assert "buffer2" in mock_gpu_worker._sleep_saved_buffers
|
||||
|
||||
@patch("vllm_omni.diffusion.worker.gpu_worker.torch.cuda.mem_get_info")
|
||||
@patch("vllm_omni.diffusion.worker.gpu_diffusion_worker.torch.cuda.mem_get_info")
|
||||
@patch("vllm.device_allocator.cumem.CuMemAllocator")
|
||||
def test_sleep_memory_freed_validation(self, mock_allocator_class, mock_mem_info, mock_gpu_worker):
|
||||
"""Test that sleep validates memory was actually freed."""
|
||||
@@ -159,8 +160,8 @@ class TestGPUWorkerSleep:
|
||||
mock_gpu_worker.sleep(level=1)
|
||||
|
||||
|
||||
class TestGPUWorkerWakeUp:
|
||||
"""Test GPUWorker.wake_up method."""
|
||||
class TestGPUDiffusionWorkerWakeUp:
|
||||
"""Test GPUDiffusionWorker.wake_up method."""
|
||||
|
||||
@patch("vllm.device_allocator.cumem.CuMemAllocator")
|
||||
def test_wake_up_without_buffers(self, mock_allocator_class, mock_gpu_worker):
|
||||
@@ -202,7 +203,7 @@ class TestGPUWorkerWakeUp:
|
||||
mock_buffer2 = Mock()
|
||||
mock_buffer2.data = Mock()
|
||||
|
||||
mock_gpu_worker.pipeline.named_buffers = Mock(
|
||||
mock_gpu_worker.model_runner.pipeline.named_buffers = Mock(
|
||||
return_value=[
|
||||
("buffer1", mock_buffer1),
|
||||
("buffer2", mock_buffer2),
|
||||
@@ -243,7 +244,7 @@ class TestGPUWorkerWakeUp:
|
||||
mock_buffer2 = Mock()
|
||||
mock_buffer2.data = Mock()
|
||||
|
||||
mock_gpu_worker.pipeline.named_buffers = Mock(
|
||||
mock_gpu_worker.model_runner.pipeline.named_buffers = Mock(
|
||||
return_value=[
|
||||
("buffer1", mock_buffer1),
|
||||
("buffer2", mock_buffer2),
|
||||
@@ -45,7 +45,7 @@ stage_args:
|
||||
worker_cls: vllm_omni.worker.gpu_ar_worker.GPUARWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_ar_scheduler.OmniARScheduler
|
||||
gpu_memory_utilization: 0.3
|
||||
enforce_eager: true
|
||||
enforce_eager: false
|
||||
trust_remote_code: true
|
||||
engine_output_type: latent # Output codec codes for code2wav
|
||||
# tensor_parallel_size: 2
|
||||
|
||||
@@ -0,0 +1,98 @@
|
||||
# Stage config for running Qwen3-Omni-MoE with 3-stage architecture
|
||||
# Stage 0: Thinker (multimodal understanding + text generation)
|
||||
# Stage 1: Talker (text embeddings → 16-layer RVQ codec codes)
|
||||
# Stage 2: Code2Wav (8-layer RVQ codes → audio waveform)
|
||||
|
||||
# The following config has been verified on 2x H100-80G GPUs.
|
||||
stage_args:
|
||||
- stage_id: 0
|
||||
runtime:
|
||||
devices: "0,1"
|
||||
max_batch_size: 1
|
||||
engine_args:
|
||||
model_stage: thinker
|
||||
model_arch: Qwen3OmniMoeForConditionalGeneration
|
||||
worker_cls: vllm_omni.worker.gpu_ar_worker.GPUARWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_ar_scheduler.OmniARScheduler
|
||||
gpu_memory_utilization: 0.6
|
||||
enforce_eager: false
|
||||
trust_remote_code: true
|
||||
engine_output_type: latent # Output hidden states for talker
|
||||
distributed_executor_backend: "mp"
|
||||
enable_prefix_caching: false
|
||||
hf_config_name: thinker_config
|
||||
tensor_parallel_size: 2
|
||||
load_format: dummy
|
||||
final_output: true
|
||||
final_output_type: text
|
||||
is_comprehension: true
|
||||
default_sampling_params:
|
||||
temperature: 0.4
|
||||
top_p: 0.9
|
||||
top_k: 1
|
||||
max_tokens: 100
|
||||
seed: 42
|
||||
detokenize: True
|
||||
repetition_penalty: 1.05
|
||||
|
||||
- stage_id: 1
|
||||
runtime:
|
||||
devices: "1"
|
||||
max_batch_size: 1
|
||||
engine_args:
|
||||
model_stage: talker
|
||||
model_arch: Qwen3OmniMoeForConditionalGeneration
|
||||
worker_cls: vllm_omni.worker.gpu_ar_worker.GPUARWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_ar_scheduler.OmniARScheduler
|
||||
gpu_memory_utilization: 0.3
|
||||
enforce_eager: true
|
||||
trust_remote_code: true
|
||||
engine_output_type: latent # Output codec codes for code2wav
|
||||
# tensor_parallel_size: 2
|
||||
enable_prefix_caching: false
|
||||
distributed_executor_backend: "mp"
|
||||
hf_config_name: talker_config
|
||||
load_format: dummy
|
||||
engine_input_source: [0]
|
||||
custom_process_input_func: vllm_omni.model_executor.stage_input_processors.qwen3_omni.thinker2talker
|
||||
# final_output: true
|
||||
# final_output_type: text
|
||||
default_sampling_params:
|
||||
temperature: 0.9
|
||||
top_k: 50
|
||||
max_tokens: 100
|
||||
seed: 42
|
||||
detokenize: False
|
||||
repetition_penalty: 1.05
|
||||
stop_token_ids: [2150]
|
||||
|
||||
- stage_id: 2
|
||||
runtime:
|
||||
devices: "0"
|
||||
max_batch_size: 1
|
||||
engine_args:
|
||||
model_stage: code2wav
|
||||
model_arch: Qwen3OmniMoeForConditionalGeneration
|
||||
worker_cls: vllm_omni.worker.gpu_generation_worker.GPUGenerationWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_generation_scheduler.OmniGenerationScheduler
|
||||
enforce_eager: true
|
||||
trust_remote_code: true
|
||||
enable_prefix_caching: false
|
||||
engine_output_type: audio # Final output: audio waveform
|
||||
gpu_memory_utilization: 0.1
|
||||
distributed_executor_backend: "mp"
|
||||
max_num_batched_tokens: 1000000
|
||||
hf_config_name: thinker_config
|
||||
load_format: dummy
|
||||
engine_input_source: [1]
|
||||
custom_process_input_func: vllm_omni.model_executor.stage_input_processors.qwen3_omni.talker2code2wav
|
||||
final_output: true
|
||||
final_output_type: audio
|
||||
default_sampling_params:
|
||||
temperature: 0.0
|
||||
top_p: 1.0
|
||||
top_k: -1
|
||||
max_tokens: 200
|
||||
seed: 42
|
||||
detokenize: True
|
||||
repetition_penalty: 1.1
|
||||
@@ -0,0 +1,90 @@
|
||||
import sys
|
||||
import threading
|
||||
import time
|
||||
from pathlib import Path
|
||||
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
from vllm_omni.utils.platform_utils import is_npu, is_rocm
|
||||
|
||||
# ruff: noqa: E402
|
||||
REPO_ROOT = Path(__file__).resolve().parents[2]
|
||||
if str(REPO_ROOT) not in sys.path:
|
||||
sys.path.insert(0, str(REPO_ROOT))
|
||||
|
||||
from vllm_omni import Omni
|
||||
|
||||
|
||||
class GPUMemoryMonitor:
|
||||
"""Poll global device memory usage via CUDA APIs."""
|
||||
|
||||
def __init__(self, device_index: int, interval: float = 0.05):
|
||||
self.device_index = device_index
|
||||
self.interval = interval
|
||||
self.peak_used_mb = 0.0
|
||||
self._stop_event = threading.Event()
|
||||
self._thread: threading.Thread | None = None
|
||||
|
||||
def start(self) -> None:
|
||||
def monitor_loop() -> None:
|
||||
while not self._stop_event.is_set():
|
||||
try:
|
||||
with torch.cuda.device(self.device_index):
|
||||
free_bytes, total_bytes = torch.cuda.mem_get_info()
|
||||
used_mb = (total_bytes - free_bytes) / (1024**2)
|
||||
self.peak_used_mb = max(self.peak_used_mb, used_mb)
|
||||
except Exception:
|
||||
pass
|
||||
time.sleep(self.interval)
|
||||
|
||||
self._thread = threading.Thread(target=monitor_loop, daemon=True)
|
||||
self._thread.start()
|
||||
|
||||
def stop(self) -> None:
|
||||
if self._thread is None:
|
||||
return
|
||||
self._stop_event.set()
|
||||
self._thread.join(timeout=2.0)
|
||||
|
||||
|
||||
models = ["riverclouds/qwen_image_random"]
|
||||
|
||||
|
||||
@pytest.mark.skipif(is_npu() or is_rocm(), reason="Hardware not supported")
|
||||
@pytest.mark.parametrize("model_name", models)
|
||||
def test_cpu_offload_diffusion_model(model_name: str):
|
||||
def inference(offload: bool = True):
|
||||
torch.cuda.empty_cache()
|
||||
device_index = torch.cuda.current_device()
|
||||
monitor = GPUMemoryMonitor(device_index=device_index, interval=0.02)
|
||||
monitor.start()
|
||||
m = Omni(model=model_name, enable_cpu_offload=offload)
|
||||
torch.cuda.reset_peak_memory_stats(device=device_index)
|
||||
height = 256
|
||||
width = 256
|
||||
|
||||
m.generate(
|
||||
"a photo of a cat sitting on a laptop keyboard",
|
||||
height=height,
|
||||
width=width,
|
||||
num_inference_steps=9,
|
||||
guidance_scale=0.0,
|
||||
generator=torch.Generator("cuda").manual_seed(42),
|
||||
)
|
||||
|
||||
monitor.stop()
|
||||
torch.cuda.synchronize(device_index)
|
||||
fallback_alloc = torch.cuda.max_memory_allocated(device=device_index) / (1024**2)
|
||||
fallback_reserved = torch.cuda.max_memory_reserved(device=device_index) / (1024**2)
|
||||
peak_memory_mb = max(monitor.peak_used_mb, fallback_alloc, fallback_reserved)
|
||||
|
||||
return peak_memory_mb
|
||||
|
||||
offload_peak_memory = inference(offload=True)
|
||||
no_offload_peak_memory = inference(offload=False)
|
||||
print(f"Offload peak memory: {offload_peak_memory} MB")
|
||||
print(f"No offload peak memory: {no_offload_peak_memory} MB")
|
||||
assert offload_peak_memory + 2500 < no_offload_peak_memory, (
|
||||
f"Offload peak memory {offload_peak_memory} MB should be less than no offload peak memory {no_offload_peak_memory} MB"
|
||||
)
|
||||
@@ -10,14 +10,20 @@ from pathlib import Path
|
||||
import pytest
|
||||
from vllm.assets.video import VideoAsset
|
||||
|
||||
from vllm_omni.utils import is_rocm
|
||||
|
||||
from .conftest import OmniRunner
|
||||
|
||||
os.environ["VLLM_WORKER_MULTIPROC_METHOD"] = "spawn"
|
||||
|
||||
models = ["Qwen/Qwen3-Omni-30B-A3B-Instruct"]
|
||||
|
||||
# CI stage config for 2xH100-80G GPUs
|
||||
stage_configs = [str(Path(__file__).parent / "stage_configs" / "qwen3_omni_ci.yaml")]
|
||||
# CI stage config for 2xH100-80G GPUs or AMD GPU MI325
|
||||
if is_rocm():
|
||||
# ROCm stage config optimized for MI325 GPU
|
||||
stage_configs = [str(Path(__file__).parent / "stage_configs" / "rocm" / "qwen3_omni_ci.yaml")]
|
||||
else:
|
||||
stage_configs = [str(Path(__file__).parent / "stage_configs" / "qwen3_omni_ci.yaml")]
|
||||
|
||||
# Create parameter combinations for model and stage config
|
||||
test_params = [(model, stage_config) for model in models for stage_config in stage_configs]
|
||||
|
||||
@@ -202,3 +202,114 @@ def test_sequence_parallel(
|
||||
f"(thresholds: mean<={mean_threshold:.6e}, max<={max_threshold:.6e}); "
|
||||
f"ulysses_degree={ulysses_degree}, ring_degree={ring_degree}, dtype={dtype}"
|
||||
)
|
||||
|
||||
|
||||
@pytest.mark.parametrize("model_name", models)
|
||||
@pytest.mark.parametrize("dtype", [torch.bfloat16])
|
||||
@pytest.mark.parametrize("attn_backend", ["sdpa"])
|
||||
def test_sequence_parallel_ulysses_sp_only(
|
||||
model_name: str,
|
||||
dtype: torch.dtype,
|
||||
attn_backend: str,
|
||||
):
|
||||
"""Test sequence parallel with ulysses_degree=4, ring_degree=1, and the image size (332x332) where the sequence length is NOT divisible by sp_size."""
|
||||
ulysses_degree = 4
|
||||
ring_degree = 1
|
||||
|
||||
# Skip if not enough GPUs available for SP run
|
||||
if device_count() < ulysses_degree * ring_degree:
|
||||
pytest.skip(f"Test requires {ulysses_degree * ring_degree} GPUs but only {device_count()} available")
|
||||
|
||||
# (272/8) * (272/8) = 17 * 17 = 289 Not divisible by sp_size=4
|
||||
height = 272
|
||||
width = 272
|
||||
num_inference_steps = 4 # Minimal steps for fast test
|
||||
seed = 42
|
||||
|
||||
# Step 1: Baseline (no Ulysses sequence parallel)
|
||||
baseline_parallel_config = DiffusionParallelConfig(ulysses_degree=1, ring_degree=1)
|
||||
baseline = Omni(
|
||||
model=model_name,
|
||||
parallel_config=baseline_parallel_config,
|
||||
dtype=dtype,
|
||||
attention_backend=attn_backend,
|
||||
)
|
||||
try:
|
||||
outputs = baseline.generate(
|
||||
PROMPT,
|
||||
height=height,
|
||||
width=width,
|
||||
num_inference_steps=num_inference_steps,
|
||||
guidance_scale=0.0,
|
||||
generator=torch.Generator(get_device_name()).manual_seed(seed),
|
||||
num_outputs_per_prompt=1,
|
||||
)
|
||||
baseline_images = outputs[0].request_output[0].images
|
||||
finally:
|
||||
baseline.close()
|
||||
if dist.is_initialized():
|
||||
dist.destroy_process_group()
|
||||
for key in ["MASTER_ADDR", "MASTER_PORT", "RANK", "WORLD_SIZE", "LOCAL_RANK"]:
|
||||
os.environ.pop(key, None)
|
||||
time.sleep(2) # Wait for resources to release
|
||||
|
||||
assert baseline_images is not None
|
||||
assert len(baseline_images) == 1
|
||||
assert baseline_images[0].width == width
|
||||
assert baseline_images[0].height == height
|
||||
|
||||
# Step 2: SP (Ulysses-SP + Ring-SP)
|
||||
sp_parallel_config = DiffusionParallelConfig(ulysses_degree=ulysses_degree, ring_degree=ring_degree)
|
||||
sp = Omni(
|
||||
model=model_name,
|
||||
parallel_config=sp_parallel_config,
|
||||
dtype=dtype,
|
||||
attention_backend=attn_backend,
|
||||
)
|
||||
try:
|
||||
outputs = sp.generate(
|
||||
PROMPT,
|
||||
height=height,
|
||||
width=width,
|
||||
num_inference_steps=num_inference_steps,
|
||||
guidance_scale=0.0,
|
||||
generator=torch.Generator(get_device_name()).manual_seed(seed),
|
||||
num_outputs_per_prompt=1,
|
||||
)
|
||||
sp_images = outputs[0].request_output[0].images
|
||||
finally:
|
||||
sp.close()
|
||||
if dist.is_initialized():
|
||||
dist.destroy_process_group()
|
||||
for key in ["MASTER_ADDR", "MASTER_PORT", "RANK", "WORLD_SIZE", "LOCAL_RANK"]:
|
||||
os.environ.pop(key, None)
|
||||
time.sleep(2)
|
||||
|
||||
assert sp_images is not None
|
||||
assert len(sp_images) == 1
|
||||
assert sp_images[0].width == width
|
||||
assert sp_images[0].height == height
|
||||
|
||||
# Step 3: Compare outputs
|
||||
mean_abs_diff, max_abs_diff = _diff_metrics(baseline_images[0], sp_images[0])
|
||||
|
||||
# FP16/BF16 may differ slightly due to different computation order under parallelism.
|
||||
if dtype in (torch.float16, torch.bfloat16):
|
||||
mean_threshold = 2e-2
|
||||
max_threshold = 2e-1
|
||||
else:
|
||||
mean_threshold = 1e-2
|
||||
max_threshold = 1e-1
|
||||
|
||||
print(
|
||||
"Image diff stats (baseline ulysses_degree*ring_degree=1 vs SP): "
|
||||
f"mean_abs_diff={mean_abs_diff:.6e}, max_abs_diff={max_abs_diff:.6e}; "
|
||||
f"thresholds: mean<={mean_threshold:.6e}, max<={max_threshold:.6e}; "
|
||||
f"ulysses_degree={ulysses_degree}, ring_degree={ring_degree}, dtype={dtype}"
|
||||
)
|
||||
|
||||
assert mean_abs_diff <= mean_threshold and max_abs_diff <= max_threshold, (
|
||||
f"Image diff exceeded threshold: mean_abs_diff={mean_abs_diff:.6e}, max_abs_diff={max_abs_diff:.6e} "
|
||||
f"(thresholds: mean<={mean_threshold:.6e}, max<={max_threshold:.6e}); "
|
||||
f"ulysses_degree={ulysses_degree}, ring_degree={ring_degree}, dtype={dtype}"
|
||||
)
|
||||
@@ -0,0 +1,66 @@
|
||||
import os
|
||||
import sys
|
||||
from pathlib import Path
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
import torch
|
||||
|
||||
from vllm_omni.outputs import OmniRequestOutput
|
||||
|
||||
# ruff: noqa: E402
|
||||
REPO_ROOT = Path(__file__).resolve().parents[2]
|
||||
if str(REPO_ROOT) not in sys.path:
|
||||
sys.path.insert(0, str(REPO_ROOT))
|
||||
|
||||
from vllm_omni import Omni
|
||||
|
||||
os.environ["VLLM_TEST_CLEAN_GPU_MEMORY"] = "1"
|
||||
|
||||
# Use random weights model for CI testing (small, no authentication required)
|
||||
models = ["linyueqian/stable_audio_random"]
|
||||
|
||||
|
||||
@pytest.mark.parametrize("model_name", models)
|
||||
def test_stable_audio_model(model_name: str):
|
||||
m = Omni(model=model_name)
|
||||
|
||||
# Use minimal settings for testing
|
||||
# Generate a short 2-second audio clip with minimal inference steps
|
||||
audio_start_in_s = 0.0
|
||||
audio_end_in_s = 2.0 # Short duration for fast testing
|
||||
sample_rate = 44100 # Stable Audio uses 44100 Hz
|
||||
|
||||
outputs = m.generate(
|
||||
"The sound of a dog barking",
|
||||
negative_prompt="Low quality.",
|
||||
num_inference_steps=4, # Minimal steps for speed
|
||||
guidance_scale=7.0,
|
||||
generator=torch.Generator("cuda").manual_seed(42),
|
||||
num_outputs_per_prompt=1,
|
||||
extra={
|
||||
"audio_start_in_s": audio_start_in_s,
|
||||
"audio_end_in_s": audio_end_in_s,
|
||||
},
|
||||
)
|
||||
|
||||
# Extract audio from OmniRequestOutput
|
||||
assert outputs is not None
|
||||
first_output = outputs[0]
|
||||
assert first_output.final_output_type == "image" # Generic output type
|
||||
assert hasattr(first_output, "request_output") and first_output.request_output
|
||||
|
||||
req_out = first_output.request_output[0]
|
||||
assert isinstance(req_out, OmniRequestOutput)
|
||||
assert hasattr(req_out, "images") and len(req_out.images) >= 1
|
||||
|
||||
# For stable audio, the "images" field contains audio numpy arrays
|
||||
audio = req_out.images[0]
|
||||
assert isinstance(audio, np.ndarray)
|
||||
# audio shape: (batch, channels, samples)
|
||||
# For stable-audio-open-1.0: sample_rate=44100, so 2 seconds = 88200 samples
|
||||
assert audio.ndim == 3
|
||||
assert audio.shape[0] == 1 # batch size
|
||||
assert audio.shape[1] == 2 # stereo channels
|
||||
expected_samples = int((audio_end_in_s - audio_start_in_s) * sample_rate)
|
||||
assert audio.shape[2] == expected_samples # 88200 samples for 2 seconds
|
||||
@@ -0,0 +1,166 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
|
||||
import os
|
||||
import sys
|
||||
import time
|
||||
from pathlib import Path
|
||||
|
||||
import numpy as np
|
||||
import pytest
|
||||
import torch
|
||||
from PIL import Image
|
||||
from vllm.distributed.parallel_state import cleanup_dist_env_and_memory
|
||||
|
||||
# ruff: noqa: E402
|
||||
REPO_ROOT = Path(__file__).resolve().parents[2]
|
||||
if str(REPO_ROOT) not in sys.path:
|
||||
sys.path.insert(0, str(REPO_ROOT))
|
||||
|
||||
from vllm_omni import Omni
|
||||
from vllm_omni.diffusion.data import DiffusionParallelConfig
|
||||
from vllm_omni.outputs import OmniRequestOutput
|
||||
from vllm_omni.utils.platform_utils import is_npu, is_rocm
|
||||
|
||||
os.environ["VLLM_TEST_CLEAN_GPU_MEMORY"] = "1"
|
||||
|
||||
PROMPT = "a photo of a cat sitting on a laptop keyboard"
|
||||
|
||||
|
||||
def _get_zimage_model() -> str:
|
||||
# Allow overriding the model for local/offline environments.
|
||||
# Can be either a HuggingFace repo id or a local path.
|
||||
return os.environ.get("VLLM_TEST_ZIMAGE_MODEL", "Tongyi-MAI/Z-Image-Turbo")
|
||||
|
||||
|
||||
def _pil_to_float_rgb_tensor(img: Image.Image) -> torch.Tensor:
|
||||
"""Convert PIL image to float32 RGB tensor in [0, 1] with shape [H, W, 3]."""
|
||||
arr = np.asarray(img.convert("RGB"), dtype=np.float32) / 255.0
|
||||
return torch.from_numpy(arr)
|
||||
|
||||
|
||||
def _diff_metrics(a: Image.Image, b: Image.Image) -> tuple[float, float]:
|
||||
"""Return (mean_abs_diff, max_abs_diff) over RGB pixels in [0, 1]."""
|
||||
ta = _pil_to_float_rgb_tensor(a)
|
||||
tb = _pil_to_float_rgb_tensor(b)
|
||||
assert ta.shape == tb.shape, f"Image shapes differ: {ta.shape} vs {tb.shape}"
|
||||
abs_diff = torch.abs(ta - tb)
|
||||
return abs_diff.mean().item(), abs_diff.max().item()
|
||||
|
||||
|
||||
def _extract_single_image(outputs) -> Image.Image:
|
||||
first_output = outputs[0]
|
||||
assert first_output.final_output_type == "image"
|
||||
if not hasattr(first_output, "request_output") or not first_output.request_output:
|
||||
raise ValueError("No request_output found in OmniRequestOutput")
|
||||
|
||||
req_out = first_output.request_output[0]
|
||||
if not isinstance(req_out, OmniRequestOutput) or not hasattr(req_out, "images"):
|
||||
raise ValueError("Invalid request_output structure or missing 'images' key")
|
||||
|
||||
images = req_out.images
|
||||
if images is None or len(images) != 1:
|
||||
raise ValueError(f"Expected 1 image, got {0 if images is None else len(images)}")
|
||||
return images[0]
|
||||
|
||||
|
||||
def _run_zimage_generate(
|
||||
*, tp_size: int, height: int, width: int, num_inference_steps: int, seed: int
|
||||
) -> tuple[Image.Image, float]:
|
||||
m = Omni(
|
||||
model=_get_zimage_model(),
|
||||
parallel_config=DiffusionParallelConfig(tensor_parallel_size=tp_size),
|
||||
)
|
||||
try:
|
||||
# NOTE: Omni closes itself when a generate() call is exhausted.
|
||||
# To avoid measuring teardown time (process shutdown, memory cleanup),
|
||||
# we measure the latency to produce *subsequent* outputs within a single
|
||||
# generator run.
|
||||
#
|
||||
# This also serves as a warmup: the first output may include extra
|
||||
# compilation/caching overhead, while later outputs are closer to
|
||||
# steady-state inference.
|
||||
num_requests = 4 # 1 warmup + 3 timed
|
||||
gen = m.generate(
|
||||
[PROMPT] * num_requests,
|
||||
height=height,
|
||||
width=width,
|
||||
num_inference_steps=num_inference_steps,
|
||||
guidance_scale=0.0,
|
||||
seed=seed,
|
||||
num_outputs_per_prompt=1,
|
||||
py_generator=True,
|
||||
)
|
||||
|
||||
warmup_output = next(gen)
|
||||
t_prev = time.perf_counter()
|
||||
per_request_times_s: list[float] = []
|
||||
last_output = warmup_output
|
||||
for _ in range(num_requests - 1):
|
||||
last_output = next(gen)
|
||||
t_now = time.perf_counter()
|
||||
per_request_times_s.append(t_now - t_prev)
|
||||
t_prev = t_now
|
||||
|
||||
# Ensure the generator is fully consumed so it can clean up.
|
||||
for _ in gen:
|
||||
pass
|
||||
|
||||
median_time_s = float(np.median(per_request_times_s))
|
||||
return _extract_single_image([last_output]), median_time_s
|
||||
finally:
|
||||
m.close()
|
||||
cleanup_dist_env_and_memory()
|
||||
|
||||
|
||||
@pytest.mark.integration
|
||||
def test_zimage_tensor_parallel_tp2(tmp_path: Path):
|
||||
if is_npu() or is_rocm():
|
||||
pytest.skip("Z-Image TP e2e test is only supported on CUDA for now.")
|
||||
if not torch.cuda.is_available() or torch.cuda.device_count() < 2:
|
||||
pytest.skip("Z-Image TP=2 requires >= 2 CUDA devices.")
|
||||
|
||||
height = 256
|
||||
width = 256
|
||||
num_inference_steps = 2
|
||||
seed = 42
|
||||
|
||||
tp1_img, tp1_time_s = _run_zimage_generate(
|
||||
tp_size=1,
|
||||
height=height,
|
||||
width=width,
|
||||
num_inference_steps=num_inference_steps,
|
||||
seed=seed,
|
||||
)
|
||||
tp2_img, tp2_time_s = _run_zimage_generate(
|
||||
tp_size=2,
|
||||
height=height,
|
||||
width=width,
|
||||
num_inference_steps=num_inference_steps,
|
||||
seed=seed,
|
||||
)
|
||||
|
||||
tp1_path = tmp_path / "zimage_tp1.png"
|
||||
tp2_path = tmp_path / "zimage_tp2.png"
|
||||
tp1_img.save(tp1_path)
|
||||
tp2_img.save(tp2_path)
|
||||
|
||||
assert tp1_img.width == width and tp1_img.height == height
|
||||
assert tp2_img.width == width and tp2_img.height == height
|
||||
|
||||
mean_abs_diff, max_abs_diff = _diff_metrics(tp1_img, tp2_img)
|
||||
mean_threshold = 3e-2
|
||||
max_threshold = 3.5e-1
|
||||
print(
|
||||
"Z-Image TP image diff stats (TP=1 vs TP=2): "
|
||||
f"mean_abs_diff={mean_abs_diff:.6e}, max_abs_diff={max_abs_diff:.6e}; "
|
||||
f"thresholds: mean<={mean_threshold:.6e}, max<={max_threshold:.6e}; "
|
||||
f"tp1_img={tp1_path}, tp2_img={tp2_path}"
|
||||
)
|
||||
assert mean_abs_diff <= mean_threshold and max_abs_diff <= max_threshold, (
|
||||
f"Image diff exceeded threshold: mean_abs_diff={mean_abs_diff:.6e}, max_abs_diff={max_abs_diff:.6e} "
|
||||
f"(thresholds: mean<={mean_threshold:.6e}, max<={max_threshold:.6e})"
|
||||
)
|
||||
|
||||
print(f"Z-Image TP perf (lower is better): tp1_time_s={tp1_time_s:.6f}, tp2_time_s={tp2_time_s:.6f}")
|
||||
assert tp2_time_s < tp1_time_s, f"Expected TP=2 to be faster than TP=1 (tp1={tp1_time_s}, tp2={tp2_time_s})"
|
||||
@@ -45,7 +45,7 @@ stage_args:
|
||||
worker_cls: vllm_omni.worker.gpu_ar_worker.GPUARWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_ar_scheduler.OmniARScheduler
|
||||
gpu_memory_utilization: 0.3
|
||||
enforce_eager: true
|
||||
enforce_eager: false
|
||||
trust_remote_code: true
|
||||
engine_output_type: latent # Output codec codes for code2wav
|
||||
# tensor_parallel_size: 2
|
||||
|
||||
@@ -0,0 +1,98 @@
|
||||
# Stage config for running Qwen3-Omni-MoE with 3-stage architecture
|
||||
# Stage 0: Thinker (multimodal understanding + text generation)
|
||||
# Stage 1: Talker (text embeddings → 16-layer RVQ codec codes)
|
||||
# Stage 2: Code2Wav (8-layer RVQ codes → audio waveform)
|
||||
|
||||
# The following config has been verified on 2x H100-80G GPUs.
|
||||
stage_args:
|
||||
- stage_id: 0
|
||||
runtime:
|
||||
devices: "0,1"
|
||||
max_batch_size: 5
|
||||
engine_args:
|
||||
model_stage: thinker
|
||||
model_arch: Qwen3OmniMoeForConditionalGeneration
|
||||
worker_cls: vllm_omni.worker.gpu_ar_worker.GPUARWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_ar_scheduler.OmniARScheduler
|
||||
gpu_memory_utilization: 0.6
|
||||
enforce_eager: false
|
||||
trust_remote_code: true
|
||||
engine_output_type: latent # Output hidden states for talker
|
||||
distributed_executor_backend: "mp"
|
||||
enable_prefix_caching: false
|
||||
hf_config_name: thinker_config
|
||||
tensor_parallel_size: 2
|
||||
load_format: dummy
|
||||
final_output: true
|
||||
final_output_type: text
|
||||
is_comprehension: true
|
||||
default_sampling_params:
|
||||
temperature: 0.4
|
||||
top_p: 0.9
|
||||
top_k: 1
|
||||
max_tokens: 100
|
||||
seed: 42
|
||||
detokenize: True
|
||||
repetition_penalty: 1.05
|
||||
|
||||
- stage_id: 1
|
||||
runtime:
|
||||
devices: "1"
|
||||
max_batch_size: 5
|
||||
engine_args:
|
||||
model_stage: talker
|
||||
model_arch: Qwen3OmniMoeForConditionalGeneration
|
||||
worker_cls: vllm_omni.worker.gpu_ar_worker.GPUARWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_ar_scheduler.OmniARScheduler
|
||||
gpu_memory_utilization: 0.3
|
||||
enforce_eager: true
|
||||
trust_remote_code: true
|
||||
engine_output_type: latent # Output codec codes for code2wav
|
||||
# tensor_parallel_size: 2
|
||||
enable_prefix_caching: false
|
||||
distributed_executor_backend: "mp"
|
||||
hf_config_name: talker_config
|
||||
load_format: dummy
|
||||
engine_input_source: [0]
|
||||
custom_process_input_func: vllm_omni.model_executor.stage_input_processors.qwen3_omni.thinker2talker
|
||||
# final_output: true
|
||||
# final_output_type: text
|
||||
default_sampling_params:
|
||||
temperature: 0.9
|
||||
top_k: 50
|
||||
max_tokens: 100
|
||||
seed: 42
|
||||
detokenize: False
|
||||
repetition_penalty: 1.05
|
||||
stop_token_ids: [2150]
|
||||
|
||||
- stage_id: 2
|
||||
runtime:
|
||||
devices: "0"
|
||||
max_batch_size: 1
|
||||
engine_args:
|
||||
model_stage: code2wav
|
||||
model_arch: Qwen3OmniMoeForConditionalGeneration
|
||||
worker_cls: vllm_omni.worker.gpu_generation_worker.GPUGenerationWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_generation_scheduler.OmniGenerationScheduler
|
||||
enforce_eager: true
|
||||
trust_remote_code: true
|
||||
enable_prefix_caching: false
|
||||
engine_output_type: audio # Final output: audio waveform
|
||||
gpu_memory_utilization: 0.1
|
||||
distributed_executor_backend: "mp"
|
||||
max_num_batched_tokens: 1000000
|
||||
hf_config_name: thinker_config
|
||||
load_format: dummy
|
||||
engine_input_source: [1]
|
||||
custom_process_input_func: vllm_omni.model_executor.stage_input_processors.qwen3_omni.talker2code2wav
|
||||
final_output: true
|
||||
final_output_type: audio
|
||||
default_sampling_params:
|
||||
temperature: 0.0
|
||||
top_p: 1.0
|
||||
top_k: -1
|
||||
max_tokens: 200
|
||||
seed: 42
|
||||
detokenize: True
|
||||
repetition_penalty: 1.1
|
||||
@@ -5,7 +5,7 @@ from pathlib import Path
|
||||
import pytest
|
||||
from vllm.inputs import PromptType
|
||||
|
||||
from vllm_omni.entrypoints.async_omni import AsyncOmni
|
||||
from vllm_omni.entrypoints.async_omni import AsyncOmni, ClientRequestState
|
||||
|
||||
SEED = 42
|
||||
|
||||
@@ -98,3 +98,46 @@ async def test_abort():
|
||||
num_generated_tokens, request_id = await task
|
||||
assert num_generated_tokens == NUM_EXPECTED_TOKENS
|
||||
await asyncio.sleep(5)
|
||||
|
||||
|
||||
@pytest.mark.asyncio
|
||||
async def test_build_and_log_summary(monkeypatch):
|
||||
from vllm_omni.entrypoints.utils import get_final_stage_id_for_e2e
|
||||
|
||||
RealCRS = ClientRequestState
|
||||
capture_metrics = {}
|
||||
|
||||
class MockCRS(RealCRS):
|
||||
def __init__(self, request_id: str):
|
||||
super().__init__(request_id)
|
||||
capture_metrics[request_id] = self
|
||||
|
||||
monkeypatch.setattr("vllm_omni.entrypoints.async_omni.ClientRequestState", MockCRS)
|
||||
monkeypatch.setattr("vllm_omni.entrypoints.client_request_state.ClientRequestState", MockCRS)
|
||||
|
||||
with ExitStack() as after:
|
||||
engine = AsyncOmni(model=model, stage_configs_path=stage_config)
|
||||
after.callback(engine.shutdown)
|
||||
prompt = "Hello my name is Robert and "
|
||||
NUM_EXPECTED_TOKENS = 100
|
||||
NUM_REQUESTS = 5
|
||||
request_ids = [f"request-{i}" for i in range(NUM_REQUESTS)]
|
||||
|
||||
# Create concurrent requests.
|
||||
tasks: list[asyncio.Task] = []
|
||||
for idx, request_id in enumerate(request_ids):
|
||||
tasks.append(asyncio.create_task(generate(engine, request_id, prompt, NUM_EXPECTED_TOKENS)))
|
||||
|
||||
# Confirm the requests are okay.
|
||||
for idx, task in enumerate(tasks):
|
||||
await task
|
||||
output_modalities = ["text"]
|
||||
final_stage_id_for_e2e = get_final_stage_id_for_e2e(
|
||||
output_modalities, engine.output_modalities, engine.stage_list
|
||||
)
|
||||
summary = capture_metrics[request_ids[idx]].metrics.build_and_log_summary(final_stage_id_for_e2e)
|
||||
|
||||
# Check that total tokens matches sum of stage tokens.
|
||||
assert summary["e2e_total_tokens"] == sum(stage["tokens"] for stage in summary["stages"])
|
||||
# Check that total time matches sum of stage times.
|
||||
assert summary["e2e_total_time_ms"] >= sum(stage["total_time_ms"] for stage in summary["stages"])
|
||||
@@ -20,12 +20,18 @@ import pytest
|
||||
from vllm.assets.video import VideoAsset
|
||||
from vllm.utils import get_open_port
|
||||
|
||||
from vllm_omni.utils import is_rocm
|
||||
|
||||
os.environ["VLLM_WORKER_MULTIPROC_METHOD"] = "spawn"
|
||||
|
||||
models = ["Qwen/Qwen3-Omni-30B-A3B-Instruct"]
|
||||
|
||||
# CI stage config for 2*H100-80G GPUs
|
||||
stage_configs = [str(Path(__file__).parent / "stage_configs" / "qwen3_omni_ci.yaml")]
|
||||
# CI stage config for 2xH100-80G GPUs or AMD GPU MI325
|
||||
if is_rocm():
|
||||
# ROCm stage config optimized for MI325 GPU
|
||||
stage_configs = [str(Path(__file__).parent / "stage_configs" / "rocm" / "qwen3_omni_ci.yaml")]
|
||||
else:
|
||||
stage_configs = [str(Path(__file__).parent / "stage_configs" / "qwen3_omni_ci.yaml")]
|
||||
|
||||
# Create parameter combinations for model and stage config
|
||||
test_params = [(model, stage_config) for model in models for stage_config in stage_configs]
|
||||
|
||||
@@ -0,0 +1,158 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
"""
|
||||
E2E Online tests for Qwen3-Omni model.
|
||||
"""
|
||||
|
||||
import concurrent.futures
|
||||
import os
|
||||
import time
|
||||
from pathlib import Path
|
||||
|
||||
import openai
|
||||
import pytest
|
||||
|
||||
from tests.conftest import (
|
||||
OmniServer,
|
||||
convert_audio_to_text,
|
||||
cosine_similarity_text,
|
||||
dummy_messages_from_mix_data,
|
||||
modify_stage_config,
|
||||
)
|
||||
|
||||
os.environ["VLLM_WORKER_MULTIPROC_METHOD"] = "spawn"
|
||||
|
||||
models = ["Qwen/Qwen3-Omni-30B-A3B-Instruct"]
|
||||
|
||||
# CI stage config for 2*H100-80G GPUs
|
||||
stage_configs = [str(Path(__file__).parent.parent / "stage_configs" / "qwen3_omni_ci.yaml")]
|
||||
|
||||
# Create parameter combinations for model and stage config
|
||||
test_params = [(model, stage_config) for model in models for stage_config in stage_configs]
|
||||
|
||||
|
||||
def client(omni_server):
|
||||
"""OpenAI client for the running vLLM-Omni server."""
|
||||
return openai.OpenAI(
|
||||
base_url=f"http://{omni_server.host}:{omni_server.port}/v1",
|
||||
api_key="EMPTY",
|
||||
)
|
||||
|
||||
|
||||
def get_system_prompt():
|
||||
return {
|
||||
"role": "system",
|
||||
"content": [
|
||||
{
|
||||
"type": "text",
|
||||
"text": (
|
||||
"You are Qwen, a virtual human developed by the Qwen Team, "
|
||||
"Alibaba Group, capable of perceiving auditory and visual inputs, "
|
||||
"as well as generating text and speech."
|
||||
),
|
||||
}
|
||||
],
|
||||
}
|
||||
|
||||
|
||||
def get_prompt(prompt_type="text_only"):
|
||||
prompts = {
|
||||
"text_only": "What is the capital of China?",
|
||||
"mix": "What is recited in the audio? What is in this image? Describe the video briefly.",
|
||||
}
|
||||
return prompts.get(prompt_type, prompts["text_only"])
|
||||
|
||||
|
||||
def get_max_batch_size(size_type="few"):
|
||||
batch_sizes = {"few": 5, "medium": 100, "large": 256}
|
||||
return batch_sizes.get(size_type, 5)
|
||||
|
||||
|
||||
@pytest.mark.parametrize("test_config", test_params)
|
||||
def test_text_to_text_001(test_config: tuple[str, str]) -> None:
|
||||
"""Test processing text, generating text output via OpenAI API."""
|
||||
model, stage_config_path = test_config
|
||||
with OmniServer(model, ["--stage-configs-path", stage_config_path, "--stage-init-timeout", "90"]) as server:
|
||||
messages = dummy_messages_from_mix_data(system_prompt=get_system_prompt(), content_text=get_prompt())
|
||||
|
||||
# Test single completion
|
||||
api_client = client(server)
|
||||
start_time = time.perf_counter()
|
||||
chat_completion = api_client.chat.completions.create(
|
||||
model=server.model, messages=messages, max_tokens=20, modalities=["text"]
|
||||
)
|
||||
# Verify E2E
|
||||
print(f"the request e2e is: {time.perf_counter() - start_time}")
|
||||
# TODO: Verify the E2E latency after confirmation baseline.
|
||||
|
||||
# Verify only output text
|
||||
assert len(chat_completion.choices) == 1, "The generated content includes more than just text."
|
||||
|
||||
# Verify text output success
|
||||
text_choice = chat_completion.choices[0]
|
||||
assert text_choice.message.content is not None, "No text output is generated"
|
||||
assert chat_completion.usage.completion_tokens <= 20, "The output length more than the requested max_tokens."
|
||||
assert "beijing" in text_choice.message.content.lower(), "The output do not contain keywords."
|
||||
|
||||
|
||||
@pytest.mark.parametrize("test_config", test_params)
|
||||
def test_text_to_text_audio_001(test_config: tuple[str, str]) -> None:
|
||||
"""Test processing text, generating text and audio output via OpenAI API."""
|
||||
|
||||
model, stage_config_path = test_config
|
||||
num_concurrent_requests = get_max_batch_size()
|
||||
stage_config_path = modify_stage_config(
|
||||
stage_config_path,
|
||||
{
|
||||
0: {"runtime.max_batch_size": num_concurrent_requests},
|
||||
1: {"runtime.max_batch_size": num_concurrent_requests},
|
||||
},
|
||||
)
|
||||
with OmniServer(model, ["--stage-configs-path", stage_config_path, "--stage-init-timeout", "90"]) as server:
|
||||
messages = dummy_messages_from_mix_data(
|
||||
system_prompt=get_system_prompt(), content_text="What is the capital of China?"
|
||||
)
|
||||
|
||||
# Test single completion
|
||||
api_client = client(server)
|
||||
e2e_list = list()
|
||||
with concurrent.futures.ThreadPoolExecutor(max_workers=num_concurrent_requests) as executor:
|
||||
# Submit multiple completion requests concurrently
|
||||
futures = [
|
||||
executor.submit(api_client.chat.completions.create, model=server.model, messages=messages)
|
||||
for _ in range(num_concurrent_requests)
|
||||
]
|
||||
start_time = time.perf_counter()
|
||||
# Wait for all requests to complete and collect results
|
||||
chat_completions = list()
|
||||
for future in concurrent.futures.as_completed(futures):
|
||||
chat_completions.append(future.result())
|
||||
# Verify E2E
|
||||
current_e2e = time.perf_counter() - start_time
|
||||
print(f"the request e2e is: {current_e2e}")
|
||||
# TODO: Verify the E2E latency after confirmation baseline.
|
||||
e2e_list.append(current_e2e)
|
||||
|
||||
print(f"the avg e2e is: {sum(e2e_list) / len(e2e_list)}")
|
||||
# Verify all completions succeeded
|
||||
assert len(chat_completions) == num_concurrent_requests, "Not all requests succeeded."
|
||||
for chat_completion in chat_completions:
|
||||
# Verify audio output success
|
||||
audio_message = chat_completion.choices[1].message
|
||||
audio_data = audio_message.audio.data
|
||||
assert audio_data is not None, "No audio output is generated"
|
||||
assert audio_message.audio.expires_at > time.time(), "The generated audio has expired."
|
||||
|
||||
# Verify text output success
|
||||
text_choice = chat_completion.choices[0]
|
||||
text_content = text_choice.message.content
|
||||
assert text_choice.message.content is not None, "No text output is generated"
|
||||
assert "beijing" in text_choice.message.content.lower(), "The output do not contain keywords."
|
||||
|
||||
# Verify text output same as audio output
|
||||
audio_content = convert_audio_to_text(audio_data)
|
||||
print(f"text content is: {text_content}")
|
||||
print(f"audio content is: {audio_content}")
|
||||
assert cosine_similarity_text(audio_content.lower(), text_content.lower()) > 0.9, (
|
||||
"The audio content is not same as the text"
|
||||
)
|
||||
@@ -0,0 +1,95 @@
|
||||
# Stage config for running Qwen3-Omni-MoE with 3-stage architecture
|
||||
# Stage 0: Thinker (multimodal understanding + text generation)
|
||||
# Stage 1: Talker (text embeddings → 16-layer RVQ codec codes)
|
||||
# Stage 2: Code2Wav (8-layer RVQ codes → audio waveform)
|
||||
|
||||
# The following config has been verified on 2x H100-80G GPUs.
|
||||
stage_args:
|
||||
- stage_id: 0
|
||||
runtime:
|
||||
devices: "0,1"
|
||||
max_batch_size: 1
|
||||
engine_args:
|
||||
model_stage: thinker
|
||||
model_arch: Qwen3OmniMoeForConditionalGeneration
|
||||
worker_cls: vllm_omni.worker.gpu_ar_worker.GPUARWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_ar_scheduler.OmniARScheduler
|
||||
gpu_memory_utilization: 0.6
|
||||
enforce_eager: true
|
||||
trust_remote_code: true
|
||||
engine_output_type: latent # Output hidden states for talker
|
||||
distributed_executor_backend: "mp"
|
||||
max_num_batched_tokens: 32768
|
||||
enable_prefix_caching: false
|
||||
hf_config_name: thinker_config
|
||||
tensor_parallel_size: 2
|
||||
final_output: true
|
||||
final_output_type: text
|
||||
is_comprehension: true
|
||||
default_sampling_params:
|
||||
temperature: 0.4
|
||||
top_p: 0.9
|
||||
top_k: 1
|
||||
max_tokens: 100
|
||||
seed: 42
|
||||
ignore_eos: False
|
||||
detokenize: True
|
||||
repetition_penalty: 1.05
|
||||
|
||||
- stage_id: 1
|
||||
runtime:
|
||||
devices: "1"
|
||||
max_batch_size: 1
|
||||
engine_args:
|
||||
model_stage: talker
|
||||
model_arch: Qwen3OmniMoeForConditionalGeneration
|
||||
worker_cls: vllm_omni.worker.gpu_ar_worker.GPUARWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_ar_scheduler.OmniARScheduler
|
||||
gpu_memory_utilization: 0.3
|
||||
enforce_eager: true
|
||||
trust_remote_code: true
|
||||
engine_output_type: latent # Output codec codes for code2wav
|
||||
enable_prefix_caching: false
|
||||
max_num_batched_tokens: 32768
|
||||
distributed_executor_backend: "mp"
|
||||
hf_config_name: talker_config
|
||||
engine_input_source: [0]
|
||||
custom_process_input_func: vllm_omni.model_executor.stage_input_processors.qwen3_omni.thinker2talker
|
||||
default_sampling_params:
|
||||
temperature: 0.9
|
||||
top_k: 50
|
||||
max_tokens: 100
|
||||
seed: 42
|
||||
detokenize: False
|
||||
repetition_penalty: 1.05
|
||||
stop_token_ids: [2150]
|
||||
|
||||
- stage_id: 2
|
||||
runtime:
|
||||
devices: "0"
|
||||
max_batch_size: 1
|
||||
engine_args:
|
||||
model_stage: code2wav
|
||||
model_arch: Qwen3OmniMoeForConditionalGeneration
|
||||
worker_cls: vllm_omni.worker.gpu_generation_worker.GPUGenerationWorker
|
||||
scheduler_cls: vllm_omni.core.sched.omni_generation_scheduler.OmniGenerationScheduler
|
||||
enforce_eager: true
|
||||
trust_remote_code: true
|
||||
enable_prefix_caching: false
|
||||
engine_output_type: audio # Final output: audio waveform
|
||||
gpu_memory_utilization: 0.1
|
||||
distributed_executor_backend: "mp"
|
||||
max_num_batched_tokens: 1000000
|
||||
hf_config_name: thinker_config
|
||||
engine_input_source: [1]
|
||||
custom_process_input_func: vllm_omni.model_executor.stage_input_processors.qwen3_omni.talker2code2wav
|
||||
final_output: true
|
||||
final_output_type: audio
|
||||
default_sampling_params:
|
||||
temperature: 0.0
|
||||
top_p: 1.0
|
||||
top_k: -1
|
||||
max_tokens: 200
|
||||
seed: 42
|
||||
detokenize: True
|
||||
repetition_penalty: 1.1
|
||||
@@ -0,0 +1,117 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
"""
|
||||
Unit tests for OmniOpenAIServingChat modalities filtering.
|
||||
|
||||
Tests that modalities parameter correctly filters outputs in non-streaming
|
||||
chat completions while preserving usage/billing information.
|
||||
"""
|
||||
|
||||
from unittest.mock import MagicMock
|
||||
|
||||
# =============================================================================
|
||||
# Tests for modalities set creation logic
|
||||
# =============================================================================
|
||||
|
||||
|
||||
def test_requested_modalities_set_creation_with_list():
|
||||
"""Test that requested_modalities set is created from list."""
|
||||
# Simulate what happens in the code
|
||||
request = MagicMock()
|
||||
request.modalities = ["text", "audio"]
|
||||
|
||||
# This is the logic from the fix
|
||||
requested_modalities = set(request.modalities) if hasattr(request, "modalities") and request.modalities else None
|
||||
|
||||
assert requested_modalities == {"text", "audio"}
|
||||
|
||||
|
||||
def test_requested_modalities_set_creation_with_none():
|
||||
"""Test that requested_modalities is None when modalities is None."""
|
||||
request = MagicMock()
|
||||
request.modalities = None
|
||||
|
||||
requested_modalities = set(request.modalities) if hasattr(request, "modalities") and request.modalities else None
|
||||
|
||||
assert requested_modalities is None
|
||||
|
||||
|
||||
def test_requested_modalities_set_creation_when_missing():
|
||||
"""Test that requested_modalities is None when attribute missing."""
|
||||
request = MagicMock(spec=[]) # No modalities attribute
|
||||
|
||||
requested_modalities = set(request.modalities) if hasattr(request, "modalities") and request.modalities else None
|
||||
|
||||
assert requested_modalities is None
|
||||
|
||||
|
||||
# =============================================================================
|
||||
# Tests for modality filtering logic
|
||||
# =============================================================================
|
||||
|
||||
|
||||
def test_modality_filtering_text_in_set():
|
||||
"""Test that text output passes filter when text is requested."""
|
||||
requested_modalities = {"text", "audio"}
|
||||
final_output_type = "text"
|
||||
|
||||
# This is the filtering logic from the fix
|
||||
should_filter = requested_modalities is not None and final_output_type not in requested_modalities
|
||||
|
||||
assert not should_filter # text should NOT be filtered
|
||||
|
||||
|
||||
def test_modality_filtering_audio_not_in_set():
|
||||
"""Test that audio output is filtered when only text requested."""
|
||||
requested_modalities = {"text"}
|
||||
final_output_type = "audio"
|
||||
|
||||
should_filter = requested_modalities is not None and final_output_type not in requested_modalities
|
||||
|
||||
assert should_filter # audio SHOULD be filtered
|
||||
|
||||
|
||||
def test_modality_filtering_with_none_modalities():
|
||||
"""Test that nothing is filtered when modalities is None."""
|
||||
requested_modalities = None
|
||||
final_output_type = "text"
|
||||
|
||||
should_filter = requested_modalities is not None and final_output_type not in requested_modalities
|
||||
|
||||
assert not should_filter # Nothing should be filtered
|
||||
|
||||
final_output_type = "audio"
|
||||
should_filter = requested_modalities is not None and final_output_type not in requested_modalities
|
||||
|
||||
assert not should_filter # Nothing should be filtered
|
||||
|
||||
|
||||
# =============================================================================
|
||||
# Tests for usage extraction logic
|
||||
# =============================================================================
|
||||
|
||||
|
||||
def test_usage_extraction_logic():
|
||||
"""Test that usage info is extracted correctly from request_output."""
|
||||
# Mock the omni_outputs structure
|
||||
omni_outputs = MagicMock()
|
||||
omni_outputs.final_output_type = "text"
|
||||
omni_outputs.request_output = MagicMock()
|
||||
omni_outputs.request_output.prompt_token_ids = [1] * 10
|
||||
omni_outputs.request_output.encoder_prompt_token_ids = None
|
||||
|
||||
mock_output = MagicMock()
|
||||
mock_output.token_ids = [1] * 20
|
||||
omni_outputs.request_output.outputs = [mock_output]
|
||||
|
||||
# Simulate the usage extraction logic
|
||||
final_output_type = omni_outputs.final_output_type
|
||||
if final_output_type == "text" and omni_outputs.request_output is not None:
|
||||
final_res = omni_outputs.request_output
|
||||
if final_res.prompt_token_ids is not None:
|
||||
num_prompt_tokens = len(final_res.prompt_token_ids)
|
||||
if final_res.encoder_prompt_token_ids is not None:
|
||||
num_prompt_tokens += len(final_res.encoder_prompt_token_ids)
|
||||
num_generated_tokens = sum(len(output.token_ids) for output in final_res.outputs)
|
||||
|
||||
assert num_prompt_tokens == 10
|
||||
assert num_generated_tokens == 20
|
||||
@@ -7,7 +7,7 @@ from vllm_omni.entrypoints.async_omni import AsyncOmni
|
||||
|
||||
def test_default_stage_config_includes_cache_backend(monkeypatch):
|
||||
"""Ensure cache_backend/cache_config are preserved in default diffusion stage."""
|
||||
monkeypatch.setattr(omni_module, "load_stage_configs_from_model", lambda model: [])
|
||||
monkeypatch.setattr(omni_module, "load_stage_configs_from_model", lambda model, base_engine_args=None: [])
|
||||
monkeypatch.setattr(omni_module, "resolve_model_config_path", lambda model: None)
|
||||
monkeypatch.setattr(AsyncOmni, "_start_stages", lambda self, model: None)
|
||||
monkeypatch.setattr(AsyncOmni, "_wait_for_stages_ready", lambda self, timeout=0: None)
|
||||
@@ -37,7 +37,7 @@ def test_default_stage_config_includes_cache_backend(monkeypatch):
|
||||
|
||||
def test_default_cache_config_used_when_missing(monkeypatch):
|
||||
"""Ensure default cache_config is applied when cache_backend is set."""
|
||||
monkeypatch.setattr(omni_module, "load_stage_configs_from_model", lambda model: [])
|
||||
monkeypatch.setattr(omni_module, "load_stage_configs_from_model", lambda model, base_engine_args=None: [])
|
||||
monkeypatch.setattr(omni_module, "resolve_model_config_path", lambda model: None)
|
||||
monkeypatch.setattr(AsyncOmni, "_start_stages", lambda self, model: None)
|
||||
monkeypatch.setattr(AsyncOmni, "_wait_for_stages_ready", lambda self, timeout=0: None)
|
||||
@@ -55,7 +55,7 @@ def test_default_cache_config_used_when_missing(monkeypatch):
|
||||
|
||||
def test_default_stage_devices_from_sequence_parallel(monkeypatch):
|
||||
"""Ensure devices list reflects sequence parallel size when no parallel_config is provided."""
|
||||
monkeypatch.setattr(omni_module, "load_stage_configs_from_model", lambda model: [])
|
||||
monkeypatch.setattr(omni_module, "load_stage_configs_from_model", lambda model, base_engine_args=None: [])
|
||||
monkeypatch.setattr(omni_module, "resolve_model_config_path", lambda model: None)
|
||||
monkeypatch.setattr(AsyncOmni, "_start_stages", lambda self, model: None)
|
||||
monkeypatch.setattr(AsyncOmni, "_wait_for_stages_ready", lambda self, timeout=0: None)
|
||||
|
||||
@@ -445,7 +445,7 @@ def mock_get_config(monkeypatch):
|
||||
def test_initialize_stage_configs_called_when_none(monkeypatch, fake_stage_config):
|
||||
"""Test that stage configs are auto-loaded when stage_configs_path is None."""
|
||||
|
||||
def _fake_loader(model: str):
|
||||
def _fake_loader(model: str, base_engine_args=None):
|
||||
return [
|
||||
_FakeStageConfig(fake_stage_config),
|
||||
_FakeStageConfig(fake_stage_config),
|
||||
@@ -510,7 +510,7 @@ def test_initialize_stage_configs_called_when_none(monkeypatch, fake_stage_confi
|
||||
def test_generate_raises_on_length_mismatch(monkeypatch, fake_stage_config):
|
||||
"""Test that generate raises ValueError when sampling_params_list length doesn't match."""
|
||||
|
||||
def _fake_loader(model: str):
|
||||
def _fake_loader(model: str, base_engine_args=None):
|
||||
return [_FakeStageConfig(fake_stage_config)]
|
||||
|
||||
import sys
|
||||
@@ -562,7 +562,7 @@ def test_generate_pipeline_and_final_outputs(monkeypatch, fake_stage_config):
|
||||
stage_cfg1 = dict(fake_stage_config)
|
||||
stage_cfg1["processed_input"] = ["processed-for-stage-1"]
|
||||
|
||||
def _fake_loader(model: str):
|
||||
def _fake_loader(model: str, base_engine_args=None):
|
||||
return [_FakeStageConfig(stage_cfg0), _FakeStageConfig(stage_cfg1)]
|
||||
|
||||
import sys
|
||||
@@ -660,7 +660,7 @@ def test_generate_no_final_output_returns_empty(monkeypatch, fake_stage_config):
|
||||
stage_cfg0["final_output"] = False
|
||||
stage_cfg1["final_output"] = False
|
||||
|
||||
def _fake_loader(model: str):
|
||||
def _fake_loader(model: str, base_engine_args=None):
|
||||
return [_FakeStageConfig(stage_cfg0), _FakeStageConfig(stage_cfg1)]
|
||||
|
||||
import sys
|
||||
@@ -734,7 +734,7 @@ def test_generate_sampling_params_none_use_default(monkeypatch, fake_stage_confi
|
||||
stage_cfg0["final_output"] = False
|
||||
stage_cfg1["final_output"] = False
|
||||
|
||||
def _fake_loader(model: str):
|
||||
def _fake_loader(model: str, base_engine_args=None):
|
||||
return [_FakeStageConfig(stage_cfg0), _FakeStageConfig(stage_cfg1)]
|
||||
|
||||
import sys
|
||||
@@ -802,7 +802,7 @@ def test_generate_sampling_params_none_use_default(monkeypatch, fake_stage_confi
|
||||
def test_wait_for_stages_ready_timeout(monkeypatch, fake_stage_config):
|
||||
"""Test that _wait_for_stages_ready handles timeout correctly."""
|
||||
|
||||
def _fake_loader(model: str):
|
||||
def _fake_loader(model: str, base_engine_args=None):
|
||||
return [_FakeStageConfig(fake_stage_config)]
|
||||
|
||||
import sys
|
||||
@@ -858,7 +858,7 @@ def test_wait_for_stages_ready_timeout(monkeypatch, fake_stage_config):
|
||||
def test_generate_handles_error_messages(monkeypatch, fake_stage_config):
|
||||
"""Test that generate handles error messages from stages correctly."""
|
||||
|
||||
def _fake_loader(model: str):
|
||||
def _fake_loader(model: str, base_engine_args=None):
|
||||
return [_FakeStageConfig(fake_stage_config)]
|
||||
|
||||
import sys
|
||||
@@ -934,7 +934,7 @@ def test_generate_handles_error_messages(monkeypatch, fake_stage_config):
|
||||
def test_close_sends_shutdown_signal(monkeypatch, fake_stage_config):
|
||||
"""Test that close() sends shutdown signal to all input queues."""
|
||||
|
||||
def _fake_loader(model: str):
|
||||
def _fake_loader(model: str, base_engine_args=None):
|
||||
return [_FakeStageConfig(fake_stage_config)]
|
||||
|
||||
import sys
|
||||
|
||||
@@ -55,4 +55,3 @@ def test_set_stage_devices_respects_logical_ids(monkeypatch):
|
||||
set_stage_devices(stage_id=0, devices="0,1")
|
||||
|
||||
assert os.environ["CUDA_VISIBLE_DEVICES"] == "6,7"
|
||||
assert call_log and call_log[0] == 0 # current device set after remap
|
||||
+373
-4
@@ -1,11 +1,24 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
|
||||
# Some functions are copied from vllm/tests/utils.py
|
||||
import functools
|
||||
import os
|
||||
import signal
|
||||
import subprocess
|
||||
import sys
|
||||
import tempfile
|
||||
import time
|
||||
from contextlib import contextmanager
|
||||
from collections.abc import Callable
|
||||
from contextlib import ExitStack, contextmanager, suppress
|
||||
from typing import Any, Literal
|
||||
|
||||
import cloudpickle
|
||||
import pytest
|
||||
from typing_extensions import ParamSpec
|
||||
from vllm.platforms import current_platform
|
||||
from vllm.utils.torch_utils import cuda_device_count_stateless
|
||||
|
||||
_P = ParamSpec("_P")
|
||||
|
||||
if current_platform.is_rocm():
|
||||
from amdsmi import (
|
||||
@@ -90,10 +103,16 @@ def wait_for_gpu_memory_to_clear(
|
||||
print("")
|
||||
|
||||
if threshold_bytes is not None:
|
||||
is_free = lambda used, total: used <= threshold_bytes / 2**30 # noqa E731
|
||||
|
||||
def is_free(used, total):
|
||||
return used <= threshold_bytes / 2**30 # noqa E731
|
||||
|
||||
threshold = f"{threshold_bytes / 2**30} GiB"
|
||||
else:
|
||||
is_free = lambda used, total: used / total <= threshold_ratio # noqa E731
|
||||
|
||||
def is_free(used, total):
|
||||
return used / total <= threshold_ratio # noqa E731
|
||||
|
||||
threshold = f"{threshold_ratio:.2f}"
|
||||
|
||||
dur_s = time.time() - start_time
|
||||
@@ -105,3 +124,353 @@ def wait_for_gpu_memory_to_clear(
|
||||
raise ValueError(f"Memory of devices {devices=} not free after {dur_s=:.02f} ({threshold=})")
|
||||
|
||||
time.sleep(5)
|
||||
|
||||
|
||||
def fork_new_process_for_each_test(func: Callable[_P, None]) -> Callable[_P, None]:
|
||||
"""Decorator to fork a new process for each test function.
|
||||
See https://github.com/vllm-project/vllm/issues/7053 for more details.
|
||||
"""
|
||||
|
||||
@functools.wraps(func)
|
||||
def wrapper(*args: _P.args, **kwargs: _P.kwargs) -> None:
|
||||
# Make the process the leader of its own process group
|
||||
# to avoid sending SIGTERM to the parent process
|
||||
os.setpgrp()
|
||||
from _pytest.outcomes import Skipped
|
||||
|
||||
# Create a unique temporary file to store exception info from child
|
||||
# process. Use test function name and process ID to avoid collisions.
|
||||
with (
|
||||
tempfile.NamedTemporaryFile(
|
||||
delete=False, mode="w+b", prefix=f"vllm_test_{func.__name__}_{os.getpid()}_", suffix=".exc"
|
||||
) as exc_file,
|
||||
ExitStack() as delete_after,
|
||||
):
|
||||
exc_file_path = exc_file.name
|
||||
delete_after.callback(os.remove, exc_file_path)
|
||||
|
||||
pid = os.fork()
|
||||
print(f"Fork a new process to run a test {pid}")
|
||||
if pid == 0:
|
||||
# Parent process responsible for deleting, don't delete
|
||||
# in child.
|
||||
delete_after.pop_all()
|
||||
try:
|
||||
func(*args, **kwargs)
|
||||
except Skipped as e:
|
||||
# convert Skipped to exit code 0
|
||||
print(str(e))
|
||||
os._exit(0)
|
||||
except Exception as e:
|
||||
import traceback
|
||||
|
||||
tb_string = traceback.format_exc()
|
||||
|
||||
# Try to serialize the exception object first
|
||||
exc_to_serialize: dict[str, Any]
|
||||
try:
|
||||
# First, try to pickle the actual exception with
|
||||
# its traceback.
|
||||
exc_to_serialize = {"pickled_exception": e}
|
||||
# Test if it can be pickled
|
||||
cloudpickle.dumps(exc_to_serialize)
|
||||
except (Exception, KeyboardInterrupt):
|
||||
# Fall back to string-based approach.
|
||||
exc_to_serialize = {
|
||||
"exception_type": type(e).__name__,
|
||||
"exception_msg": str(e),
|
||||
"traceback": tb_string,
|
||||
}
|
||||
try:
|
||||
with open(exc_file_path, "wb") as f:
|
||||
cloudpickle.dump(exc_to_serialize, f)
|
||||
except Exception:
|
||||
# Fallback: just print the traceback.
|
||||
print(tb_string)
|
||||
os._exit(1)
|
||||
else:
|
||||
os._exit(0)
|
||||
else:
|
||||
pgid = os.getpgid(pid)
|
||||
_pid, _exitcode = os.waitpid(pid, 0)
|
||||
# ignore SIGTERM signal itself
|
||||
old_signal_handler = signal.signal(signal.SIGTERM, signal.SIG_IGN)
|
||||
# kill all child processes
|
||||
os.killpg(pgid, signal.SIGTERM)
|
||||
# restore the signal handler
|
||||
signal.signal(signal.SIGTERM, old_signal_handler)
|
||||
if _exitcode != 0:
|
||||
# Try to read the exception from the child process
|
||||
exc_info = {}
|
||||
if os.path.exists(exc_file_path):
|
||||
with suppress(Exception), open(exc_file_path, "rb") as f:
|
||||
exc_info = cloudpickle.load(f)
|
||||
|
||||
if (original_exception := exc_info.get("pickled_exception")) is not None:
|
||||
# Re-raise the actual exception object if it was
|
||||
# successfully pickled.
|
||||
assert isinstance(original_exception, Exception)
|
||||
raise original_exception
|
||||
|
||||
if (original_tb := exc_info.get("traceback")) is not None:
|
||||
# Use string-based traceback for fallback case
|
||||
raise AssertionError(
|
||||
f"Test {func.__name__} failed when called with"
|
||||
f" args {args} and kwargs {kwargs}"
|
||||
f" (exit code: {_exitcode}):\n{original_tb}"
|
||||
) from None
|
||||
|
||||
# Fallback to the original generic error
|
||||
raise AssertionError(
|
||||
f"function {func.__name__} failed when called with"
|
||||
f" args {args} and kwargs {kwargs}"
|
||||
f" (exit code: {_exitcode})"
|
||||
) from None
|
||||
|
||||
return wrapper
|
||||
|
||||
|
||||
def spawn_new_process_for_each_test(f: Callable[_P, None]) -> Callable[_P, None]:
|
||||
"""Decorator to spawn a new process for each test function."""
|
||||
|
||||
@functools.wraps(f)
|
||||
def wrapper(*args: _P.args, **kwargs: _P.kwargs) -> None:
|
||||
# Check if we're already in a subprocess
|
||||
if os.environ.get("RUNNING_IN_SUBPROCESS") == "1":
|
||||
# If we are, just run the function directly
|
||||
return f(*args, **kwargs)
|
||||
|
||||
import torch.multiprocessing as mp
|
||||
|
||||
with suppress(RuntimeError):
|
||||
mp.set_start_method("spawn")
|
||||
|
||||
# Get the module
|
||||
module_name = f.__module__
|
||||
|
||||
# Create a process with environment variable set
|
||||
env = os.environ.copy()
|
||||
env["RUNNING_IN_SUBPROCESS"] = "1"
|
||||
|
||||
with tempfile.TemporaryDirectory() as tempdir:
|
||||
output_filepath = os.path.join(tempdir, "new_process.tmp")
|
||||
|
||||
# `cloudpickle` allows pickling complex functions directly
|
||||
input_bytes = cloudpickle.dumps((f, output_filepath))
|
||||
|
||||
cmd = [sys.executable, "-m", f"{module_name}"]
|
||||
|
||||
returned = subprocess.run(cmd, input=input_bytes, capture_output=True, env=env)
|
||||
|
||||
# check if the subprocess is successful
|
||||
try:
|
||||
returned.check_returncode()
|
||||
except Exception as e:
|
||||
# wrap raised exception to provide more information
|
||||
raise RuntimeError(f"Error raised in subprocess:\n{returned.stderr.decode()}") from e
|
||||
|
||||
return wrapper
|
||||
|
||||
|
||||
def create_new_process_for_each_test(
|
||||
method: Literal["spawn", "fork"] | None = None,
|
||||
) -> Callable[[Callable[_P, None]], Callable[_P, None]]:
|
||||
"""Creates a decorator that runs each test function in a new process.
|
||||
|
||||
Args:
|
||||
method: The process creation method. Can be either "spawn" or "fork".
|
||||
If not specified, it defaults to "spawn" on ROCm and XPU
|
||||
platforms and "fork" otherwise.
|
||||
|
||||
Returns:
|
||||
A decorator to run test functions in separate processes.
|
||||
"""
|
||||
if method is None:
|
||||
# TODO: Spawn is not working correctly on ROCm
|
||||
# The test content will not run and tests passed immediately.
|
||||
# For now, using `fork` for ROCm as it can run with `fork`
|
||||
# and tests are running correctly.
|
||||
use_spawn = current_platform.is_xpu()
|
||||
method = "spawn" if use_spawn else "fork"
|
||||
|
||||
assert method in ["spawn", "fork"], "Method must be either 'spawn' or 'fork'"
|
||||
|
||||
if method == "fork":
|
||||
return fork_new_process_for_each_test
|
||||
|
||||
return spawn_new_process_for_each_test
|
||||
|
||||
|
||||
def cuda_marks(*, res: str, num_cards: int):
|
||||
"""
|
||||
Get a collection of pytest marks to apply for `@cuda_test`.
|
||||
|
||||
Args:
|
||||
res: Resource type, e.g., "L4" or "H100".
|
||||
num_cards: Number of GPU cards required.
|
||||
|
||||
Returns:
|
||||
List of pytest marks to apply.
|
||||
"""
|
||||
test_platform_detail = pytest.mark.cuda
|
||||
|
||||
if res == "L4":
|
||||
test_resource = pytest.mark.L4
|
||||
elif res == "H100":
|
||||
test_resource = pytest.mark.H100
|
||||
else:
|
||||
raise ValueError(f"Invalid CUDA resource type: {res}. Supported: L4, H100")
|
||||
|
||||
marks = [test_resource, test_platform_detail]
|
||||
|
||||
if num_cards == 1:
|
||||
return marks
|
||||
else:
|
||||
test_distributed = pytest.mark.distributed_cuda(num_cards=num_cards)
|
||||
test_skipif = pytest.mark.skipif_cuda(
|
||||
cuda_device_count_stateless() < num_cards,
|
||||
reason=f"Need at least {num_cards} CUDA GPUs to run the test.",
|
||||
)
|
||||
return marks + [test_distributed, test_skipif]
|
||||
|
||||
|
||||
def rocm_marks(*, res: str, num_cards: int):
|
||||
"""
|
||||
Get a collection of pytest marks to apply for `@rocm_test`.
|
||||
|
||||
Args:
|
||||
res: Resource type, e.g., "MI325".
|
||||
num_cards: Number of GPU cards required.
|
||||
|
||||
Returns:
|
||||
List of pytest marks to apply.
|
||||
"""
|
||||
test_platform_detail = pytest.mark.rocm
|
||||
|
||||
if res == "MI325":
|
||||
test_resource = pytest.mark.MI325
|
||||
else:
|
||||
raise ValueError(f"Invalid ROCm resource type: {res}. Supported: MI325")
|
||||
|
||||
marks = [test_resource, test_platform_detail]
|
||||
|
||||
if num_cards == 1:
|
||||
return marks
|
||||
else:
|
||||
test_distributed = pytest.mark.distributed_rocm(num_cards=num_cards)
|
||||
# TODO: add ROCm support for `skipif_rocm` marker
|
||||
return marks + [test_distributed]
|
||||
|
||||
|
||||
def gpu_marks(*, res: str, num_cards: int):
|
||||
"""
|
||||
Get a collection of pytest marks to apply for `@gpu_test`.
|
||||
Platform is automatically determined based on resource type.
|
||||
|
||||
Args:
|
||||
res: Resource type, e.g., "L4", "H100" for CUDA, or "MI325" for ROCm.
|
||||
num_cards: Number of GPU cards required.
|
||||
|
||||
Returns:
|
||||
List of pytest marks to apply.
|
||||
"""
|
||||
test_platform = pytest.mark.gpu
|
||||
if res in ("L4", "H100"):
|
||||
return [test_platform] + cuda_marks(res=res, num_cards=num_cards)
|
||||
if res == "MI325":
|
||||
return [test_platform] + rocm_marks(res=res, num_cards=num_cards)
|
||||
raise ValueError(f"Invalid resource type: {res}. Supported: L4, H100, MI325")
|
||||
|
||||
|
||||
def npu_marks(*, res: str, num_cards: int):
|
||||
"""Get a collection of pytest marks to apply for `@npu_test`."""
|
||||
test_platform = pytest.mark.npu
|
||||
if res == "A2":
|
||||
test_resource = pytest.mark.A2
|
||||
elif res == "A3":
|
||||
test_resource = pytest.mark.A3
|
||||
else:
|
||||
# TODO: Currently we don't have various NPU card types defined
|
||||
# Use None to skip resource-specific marking for unknown types
|
||||
test_resource = None
|
||||
|
||||
if num_cards == 1:
|
||||
return [mark for mark in [test_platform, test_resource] if mark is not None]
|
||||
else:
|
||||
# Multiple cards scenario needs distributed_npu mark
|
||||
test_distributed = pytest.mark.distributed_npu(num_cards=num_cards)
|
||||
# TODO: add NPU support for `skipif_npu` marker
|
||||
return [mark for mark in [test_platform, test_resource, test_distributed] if mark is not None]
|
||||
|
||||
|
||||
def hardware_test(*, res: dict[str, str], num_cards: int | dict[str, int] = 1):
|
||||
"""
|
||||
Decorate a test for multiple hardware platforms with a single call.
|
||||
Automatically wraps the test with @create_new_process_for_each_test() for distributed tests.
|
||||
|
||||
Args:
|
||||
res: Mapping from platform to resource type. Supported platforms/resources:
|
||||
- cuda: L4, H100
|
||||
- rocm: MI325
|
||||
- npu: A2, A3
|
||||
num_cards: Number of cards required. Can be:
|
||||
- int: same card count for all platforms (default: 1)
|
||||
- dict: per-platform card count, e.g., {"cuda": 2, "rocm": 2}
|
||||
|
||||
Example:
|
||||
@hardware_test(
|
||||
res={"cuda": "L4", "rocm": "MI325", "npu": "A2"},
|
||||
num_cards={"cuda": 2, "rocm": 2, "npu": 2},
|
||||
)
|
||||
def test_multi_platform():
|
||||
...
|
||||
"""
|
||||
# Validate platforms
|
||||
# Don't validate platform details in this decorator
|
||||
for platform, _ in res.items():
|
||||
if platform not in ("cuda", "rocm", "npu"):
|
||||
raise ValueError(f"Unsupported platform: {platform}")
|
||||
|
||||
# Normalize num_cards
|
||||
if isinstance(num_cards, int):
|
||||
num_cards_dict = {platform: num_cards for platform in res.keys()}
|
||||
else:
|
||||
num_cards_dict = num_cards
|
||||
for platform in num_cards_dict.keys():
|
||||
if platform not in res:
|
||||
raise ValueError(
|
||||
f"Platform '{platform}' in num_cards but not in res. Available platforms: {list(res.keys())}"
|
||||
)
|
||||
for platform in res.keys():
|
||||
if platform not in num_cards_dict:
|
||||
num_cards_dict[platform] = 1
|
||||
|
||||
# Collect marks from all platforms
|
||||
all_marks: list[Callable[[Callable[_P, None]], Callable[_P, None]]] = []
|
||||
for platform, resource in res.items():
|
||||
cards = num_cards_dict[platform]
|
||||
if platform == "cuda" or platform == "rocm":
|
||||
marks = gpu_marks(res=resource, num_cards=cards)
|
||||
elif platform == "npu":
|
||||
marks = npu_marks(res=resource, num_cards=cards)
|
||||
else:
|
||||
raise ValueError(f"Unsupported platform: {platform}")
|
||||
all_marks.extend(marks)
|
||||
|
||||
create_new_process_flag = False
|
||||
for cards in num_cards_dict.values():
|
||||
if cards > 1:
|
||||
create_new_process_flag = True
|
||||
break
|
||||
|
||||
def wrapper(f: Callable[_P, None]) -> Callable[_P, None]:
|
||||
if create_new_process_flag:
|
||||
# only for distributed tests
|
||||
func = create_new_process_for_each_test()(f)
|
||||
else:
|
||||
func = f
|
||||
for mark in reversed(all_marks):
|
||||
func = mark(func)
|
||||
return func
|
||||
|
||||
return wrapper
|
||||
@@ -0,0 +1,123 @@
|
||||
from contextlib import contextmanager
|
||||
|
||||
import torch
|
||||
|
||||
from vllm_omni.worker.gpu_model_runner import OmniGPUModelRunner
|
||||
|
||||
|
||||
class DummyBuffer:
|
||||
"""A minimal buffer wrapper that exposes the `.gpu` attribute."""
|
||||
|
||||
def __init__(self, t: torch.Tensor):
|
||||
self.gpu = t
|
||||
|
||||
|
||||
class DummyInputBatch:
|
||||
"""A minimal input batch that only provides `req_ids`."""
|
||||
|
||||
def __init__(self, req_ids):
|
||||
self.req_ids = req_ids
|
||||
|
||||
|
||||
class DummyReqState:
|
||||
"""A minimal request state container."""
|
||||
|
||||
pass
|
||||
|
||||
|
||||
class DummyTalkerMTP(torch.nn.Module):
|
||||
"""A fake talker_mtp module for deterministic CPU testing."""
|
||||
|
||||
def forward(self, req_input_ids, req_embeds, last_talker_hidden, text_step):
|
||||
# Deterministic behavior:
|
||||
# - output embeds = input embeds + 1
|
||||
# - output codes = [[0], [1], ...]
|
||||
bsz = req_embeds.shape[0]
|
||||
new_embeds = req_embeds + 1.0
|
||||
codes = torch.arange(bsz, dtype=torch.int64).view(bsz, 1)
|
||||
return new_embeds, codes
|
||||
|
||||
|
||||
@contextmanager
|
||||
def _noop_forward_context(*args, **kwargs):
|
||||
"""A no-op context manager to replace vLLM forward context in CPU tests."""
|
||||
yield
|
||||
|
||||
|
||||
def _make_runner(req_ids=("r1", "r2"), hidden_size=4):
|
||||
# Create an instance without calling OmniGPUModelRunner.__init__
|
||||
runner = object.__new__(OmniGPUModelRunner)
|
||||
|
||||
# Minimal attributes used by OmniGPUModelRunner._talker_mtp_forward
|
||||
runner.input_batch = DummyInputBatch(list(req_ids))
|
||||
runner.requests = {rid: DummyReqState() for rid in req_ids}
|
||||
|
||||
# query_start_loc.cpu[req_index] is used to locate the token position
|
||||
# in the flattened `inputs_embeds`.
|
||||
runner.query_start_loc = type("QSL", (), {})()
|
||||
# Map: r1 -> offset 0, r2 -> offset 3
|
||||
runner.query_start_loc.cpu = torch.tensor([0, 3], dtype=torch.int32)
|
||||
|
||||
bsz = len(req_ids)
|
||||
runner.talker_mtp_input_ids = DummyBuffer(torch.zeros((bsz,), dtype=torch.int64))
|
||||
runner.talker_mtp_inputs_embeds = DummyBuffer(torch.zeros((bsz, hidden_size), dtype=torch.float32))
|
||||
runner.last_talker_hidden = DummyBuffer(torch.zeros((bsz, hidden_size), dtype=torch.float32))
|
||||
runner.text_step = DummyBuffer(torch.zeros((bsz, hidden_size), dtype=torch.float32))
|
||||
|
||||
runner.talker_mtp = DummyTalkerMTP()
|
||||
runner.vllm_config = object()
|
||||
|
||||
# Provide a minimal implementation that returns the expected 4-tuple.
|
||||
def _determine_batch_execution_and_padding(**kwargs):
|
||||
return None, object(), None, None
|
||||
|
||||
runner._determine_batch_execution_and_padding = _determine_batch_execution_and_padding
|
||||
|
||||
# Use the real merge method from OmniGPUModelRunner.
|
||||
return runner
|
||||
|
||||
|
||||
def test_talker_mtp_forward_cpu_updates_inputs_and_info(monkeypatch):
|
||||
# Patch the module-level `set_forward_context` symbol used inside
|
||||
# OmniGPUModelRunner._talker_mtp_forward.
|
||||
import vllm_omni.worker.gpu_model_runner as mod # Must be the same module that defines OmniGPUModelRunner
|
||||
|
||||
monkeypatch.setattr(mod, "set_forward_context", _noop_forward_context)
|
||||
|
||||
runner = _make_runner(req_ids=("r1", "r2"), hidden_size=4)
|
||||
|
||||
# Initialize per-request embeds (batch-major inside talker_mtp_inputs_embeds)
|
||||
runner.talker_mtp_inputs_embeds.gpu[0] = torch.tensor([1.0, 2.0, 3.0, 4.0])
|
||||
runner.talker_mtp_inputs_embeds.gpu[1] = torch.tensor([10.0, 20.0, 30.0, 40.0])
|
||||
|
||||
# Flattened `inputs_embeds`: offsets 0 and 3 will be overwritten
|
||||
inputs_embeds = torch.zeros((6, 4), dtype=torch.float32)
|
||||
|
||||
# Call the original implementation from OmniGPUModelRunner (no re-implementation)
|
||||
OmniGPUModelRunner._talker_mtp_forward(runner, ["r1", "r2"], inputs_embeds)
|
||||
|
||||
# Validate embeds were written back (+1)
|
||||
assert torch.allclose(inputs_embeds[0], torch.tensor([2.0, 3.0, 4.0, 5.0]))
|
||||
assert torch.allclose(inputs_embeds[3], torch.tensor([11.0, 21.0, 31.0, 41.0]))
|
||||
|
||||
# Validate per-request additional_information_cpu was updated
|
||||
info_r1 = runner.requests["r1"].additional_information_cpu
|
||||
info_r2 = runner.requests["r2"].additional_information_cpu
|
||||
assert int(info_r1["code_predictor_codes"][0, 0]) == 0
|
||||
assert int(info_r2["code_predictor_codes"][0, 0]) == 1
|
||||
|
||||
|
||||
def test_talker_mtp_forward_cpu_empty_batch_noop(monkeypatch):
|
||||
import vllm_omni.worker.gpu_model_runner as mod
|
||||
|
||||
monkeypatch.setattr(mod, "set_forward_context", _noop_forward_context)
|
||||
|
||||
runner = _make_runner(req_ids=("r1",), hidden_size=4)
|
||||
|
||||
inputs_embeds = torch.randn((2, 4))
|
||||
before = inputs_embeds.clone()
|
||||
|
||||
OmniGPUModelRunner._talker_mtp_forward(runner, [], inputs_embeds)
|
||||
|
||||
# Ensure no changes were made
|
||||
assert torch.allclose(inputs_embeds, before)
|
||||
@@ -18,6 +18,7 @@ import regex as re
|
||||
ALLOWED_FILES = {
|
||||
"vllm_omni/entrypoints/omni_llm.py",
|
||||
"tests/e2e/offline_inference/utils.py",
|
||||
"tests/utils.py",
|
||||
"vllm_omni/diffusion/distributed/group_coordinator.py",
|
||||
"tests/diffusion/attention/test_sequence_parallel.py",
|
||||
}
|
||||
|
||||
@@ -48,6 +48,8 @@ class AttentionBackend(ABC):
|
||||
@dataclass
|
||||
class AttentionMetadata:
|
||||
attn_mask: torch.Tensor | None = None
|
||||
joint_attn_mask: torch.Tensor | None = None
|
||||
# a joint mask for the joint query, key, and value, depends the joint_strategy
|
||||
joint_query: torch.Tensor | None = None
|
||||
# a replicated tensor among processes appended to the front or rear of query, depends the joint_strategy
|
||||
joint_key: torch.Tensor | None = None
|
||||
|
||||
@@ -9,13 +9,14 @@ from vllm_omni.diffusion.attention.backends.abstract import (
|
||||
AttentionImpl,
|
||||
AttentionMetadata,
|
||||
)
|
||||
from vllm_omni.diffusion.attention.backends.utils.fa import _pad_input, _unpad_input, _upad_input
|
||||
|
||||
logger = init_logger(__name__)
|
||||
|
||||
try:
|
||||
# only tested with flash_attn v3
|
||||
# from flash_attn_interface import flash_attn_func as flash_attn_3_func # not available in flash-attn 2.8.1
|
||||
from flash_attn import flash_attn_func # can be FA2 or FA3
|
||||
from flash_attn import flash_attn_func, flash_attn_varlen_func # can be FA2 or FA3
|
||||
except ImportError:
|
||||
logger.warning(
|
||||
"FlashAttentionBackend is not available. You may install flash-attn "
|
||||
@@ -63,12 +64,51 @@ class FlashAttentionImpl(AttentionImpl):
|
||||
value: torch.Tensor,
|
||||
attn_metadata: AttentionMetadata = None,
|
||||
) -> torch.Tensor:
|
||||
# TODO: flash_attn_func does not support attn_mask.
|
||||
out: torch.Tensor = flash_attn_func(
|
||||
query,
|
||||
key,
|
||||
value,
|
||||
causal=self.causal,
|
||||
softmax_scale=self.softmax_scale,
|
||||
)
|
||||
"""
|
||||
Flash attention implementation.
|
||||
|
||||
Args:
|
||||
query: (batch_size, seq_len, num_heads, head_dim)
|
||||
key: (batch_size, seq_len, num_heads, head_dim)
|
||||
value: (batch_size, seq_len, num_heads, head_dim)
|
||||
attn_metadata: AttentionMetadata. Attention mask is supported as attn_metadata.attn_mask
|
||||
|
||||
Returns:
|
||||
(batch_size, seq_len, num_heads, head_dim)
|
||||
"""
|
||||
query_length = query.size(1)
|
||||
attention_mask = attn_metadata.attn_mask if attn_metadata is not None else None
|
||||
# Contains at least one padding token in the sequence
|
||||
if attention_mask is not None and torch.any(~attention_mask):
|
||||
assert attention_mask.ndim == 2, "attention_mask must be 2D, (batch_size, seq_len)"
|
||||
q, k, v, indices_q, (cu_seq_lens_q, cu_seq_lens_k), (max_length_q, max_length_k) = _upad_input(
|
||||
query, key, value, attention_mask, query_length, _unpad_input
|
||||
)
|
||||
|
||||
out_unpad = flash_attn_varlen_func(
|
||||
q,
|
||||
k,
|
||||
v,
|
||||
cu_seqlens_q=cu_seq_lens_q,
|
||||
cu_seqlens_k=cu_seq_lens_k,
|
||||
max_seqlen_q=max_length_q,
|
||||
max_seqlen_k=max_length_k,
|
||||
**{
|
||||
"causal": self.causal,
|
||||
"softmax_scale": self.softmax_scale,
|
||||
},
|
||||
)
|
||||
if isinstance(out_unpad, tuple):
|
||||
out_unpad = out_unpad[0]
|
||||
|
||||
out = _pad_input(out_unpad, indices_q, query.size(0), query_length)
|
||||
|
||||
else:
|
||||
out: torch.Tensor = flash_attn_func(
|
||||
query,
|
||||
key,
|
||||
value,
|
||||
causal=self.causal,
|
||||
softmax_scale=self.softmax_scale,
|
||||
)
|
||||
return out
|
||||
@@ -28,6 +28,20 @@ def ring_flash_attn_forward(
|
||||
joint_tensor_value=None,
|
||||
joint_strategy="front",
|
||||
):
|
||||
# Validate causal + joint_strategy combination
|
||||
# When causal=True and joint_strategy="rear", the causal mask would incorrectly
|
||||
# prevent local query tokens from attending to joint key tokens (which are
|
||||
# concatenated at the end). This breaks the semantics where joint tokens
|
||||
# (e.g., text conditioning) should be visible to all local tokens.
|
||||
if causal and joint_tensor_key is not None and joint_strategy == "rear":
|
||||
raise ValueError(
|
||||
"joint_strategy='rear' is not compatible with causal=True in Ring Attention. "
|
||||
"When using causal attention with joint tokens, use joint_strategy='front' "
|
||||
"to ensure joint tokens act as a visible prefix for all local tokens. "
|
||||
"With 'rear' strategy, the causal mask would incorrectly block local tokens "
|
||||
"from seeing the joint tokens."
|
||||
)
|
||||
|
||||
comm = RingComm(process_group)
|
||||
|
||||
out = None
|
||||
|
||||
@@ -62,6 +62,20 @@ class RingAttentionFunc(torch.autograd.Function):
|
||||
joint_tensor_value=None,
|
||||
joint_strategy="front",
|
||||
):
|
||||
# Validate causal + joint_strategy combination
|
||||
# When causal=True and joint_strategy="rear", the causal mask would incorrectly
|
||||
# prevent local query tokens from attending to joint key tokens (which are
|
||||
# concatenated at the end). This breaks the semantics where joint tokens
|
||||
# (e.g., text conditioning) should be visible to all local tokens.
|
||||
if is_causal and joint_tensor_key is not None and joint_strategy == "rear":
|
||||
raise ValueError(
|
||||
"joint_strategy='rear' is not compatible with causal=True in Ring Attention. "
|
||||
"When using causal attention with joint tokens, use joint_strategy='front' "
|
||||
"to ensure joint tokens act as a visible prefix for all local tokens. "
|
||||
"With 'rear' strategy, the causal mask would incorrectly block local tokens "
|
||||
"from seeing the joint tokens."
|
||||
)
|
||||
|
||||
comm = RingComm(group)
|
||||
# Ensure tensors are contiguous for P2P communication
|
||||
q = q.contiguous()
|
||||
|
||||
@@ -0,0 +1,13 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
"""
|
||||
Utils for attention backends.
|
||||
"""
|
||||
|
||||
from vllm_omni.diffusion.attention.backends.utils.fa import _pad_input, _unpad_input, _upad_input
|
||||
|
||||
__all__ = [
|
||||
"_pad_input",
|
||||
"_unpad_input",
|
||||
"_upad_input",
|
||||
]
|
||||
@@ -0,0 +1,209 @@
|
||||
# Copyright 2025 The Fairseq Authors and the HuggingFace Inc. team. All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
# Adapted from https://github.com/huggingface/transformers/blob/main/src/transformers/modeling_flash_attention_utils.py
|
||||
import torch
|
||||
import torch.nn.functional as F
|
||||
|
||||
|
||||
def _index_first_axis(tensor, indices):
|
||||
"""
|
||||
A local implementation of the PyTorch indexing operation `tensor[indices]` on the first axis,
|
||||
after flattening the first two dimensions of the tensor. This is functionally equivalent to
|
||||
FA2's `index_first_axis` and replaces the need to import it.
|
||||
"""
|
||||
# The input tensor is expected to be of shape (batch, seq_len, ...). We flatten the first
|
||||
# two dimensions to get (total_tokens, ...) before indexing.
|
||||
reshaped_tensor = tensor.reshape(-1, *tensor.shape[2:])
|
||||
return reshaped_tensor[indices]
|
||||
|
||||
|
||||
def _unpad_input(hidden_states, attention_mask, unused_mask=None):
|
||||
"""
|
||||
unpad_input function for flash attention variants that do not have them within their pkg themselves, e.g. fa3.
|
||||
|
||||
Arguments:
|
||||
hidden_states: (batch, seqlen, ...)
|
||||
attention_mask: (batch, seqlen), bool / int, 1 means valid and 0 means not valid.
|
||||
unused_mask: (batch, seqlen), bool / int, 1 means the element is allocated but unused.
|
||||
|
||||
Return:
|
||||
hidden_states: (total_nnz, ...), where total_nnz = number of tokens selected in attention_mask + unused_mask.
|
||||
indices: (total_nnz), the indices of masked tokens from the flattened input sequence.
|
||||
cu_seqlens: (batch + 1), the cumulative sequence lengths, used to index into hidden_states.
|
||||
max_seqlen_in_batch: int
|
||||
seqused: (batch), returns the number of tokens selected in attention_mask + unused_mask.
|
||||
"""
|
||||
all_masks = (attention_mask + unused_mask) if unused_mask is not None else attention_mask
|
||||
seqlens_in_batch = all_masks.sum(dim=-1, dtype=torch.int32)
|
||||
used_seqlens_in_batch = attention_mask.sum(dim=-1, dtype=torch.int32)
|
||||
indices = torch.nonzero(all_masks.flatten(), as_tuple=False).flatten()
|
||||
max_seqlen_in_batch = seqlens_in_batch.max().item()
|
||||
cu_seqlens = F.pad(torch.cumsum(seqlens_in_batch, dim=0, dtype=torch.int32), (1, 0))
|
||||
|
||||
return (
|
||||
_index_first_axis(hidden_states, indices),
|
||||
indices,
|
||||
cu_seqlens,
|
||||
max_seqlen_in_batch,
|
||||
used_seqlens_in_batch,
|
||||
)
|
||||
|
||||
|
||||
def _pad_input(hidden_states, indices, batch, seqlen):
|
||||
"""
|
||||
pad_input function for flash attention variants that do not have them within their pkg themselves, e.g. fa3.
|
||||
|
||||
Arguments:
|
||||
hidden_states: (total_nnz, ...), where total_nnz = number of tokens in selected in attention_mask.
|
||||
indices: (total_nnz), the indices that represent the non-masked tokens of the original padded input sequence.
|
||||
batch: int, batch size for the padded sequence.
|
||||
seqlen: int, maximum sequence length for the padded sequence.
|
||||
|
||||
Return:
|
||||
hidden_states: (batch, seqlen, ...)
|
||||
"""
|
||||
dim = hidden_states.shape[1:]
|
||||
output = torch.zeros((batch * seqlen), *dim, device=hidden_states.device, dtype=hidden_states.dtype)
|
||||
output[indices] = hidden_states
|
||||
return output.view(batch, seqlen, *dim)
|
||||
|
||||
|
||||
def _get_unpad_data(attention_mask: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor, int]:
|
||||
"""
|
||||
Retrieves indexing data required to repad unpadded (ragged) tensors.
|
||||
|
||||
Arguments:
|
||||
attention_mask (`torch.Tensor`):
|
||||
Boolean or int tensor of shape (batch_size, sequence_length), 1 means valid and 0 means not valid.
|
||||
|
||||
Return:
|
||||
indices (`torch.Tensor`):
|
||||
The indices of non-masked tokens from the flattened input sequence.
|
||||
cu_seqlens (`torch.Tensor`):
|
||||
The cumulative sequence lengths, used to index into ragged (unpadded) tensors.
|
||||
`cu_seqlens` shape is (batch_size + 1,).
|
||||
max_seqlen_in_batch (`int`):
|
||||
Maximum sequence length in batch.
|
||||
"""
|
||||
seqlens_in_batch = attention_mask.sum(dim=-1, dtype=torch.int32)
|
||||
indices = torch.nonzero(attention_mask.flatten(), as_tuple=False).flatten()
|
||||
# NOTE: Similar to the `.item()` in prepare_fa2_from_position_ids, with torch compile,
|
||||
# this might cause a graph break
|
||||
max_seqlen_in_batch = seqlens_in_batch.max().item()
|
||||
cu_seqlens = F.pad(torch.cumsum(seqlens_in_batch, dim=0, dtype=torch.int32), (1, 0))
|
||||
return (
|
||||
indices,
|
||||
cu_seqlens,
|
||||
max_seqlen_in_batch,
|
||||
)
|
||||
|
||||
|
||||
def _upad_input(
|
||||
query_layer: torch.Tensor,
|
||||
key_layer: torch.Tensor,
|
||||
value_layer: torch.Tensor,
|
||||
attention_mask: torch.Tensor,
|
||||
query_length: int,
|
||||
unpad_input_func,
|
||||
):
|
||||
"""
|
||||
Unpads query, key, and values tensors, using a single dimension for all tokens even though they belong
|
||||
to different batches. This function is used instead of `flash_attn.bert_padding.unpad_input` in
|
||||
order to avoid the recomputation of the same intermediary tensors for query, key, value tensors.
|
||||
|
||||
Arguments:
|
||||
query_layer (`torch.Tensor`):
|
||||
Query state with padding. Shape: (batch_size, query_length, num_heads, head_dim).
|
||||
key_layer (`torch.Tensor`):
|
||||
Key state with padding. Shape: (batch_size, kv_seq_len, num_key_value_heads, head_dim).
|
||||
value_layer (`torch.Tensor`):
|
||||
Value state with padding. Shape: (batch_size, kv_seq_len, num_key_value_heads, head_dim).
|
||||
attention_mask (`torch.Tensor`):
|
||||
Boolean or int tensor of shape (batch_size, sequence_length), 1 means valid and 0 means not valid.
|
||||
query_length (`int`):
|
||||
Target length.
|
||||
unpad_input_func:
|
||||
The function to use for unpadding the input tensors.
|
||||
|
||||
Return:
|
||||
query_layer (`torch.Tensor`):
|
||||
Query state without padding. Shape: (total_target_length, num_heads, head_dim).
|
||||
key_layer (`torch.Tensor`):
|
||||
Key state with padding. Shape: (total_source_length, num_key_value_heads, head_dim).
|
||||
value_layer (`torch.Tensor`):
|
||||
Value state with padding. Shape: (total_source_length, num_key_value_heads, head_dim).
|
||||
indices_q (`torch.Tensor`):
|
||||
The indices of non-masked tokens from the flattened input target sequence.
|
||||
(cu_seqlens_q, cu_seqlens_k) (`tuple[int]`):
|
||||
The cumulative sequence lengths for the target (query) and source (key, value), used to index into
|
||||
ragged (unpadded) tensors. `cu_seqlens` shape is (batch_size + 1,).
|
||||
(max_seqlen_in_batch_q, max_seqlen_in_batch_k) (`tuple[int]`):
|
||||
Maximum sequence length in batch (`max_seqlen_in_batch_q` for the target sequence i.e. query,
|
||||
`max_seqlen_in_batch_k` for the source sequence i.e. key/value).
|
||||
"""
|
||||
if torch.compiler.is_compiling():
|
||||
# allow PyTorch compiler to include operations that return scalar values (like .item()
|
||||
torch._dynamo.config.capture_scalar_outputs = True
|
||||
indices_k, cu_seqlens_k, max_seqlen_in_batch_k = _get_unpad_data(attention_mask)
|
||||
|
||||
# With static caches, the k/v states may be larger than the mask ->
|
||||
# we need to slice them to avoid generating garbage
|
||||
# It's a bit of an anti-pattern, but otherwise we silently compute wrong attentions scores
|
||||
if key_layer.shape[1] > (seq_len := attention_mask.shape[-1]):
|
||||
key_layer, value_layer = key_layer[:, :seq_len, :, :], value_layer[:, :seq_len, :, :]
|
||||
|
||||
batch_size, kv_seq_len, num_key_value_heads, head_dim = key_layer.shape
|
||||
|
||||
key_layer = _index_first_axis(key_layer, indices_k)
|
||||
value_layer = _index_first_axis(value_layer, indices_k)
|
||||
if query_length == kv_seq_len:
|
||||
query_layer = _index_first_axis(query_layer, indices_k)
|
||||
cu_seqlens_q = cu_seqlens_k
|
||||
max_seqlen_in_batch_q = max_seqlen_in_batch_k
|
||||
indices_q = indices_k
|
||||
elif query_length == 1:
|
||||
max_seqlen_in_batch_q = 1
|
||||
cu_seqlens_q = torch.arange(
|
||||
batch_size + 1, dtype=torch.int32, device=query_layer.device
|
||||
) # There is a memcpy here, that is very bad.
|
||||
indices_q = cu_seqlens_q[:-1]
|
||||
query_layer = query_layer.squeeze(1)
|
||||
else:
|
||||
# The -q_len: slice assumes left padding.
|
||||
attention_mask = attention_mask[:, -query_length:]
|
||||
query_layer, indices_q, cu_seqlens_q, max_seqlen_in_batch_q, *_ = unpad_input_func(query_layer, attention_mask)
|
||||
|
||||
return (
|
||||
query_layer,
|
||||
key_layer,
|
||||
value_layer,
|
||||
indices_q,
|
||||
(cu_seqlens_q, cu_seqlens_k),
|
||||
(max_seqlen_in_batch_q, max_seqlen_in_batch_k),
|
||||
)
|
||||
|
||||
|
||||
def _is_packed_sequence(position_ids, batch_size):
|
||||
"""
|
||||
Check the position ids whether packed sequences are indicated or not
|
||||
1. Position ids exist
|
||||
2. Flattened sequences only are supported
|
||||
3. Compile-friendly `not (torch.diff(position_ids, dim=-1) >= 0).all()`, i.e.
|
||||
we have multiple increasing sequences
|
||||
"""
|
||||
if position_ids is None:
|
||||
return False
|
||||
|
||||
increasing_position_sequences = torch.arange(position_ids.shape[1], device=position_ids.device) + position_ids.min()
|
||||
return batch_size == 1 and (increasing_position_sequences - position_ids).abs().sum().bool()
|
||||
@@ -163,6 +163,36 @@ class UlyssesParallelAttention:
|
||||
joint_len=joint_len,
|
||||
joint_strategy=joint_strategy,
|
||||
)
|
||||
|
||||
if attn_metadata is not None:
|
||||
if is_joint:
|
||||
if attn_metadata.joint_attn_mask is None and attn_metadata.attn_mask is None:
|
||||
attn_metadata.attn_mask = None
|
||||
else:
|
||||
if attn_metadata.attn_mask is None:
|
||||
attn_metadata.attn_mask = torch.ones(
|
||||
[query.shape[0], query.shape[1] - attn_metadata.joint_attn_mask.shape[1]],
|
||||
dtype=torch.bool,
|
||||
device=query.device,
|
||||
)
|
||||
elif attn_metadata.joint_attn_mask is None:
|
||||
attn_metadata.joint_attn_mask = torch.ones(
|
||||
[query.shape[0], query.shape[1] - attn_metadata.attn_mask.shape[1]],
|
||||
dtype=torch.bool,
|
||||
device=query.device,
|
||||
)
|
||||
attn_metadata.attn_mask = (
|
||||
torch.cat([attn_metadata.joint_attn_mask, attn_metadata.attn_mask], dim=1)
|
||||
if joint_strategy == "front"
|
||||
else torch.cat([attn_metadata.attn_mask, attn_metadata.joint_attn_mask], dim=1)
|
||||
)
|
||||
|
||||
if attn_metadata.attn_mask is not None:
|
||||
# the final attn_mask is ready, the length should be aligedn with query length
|
||||
assert attn_metadata.attn_mask.shape[1] == query.shape[1], (
|
||||
f"attn_mask length: {attn_metadata.attn_mask.shape[1]} != query length: {query.shape[1]}"
|
||||
)
|
||||
attn_metadata.attn_mask = attn_metadata.attn_mask.bool().contiguous()
|
||||
return query, key, value, attn_metadata, ctx
|
||||
|
||||
def post_attention(self, attn_output: torch.Tensor, ctx: ParallelAttentionContext | None) -> torch.Tensor:
|
||||
|
||||
@@ -31,6 +31,8 @@ _BACKEND_CONFIG = {
|
||||
"ASCEND": {"module": "vllm_omni.diffusion.attention.backends.ascend_attn", "class": "AscendAttentionBackend"},
|
||||
}
|
||||
|
||||
_BACKENDS_SUPPORT_ATTENTION_MASK = ["SDPA", "ASCEND", "FLASH_ATTN"]
|
||||
|
||||
|
||||
def load_backend(backend_name: str) -> type[AttentionBackend]:
|
||||
config = _BACKEND_CONFIG[backend_name]
|
||||
|
||||
+387
@@ -7,11 +7,19 @@ This module provides a CacheDiTBackend class to enable cache-dit acceleration on
|
||||
pipelines in vllm-omni, supporting both single and dual-transformer architectures.
|
||||
"""
|
||||
|
||||
import functools
|
||||
from collections.abc import Callable
|
||||
from contextlib import ExitStack
|
||||
from typing import Any, Optional
|
||||
|
||||
import cache_dit
|
||||
import torch
|
||||
from cache_dit import BlockAdapter, DBCacheConfig, ForwardPattern, ParamsModifier, TaylorSeerCalibratorConfig
|
||||
from cache_dit.caching.block_adapters import FakeDiffusionPipeline
|
||||
from cache_dit.caching.cache_adapters.cache_adapter import CachedAdapter
|
||||
from cache_dit.caching.cache_blocks.pattern_0_1_2 import CachedBlocks_Pattern_0_1_2
|
||||
from cache_dit.caching.cache_contexts import BasicCacheConfig
|
||||
from cache_dit.caching.cache_contexts.cache_manager import CachedContextManager
|
||||
from vllm.logger import init_logger
|
||||
|
||||
from vllm_omni.diffusion.cache.base import CacheBackend
|
||||
@@ -401,6 +409,384 @@ def enable_cache_for_dit(pipeline: Any, cache_config: Any) -> Callable[[int], No
|
||||
return refresh_cache_context
|
||||
|
||||
|
||||
class BagelCachedContextManager(CachedContextManager):
|
||||
"""
|
||||
Custom CachedContextManager for Bagel that safely handles NaiveCache objects
|
||||
(mapped to encoder_hidden_states) by skipping tensor operations on them.
|
||||
"""
|
||||
|
||||
@torch.compiler.disable
|
||||
def apply_cache(
|
||||
self,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor = None,
|
||||
prefix: str = "Bn",
|
||||
encoder_prefix: str = "Bn_encoder",
|
||||
) -> tuple[torch.Tensor, torch.Tensor | None]:
|
||||
# Allow Bn and Fn prefix to be used for residual cache.
|
||||
if "Bn" in prefix:
|
||||
hidden_states_prev = self.get_Bn_buffer(prefix)
|
||||
else:
|
||||
hidden_states_prev = self.get_Fn_buffer(prefix)
|
||||
|
||||
assert hidden_states_prev is not None, f"{prefix}_buffer must be set before"
|
||||
|
||||
if self.is_cache_residual():
|
||||
hidden_states = hidden_states_prev + hidden_states
|
||||
else:
|
||||
# If cache is not residual, we use the hidden states directly
|
||||
hidden_states = hidden_states_prev
|
||||
|
||||
hidden_states = hidden_states.contiguous()
|
||||
|
||||
if encoder_hidden_states is not None:
|
||||
if "Bn" in encoder_prefix:
|
||||
encoder_hidden_states_prev = self.get_Bn_encoder_buffer(encoder_prefix)
|
||||
else:
|
||||
encoder_hidden_states_prev = self.get_Fn_encoder_buffer(encoder_prefix)
|
||||
|
||||
if encoder_hidden_states_prev is not None:
|
||||
if self.is_encoder_cache_residual():
|
||||
# FIX: Check if encoder_hidden_states is a tensor before adding
|
||||
if isinstance(encoder_hidden_states, torch.Tensor) and isinstance(
|
||||
encoder_hidden_states_prev, torch.Tensor
|
||||
):
|
||||
encoder_hidden_states = encoder_hidden_states_prev + encoder_hidden_states
|
||||
else:
|
||||
# If encoder cache is not residual, we use the encoder hidden states directly
|
||||
encoder_hidden_states = encoder_hidden_states_prev
|
||||
|
||||
# FIX: Check if encoder_hidden_states is a tensor before calling contiguous
|
||||
if isinstance(encoder_hidden_states, torch.Tensor):
|
||||
encoder_hidden_states = encoder_hidden_states.contiguous()
|
||||
|
||||
return hidden_states, encoder_hidden_states
|
||||
|
||||
|
||||
class BagelCachedBlocks(CachedBlocks_Pattern_0_1_2):
|
||||
"""
|
||||
Custom CachedBlocks for Bagel that safely handles NaiveCache objects
|
||||
by adding isinstance checks in call_Mn_blocks and compute_or_prune.
|
||||
"""
|
||||
|
||||
def call_Mn_blocks(
|
||||
self,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor,
|
||||
*args,
|
||||
**kwargs,
|
||||
):
|
||||
original_hidden_states = hidden_states
|
||||
original_encoder_hidden_states = encoder_hidden_states
|
||||
for block in self._Mn_blocks():
|
||||
hidden_states = block(
|
||||
hidden_states,
|
||||
encoder_hidden_states,
|
||||
*args,
|
||||
**kwargs,
|
||||
)
|
||||
hidden_states, encoder_hidden_states = self._process_block_outputs(hidden_states, encoder_hidden_states)
|
||||
|
||||
# compute hidden_states residual
|
||||
hidden_states = hidden_states.contiguous()
|
||||
|
||||
hidden_states_residual = hidden_states - original_hidden_states
|
||||
|
||||
if (
|
||||
encoder_hidden_states is not None
|
||||
and original_encoder_hidden_states is not None
|
||||
and isinstance(encoder_hidden_states, torch.Tensor) # FIX: Added Check
|
||||
):
|
||||
encoder_hidden_states = encoder_hidden_states.contiguous()
|
||||
encoder_hidden_states_residual = encoder_hidden_states - original_encoder_hidden_states
|
||||
else:
|
||||
encoder_hidden_states_residual = None
|
||||
|
||||
return (
|
||||
hidden_states,
|
||||
encoder_hidden_states,
|
||||
hidden_states_residual,
|
||||
encoder_hidden_states_residual,
|
||||
)
|
||||
|
||||
def compute_or_prune(
|
||||
self,
|
||||
block_id: int, # Block index in the transformer blocks
|
||||
# Below are the inputs to the block
|
||||
block, # The transformer block to be executed
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor,
|
||||
*args,
|
||||
**kwargs,
|
||||
):
|
||||
# NOTE: Although Bagel likely won't use pruning, implementing safe version just in case.
|
||||
# Copy-pasted from original but adding checks.
|
||||
|
||||
original_hidden_states = hidden_states
|
||||
original_encoder_hidden_states = encoder_hidden_states
|
||||
|
||||
can_use_prune = self._maybe_prune(
|
||||
block_id,
|
||||
hidden_states,
|
||||
prefix=f"{self.cache_prefix}_{block_id}_Fn_original",
|
||||
)
|
||||
|
||||
torch._dynamo.graph_break()
|
||||
if can_use_prune:
|
||||
self.context_manager.add_pruned_step()
|
||||
hidden_states, encoder_hidden_states = self.context_manager.apply_prune(
|
||||
hidden_states,
|
||||
encoder_hidden_states,
|
||||
prefix=(
|
||||
f"{self.cache_prefix}_{block_id}_Bn_residual"
|
||||
if self.context_manager.is_cache_residual()
|
||||
else f"{self.cache_prefix}_Bn_hidden_states"
|
||||
),
|
||||
encoder_prefix=(
|
||||
f"{self.cache_prefix}_{block_id}_Bn_encoder_residual"
|
||||
if self.context_manager.is_encoder_cache_residual()
|
||||
else f"{self.cache_prefix}_{block_id}_Bn_encoder_hidden_states"
|
||||
),
|
||||
)
|
||||
torch._dynamo.graph_break()
|
||||
else:
|
||||
# Normal steps: Compute the block and cache the residuals.
|
||||
hidden_states = block(
|
||||
hidden_states,
|
||||
encoder_hidden_states,
|
||||
*args,
|
||||
**kwargs,
|
||||
)
|
||||
hidden_states, encoder_hidden_states = self._process_block_outputs(hidden_states, encoder_hidden_states)
|
||||
if not self._skip_prune(block_id):
|
||||
hidden_states = hidden_states.contiguous()
|
||||
hidden_states_residual = hidden_states - original_hidden_states
|
||||
|
||||
if (
|
||||
encoder_hidden_states is not None
|
||||
and original_encoder_hidden_states is not None
|
||||
and isinstance(encoder_hidden_states, torch.Tensor) # FIX: Added Check
|
||||
):
|
||||
encoder_hidden_states = encoder_hidden_states.contiguous()
|
||||
encoder_hidden_states_residual = encoder_hidden_states - original_encoder_hidden_states
|
||||
else:
|
||||
encoder_hidden_states_residual = None
|
||||
|
||||
self.context_manager.set_Fn_buffer(
|
||||
original_hidden_states,
|
||||
prefix=f"{self.cache_prefix}_{block_id}_Fn_original",
|
||||
)
|
||||
if self.context_manager.is_cache_residual():
|
||||
self.context_manager.set_Bn_buffer(
|
||||
hidden_states_residual,
|
||||
prefix=f"{self.cache_prefix}_{block_id}_Bn_residual",
|
||||
)
|
||||
else:
|
||||
self.context_manager.set_Bn_buffer(
|
||||
hidden_states,
|
||||
prefix=f"{self.cache_prefix}_{block_id}_Bn_hidden_states",
|
||||
)
|
||||
if encoder_hidden_states_residual is not None:
|
||||
if self.context_manager.is_encoder_cache_residual():
|
||||
self.context_manager.set_Bn_encoder_buffer(
|
||||
encoder_hidden_states_residual,
|
||||
prefix=f"{self.cache_prefix}_{block_id}_Bn_encoder_residual",
|
||||
)
|
||||
else:
|
||||
self.context_manager.set_Bn_encoder_buffer(
|
||||
encoder_hidden_states_residual,
|
||||
prefix=f"{self.cache_prefix}_{block_id}_Bn_encoder_hidden_states",
|
||||
)
|
||||
torch._dynamo.graph_break()
|
||||
|
||||
return hidden_states, encoder_hidden_states
|
||||
|
||||
|
||||
class BagelCachedAdapter(CachedAdapter):
|
||||
"""
|
||||
Custom CachedAdapter for Bagel that uses BagelCachedContextManager and BagelCachedBlocks.
|
||||
"""
|
||||
|
||||
@classmethod
|
||||
def create_context(
|
||||
cls,
|
||||
block_adapter: BlockAdapter,
|
||||
**context_kwargs,
|
||||
) -> tuple[list[str], list[dict[str, Any]]]:
|
||||
# Override to use BagelCachedContextManager
|
||||
|
||||
BlockAdapter.assert_normalized(block_adapter)
|
||||
|
||||
if BlockAdapter.is_cached(block_adapter.pipe):
|
||||
return block_adapter.pipe
|
||||
|
||||
# Check context_kwargs
|
||||
context_kwargs = cls.check_context_kwargs(block_adapter, **context_kwargs)
|
||||
|
||||
# Each Pipeline should have it's own context manager instance.
|
||||
cache_config: BasicCacheConfig = context_kwargs.get("cache_config", None)
|
||||
assert cache_config is not None, "cache_config can not be None."
|
||||
|
||||
# Apply cache on pipeline: wrap cache context
|
||||
pipe_cls_name = block_adapter.pipe.__class__.__name__
|
||||
|
||||
# USE CUSTOM CONTEXT MANAGER
|
||||
context_manager = BagelCachedContextManager(
|
||||
name=f"{pipe_cls_name}_{hash(id(block_adapter.pipe))}",
|
||||
persistent_context=isinstance(block_adapter.pipe, FakeDiffusionPipeline),
|
||||
)
|
||||
|
||||
flatten_contexts, contexts_kwargs = cls.modify_context_params(block_adapter, **context_kwargs)
|
||||
|
||||
block_adapter.pipe._context_manager = context_manager # instance level
|
||||
|
||||
if not context_manager.persistent_context:
|
||||
original_call = block_adapter.pipe.__class__.__call__
|
||||
|
||||
@functools.wraps(original_call)
|
||||
def new_call(self, *args, **kwargs):
|
||||
with ExitStack() as stack:
|
||||
# cache context will be reset for each pipe inference
|
||||
for context_name, context_kwargs in zip(flatten_contexts, contexts_kwargs):
|
||||
stack.enter_context(
|
||||
context_manager.enter_context(
|
||||
context_manager.reset_context(
|
||||
context_name,
|
||||
**context_kwargs,
|
||||
),
|
||||
)
|
||||
)
|
||||
outputs = original_call(self, *args, **kwargs)
|
||||
cls.apply_stats_hooks(block_adapter)
|
||||
return outputs
|
||||
|
||||
block_adapter.pipe.__class__.__call__ = new_call
|
||||
block_adapter.pipe.__class__._original_call = original_call
|
||||
|
||||
else:
|
||||
# Init persistent cache context for transformer
|
||||
for context_name, context_kwargs in zip(flatten_contexts, contexts_kwargs):
|
||||
context_manager.reset_context(
|
||||
context_name,
|
||||
**context_kwargs,
|
||||
)
|
||||
|
||||
block_adapter.pipe.__class__._is_cached = True
|
||||
|
||||
cls.apply_params_hooks(block_adapter, contexts_kwargs)
|
||||
|
||||
return flatten_contexts, contexts_kwargs
|
||||
|
||||
@classmethod
|
||||
def collect_unified_blocks(
|
||||
cls,
|
||||
block_adapter: BlockAdapter,
|
||||
contexts_kwargs: list[dict],
|
||||
) -> list[dict[str, torch.nn.ModuleList]]:
|
||||
# Override to use BagelCachedBlocks
|
||||
|
||||
BlockAdapter.assert_normalized(block_adapter)
|
||||
|
||||
total_cached_blocks: list[dict[str, torch.nn.ModuleList]] = []
|
||||
assert hasattr(block_adapter.pipe, "_context_manager")
|
||||
# Skipping isinstance check for ContextManager._supported_managers to avoid import issues
|
||||
|
||||
for i in range(len(block_adapter.transformer)):
|
||||
unified_blocks_bind_context = {}
|
||||
for j in range(len(block_adapter.blocks[i])):
|
||||
cache_config: BasicCacheConfig = contexts_kwargs[i * len(block_adapter.blocks[i]) + j]["cache_config"]
|
||||
|
||||
# Directly instantiate BagelCachedBlocks
|
||||
unified_blocks_bind_context[block_adapter.unique_blocks_name[i][j]] = torch.nn.ModuleList(
|
||||
[
|
||||
BagelCachedBlocks(
|
||||
# 0. Transformer blocks configuration
|
||||
block_adapter.blocks[i][j],
|
||||
transformer=block_adapter.transformer[i],
|
||||
forward_pattern=block_adapter.forward_pattern[i][j],
|
||||
check_forward_pattern=block_adapter.check_forward_pattern,
|
||||
check_num_outputs=block_adapter.check_num_outputs,
|
||||
# 1. Cache/Prune context configuration
|
||||
cache_prefix=block_adapter.blocks_name[i][j],
|
||||
cache_context=block_adapter.unique_blocks_name[i][j],
|
||||
context_manager=block_adapter.pipe._context_manager,
|
||||
cache_type=cache_config.cache_type,
|
||||
)
|
||||
]
|
||||
)
|
||||
|
||||
total_cached_blocks.append(unified_blocks_bind_context)
|
||||
|
||||
return total_cached_blocks
|
||||
|
||||
|
||||
def enable_cache_for_bagel(pipeline: Any, cache_config: Any) -> Callable[[int], None]:
|
||||
"""Enable cache-dit for Bagel model (via OmniDiffusion pipeline).
|
||||
|
||||
Args:
|
||||
pipeline: The OmniDiffusion pipeline instance.
|
||||
cache_config: DiffusionCacheConfig instance with cache configuration.
|
||||
|
||||
Returns:
|
||||
A refresh function that can be called to update cache context with new num_inference_steps.
|
||||
"""
|
||||
# Build DBCacheConfig
|
||||
db_cache_config = _build_db_cache_config(cache_config)
|
||||
|
||||
# Build calibrator config if TaylorSeer is enabled
|
||||
calibrator_config = None
|
||||
if cache_config.enable_taylorseer:
|
||||
taylorseer_order = cache_config.taylorseer_order
|
||||
calibrator_config = TaylorSeerCalibratorConfig(taylorseer_order=taylorseer_order)
|
||||
logger.info(f"TaylorSeer enabled with order={taylorseer_order}")
|
||||
|
||||
# Access the transformer: BagelPipeline -> Qwen2MoTForCausalLM -> Qwen2MoTModel
|
||||
# BagelPipeline has self.language_model which is Qwen2MoTForCausalLM
|
||||
# Qwen2MoTForCausalLM has self.model which is Qwen2MoTModel
|
||||
transformer = pipeline.language_model.model
|
||||
|
||||
logger.info(
|
||||
f"Enabling cache-dit on Bagel transformer: "
|
||||
f"Fn={db_cache_config.Fn_compute_blocks}, "
|
||||
f"Bn={db_cache_config.Bn_compute_blocks}, "
|
||||
f"W={db_cache_config.max_warmup_steps}, "
|
||||
)
|
||||
|
||||
# Enable cache-dit on the transformer
|
||||
# Pattern_0 corresponds to (hidden_states, encoder_hidden_states) input, output
|
||||
# Custom adapter for Bagel to handle NaiveCache correctly
|
||||
# from vllm_omni.diffusion.cache.bagel_cache_adapter import BagelCachedAdapter # No longer needed
|
||||
BagelCachedAdapter.apply(
|
||||
BlockAdapter(
|
||||
transformer=transformer,
|
||||
blocks=transformer.layers,
|
||||
forward_pattern=ForwardPattern.Pattern_0,
|
||||
),
|
||||
cache_config=db_cache_config,
|
||||
calibrator_config=calibrator_config,
|
||||
)
|
||||
|
||||
def refresh_cache_context(pipeline: Any, num_inference_steps: int, verbose: bool = True) -> None:
|
||||
transformer = pipeline.language_model.model
|
||||
if cache_config.scm_steps_mask_policy is None:
|
||||
cache_dit.refresh_context(transformer, num_inference_steps=num_inference_steps, verbose=verbose)
|
||||
else:
|
||||
cache_dit.refresh_context(
|
||||
transformer,
|
||||
cache_config=DBCacheConfig().reset(
|
||||
num_inference_steps=num_inference_steps,
|
||||
steps_computation_mask=cache_dit.steps_mask(
|
||||
mask_policy=cache_config.scm_steps_mask_policy,
|
||||
total_steps=num_inference_steps,
|
||||
),
|
||||
steps_computation_policy=cache_config.scm_steps_policy,
|
||||
),
|
||||
verbose=verbose,
|
||||
)
|
||||
|
||||
return refresh_cache_context
|
||||
|
||||
|
||||
# Register custom cache-dit enablers after function definitions
|
||||
CUSTOM_DIT_ENABLERS.update(
|
||||
{
|
||||
@@ -409,6 +795,7 @@ CUSTOM_DIT_ENABLERS.update(
|
||||
"LongCatImagePipeline": enable_cache_for_longcat_image,
|
||||
"LongCatImageEditPipeline": enable_cache_for_longcat_image,
|
||||
"StableDiffusion3Pipeline": enable_cache_for_sd3,
|
||||
"BagelPipeline": enable_cache_for_bagel,
|
||||
}
|
||||
)
|
||||
|
||||
|
||||
+17
-2
@@ -20,6 +20,10 @@ import torch
|
||||
from vllm_omni.diffusion.cache.teacache.config import TeaCacheConfig
|
||||
from vllm_omni.diffusion.cache.teacache.extractors import get_extractor
|
||||
from vllm_omni.diffusion.cache.teacache.state import TeaCacheState
|
||||
from vllm_omni.diffusion.distributed.parallel_state import (
|
||||
get_classifier_free_guidance_rank,
|
||||
get_classifier_free_guidance_world_size,
|
||||
)
|
||||
from vllm_omni.diffusion.hooks import HookRegistry, ModelHook, StateManager
|
||||
|
||||
|
||||
@@ -34,6 +38,7 @@ class TeaCacheHook(ModelHook):
|
||||
Key features:
|
||||
- Zero changes to model code
|
||||
- CFG-aware with separate states for positive/negative branches
|
||||
- CFG-parallel compatible: properly detects branch identity across ranks
|
||||
- Model-specific polynomial rescaling
|
||||
- Auto-detection of model types
|
||||
|
||||
@@ -113,8 +118,18 @@ class TeaCacheHook(ModelHook):
|
||||
# GENERIC CACHING LOGIC (works for all models)
|
||||
# ============================================================================
|
||||
# Set context based on CFG branch for separate state tracking
|
||||
if module.do_true_cfg and self._forward_cnt % 2 == 1:
|
||||
cache_branch = "negative"
|
||||
# With CFG-parallel, each rank processes only one branch:
|
||||
# - cfg_rank 0: positive branch
|
||||
# - cfg_rank > 0: negative branch
|
||||
# Without CFG-parallel, branches alternate within a single rank
|
||||
if module.do_true_cfg:
|
||||
cfg_parallel_size = get_classifier_free_guidance_world_size()
|
||||
if cfg_parallel_size > 1:
|
||||
cfg_rank = get_classifier_free_guidance_rank()
|
||||
cache_branch = "negative" if cfg_rank > 0 else "positive"
|
||||
else:
|
||||
# No CFG-parallel: use forward counter to alternate branches
|
||||
cache_branch = "negative" if self._forward_cnt % 2 == 1 else "positive"
|
||||
else:
|
||||
cache_branch = "positive"
|
||||
|
||||
|
||||
@@ -0,0 +1,41 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
from typing import Any
|
||||
|
||||
import torch.nn as nn
|
||||
from vllm.logger import init_logger
|
||||
|
||||
logger = init_logger(__name__)
|
||||
|
||||
|
||||
def regionally_compile(model: nn.Module, *compile_args: Any, **compile_kwargs: Any) -> nn.Module:
|
||||
"""
|
||||
Apply regional compilation to a PyTorch model.
|
||||
|
||||
Args:
|
||||
model: The PyTorch model instance to compile
|
||||
*compile_args: Positional arguments forwarded to torch.compile
|
||||
**compile_kwargs: Keyword arguments forwarded to torch.compile
|
||||
|
||||
Returns:
|
||||
The same model instance (modified in-place)
|
||||
"""
|
||||
# Get the list of repeated blocks from the model
|
||||
repeated_blocks = getattr(model, "_repeated_blocks", None)
|
||||
|
||||
if not repeated_blocks:
|
||||
logger.warning("Regional compilation skipped because the model does not define `_repeated_blocks`.")
|
||||
return model
|
||||
|
||||
# Check if we have modules with the specified class names
|
||||
has_compiled_region = False
|
||||
for submod in model.modules():
|
||||
if submod.__class__.__name__ in repeated_blocks:
|
||||
# Compile this submodule
|
||||
submod.compile(*compile_args, **compile_kwargs)
|
||||
has_compiled_region = True
|
||||
|
||||
if not has_compiled_region:
|
||||
logger.warning(f"Regional compilation skipped because {repeated_blocks} classes are not found in the model.")
|
||||
|
||||
return model
|
||||
@@ -286,12 +286,12 @@ class OmniDiffusionConfig:
|
||||
output_type: str = "pil"
|
||||
|
||||
# CPU offload parameters
|
||||
dit_cpu_offload: bool = True
|
||||
# When enabled, DiT and encoders swap GPU access (mutual exclusion):
|
||||
# - Text encoders run on GPU while DiT is on CPU
|
||||
# - DiT runs on GPU while encoders are on CPU
|
||||
enable_cpu_offload: bool = False
|
||||
use_fsdp_inference: bool = False
|
||||
text_encoder_cpu_offload: bool = True
|
||||
image_encoder_cpu_offload: bool = True
|
||||
vae_cpu_offload: bool = True
|
||||
pin_cpu_memory: bool = True
|
||||
pin_cpu_memory: bool = True # Use pinned memory for faster transfers when offloading
|
||||
|
||||
# VAE memory optimization parameters
|
||||
vae_use_slicing: bool = False
|
||||
@@ -303,7 +303,7 @@ class OmniDiffusionConfig:
|
||||
skip_time_steps: int = 15
|
||||
|
||||
# Compilation
|
||||
enable_torch_compile: bool = False
|
||||
enforce_eager: bool = False
|
||||
|
||||
# Enable sleep mode
|
||||
enable_sleep_mode: bool = False
|
||||
|
||||
@@ -8,10 +8,15 @@ from collections.abc import Callable, Iterable
|
||||
from dataclasses import dataclass
|
||||
from typing import Any
|
||||
|
||||
import PIL.Image
|
||||
from vllm.logger import init_logger
|
||||
|
||||
from vllm_omni.diffusion.data import SHUTDOWN_MESSAGE, OmniDiffusionConfig
|
||||
from vllm_omni.diffusion.registry import get_diffusion_post_process_func, get_diffusion_pre_process_func
|
||||
from vllm_omni.diffusion.registry import (
|
||||
DiffusionModelRegistry,
|
||||
get_diffusion_post_process_func,
|
||||
get_diffusion_pre_process_func,
|
||||
)
|
||||
from vllm_omni.diffusion.request import OmniDiffusionRequest
|
||||
from vllm_omni.diffusion.scheduler import Scheduler, scheduler
|
||||
from vllm_omni.outputs import OmniRequestOutput
|
||||
@@ -20,6 +25,13 @@ from vllm_omni.utils.platform_utils import get_diffusion_worker_class
|
||||
logger = init_logger(__name__)
|
||||
|
||||
|
||||
def supports_image_input(model_class_name: str) -> bool:
|
||||
model_cls = DiffusionModelRegistry._try_load_model_cls(model_class_name)
|
||||
if model_cls is None:
|
||||
return False
|
||||
return bool(getattr(model_cls, "support_image_input", False))
|
||||
|
||||
|
||||
@dataclass
|
||||
class BackgroundResources:
|
||||
"""
|
||||
@@ -70,6 +82,12 @@ class DiffusionEngine:
|
||||
self._processes: list[mp.Process] = []
|
||||
self._closed = False
|
||||
self._make_client()
|
||||
try:
|
||||
self._dummy_run()
|
||||
except Exception as e:
|
||||
logger.error(f"Dummy run failed: {e}")
|
||||
self.close()
|
||||
raise e
|
||||
|
||||
def step(self, requests: list[OmniDiffusionRequest]):
|
||||
try:
|
||||
@@ -272,6 +290,31 @@ class DiffusionEngine:
|
||||
def add_req_and_wait_for_response(self, requests: list[OmniDiffusionRequest]):
|
||||
return scheduler.add_req(requests)
|
||||
|
||||
def _dummy_run(self):
|
||||
"""A dummy run to warm up the model."""
|
||||
prompt = "dummy run"
|
||||
# note that num_inference_steps=1 will cause timestep and temb None in the pipeline
|
||||
num_inference_steps = 1
|
||||
height = 1024
|
||||
width = 1024
|
||||
if supports_image_input(self.od_config.model_class_name):
|
||||
# Provide a dummy image input if the model supports it
|
||||
|
||||
dummy_image = PIL.Image.new("RGB", (width, height), color=(0, 0, 0))
|
||||
else:
|
||||
dummy_image = None
|
||||
req = OmniDiffusionRequest(
|
||||
prompt=prompt,
|
||||
height=height,
|
||||
width=width,
|
||||
pil_image=dummy_image,
|
||||
num_inference_steps=num_inference_steps,
|
||||
num_outputs_per_prompt=1,
|
||||
)
|
||||
logger.info("dummy run to warm up the model")
|
||||
requests = self.pre_process_func([req]) if self.pre_process_func is not None else [req]
|
||||
self.add_req_and_wait_for_response(requests)
|
||||
|
||||
def collective_rpc(
|
||||
self,
|
||||
method: str | Callable,
|
||||
@@ -343,22 +386,6 @@ class DiffusionEngine:
|
||||
logger.error(f"RPC call failed: {e}")
|
||||
raise
|
||||
|
||||
def _dummy_run(self):
|
||||
"""A dummy run to warm up the model."""
|
||||
prompt = "dummy run"
|
||||
num_inference_steps = 1
|
||||
height = 1024
|
||||
width = 1024
|
||||
req = OmniDiffusionRequest(
|
||||
prompt=prompt,
|
||||
height=height,
|
||||
width=width,
|
||||
num_inference_steps=num_inference_steps,
|
||||
num_outputs_per_prompt=1,
|
||||
)
|
||||
logger.info("dummy run to warm up the model")
|
||||
self.add_req_and_wait_for_response([req])
|
||||
|
||||
def close(self) -> None:
|
||||
self._finalizer()
|
||||
|
||||
|
||||
@@ -314,10 +314,12 @@ class Qwen2MoTDecoderLayer(nn.Module):
|
||||
|
||||
def forward(
|
||||
self,
|
||||
packed_query_sequence: torch.Tensor,
|
||||
query_lens: torch.Tensor,
|
||||
packed_query_position_embeddings: torch.Tensor,
|
||||
packed_query_indexes: torch.Tensor,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor | None = None,
|
||||
packed_query_sequence: torch.Tensor | None = None,
|
||||
query_lens: torch.Tensor = None,
|
||||
packed_query_position_embeddings: torch.Tensor = None,
|
||||
packed_query_indexes: torch.Tensor = None,
|
||||
past_key_values: NaiveCache | None = None,
|
||||
key_values_lens: torch.Tensor | None = None,
|
||||
packed_key_value_indexes: torch.Tensor | None = None,
|
||||
@@ -327,6 +329,8 @@ class Qwen2MoTDecoderLayer(nn.Module):
|
||||
packed_vae_token_indexes=None,
|
||||
packed_text_indexes=None,
|
||||
) -> BaseNavitOutputWithPast:
|
||||
if packed_query_sequence is None:
|
||||
packed_query_sequence = hidden_states
|
||||
residual = packed_query_sequence
|
||||
if mode == "und":
|
||||
packed_query_sequence = self.input_layernorm(packed_query_sequence)
|
||||
@@ -437,7 +441,8 @@ class Qwen2MoTModel(Qwen2PreTrainedModel):
|
||||
|
||||
for layer_idx, decoder_layer in enumerate(self.layers):
|
||||
packed_query_sequence, past_key_values = decoder_layer(
|
||||
packed_query_sequence=packed_query_sequence,
|
||||
hidden_states=packed_query_sequence,
|
||||
encoder_hidden_states=None,
|
||||
query_lens=query_lens,
|
||||
packed_query_position_embeddings=packed_query_position_embeddings,
|
||||
packed_query_indexes=packed_query_indexes,
|
||||
|
||||
@@ -0,0 +1,17 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
"""Flux2 klein diffusion model components."""
|
||||
|
||||
from vllm_omni.diffusion.models.flux2_klein.flux2_klein_transformer import (
|
||||
Flux2Transformer2DModel,
|
||||
)
|
||||
from vllm_omni.diffusion.models.flux2_klein.pipeline_flux2_klein import (
|
||||
Flux2KleinPipeline,
|
||||
get_flux2_klein_post_process_func,
|
||||
)
|
||||
|
||||
__all__ = [
|
||||
"Flux2KleinPipeline",
|
||||
"Flux2Transformer2DModel",
|
||||
"get_flux2_klein_post_process_func",
|
||||
]
|
||||
@@ -0,0 +1,723 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
|
||||
# Copyright 2025 Black Forest Labs, The HuggingFace Team and The InstantX Team. All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
from collections.abc import Iterable
|
||||
from types import SimpleNamespace
|
||||
from typing import Any
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from diffusers.models.embeddings import (
|
||||
TimestepEmbedding,
|
||||
Timesteps,
|
||||
get_1d_rotary_pos_embed,
|
||||
)
|
||||
from diffusers.models.modeling_outputs import Transformer2DModelOutput
|
||||
from diffusers.models.normalization import AdaLayerNormContinuous
|
||||
from vllm.model_executor.layers.layernorm import RMSNorm
|
||||
from vllm.model_executor.layers.linear import QKVParallelLinear, ReplicatedLinear
|
||||
from vllm.model_executor.model_loader.weight_utils import default_weight_loader
|
||||
|
||||
from vllm_omni.diffusion.attention.backends.abstract import AttentionMetadata
|
||||
from vllm_omni.diffusion.attention.layer import Attention
|
||||
from vllm_omni.diffusion.layers.rope import RotaryEmbedding
|
||||
|
||||
|
||||
class Flux2SwiGLU(nn.Module):
|
||||
"""SwiGLU activation used by Flux2."""
|
||||
|
||||
def __init__(self):
|
||||
super().__init__()
|
||||
self.gate_fn = nn.SiLU()
|
||||
|
||||
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
||||
x1, x2 = x.chunk(2, dim=-1)
|
||||
return self.gate_fn(x1) * x2
|
||||
|
||||
|
||||
class Flux2FeedForward(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
dim: int,
|
||||
dim_out: int | None = None,
|
||||
mult: float = 3.0,
|
||||
inner_dim: int | None = None,
|
||||
bias: bool = False,
|
||||
):
|
||||
super().__init__()
|
||||
if inner_dim is None:
|
||||
inner_dim = int(dim * mult)
|
||||
dim_out = dim_out or dim
|
||||
|
||||
self.linear_in = nn.Linear(dim, inner_dim * 2, bias=bias)
|
||||
self.act_fn = Flux2SwiGLU()
|
||||
self.linear_out = nn.Linear(inner_dim, dim_out, bias=bias)
|
||||
|
||||
def forward(self, x: torch.Tensor) -> torch.Tensor:
|
||||
x = self.linear_in(x)
|
||||
x = self.act_fn(x)
|
||||
return self.linear_out(x)
|
||||
|
||||
|
||||
class Flux2Attention(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
query_dim: int,
|
||||
heads: int = 8,
|
||||
dim_head: int = 64,
|
||||
dropout: float = 0.0,
|
||||
bias: bool = False,
|
||||
added_kv_proj_dim: int | None = None,
|
||||
added_proj_bias: bool | None = True,
|
||||
out_bias: bool = True,
|
||||
eps: float = 1e-5,
|
||||
out_dim: int = None,
|
||||
elementwise_affine: bool = True,
|
||||
):
|
||||
super().__init__()
|
||||
self.head_dim = dim_head
|
||||
self.inner_dim = out_dim if out_dim is not None else dim_head * heads
|
||||
self.query_dim = query_dim
|
||||
self.out_dim = out_dim if out_dim is not None else query_dim
|
||||
self.heads = out_dim // dim_head if out_dim is not None else heads
|
||||
self.dropout = dropout
|
||||
self.added_kv_proj_dim = added_kv_proj_dim
|
||||
|
||||
self.to_qkv = QKVParallelLinear(
|
||||
hidden_size=query_dim,
|
||||
head_size=self.head_dim,
|
||||
total_num_heads=self.heads,
|
||||
disable_tp=True,
|
||||
bias=bias,
|
||||
)
|
||||
|
||||
self.norm_q = RMSNorm(dim_head, eps=eps)
|
||||
self.norm_k = RMSNorm(dim_head, eps=eps)
|
||||
|
||||
self.to_out = nn.ModuleList(
|
||||
[ReplicatedLinear(self.inner_dim, self.out_dim, bias=out_bias), nn.Dropout(dropout)]
|
||||
)
|
||||
|
||||
if added_kv_proj_dim is not None:
|
||||
self.norm_added_q = RMSNorm(dim_head, eps=eps)
|
||||
self.norm_added_k = RMSNorm(dim_head, eps=eps)
|
||||
self.add_kv_proj = QKVParallelLinear(
|
||||
hidden_size=added_kv_proj_dim,
|
||||
head_size=self.head_dim,
|
||||
total_num_heads=self.heads,
|
||||
disable_tp=True,
|
||||
bias=added_proj_bias,
|
||||
)
|
||||
self.to_add_out = ReplicatedLinear(self.inner_dim, query_dim, bias=out_bias)
|
||||
|
||||
self.rope = RotaryEmbedding(is_neox_style=False)
|
||||
self.attn = Attention(
|
||||
num_heads=self.heads,
|
||||
head_size=self.head_dim,
|
||||
softmax_scale=1.0 / (self.head_dim**0.5),
|
||||
causal=False,
|
||||
)
|
||||
|
||||
def forward(
|
||||
self,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor | None = None,
|
||||
attention_mask: torch.Tensor | None = None,
|
||||
image_rotary_emb: tuple[torch.Tensor, torch.Tensor] | None = None,
|
||||
**kwargs,
|
||||
) -> torch.Tensor | tuple[torch.Tensor, torch.Tensor]:
|
||||
qkv, _ = self.to_qkv(hidden_states)
|
||||
query, key, value = qkv.chunk(3, dim=-1)
|
||||
|
||||
encoder_query = encoder_key = encoder_value = None
|
||||
if encoder_hidden_states is not None and self.added_kv_proj_dim is not None:
|
||||
encoder_qkv, _ = self.add_kv_proj(encoder_hidden_states)
|
||||
encoder_query, encoder_key, encoder_value = encoder_qkv.chunk(3, dim=-1)
|
||||
|
||||
query = query.unflatten(-1, (self.heads, -1))
|
||||
key = key.unflatten(-1, (self.heads, -1))
|
||||
value = value.unflatten(-1, (self.heads, -1))
|
||||
|
||||
query = self.norm_q(query)
|
||||
key = self.norm_k(key)
|
||||
|
||||
if encoder_hidden_states is not None and self.added_kv_proj_dim is not None:
|
||||
encoder_query = encoder_query.unflatten(-1, (self.heads, -1))
|
||||
encoder_key = encoder_key.unflatten(-1, (self.heads, -1))
|
||||
encoder_value = encoder_value.unflatten(-1, (self.heads, -1))
|
||||
|
||||
encoder_query = self.norm_added_q(encoder_query)
|
||||
encoder_key = self.norm_added_k(encoder_key)
|
||||
|
||||
query = torch.cat([encoder_query, query], dim=1)
|
||||
key = torch.cat([encoder_key, key], dim=1)
|
||||
value = torch.cat([encoder_value, value], dim=1)
|
||||
|
||||
if image_rotary_emb is not None:
|
||||
cos, sin = image_rotary_emb
|
||||
cos = cos.to(query.dtype)
|
||||
sin = sin.to(query.dtype)
|
||||
query = self.rope(query, cos, sin)
|
||||
key = self.rope(key, cos, sin)
|
||||
|
||||
attn_metadata = None
|
||||
if attention_mask is not None:
|
||||
if attention_mask.dim() == 3:
|
||||
attention_mask = attention_mask.unsqueeze(1)
|
||||
attn_metadata = AttentionMetadata(attn_mask=attention_mask)
|
||||
|
||||
hidden_states = self.attn(query, key, value, attn_metadata)
|
||||
hidden_states = hidden_states.flatten(2, 3).to(query.dtype)
|
||||
|
||||
if encoder_hidden_states is not None:
|
||||
context_len = encoder_hidden_states.shape[1]
|
||||
encoder_hidden_states, hidden_states = hidden_states.split_with_sizes(
|
||||
[context_len, hidden_states.shape[1] - context_len],
|
||||
dim=1,
|
||||
)
|
||||
encoder_hidden_states, _ = self.to_add_out(encoder_hidden_states)
|
||||
|
||||
hidden_states, _ = self.to_out[0](hidden_states)
|
||||
hidden_states = self.to_out[1](hidden_states)
|
||||
|
||||
if encoder_hidden_states is not None:
|
||||
return hidden_states, encoder_hidden_states
|
||||
return hidden_states
|
||||
|
||||
|
||||
class Flux2ParallelSelfAttention(nn.Module):
|
||||
"""
|
||||
Parallel attention block that fuses QKV projections with MLP input projections.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
query_dim: int,
|
||||
heads: int = 8,
|
||||
dim_head: int = 64,
|
||||
dropout: float = 0.0,
|
||||
bias: bool = False,
|
||||
out_bias: bool = True,
|
||||
eps: float = 1e-5,
|
||||
out_dim: int = None,
|
||||
elementwise_affine: bool = True,
|
||||
mlp_ratio: float = 4.0,
|
||||
mlp_mult_factor: int = 2,
|
||||
):
|
||||
super().__init__()
|
||||
self.head_dim = dim_head
|
||||
self.inner_dim = out_dim if out_dim is not None else dim_head * heads
|
||||
self.query_dim = query_dim
|
||||
self.out_dim = out_dim if out_dim is not None else query_dim
|
||||
self.heads = out_dim // dim_head if out_dim is not None else heads
|
||||
self.dropout = dropout
|
||||
|
||||
self.mlp_ratio = mlp_ratio
|
||||
self.mlp_hidden_dim = int(query_dim * self.mlp_ratio)
|
||||
self.mlp_mult_factor = mlp_mult_factor
|
||||
|
||||
self.to_qkv_mlp_proj = nn.Linear(
|
||||
self.query_dim,
|
||||
self.inner_dim * 3 + self.mlp_hidden_dim * self.mlp_mult_factor,
|
||||
bias=bias,
|
||||
)
|
||||
self.mlp_act_fn = Flux2SwiGLU()
|
||||
|
||||
self.norm_q = RMSNorm(dim_head, eps=eps)
|
||||
self.norm_k = RMSNorm(dim_head, eps=eps)
|
||||
|
||||
self.to_out = nn.Linear(self.inner_dim + self.mlp_hidden_dim, self.out_dim, bias=out_bias)
|
||||
self.rope = RotaryEmbedding(is_neox_style=False)
|
||||
self.attn = Attention(
|
||||
num_heads=self.heads,
|
||||
head_size=self.head_dim,
|
||||
softmax_scale=1.0 / (self.head_dim**0.5),
|
||||
causal=False,
|
||||
)
|
||||
|
||||
def forward(
|
||||
self,
|
||||
hidden_states: torch.Tensor,
|
||||
attention_mask: torch.Tensor | None = None,
|
||||
image_rotary_emb: tuple[torch.Tensor, torch.Tensor] | None = None,
|
||||
**kwargs,
|
||||
) -> torch.Tensor:
|
||||
hidden_states = self.to_qkv_mlp_proj(hidden_states)
|
||||
qkv, mlp_hidden_states = torch.split(
|
||||
hidden_states,
|
||||
[3 * self.inner_dim, self.mlp_hidden_dim * self.mlp_mult_factor],
|
||||
dim=-1,
|
||||
)
|
||||
|
||||
query, key, value = qkv.chunk(3, dim=-1)
|
||||
query = query.unflatten(-1, (self.heads, -1))
|
||||
key = key.unflatten(-1, (self.heads, -1))
|
||||
value = value.unflatten(-1, (self.heads, -1))
|
||||
|
||||
query = self.norm_q(query)
|
||||
key = self.norm_k(key)
|
||||
|
||||
if image_rotary_emb is not None:
|
||||
cos, sin = image_rotary_emb
|
||||
cos = cos.to(query.dtype)
|
||||
sin = sin.to(query.dtype)
|
||||
query = self.rope(query, cos, sin)
|
||||
key = self.rope(key, cos, sin)
|
||||
|
||||
attn_metadata = None
|
||||
if attention_mask is not None:
|
||||
if attention_mask.dim() == 3:
|
||||
attention_mask = attention_mask.unsqueeze(1)
|
||||
attn_metadata = AttentionMetadata(attn_mask=attention_mask)
|
||||
|
||||
attn_output = self.attn(query, key, value, attn_metadata)
|
||||
attn_output = attn_output.flatten(2, 3).to(query.dtype)
|
||||
|
||||
mlp_hidden_states = self.mlp_act_fn(mlp_hidden_states)
|
||||
hidden_states = torch.cat([attn_output, mlp_hidden_states], dim=-1)
|
||||
return self.to_out(hidden_states)
|
||||
|
||||
|
||||
class Flux2SingleTransformerBlock(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
dim: int,
|
||||
num_attention_heads: int,
|
||||
attention_head_dim: int,
|
||||
mlp_ratio: float = 3.0,
|
||||
eps: float = 1e-6,
|
||||
bias: bool = False,
|
||||
):
|
||||
super().__init__()
|
||||
self.norm = nn.LayerNorm(dim, elementwise_affine=False, eps=eps)
|
||||
self.attn = Flux2ParallelSelfAttention(
|
||||
query_dim=dim,
|
||||
dim_head=attention_head_dim,
|
||||
heads=num_attention_heads,
|
||||
out_dim=dim,
|
||||
bias=bias,
|
||||
out_bias=bias,
|
||||
eps=eps,
|
||||
mlp_ratio=mlp_ratio,
|
||||
mlp_mult_factor=2,
|
||||
)
|
||||
|
||||
def forward(
|
||||
self,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor | None,
|
||||
temb_mod_params: tuple[torch.Tensor, torch.Tensor, torch.Tensor],
|
||||
image_rotary_emb: tuple[torch.Tensor, torch.Tensor] | None = None,
|
||||
joint_attention_kwargs: dict[str, Any] | None = None,
|
||||
split_hidden_states: bool = False,
|
||||
text_seq_len: int | None = None,
|
||||
) -> torch.Tensor | tuple[torch.Tensor, torch.Tensor]:
|
||||
if encoder_hidden_states is not None:
|
||||
text_seq_len = encoder_hidden_states.shape[1]
|
||||
hidden_states = torch.cat([encoder_hidden_states, hidden_states], dim=1)
|
||||
|
||||
mod_shift, mod_scale, mod_gate = temb_mod_params
|
||||
|
||||
norm_hidden_states = self.norm(hidden_states)
|
||||
norm_hidden_states = (1 + mod_scale) * norm_hidden_states + mod_shift
|
||||
|
||||
joint_attention_kwargs = joint_attention_kwargs or {}
|
||||
attn_output = self.attn(
|
||||
hidden_states=norm_hidden_states,
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
**joint_attention_kwargs,
|
||||
)
|
||||
|
||||
hidden_states = hidden_states + mod_gate * attn_output
|
||||
if hidden_states.dtype == torch.float16:
|
||||
hidden_states = hidden_states.clip(-65504, 65504)
|
||||
|
||||
if split_hidden_states:
|
||||
encoder_hidden_states, hidden_states = hidden_states[:, :text_seq_len], hidden_states[:, text_seq_len:]
|
||||
return encoder_hidden_states, hidden_states
|
||||
return hidden_states
|
||||
|
||||
|
||||
class Flux2TransformerBlock(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
dim: int,
|
||||
num_attention_heads: int,
|
||||
attention_head_dim: int,
|
||||
mlp_ratio: float = 3.0,
|
||||
eps: float = 1e-6,
|
||||
bias: bool = False,
|
||||
):
|
||||
super().__init__()
|
||||
self.norm1 = nn.LayerNorm(dim, elementwise_affine=False, eps=eps)
|
||||
self.norm1_context = nn.LayerNorm(dim, elementwise_affine=False, eps=eps)
|
||||
|
||||
self.attn = Flux2Attention(
|
||||
query_dim=dim,
|
||||
added_kv_proj_dim=dim,
|
||||
dim_head=attention_head_dim,
|
||||
heads=num_attention_heads,
|
||||
out_dim=dim,
|
||||
bias=bias,
|
||||
added_proj_bias=bias,
|
||||
out_bias=bias,
|
||||
eps=eps,
|
||||
)
|
||||
|
||||
self.norm2 = nn.LayerNorm(dim, elementwise_affine=False, eps=eps)
|
||||
self.ff = Flux2FeedForward(dim=dim, dim_out=dim, mult=mlp_ratio, bias=bias)
|
||||
|
||||
self.norm2_context = nn.LayerNorm(dim, elementwise_affine=False, eps=eps)
|
||||
self.ff_context = Flux2FeedForward(dim=dim, dim_out=dim, mult=mlp_ratio, bias=bias)
|
||||
|
||||
def forward(
|
||||
self,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor,
|
||||
temb_mod_params_img: tuple[tuple[torch.Tensor, torch.Tensor, torch.Tensor], ...],
|
||||
temb_mod_params_txt: tuple[tuple[torch.Tensor, torch.Tensor, torch.Tensor], ...],
|
||||
image_rotary_emb: tuple[torch.Tensor, torch.Tensor] | None = None,
|
||||
joint_attention_kwargs: dict[str, Any] | None = None,
|
||||
) -> tuple[torch.Tensor, torch.Tensor]:
|
||||
joint_attention_kwargs = joint_attention_kwargs or {}
|
||||
|
||||
(shift_msa, scale_msa, gate_msa), (shift_mlp, scale_mlp, gate_mlp) = temb_mod_params_img
|
||||
(c_shift_msa, c_scale_msa, c_gate_msa), (c_shift_mlp, c_scale_mlp, c_gate_mlp) = temb_mod_params_txt
|
||||
|
||||
norm_hidden_states = self.norm1(hidden_states)
|
||||
norm_hidden_states = (1 + scale_msa) * norm_hidden_states + shift_msa
|
||||
|
||||
norm_encoder_hidden_states = self.norm1_context(encoder_hidden_states)
|
||||
norm_encoder_hidden_states = (1 + c_scale_msa) * norm_encoder_hidden_states + c_shift_msa
|
||||
|
||||
attn_output, context_attn_output = self.attn(
|
||||
hidden_states=norm_hidden_states,
|
||||
encoder_hidden_states=norm_encoder_hidden_states,
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
**joint_attention_kwargs,
|
||||
)
|
||||
|
||||
attn_output = gate_msa * attn_output
|
||||
hidden_states = hidden_states + attn_output
|
||||
|
||||
norm_hidden_states = self.norm2(hidden_states)
|
||||
norm_hidden_states = norm_hidden_states * (1 + scale_mlp) + shift_mlp
|
||||
ff_output = self.ff(norm_hidden_states)
|
||||
hidden_states = hidden_states + gate_mlp * ff_output
|
||||
|
||||
context_attn_output = c_gate_msa * context_attn_output
|
||||
encoder_hidden_states = encoder_hidden_states + context_attn_output
|
||||
|
||||
norm_encoder_hidden_states = self.norm2_context(encoder_hidden_states)
|
||||
norm_encoder_hidden_states = norm_encoder_hidden_states * (1 + c_scale_mlp) + c_shift_mlp
|
||||
context_ff_output = self.ff_context(norm_encoder_hidden_states)
|
||||
encoder_hidden_states = encoder_hidden_states + c_gate_mlp * context_ff_output
|
||||
if encoder_hidden_states.dtype == torch.float16:
|
||||
encoder_hidden_states = encoder_hidden_states.clip(-65504, 65504)
|
||||
|
||||
return encoder_hidden_states, hidden_states
|
||||
|
||||
|
||||
class Flux2PosEmbed(nn.Module):
|
||||
def __init__(self, theta: int, axes_dim: list[int]):
|
||||
super().__init__()
|
||||
self.theta = theta
|
||||
self.axes_dim = axes_dim
|
||||
|
||||
def forward(self, ids: torch.Tensor) -> tuple[torch.Tensor, torch.Tensor]:
|
||||
cos_out = []
|
||||
sin_out = []
|
||||
pos = ids.float()
|
||||
is_mps = ids.device.type == "mps"
|
||||
is_npu = ids.device.type == "npu"
|
||||
freqs_dtype = torch.float32 if (is_mps or is_npu) else torch.float64
|
||||
for i in range(len(self.axes_dim)):
|
||||
freqs_cis = get_1d_rotary_pos_embed(
|
||||
self.axes_dim[i],
|
||||
pos[..., i],
|
||||
theta=self.theta,
|
||||
use_real=False,
|
||||
freqs_dtype=freqs_dtype,
|
||||
)
|
||||
cos_out.append(freqs_cis.real)
|
||||
sin_out.append(freqs_cis.imag)
|
||||
freqs_cos = torch.cat(cos_out, dim=-1).to(ids.device)
|
||||
freqs_sin = torch.cat(sin_out, dim=-1).to(ids.device)
|
||||
return freqs_cos, freqs_sin
|
||||
|
||||
|
||||
class Flux2TimestepGuidanceEmbeddings(nn.Module):
|
||||
def __init__(
|
||||
self,
|
||||
in_channels: int = 256,
|
||||
embedding_dim: int = 6144,
|
||||
bias: bool = False,
|
||||
guidance_embeds: bool = True,
|
||||
):
|
||||
super().__init__()
|
||||
self.time_proj = Timesteps(num_channels=in_channels, flip_sin_to_cos=True, downscale_freq_shift=0)
|
||||
self.timestep_embedder = TimestepEmbedding(
|
||||
in_channels=in_channels,
|
||||
time_embed_dim=embedding_dim,
|
||||
sample_proj_bias=bias,
|
||||
)
|
||||
|
||||
if guidance_embeds:
|
||||
self.guidance_embedder = TimestepEmbedding(
|
||||
in_channels=in_channels,
|
||||
time_embed_dim=embedding_dim,
|
||||
sample_proj_bias=bias,
|
||||
)
|
||||
else:
|
||||
self.guidance_embedder = None
|
||||
|
||||
def forward(self, timestep: torch.Tensor, guidance: torch.Tensor | None) -> torch.Tensor:
|
||||
timesteps_proj = self.time_proj(timestep)
|
||||
timesteps_emb = self.timestep_embedder(timesteps_proj.to(timestep.dtype))
|
||||
|
||||
if guidance is not None and self.guidance_embedder is not None:
|
||||
guidance_proj = self.time_proj(guidance)
|
||||
guidance_emb = self.guidance_embedder(guidance_proj.to(guidance.dtype))
|
||||
return timesteps_emb + guidance_emb
|
||||
return timesteps_emb
|
||||
|
||||
|
||||
class Flux2Modulation(nn.Module):
|
||||
def __init__(self, dim: int, mod_param_sets: int = 2, bias: bool = False):
|
||||
super().__init__()
|
||||
self.mod_param_sets = mod_param_sets
|
||||
self.linear = nn.Linear(dim, dim * 3 * self.mod_param_sets, bias=bias)
|
||||
self.act_fn = nn.SiLU()
|
||||
|
||||
def forward(self, temb: torch.Tensor) -> tuple[tuple[torch.Tensor, torch.Tensor, torch.Tensor], ...]:
|
||||
mod = self.act_fn(temb)
|
||||
mod = self.linear(mod)
|
||||
if mod.ndim == 2:
|
||||
mod = mod.unsqueeze(1)
|
||||
mod_params = torch.chunk(mod, 3 * self.mod_param_sets, dim=-1)
|
||||
return tuple(mod_params[3 * i : 3 * (i + 1)] for i in range(self.mod_param_sets))
|
||||
|
||||
|
||||
class Flux2Transformer2DModel(nn.Module):
|
||||
"""
|
||||
The Transformer model introduced in Flux 2.
|
||||
"""
|
||||
|
||||
_repeated_blocks = ["Flux2TransformerBlock", "Flux2SingleTransformerBlock"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
patch_size: int = 1,
|
||||
in_channels: int = 128,
|
||||
out_channels: int | None = None,
|
||||
num_layers: int = 8,
|
||||
num_single_layers: int = 48,
|
||||
attention_head_dim: int = 128,
|
||||
num_attention_heads: int = 48,
|
||||
joint_attention_dim: int = 15360,
|
||||
timestep_guidance_channels: int = 256,
|
||||
mlp_ratio: float = 3.0,
|
||||
axes_dims_rope: tuple[int, ...] = (32, 32, 32, 32),
|
||||
rope_theta: int = 2000,
|
||||
eps: float = 1e-6,
|
||||
guidance_embeds: bool = True,
|
||||
):
|
||||
super().__init__()
|
||||
self.out_channels = out_channels or in_channels
|
||||
self.inner_dim = num_attention_heads * attention_head_dim
|
||||
self.config = SimpleNamespace(
|
||||
patch_size=patch_size,
|
||||
in_channels=in_channels,
|
||||
out_channels=self.out_channels,
|
||||
num_layers=num_layers,
|
||||
num_single_layers=num_single_layers,
|
||||
attention_head_dim=attention_head_dim,
|
||||
num_attention_heads=num_attention_heads,
|
||||
joint_attention_dim=joint_attention_dim,
|
||||
timestep_guidance_channels=timestep_guidance_channels,
|
||||
mlp_ratio=mlp_ratio,
|
||||
axes_dims_rope=axes_dims_rope,
|
||||
rope_theta=rope_theta,
|
||||
eps=eps,
|
||||
guidance_embeds=guidance_embeds,
|
||||
)
|
||||
|
||||
self.pos_embed = Flux2PosEmbed(theta=rope_theta, axes_dim=list(axes_dims_rope))
|
||||
self.time_guidance_embed = Flux2TimestepGuidanceEmbeddings(
|
||||
in_channels=timestep_guidance_channels,
|
||||
embedding_dim=self.inner_dim,
|
||||
bias=False,
|
||||
guidance_embeds=guidance_embeds,
|
||||
)
|
||||
|
||||
self.double_stream_modulation_img = Flux2Modulation(self.inner_dim, mod_param_sets=2, bias=False)
|
||||
self.double_stream_modulation_txt = Flux2Modulation(self.inner_dim, mod_param_sets=2, bias=False)
|
||||
self.single_stream_modulation = Flux2Modulation(self.inner_dim, mod_param_sets=1, bias=False)
|
||||
|
||||
self.x_embedder = nn.Linear(in_channels, self.inner_dim, bias=False)
|
||||
self.context_embedder = nn.Linear(joint_attention_dim, self.inner_dim, bias=False)
|
||||
|
||||
self.transformer_blocks = nn.ModuleList(
|
||||
[
|
||||
Flux2TransformerBlock(
|
||||
dim=self.inner_dim,
|
||||
num_attention_heads=num_attention_heads,
|
||||
attention_head_dim=attention_head_dim,
|
||||
mlp_ratio=mlp_ratio,
|
||||
eps=eps,
|
||||
bias=False,
|
||||
)
|
||||
for _ in range(num_layers)
|
||||
]
|
||||
)
|
||||
|
||||
self.single_transformer_blocks = nn.ModuleList(
|
||||
[
|
||||
Flux2SingleTransformerBlock(
|
||||
dim=self.inner_dim,
|
||||
num_attention_heads=num_attention_heads,
|
||||
attention_head_dim=attention_head_dim,
|
||||
mlp_ratio=mlp_ratio,
|
||||
eps=eps,
|
||||
bias=False,
|
||||
)
|
||||
for _ in range(num_single_layers)
|
||||
]
|
||||
)
|
||||
|
||||
self.norm_out = AdaLayerNormContinuous(
|
||||
self.inner_dim,
|
||||
self.inner_dim,
|
||||
elementwise_affine=False,
|
||||
eps=eps,
|
||||
bias=False,
|
||||
)
|
||||
self.proj_out = nn.Linear(self.inner_dim, patch_size * patch_size * self.out_channels, bias=False)
|
||||
|
||||
@property
|
||||
def dtype(self) -> torch.dtype:
|
||||
return next(self.parameters()).dtype
|
||||
|
||||
def forward(
|
||||
self,
|
||||
hidden_states: torch.Tensor,
|
||||
encoder_hidden_states: torch.Tensor,
|
||||
timestep: torch.LongTensor,
|
||||
img_ids: torch.Tensor,
|
||||
txt_ids: torch.Tensor,
|
||||
guidance: torch.Tensor | None = None,
|
||||
joint_attention_kwargs: dict[str, Any] | None = None,
|
||||
return_dict: bool = True,
|
||||
) -> torch.Tensor | Transformer2DModelOutput:
|
||||
joint_attention_kwargs = joint_attention_kwargs or {}
|
||||
|
||||
num_txt_tokens = encoder_hidden_states.shape[1]
|
||||
|
||||
timestep = timestep.to(hidden_states.dtype) * 1000
|
||||
if guidance is not None:
|
||||
guidance = guidance.to(hidden_states.dtype) * 1000
|
||||
|
||||
temb = self.time_guidance_embed(timestep, guidance)
|
||||
|
||||
double_stream_mod_img = self.double_stream_modulation_img(temb)
|
||||
double_stream_mod_txt = self.double_stream_modulation_txt(temb)
|
||||
single_stream_mod = self.single_stream_modulation(temb)[0]
|
||||
|
||||
hidden_states = self.x_embedder(hidden_states)
|
||||
encoder_hidden_states = self.context_embedder(encoder_hidden_states)
|
||||
|
||||
if img_ids.ndim == 3:
|
||||
img_ids = img_ids[0]
|
||||
if txt_ids.ndim == 3:
|
||||
txt_ids = txt_ids[0]
|
||||
|
||||
image_rotary_emb = self.pos_embed(img_ids)
|
||||
text_rotary_emb = self.pos_embed(txt_ids)
|
||||
concat_rotary_emb = (
|
||||
torch.cat([text_rotary_emb[0], image_rotary_emb[0]], dim=0),
|
||||
torch.cat([text_rotary_emb[1], image_rotary_emb[1]], dim=0),
|
||||
)
|
||||
|
||||
for block in self.transformer_blocks:
|
||||
encoder_hidden_states, hidden_states = block(
|
||||
hidden_states=hidden_states,
|
||||
encoder_hidden_states=encoder_hidden_states,
|
||||
temb_mod_params_img=double_stream_mod_img,
|
||||
temb_mod_params_txt=double_stream_mod_txt,
|
||||
image_rotary_emb=concat_rotary_emb,
|
||||
joint_attention_kwargs=joint_attention_kwargs,
|
||||
)
|
||||
|
||||
hidden_states = torch.cat([encoder_hidden_states, hidden_states], dim=1)
|
||||
|
||||
for block in self.single_transformer_blocks:
|
||||
hidden_states = block(
|
||||
hidden_states=hidden_states,
|
||||
encoder_hidden_states=None,
|
||||
temb_mod_params=single_stream_mod,
|
||||
image_rotary_emb=concat_rotary_emb,
|
||||
joint_attention_kwargs=joint_attention_kwargs,
|
||||
)
|
||||
|
||||
hidden_states = hidden_states[:, num_txt_tokens:, ...]
|
||||
hidden_states = self.norm_out(hidden_states, temb)
|
||||
output = self.proj_out(hidden_states)
|
||||
|
||||
if not return_dict:
|
||||
return (output,)
|
||||
return Transformer2DModelOutput(sample=output)
|
||||
|
||||
def load_weights(self, weights: Iterable[tuple[str, torch.Tensor]]) -> set[str]:
|
||||
stacked_params_mapping = [
|
||||
(".to_qkv", ".to_q", "q"),
|
||||
(".to_qkv", ".to_k", "k"),
|
||||
(".to_qkv", ".to_v", "v"),
|
||||
(".add_kv_proj", ".add_q_proj", "q"),
|
||||
(".add_kv_proj", ".add_k_proj", "k"),
|
||||
(".add_kv_proj", ".add_v_proj", "v"),
|
||||
]
|
||||
|
||||
params_dict = dict(self.named_parameters())
|
||||
|
||||
for name, buffer in self.named_buffers():
|
||||
if name.endswith(".beta") or name.endswith(".eps"):
|
||||
params_dict[name] = buffer
|
||||
|
||||
loaded_params: set[str] = set()
|
||||
for name, loaded_weight in weights:
|
||||
if "to_qkvkv_mlp_proj" in name:
|
||||
name = name.replace("to_qkvkv_mlp_proj", "to_qkv_mlp_proj")
|
||||
if "to_qkv_mlp_proj" in name:
|
||||
param = params_dict[name]
|
||||
weight_loader = getattr(param, "weight_loader", default_weight_loader)
|
||||
weight_loader(param, loaded_weight)
|
||||
loaded_params.add(name)
|
||||
continue
|
||||
for param_name, weight_name, shard_id in stacked_params_mapping:
|
||||
if weight_name not in name:
|
||||
continue
|
||||
name = name.replace(weight_name, param_name)
|
||||
param = params_dict[name]
|
||||
weight_loader = param.weight_loader
|
||||
weight_loader(param, loaded_weight, shard_id)
|
||||
break
|
||||
else:
|
||||
param = params_dict[name]
|
||||
weight_loader = getattr(param, "weight_loader", default_weight_loader)
|
||||
weight_loader(param, loaded_weight)
|
||||
loaded_params.add(name)
|
||||
return loaded_params
|
||||
@@ -0,0 +1,963 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
#
|
||||
# Copyright 2025 Black Forest Labs and The HuggingFace Team. All rights reserved.
|
||||
#
|
||||
# Licensed under the Apache License, Version 2.0 (the "License");
|
||||
# you may not use this file except in compliance with the License.
|
||||
# You may obtain a copy of the License at
|
||||
#
|
||||
# http://www.apache.org/licenses/LICENSE-2.0
|
||||
#
|
||||
# Unless required by applicable law or agreed to in writing, software
|
||||
# distributed under the License is distributed on an "AS IS" BASIS,
|
||||
# WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
|
||||
# See the License for the specific language governing permissions and
|
||||
# limitations under the License.
|
||||
|
||||
import json
|
||||
import math
|
||||
import os
|
||||
from collections.abc import Callable, Iterable
|
||||
from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import PIL.Image
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from diffusers.image_processor import VaeImageProcessor
|
||||
from diffusers.models.autoencoders.autoencoder_kl_flux2 import AutoencoderKLFlux2
|
||||
from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion import retrieve_timesteps
|
||||
from diffusers.pipelines.stable_diffusion.pipeline_stable_diffusion_img2img import retrieve_latents
|
||||
from diffusers.schedulers import FlowMatchEulerDiscreteScheduler
|
||||
from diffusers.utils.torch_utils import randn_tensor
|
||||
from transformers import Qwen2TokenizerFast, Qwen3ForCausalLM
|
||||
from vllm.logger import init_logger
|
||||
from vllm.model_executor.models.utils import AutoWeightsLoader
|
||||
|
||||
from vllm_omni.diffusion.data import DiffusionOutput, OmniDiffusionConfig
|
||||
from vllm_omni.diffusion.distributed.utils import get_local_device
|
||||
from vllm_omni.diffusion.model_loader.diffusers_loader import DiffusersPipelineLoader
|
||||
from vllm_omni.diffusion.models.flux2_klein.flux2_klein_transformer import (
|
||||
Flux2Transformer2DModel,
|
||||
)
|
||||
from vllm_omni.diffusion.models.interface import SupportImageInput
|
||||
from vllm_omni.diffusion.request import OmniDiffusionRequest
|
||||
from vllm_omni.diffusion.utils.tf_utils import get_transformer_config_kwargs
|
||||
from vllm_omni.model_executor.model_loader.weight_utils import download_weights_from_hf_specific
|
||||
|
||||
logger = init_logger(__name__)
|
||||
|
||||
|
||||
class Flux2ImageProcessor(VaeImageProcessor):
|
||||
"""Image processor to preprocess the reference image for Flux2 klein."""
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
do_resize: bool = True,
|
||||
vae_scale_factor: int = 16,
|
||||
vae_latent_channels: int = 32,
|
||||
do_normalize: bool = True,
|
||||
do_convert_rgb: bool = True,
|
||||
):
|
||||
super().__init__(
|
||||
do_resize=do_resize,
|
||||
vae_scale_factor=vae_scale_factor,
|
||||
vae_latent_channels=vae_latent_channels,
|
||||
do_normalize=do_normalize,
|
||||
do_convert_rgb=do_convert_rgb,
|
||||
)
|
||||
|
||||
@staticmethod
|
||||
def check_image_input(
|
||||
image: PIL.Image.Image,
|
||||
max_aspect_ratio: int = 8,
|
||||
min_side_length: int = 64,
|
||||
max_area: int = 1024 * 1024,
|
||||
) -> PIL.Image.Image:
|
||||
if not isinstance(image, PIL.Image.Image):
|
||||
raise ValueError(f"Image must be a PIL.Image.Image, got {type(image)}")
|
||||
|
||||
width, height = image.size
|
||||
if width < min_side_length or height < min_side_length:
|
||||
raise ValueError(f"Image too small: {width}x{height}. Both dimensions must be at least {min_side_length}px")
|
||||
|
||||
aspect_ratio = max(width / height, height / width)
|
||||
if aspect_ratio > max_aspect_ratio:
|
||||
raise ValueError(
|
||||
f"Aspect ratio too extreme: {width}x{height} (ratio: {aspect_ratio:.1f}:1). "
|
||||
f"Maximum allowed ratio is {max_aspect_ratio}:1"
|
||||
)
|
||||
|
||||
if width * height > max_area:
|
||||
logger.warning("Image area exceeds recommended maximum; resizing will be applied.")
|
||||
|
||||
return image
|
||||
|
||||
@staticmethod
|
||||
def _resize_to_target_area(image: PIL.Image.Image, target_area: int = 1024 * 1024) -> PIL.Image.Image:
|
||||
image_width, image_height = image.size
|
||||
scale = math.sqrt(target_area / (image_width * image_height))
|
||||
width = int(image_width * scale)
|
||||
height = int(image_height * scale)
|
||||
return image.resize((width, height), PIL.Image.Resampling.LANCZOS)
|
||||
|
||||
@staticmethod
|
||||
def _resize_if_exceeds_area(image: PIL.Image.Image, target_area: int = 1024 * 1024) -> PIL.Image.Image:
|
||||
image_width, image_height = image.size
|
||||
if image_width * image_height <= target_area:
|
||||
return image
|
||||
return Flux2ImageProcessor._resize_to_target_area(image, target_area)
|
||||
|
||||
def _resize_and_crop(self, image: PIL.Image.Image, width: int, height: int) -> PIL.Image.Image:
|
||||
image_width, image_height = image.size
|
||||
left = (image_width - width) // 2
|
||||
top = (image_height - height) // 2
|
||||
right = left + width
|
||||
bottom = top + height
|
||||
return image.crop((left, top, right, bottom))
|
||||
|
||||
@staticmethod
|
||||
def concatenate_images(images: list[PIL.Image.Image]) -> PIL.Image.Image:
|
||||
if len(images) == 1:
|
||||
return images[0].copy()
|
||||
|
||||
images = [img.convert("RGB") if img.mode != "RGB" else img for img in images]
|
||||
total_width = sum(img.width for img in images)
|
||||
max_height = max(img.height for img in images)
|
||||
background_color = (255, 255, 255)
|
||||
new_img = PIL.Image.new("RGB", (total_width, max_height), background_color)
|
||||
|
||||
x_offset = 0
|
||||
for img in images:
|
||||
y_offset = (max_height - img.height) // 2
|
||||
new_img.paste(img, (x_offset, y_offset))
|
||||
x_offset += img.width
|
||||
|
||||
return new_img
|
||||
|
||||
|
||||
def get_flux2_klein_post_process_func(
|
||||
od_config: OmniDiffusionConfig,
|
||||
):
|
||||
model_name = od_config.model
|
||||
if os.path.exists(model_name):
|
||||
model_path = model_name
|
||||
else:
|
||||
model_path = download_weights_from_hf_specific(model_name, None, ["*"])
|
||||
|
||||
vae_config_path = os.path.join(model_path, "vae/config.json")
|
||||
with open(vae_config_path) as f:
|
||||
vae_config = json.load(f)
|
||||
vae_scale_factor = 2 ** (len(vae_config["block_out_channels"]) - 1) if "block_out_channels" in vae_config else 8
|
||||
|
||||
image_processor = Flux2ImageProcessor(vae_scale_factor=vae_scale_factor * 2)
|
||||
|
||||
def post_process_func(images: torch.Tensor):
|
||||
return image_processor.postprocess(images)
|
||||
|
||||
return post_process_func
|
||||
|
||||
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.compute_empirical_mu
|
||||
def compute_empirical_mu(image_seq_len: int, num_steps: int) -> float:
|
||||
a1, b1 = 8.73809524e-05, 1.89833333
|
||||
a2, b2 = 0.00016927, 0.45666666
|
||||
|
||||
if image_seq_len > 4300:
|
||||
mu = a2 * image_seq_len + b2
|
||||
return float(mu)
|
||||
|
||||
m_200 = a2 * image_seq_len + b2
|
||||
m_10 = a1 * image_seq_len + b1
|
||||
|
||||
a = (m_200 - m_10) / 190.0
|
||||
b = m_200 - 200.0 * a
|
||||
mu = a * num_steps + b
|
||||
|
||||
return float(mu)
|
||||
|
||||
|
||||
class Flux2KleinPipeline(nn.Module, SupportImageInput):
|
||||
"""Flux2 klein pipeline for text-to-image generation."""
|
||||
|
||||
support_image_input = True
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
od_config: OmniDiffusionConfig,
|
||||
prefix: str = "",
|
||||
is_distilled: bool = False,
|
||||
):
|
||||
super().__init__()
|
||||
self.od_config = od_config
|
||||
self.is_distilled = is_distilled
|
||||
self.weights_sources = [
|
||||
DiffusersPipelineLoader.ComponentSource(
|
||||
model_or_path=od_config.model,
|
||||
subfolder="transformer",
|
||||
revision=None,
|
||||
prefix="transformer.",
|
||||
fall_back_to_pt=True,
|
||||
)
|
||||
]
|
||||
|
||||
self._execution_device = get_local_device()
|
||||
model = od_config.model
|
||||
local_files_only = os.path.exists(model)
|
||||
|
||||
self.scheduler = FlowMatchEulerDiscreteScheduler.from_pretrained(
|
||||
model,
|
||||
subfolder="scheduler",
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
self.text_encoder = Qwen3ForCausalLM.from_pretrained(
|
||||
model,
|
||||
subfolder="text_encoder",
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
self.tokenizer = Qwen2TokenizerFast.from_pretrained(
|
||||
model,
|
||||
subfolder="tokenizer",
|
||||
local_files_only=local_files_only,
|
||||
)
|
||||
self.vae = AutoencoderKLFlux2.from_pretrained(
|
||||
model,
|
||||
subfolder="vae",
|
||||
local_files_only=local_files_only,
|
||||
).to(self._execution_device)
|
||||
|
||||
transformer_kwargs = get_transformer_config_kwargs(od_config.tf_model_config, Flux2Transformer2DModel)
|
||||
self.transformer = Flux2Transformer2DModel(**transformer_kwargs)
|
||||
|
||||
self.vae_scale_factor = 2 ** (len(self.vae.config.block_out_channels) - 1) if getattr(self, "vae", None) else 8
|
||||
self.image_processor = Flux2ImageProcessor(vae_scale_factor=self.vae_scale_factor * 2)
|
||||
self.tokenizer_max_length = 512
|
||||
self.default_sample_size = 128
|
||||
|
||||
self._guidance_scale = None
|
||||
self._attention_kwargs = None
|
||||
self._num_timesteps = None
|
||||
self._current_timestep = None
|
||||
self._interrupt = False
|
||||
|
||||
@staticmethod
|
||||
def _get_qwen3_prompt_embeds(
|
||||
text_encoder: Qwen3ForCausalLM,
|
||||
tokenizer: Qwen2TokenizerFast,
|
||||
prompt: str | list[str],
|
||||
dtype: torch.dtype | None = None,
|
||||
device: torch.device | None = None,
|
||||
max_sequence_length: int = 512,
|
||||
hidden_states_layers: list[int] = (9, 18, 27),
|
||||
):
|
||||
dtype = text_encoder.dtype if dtype is None else dtype
|
||||
device = text_encoder.device if device is None else device
|
||||
|
||||
prompt = [prompt] if isinstance(prompt, str) else prompt
|
||||
|
||||
all_input_ids = []
|
||||
all_attention_masks = []
|
||||
|
||||
for single_prompt in prompt:
|
||||
messages = [{"role": "user", "content": single_prompt}]
|
||||
text = tokenizer.apply_chat_template(
|
||||
messages,
|
||||
tokenize=False,
|
||||
add_generation_prompt=True,
|
||||
enable_thinking=False,
|
||||
)
|
||||
inputs = tokenizer(
|
||||
text,
|
||||
return_tensors="pt",
|
||||
padding="max_length",
|
||||
truncation=True,
|
||||
max_length=max_sequence_length,
|
||||
)
|
||||
|
||||
all_input_ids.append(inputs["input_ids"])
|
||||
all_attention_masks.append(inputs["attention_mask"])
|
||||
|
||||
input_ids = torch.cat(all_input_ids, dim=0).to(device)
|
||||
attention_mask = torch.cat(all_attention_masks, dim=0).to(device)
|
||||
|
||||
# Forward pass through the model
|
||||
output = text_encoder(
|
||||
input_ids=input_ids,
|
||||
attention_mask=attention_mask,
|
||||
output_hidden_states=True,
|
||||
use_cache=False,
|
||||
)
|
||||
|
||||
# Only use outputs from intermediate layers and stack them
|
||||
out = torch.stack([output.hidden_states[k] for k in hidden_states_layers], dim=1)
|
||||
out = out.to(dtype=dtype, device=device)
|
||||
|
||||
batch_size, num_channels, seq_len, hidden_dim = out.shape
|
||||
prompt_embeds = out.permute(0, 2, 1, 3).reshape(batch_size, seq_len, num_channels * hidden_dim)
|
||||
|
||||
return prompt_embeds
|
||||
|
||||
@staticmethod
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline._prepare_text_ids
|
||||
def _prepare_text_ids(
|
||||
x: torch.Tensor, # (B, L, D) or (L, D)
|
||||
t_coord: torch.Tensor | None = None,
|
||||
):
|
||||
B, L, _ = x.shape
|
||||
out_ids = []
|
||||
|
||||
for i in range(B):
|
||||
t = torch.arange(1) if t_coord is None else t_coord[i]
|
||||
h = torch.arange(1)
|
||||
w = torch.arange(1)
|
||||
seq_positions = torch.arange(L)
|
||||
|
||||
coords = torch.cartesian_prod(t, h, w, seq_positions)
|
||||
out_ids.append(coords)
|
||||
|
||||
return torch.stack(out_ids)
|
||||
|
||||
@staticmethod
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline._prepare_latent_ids
|
||||
def _prepare_latent_ids(
|
||||
latents: torch.Tensor, # (B, C, H, W)
|
||||
):
|
||||
r"""
|
||||
Generates 4D position coordinates (T, H, W, L) for latent tensors.
|
||||
|
||||
Args:
|
||||
latents (torch.Tensor):
|
||||
Latent tensor of shape (B, C, H, W)
|
||||
|
||||
Returns:
|
||||
torch.Tensor:
|
||||
Position IDs tensor of shape (B, H*W, 4) All batches share the same coordinate structure: T=0,
|
||||
H=[0..H-1], W=[0..W-1], L=0
|
||||
"""
|
||||
|
||||
batch_size, _, height, width = latents.shape
|
||||
|
||||
t = torch.arange(1) # [0] - time dimension
|
||||
h = torch.arange(height)
|
||||
w = torch.arange(width)
|
||||
layer_ids = torch.arange(1) # [0] - layer dimension
|
||||
|
||||
# Create position IDs: (H*W, 4)
|
||||
latent_ids = torch.cartesian_prod(t, h, w, layer_ids)
|
||||
|
||||
# Expand to batch: (B, H*W, 4)
|
||||
latent_ids = latent_ids.unsqueeze(0).expand(batch_size, -1, -1)
|
||||
|
||||
return latent_ids
|
||||
|
||||
@staticmethod
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline._prepare_image_ids
|
||||
def _prepare_image_ids(
|
||||
image_latents: list[torch.Tensor], # [(1, C, H, W), (1, C, H, W), ...]
|
||||
scale: int = 10,
|
||||
):
|
||||
r"""
|
||||
Generates 4D time-space coordinates (T, H, W, L) for a sequence of image latents.
|
||||
|
||||
This function creates a unique coordinate for every pixel/patch across all input latent with different
|
||||
dimensions.
|
||||
|
||||
Args:
|
||||
image_latents (List[torch.Tensor]):
|
||||
A list of image latent feature tensors, typically of shape (C, H, W).
|
||||
scale (int, optional):
|
||||
A factor used to define the time separation (T-coordinate) between latents. T-coordinate for the i-th
|
||||
latent is: 'scale + scale * i'. Defaults to 10.
|
||||
|
||||
Returns:
|
||||
torch.Tensor:
|
||||
The combined coordinate tensor. Shape: (1, N_total, 4) Where N_total is the sum of (H * W) for all
|
||||
input latents.
|
||||
|
||||
Coordinate Components (Dimension 4):
|
||||
- T (Time): The unique index indicating which latent image the coordinate belongs to.
|
||||
- H (Height): The row index within that latent image.
|
||||
- W (Width): The column index within that latent image.
|
||||
- L (Seq. Length): A sequence length dimension, which is always fixed at 0 (size 1)
|
||||
"""
|
||||
|
||||
if not isinstance(image_latents, list):
|
||||
raise ValueError(f"Expected `image_latents` to be a list, got {type(image_latents)}.")
|
||||
|
||||
# create time offset for each reference image
|
||||
t_coords = [scale + scale * t for t in torch.arange(0, len(image_latents))]
|
||||
t_coords = [t.view(-1) for t in t_coords]
|
||||
|
||||
image_latent_ids = []
|
||||
for x, t in zip(image_latents, t_coords):
|
||||
x = x.squeeze(0)
|
||||
_, height, width = x.shape
|
||||
|
||||
x_ids = torch.cartesian_prod(t, torch.arange(height), torch.arange(width), torch.arange(1))
|
||||
image_latent_ids.append(x_ids)
|
||||
|
||||
image_latent_ids = torch.cat(image_latent_ids, dim=0)
|
||||
image_latent_ids = image_latent_ids.unsqueeze(0)
|
||||
|
||||
return image_latent_ids
|
||||
|
||||
@staticmethod
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline._patchify_latents
|
||||
def _patchify_latents(latents):
|
||||
batch_size, num_channels_latents, height, width = latents.shape
|
||||
latents = latents.view(batch_size, num_channels_latents, height // 2, 2, width // 2, 2)
|
||||
latents = latents.permute(0, 1, 3, 5, 2, 4)
|
||||
latents = latents.reshape(batch_size, num_channels_latents * 4, height // 2, width // 2)
|
||||
return latents
|
||||
|
||||
@staticmethod
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline._unpatchify_latents
|
||||
def _unpatchify_latents(latents):
|
||||
batch_size, num_channels_latents, height, width = latents.shape
|
||||
latents = latents.reshape(batch_size, num_channels_latents // (2 * 2), 2, 2, height, width)
|
||||
latents = latents.permute(0, 1, 4, 2, 5, 3)
|
||||
latents = latents.reshape(batch_size, num_channels_latents // (2 * 2), height * 2, width * 2)
|
||||
return latents
|
||||
|
||||
@staticmethod
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline._pack_latents
|
||||
def _pack_latents(latents):
|
||||
"""
|
||||
pack latents: (batch_size, num_channels, height, width) -> (batch_size, height * width, num_channels)
|
||||
"""
|
||||
|
||||
batch_size, num_channels, height, width = latents.shape
|
||||
latents = latents.reshape(batch_size, num_channels, height * width).permute(0, 2, 1)
|
||||
|
||||
return latents
|
||||
|
||||
@staticmethod
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline._unpack_latents_with_ids
|
||||
def _unpack_latents_with_ids(x: torch.Tensor, x_ids: torch.Tensor) -> list[torch.Tensor]:
|
||||
"""
|
||||
using position ids to scatter tokens into place
|
||||
"""
|
||||
x_list = []
|
||||
for data, pos in zip(x, x_ids):
|
||||
_, ch = data.shape # noqa: F841
|
||||
h_ids = pos[:, 1].to(torch.int64)
|
||||
w_ids = pos[:, 2].to(torch.int64)
|
||||
|
||||
h = torch.max(h_ids) + 1
|
||||
w = torch.max(w_ids) + 1
|
||||
|
||||
flat_ids = h_ids * w + w_ids
|
||||
|
||||
out = torch.zeros((h * w, ch), device=data.device, dtype=data.dtype)
|
||||
out.scatter_(0, flat_ids.unsqueeze(1).expand(-1, ch), data)
|
||||
|
||||
# reshape from (H * W, C) to (H, W, C) and permute to (C, H, W)
|
||||
|
||||
out = out.view(h, w, ch).permute(2, 0, 1)
|
||||
x_list.append(out)
|
||||
|
||||
return torch.stack(x_list, dim=0)
|
||||
|
||||
def encode_prompt(
|
||||
self,
|
||||
prompt: str | list[str],
|
||||
device: torch.device | None = None,
|
||||
num_images_per_prompt: int = 1,
|
||||
prompt_embeds: torch.Tensor | None = None,
|
||||
max_sequence_length: int = 512,
|
||||
text_encoder_out_layers: tuple[int, ...] = (9, 18, 27),
|
||||
):
|
||||
device = device or self._execution_device
|
||||
|
||||
if prompt is None:
|
||||
prompt = ""
|
||||
|
||||
prompt = [prompt] if isinstance(prompt, str) else prompt
|
||||
|
||||
if prompt_embeds is None:
|
||||
prompt_embeds = self._get_qwen3_prompt_embeds(
|
||||
text_encoder=self.text_encoder,
|
||||
tokenizer=self.tokenizer,
|
||||
prompt=prompt,
|
||||
device=device,
|
||||
max_sequence_length=max_sequence_length,
|
||||
hidden_states_layers=text_encoder_out_layers,
|
||||
)
|
||||
|
||||
batch_size, seq_len, _ = prompt_embeds.shape
|
||||
prompt_embeds = prompt_embeds.repeat(1, num_images_per_prompt, 1)
|
||||
prompt_embeds = prompt_embeds.view(batch_size * num_images_per_prompt, seq_len, -1)
|
||||
|
||||
text_ids = self._prepare_text_ids(prompt_embeds)
|
||||
text_ids = text_ids.to(device)
|
||||
return prompt_embeds, text_ids
|
||||
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline._encode_vae_image
|
||||
def _encode_vae_image(self, image: torch.Tensor, generator: torch.Generator):
|
||||
if image.ndim != 4:
|
||||
raise ValueError(f"Expected image dims 4, got {image.ndim}.")
|
||||
|
||||
image_latents = retrieve_latents(self.vae.encode(image), generator=generator, sample_mode="argmax")
|
||||
image_latents = self._patchify_latents(image_latents)
|
||||
|
||||
latents_bn_mean = self.vae.bn.running_mean.view(1, -1, 1, 1).to(image_latents.device, image_latents.dtype)
|
||||
latents_bn_std = torch.sqrt(self.vae.bn.running_var.view(1, -1, 1, 1) + self.vae.config.batch_norm_eps)
|
||||
image_latents = (image_latents - latents_bn_mean) / latents_bn_std
|
||||
|
||||
return image_latents
|
||||
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline.prepare_latents
|
||||
def prepare_latents(
|
||||
self,
|
||||
batch_size,
|
||||
num_latents_channels,
|
||||
height,
|
||||
width,
|
||||
dtype,
|
||||
device,
|
||||
generator: torch.Generator,
|
||||
latents: torch.Tensor | None = None,
|
||||
):
|
||||
# VAE applies 8x compression on images but we must also account for packing which requires
|
||||
# latent height and width to be divisible by 2.
|
||||
height = 2 * (int(height) // (self.vae_scale_factor * 2))
|
||||
width = 2 * (int(width) // (self.vae_scale_factor * 2))
|
||||
|
||||
shape = (batch_size, num_latents_channels * 4, height // 2, width // 2)
|
||||
if isinstance(generator, list) and len(generator) != batch_size:
|
||||
raise ValueError(
|
||||
f"You have passed a list of generators of length {len(generator)}, but requested an effective batch"
|
||||
f" size of {batch_size}. Make sure the batch size matches the length of the generators."
|
||||
)
|
||||
if latents is None:
|
||||
latents = randn_tensor(shape, generator=generator, device=device, dtype=dtype)
|
||||
else:
|
||||
latents = latents.to(device=device, dtype=dtype)
|
||||
|
||||
latent_ids = self._prepare_latent_ids(latents)
|
||||
latent_ids = latent_ids.to(device)
|
||||
|
||||
latents = self._pack_latents(latents) # [B, C, H, W] -> [B, H*W, C]
|
||||
return latents, latent_ids
|
||||
|
||||
# Copied from diffusers.pipelines.flux2.pipeline_flux2.Flux2Pipeline.prepare_image_latents
|
||||
def prepare_image_latents(
|
||||
self,
|
||||
images: list[torch.Tensor],
|
||||
batch_size,
|
||||
generator: torch.Generator,
|
||||
device,
|
||||
dtype,
|
||||
):
|
||||
image_latents = []
|
||||
for image in images:
|
||||
image = image.to(device=device, dtype=dtype)
|
||||
imagge_latent = self._encode_vae_image(image=image, generator=generator)
|
||||
image_latents.append(imagge_latent) # (1, 128, 32, 32)
|
||||
|
||||
image_latent_ids = self._prepare_image_ids(image_latents)
|
||||
|
||||
# Pack each latent and concatenate
|
||||
packed_latents = []
|
||||
for latent in image_latents:
|
||||
# latent: (1, 128, 32, 32)
|
||||
packed = self._pack_latents(latent) # (1, 1024, 128)
|
||||
packed = packed.squeeze(0) # (1024, 128) - remove batch dim
|
||||
packed_latents.append(packed)
|
||||
|
||||
# Concatenate all reference tokens along sequence dimension
|
||||
image_latents = torch.cat(packed_latents, dim=0) # (N*1024, 128)
|
||||
image_latents = image_latents.unsqueeze(0) # (1, N*1024, 128)
|
||||
|
||||
image_latents = image_latents.repeat(batch_size, 1, 1)
|
||||
image_latent_ids = image_latent_ids.repeat(batch_size, 1, 1)
|
||||
image_latent_ids = image_latent_ids.to(device)
|
||||
|
||||
return image_latents, image_latent_ids
|
||||
|
||||
def check_inputs(
|
||||
self,
|
||||
prompt,
|
||||
height,
|
||||
width,
|
||||
prompt_embeds=None,
|
||||
callback_on_step_end_tensor_inputs=None,
|
||||
guidance_scale=None,
|
||||
):
|
||||
if (
|
||||
height is not None
|
||||
and height % (self.vae_scale_factor * 2) != 0
|
||||
or width is not None
|
||||
and width % (self.vae_scale_factor * 2) != 0
|
||||
):
|
||||
logger.warning(
|
||||
"`height` and `width` have to be divisible by %s but are %s and %s. "
|
||||
"Dimensions will be resized accordingly",
|
||||
self.vae_scale_factor * 2,
|
||||
height,
|
||||
width,
|
||||
)
|
||||
|
||||
if callback_on_step_end_tensor_inputs is not None and not all(
|
||||
k in ["latents", "prompt_embeds"] for k in callback_on_step_end_tensor_inputs
|
||||
):
|
||||
raise ValueError("`callback_on_step_end_tensor_inputs` must be a subset of ['latents', 'prompt_embeds'].")
|
||||
|
||||
if prompt is not None and prompt_embeds is not None:
|
||||
raise ValueError(
|
||||
f"Cannot forward both `prompt`: {prompt} and `prompt_embeds`: {prompt_embeds}. Please make sure to"
|
||||
" only forward one of the two."
|
||||
)
|
||||
elif prompt is None and prompt_embeds is None:
|
||||
raise ValueError(
|
||||
"Provide either `prompt` or `prompt_embeds`. Cannot leave both `prompt` and `prompt_embeds` undefined."
|
||||
)
|
||||
elif prompt is not None and (not isinstance(prompt, str) and not isinstance(prompt, list)):
|
||||
raise ValueError(f"`prompt` has to be of type `str` or `list` but is {type(prompt)}")
|
||||
|
||||
if guidance_scale > 1.0 and self.is_distilled:
|
||||
logger.warning(f"Guidance scale {guidance_scale} is ignored for step-wise distilled models.")
|
||||
|
||||
@property
|
||||
def guidance_scale(self):
|
||||
return self._guidance_scale
|
||||
|
||||
@property
|
||||
def do_classifier_free_guidance(self):
|
||||
return self._guidance_scale is not None and self._guidance_scale > 1 and not self.is_distilled
|
||||
|
||||
@property
|
||||
def attention_kwargs(self):
|
||||
return self._attention_kwargs
|
||||
|
||||
@property
|
||||
def num_timesteps(self):
|
||||
return self._num_timesteps
|
||||
|
||||
@property
|
||||
def current_timestep(self):
|
||||
return self._current_timestep
|
||||
|
||||
@property
|
||||
def interrupt(self):
|
||||
return self._interrupt
|
||||
|
||||
@torch.no_grad()
|
||||
def forward(
|
||||
self,
|
||||
req: OmniDiffusionRequest,
|
||||
image: PIL.Image.Image | list[PIL.Image.Image] | None = None,
|
||||
prompt: str | list[str] | None = None,
|
||||
height: int | None = None,
|
||||
width: int | None = None,
|
||||
num_inference_steps: int = 50,
|
||||
sigmas: list[float] | None = None,
|
||||
guidance_scale: float | None = 4.0,
|
||||
num_images_per_prompt: int = 1,
|
||||
generator: torch.Generator | list[torch.Generator] | None = None,
|
||||
latents: torch.Tensor | None = None,
|
||||
prompt_embeds: torch.Tensor | None = None,
|
||||
negative_prompt_embeds: torch.Tensor | None = None,
|
||||
output_type: str | None = "pil",
|
||||
return_dict: bool = True,
|
||||
attention_kwargs: dict[str, Any] | None = None,
|
||||
callback_on_step_end: Callable[[int, int, dict], None] | None = None,
|
||||
callback_on_step_end_tensor_inputs: list[str] = ["latents"],
|
||||
max_sequence_length: int = 512,
|
||||
text_encoder_out_layers: tuple[int, ...] = (9, 18, 27),
|
||||
) -> DiffusionOutput:
|
||||
r"""
|
||||
Function invoked when calling the pipeline for generation.
|
||||
|
||||
Args:
|
||||
image (`torch.Tensor`, `PIL.Image.Image`, `np.ndarray`, or list of these):
|
||||
`Image`, numpy array or tensor representing an image batch to be used as the starting point. For both
|
||||
numpy array and pytorch tensor, the expected value range is between `[0, 1]` If it's a tensor or a list
|
||||
or tensors, the expected shape should be `(B, C, H, W)` or `(C, H, W)`. If it is a numpy array or a
|
||||
list of arrays, the expected shape should be `(B, H, W, C)` or `(H, W, C)` It can also accept image
|
||||
latents as `image`, but if passing latents directly it is not encoded again.
|
||||
prompt (`str` or `List[str]`, *optional*):
|
||||
The prompt or prompts to guide the image generation. If not defined, one has to pass `prompt_embeds`.
|
||||
instead.
|
||||
guidance_scale (`float`, *optional*, defaults to 4.0):
|
||||
Guidance scale as defined in [Classifier-Free Diffusion
|
||||
Guidance](https://huggingface.co/papers/2207.12598). `guidance_scale` is defined as `w` of equation 2.
|
||||
of [Imagen Paper](https://huggingface.co/papers/2205.11487). Guidance scale is enabled by setting
|
||||
`guidance_scale > 1`. Higher guidance scale encourages to generate images that are closely linked to
|
||||
the text `prompt`, usually at the expense of lower image quality. For step-wise distilled models,
|
||||
`guidance_scale` is ignored.
|
||||
height (`int`, *optional*, defaults to self.unet.config.sample_size * self.vae_scale_factor):
|
||||
The height in pixels of the generated image. This is set to 1024 by default for the best results.
|
||||
width (`int`, *optional*, defaults to self.unet.config.sample_size * self.vae_scale_factor):
|
||||
The width in pixels of the generated image. This is set to 1024 by default for the best results.
|
||||
num_inference_steps (`int`, *optional*, defaults to 50):
|
||||
The number of denoising steps. More denoising steps usually lead to a higher quality image at the
|
||||
expense of slower inference.
|
||||
sigmas (`List[float]`, *optional*):
|
||||
Custom sigmas to use for the denoising process with schedulers which support a `sigmas` argument in
|
||||
their `set_timesteps` method. If not defined, the default behavior when `num_inference_steps` is passed
|
||||
will be used.
|
||||
num_images_per_prompt (`int`, *optional*, defaults to 1):
|
||||
The number of images to generate per prompt.
|
||||
generator (`torch.Generator` or `List[torch.Generator]`, *optional*):
|
||||
One or a list of [torch generator(s)](https://pytorch.org/docs/stable/generated/torch.Generator.html)
|
||||
to make generation deterministic.
|
||||
latents (`torch.Tensor`, *optional*):
|
||||
Pre-generated noisy latents, sampled from a Gaussian distribution, to be used as inputs for image
|
||||
generation. Can be used to tweak the same generation with different prompts. If not provided, a latents
|
||||
tensor will be generated by sampling using the supplied random `generator`.
|
||||
prompt_embeds (`torch.Tensor`, *optional*):
|
||||
Pre-generated text embeddings. Can be used to easily tweak text inputs, *e.g.* prompt weighting. If not
|
||||
provided, text embeddings will be generated from `prompt` input argument.
|
||||
negative_prompt_embeds (`torch.Tensor`, *optional*):
|
||||
Pre-generated negative text embeddings. Note that "" is used as the negative prompt in this pipeline.
|
||||
If not provided, will be generated from "".
|
||||
output_type (`str`, *optional*, defaults to `"pil"`):
|
||||
The output format of the generate image. Choose between
|
||||
[PIL](https://pillow.readthedocs.io/en/stable/): `PIL.Image.Image` or `np.array`.
|
||||
return_dict (`bool`, *optional*, defaults to `True`):
|
||||
Whether or not to return a [`~pipelines.qwenimage.QwenImagePipelineOutput`] instead of a plain tuple.
|
||||
attention_kwargs (`dict`, *optional*):
|
||||
A kwargs dictionary that if specified is passed along to the `AttentionProcessor` as defined under
|
||||
`self.processor` in
|
||||
[diffusers.models.attention_processor](https://github.com/huggingface/diffusers/blob/main/src/diffusers/models/attention_processor.py).
|
||||
callback_on_step_end (`Callable`, *optional*):
|
||||
A function that calls at the end of each denoising steps during the inference. The function is called
|
||||
with the following arguments: `callback_on_step_end(self: DiffusionPipeline, step: int, timestep: int,
|
||||
callback_kwargs: Dict)`. `callback_kwargs` will include a list of all tensors as specified by
|
||||
`callback_on_step_end_tensor_inputs`.
|
||||
callback_on_step_end_tensor_inputs (`List`, *optional*):
|
||||
The list of tensor inputs for the `callback_on_step_end` function. The tensors specified in the list
|
||||
will be passed as `callback_kwargs` argument. You will only be able to include variables listed in the
|
||||
`._callback_tensor_inputs` attribute of your pipeline class.
|
||||
max_sequence_length (`int` defaults to 512): Maximum sequence length to use with the `prompt`.
|
||||
text_encoder_out_layers (`Tuple[int]`):
|
||||
Layer indices to use in the `text_encoder` to derive the final prompt embeddings.
|
||||
|
||||
Examples:
|
||||
|
||||
Returns:
|
||||
[`~pipelines.flux2.Flux2PipelineOutput`] or `tuple`: [`~pipelines.flux2.Flux2PipelineOutput`] if
|
||||
`return_dict` is True, otherwise a `tuple`. When returning a tuple, the first element is a list with the
|
||||
generated images.
|
||||
"""
|
||||
|
||||
prompt = req.prompt if req.prompt is not None else prompt
|
||||
image = req.pil_image if req.pil_image is not None else image
|
||||
height = req.height or height
|
||||
width = req.width or width
|
||||
num_inference_steps = req.num_inference_steps or num_inference_steps
|
||||
guidance_scale = req.guidance_scale if req.guidance_scale is not None else guidance_scale
|
||||
generator = req.generator or generator
|
||||
req_num_outputs = getattr(req, "num_outputs_per_prompt", None)
|
||||
if req_num_outputs and req_num_outputs > 0:
|
||||
num_images_per_prompt = req_num_outputs
|
||||
|
||||
if isinstance(req.prompt_embeds, torch.Tensor):
|
||||
prompt_embeds = req.prompt_embeds
|
||||
if isinstance(req.negative_prompt_embeds, torch.Tensor):
|
||||
negative_prompt_embeds = req.negative_prompt_embeds
|
||||
|
||||
if req.max_sequence_length is not None:
|
||||
max_sequence_length = req.max_sequence_length
|
||||
if getattr(req, "text_encoder_out_layers", None) is not None:
|
||||
text_encoder_out_layers = req.text_encoder_out_layers
|
||||
|
||||
# 1. Check inputs. Raise error if not correct
|
||||
self.check_inputs(
|
||||
prompt=prompt,
|
||||
height=height,
|
||||
width=width,
|
||||
prompt_embeds=prompt_embeds,
|
||||
callback_on_step_end_tensor_inputs=callback_on_step_end_tensor_inputs,
|
||||
guidance_scale=guidance_scale,
|
||||
)
|
||||
|
||||
self._guidance_scale = guidance_scale
|
||||
self._attention_kwargs = attention_kwargs
|
||||
self._current_timestep = None
|
||||
self._interrupt = False
|
||||
|
||||
# 2. Define call parameters
|
||||
if prompt is not None and isinstance(prompt, str):
|
||||
batch_size = 1
|
||||
elif prompt is not None and isinstance(prompt, list):
|
||||
batch_size = len(prompt)
|
||||
else:
|
||||
batch_size = prompt_embeds.shape[0]
|
||||
|
||||
device = self._execution_device
|
||||
|
||||
# 3. prepare text embeddings
|
||||
prompt_embeds, text_ids = self.encode_prompt(
|
||||
prompt=prompt,
|
||||
prompt_embeds=prompt_embeds,
|
||||
device=device,
|
||||
num_images_per_prompt=num_images_per_prompt,
|
||||
max_sequence_length=max_sequence_length,
|
||||
text_encoder_out_layers=text_encoder_out_layers,
|
||||
)
|
||||
|
||||
if self.do_classifier_free_guidance:
|
||||
negative_prompt = ""
|
||||
if prompt is not None and isinstance(prompt, list):
|
||||
negative_prompt = [negative_prompt] * len(prompt)
|
||||
negative_prompt_embeds, negative_text_ids = self.encode_prompt(
|
||||
prompt=negative_prompt,
|
||||
prompt_embeds=negative_prompt_embeds,
|
||||
device=device,
|
||||
num_images_per_prompt=num_images_per_prompt,
|
||||
max_sequence_length=max_sequence_length,
|
||||
text_encoder_out_layers=text_encoder_out_layers,
|
||||
)
|
||||
|
||||
# 4. process images
|
||||
if image is not None and not isinstance(image, list):
|
||||
image = [image]
|
||||
|
||||
condition_images = None
|
||||
if image is not None:
|
||||
for img in image:
|
||||
self.image_processor.check_image_input(img)
|
||||
|
||||
condition_images = []
|
||||
for img in image:
|
||||
image_width, image_height = img.size
|
||||
if image_width * image_height > 1024 * 1024:
|
||||
img = self.image_processor._resize_to_target_area(img, 1024 * 1024)
|
||||
image_width, image_height = img.size
|
||||
|
||||
multiple_of = self.vae_scale_factor * 2
|
||||
image_width = (image_width // multiple_of) * multiple_of
|
||||
image_height = (image_height // multiple_of) * multiple_of
|
||||
img = self.image_processor.preprocess(img, height=image_height, width=image_width, resize_mode="crop")
|
||||
condition_images.append(img)
|
||||
height = height or image_height
|
||||
width = width or image_width
|
||||
|
||||
height = height or self.default_sample_size * self.vae_scale_factor
|
||||
width = width or self.default_sample_size * self.vae_scale_factor
|
||||
|
||||
# 5. prepare latent variables
|
||||
num_channels_latents = self.transformer.config.in_channels // 4
|
||||
latents, latent_ids = self.prepare_latents(
|
||||
batch_size=batch_size * num_images_per_prompt,
|
||||
num_latents_channels=num_channels_latents,
|
||||
height=height,
|
||||
width=width,
|
||||
dtype=prompt_embeds.dtype,
|
||||
device=device,
|
||||
generator=generator,
|
||||
latents=latents,
|
||||
)
|
||||
|
||||
image_latents = None
|
||||
image_latent_ids = None
|
||||
if condition_images is not None:
|
||||
image_latents, image_latent_ids = self.prepare_image_latents(
|
||||
images=condition_images,
|
||||
batch_size=batch_size * num_images_per_prompt,
|
||||
generator=generator,
|
||||
device=device,
|
||||
dtype=self.vae.dtype,
|
||||
)
|
||||
|
||||
# 6. Prepare timesteps
|
||||
sigmas = np.linspace(1.0, 1 / num_inference_steps, num_inference_steps) if sigmas is None else sigmas
|
||||
if hasattr(self.scheduler.config, "use_flow_sigmas") and self.scheduler.config.use_flow_sigmas:
|
||||
sigmas = None
|
||||
image_seq_len = latents.shape[1]
|
||||
mu = compute_empirical_mu(image_seq_len=image_seq_len, num_steps=num_inference_steps)
|
||||
timesteps, num_inference_steps = retrieve_timesteps(
|
||||
self.scheduler,
|
||||
num_inference_steps,
|
||||
device,
|
||||
sigmas=sigmas,
|
||||
mu=mu,
|
||||
)
|
||||
self._num_timesteps = len(timesteps)
|
||||
|
||||
# 7. Denoising loop
|
||||
# We set the index here to remove DtoH sync, helpful especially during compilation.
|
||||
# Check out more details here: https://github.com/huggingface/diffusers/pull/11696
|
||||
self.scheduler.set_begin_index(0)
|
||||
for i, t in enumerate(timesteps):
|
||||
if self.interrupt:
|
||||
continue
|
||||
|
||||
self._current_timestep = t
|
||||
timestep = t.expand(latents.shape[0]).to(latents.dtype)
|
||||
|
||||
latent_model_input = latents.to(self.transformer.dtype)
|
||||
latent_image_ids = latent_ids
|
||||
|
||||
if image_latents is not None:
|
||||
latent_model_input = torch.cat([latents, image_latents], dim=1).to(self.transformer.dtype)
|
||||
latent_image_ids = torch.cat([latent_ids, image_latent_ids], dim=1)
|
||||
|
||||
noise_pred = self.transformer(
|
||||
hidden_states=latent_model_input,
|
||||
timestep=timestep / 1000,
|
||||
guidance=None,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
txt_ids=text_ids,
|
||||
img_ids=latent_image_ids,
|
||||
joint_attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
|
||||
noise_pred = noise_pred[:, : latents.size(1) :]
|
||||
|
||||
if self.do_classifier_free_guidance:
|
||||
neg_noise_pred = self.transformer(
|
||||
hidden_states=latent_model_input,
|
||||
timestep=timestep / 1000,
|
||||
guidance=None,
|
||||
encoder_hidden_states=negative_prompt_embeds,
|
||||
txt_ids=negative_text_ids,
|
||||
img_ids=latent_image_ids,
|
||||
joint_attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
neg_noise_pred = neg_noise_pred[:, : latents.size(1) :]
|
||||
noise_pred = neg_noise_pred + guidance_scale * (noise_pred - neg_noise_pred)
|
||||
|
||||
latents_dtype = latents.dtype
|
||||
latents = self.scheduler.step(noise_pred, t, latents, return_dict=False)[0]
|
||||
|
||||
if latents.dtype != latents_dtype and torch.backends.mps.is_available():
|
||||
latents = latents.to(latents_dtype)
|
||||
|
||||
if callback_on_step_end is not None:
|
||||
callback_kwargs = {}
|
||||
for k in callback_on_step_end_tensor_inputs:
|
||||
callback_kwargs[k] = locals()[k]
|
||||
callback_outputs = callback_on_step_end(self, i, t, callback_kwargs)
|
||||
|
||||
latents = callback_outputs.pop("latents", latents)
|
||||
prompt_embeds = callback_outputs.pop("prompt_embeds", prompt_embeds)
|
||||
|
||||
self._current_timestep = None
|
||||
|
||||
latents = self._unpack_latents_with_ids(latents, latent_ids)
|
||||
|
||||
latents_bn_mean = self.vae.bn.running_mean.view(1, -1, 1, 1).to(latents.device, latents.dtype)
|
||||
latents_bn_std = torch.sqrt(self.vae.bn.running_var.view(1, -1, 1, 1) + self.vae.config.batch_norm_eps).to(
|
||||
latents.device, latents.dtype
|
||||
)
|
||||
latents = latents * latents_bn_std + latents_bn_mean
|
||||
latents = self._unpatchify_latents(latents)
|
||||
if output_type == "latent":
|
||||
image = latents
|
||||
else:
|
||||
if latents.dtype != self.vae.dtype:
|
||||
latents = latents.to(self.vae.dtype)
|
||||
image = self.vae.decode(latents, return_dict=False)[0]
|
||||
|
||||
return DiffusionOutput(output=image)
|
||||
|
||||
def load_weights(self, weights: Iterable[tuple[str, torch.Tensor]]) -> set[str]:
|
||||
loader = AutoWeightsLoader(self)
|
||||
return loader.load_weights(weights)
|
||||
@@ -0,0 +1,12 @@
|
||||
# SPDX-License-Identifier: Apache-2.0
|
||||
# SPDX-FileCopyrightText: Copyright contributors to the vLLM project
|
||||
from typing import (
|
||||
ClassVar,
|
||||
Protocol,
|
||||
runtime_checkable,
|
||||
)
|
||||
|
||||
|
||||
@runtime_checkable
|
||||
class SupportImageInput(Protocol):
|
||||
support_image_input: ClassVar[bool] = True
|
||||
@@ -6,7 +6,7 @@ from typing import Any
|
||||
|
||||
import torch
|
||||
import torch.nn as nn
|
||||
from diffusers.models.embeddings import TimestepEmbedding, Timesteps, get_1d_rotary_pos_embed
|
||||
from diffusers.models.embeddings import TimestepEmbedding, Timesteps, apply_rotary_emb, get_1d_rotary_pos_embed
|
||||
from diffusers.models.modeling_outputs import Transformer2DModelOutput
|
||||
from diffusers.models.normalization import AdaLayerNormContinuous, AdaLayerNormZero, AdaLayerNormZeroSingle
|
||||
from vllm.logger import init_logger
|
||||
@@ -15,9 +15,15 @@ from vllm.model_executor.layers.layernorm import RMSNorm
|
||||
from vllm.model_executor.layers.linear import QKVParallelLinear, ReplicatedLinear
|
||||
from vllm.model_executor.model_loader.weight_utils import default_weight_loader
|
||||
|
||||
from vllm_omni.diffusion.attention.backends.abstract import AttentionMetadata
|
||||
from vllm_omni.diffusion.attention.layer import Attention
|
||||
from vllm_omni.diffusion.data import OmniDiffusionConfig
|
||||
from vllm_omni.diffusion.layers.rope import RotaryEmbedding
|
||||
from vllm_omni.diffusion.distributed.parallel_state import (
|
||||
get_sequence_parallel_rank,
|
||||
get_sequence_parallel_world_size,
|
||||
get_sp_group,
|
||||
)
|
||||
from vllm_omni.diffusion.forward_context import get_forward_context
|
||||
from vllm_omni.utils.platform_utils import is_npu
|
||||
|
||||
logger = init_logger(__name__)
|
||||
@@ -98,7 +104,6 @@ class LongCatImageAttention(nn.Module):
|
||||
|
||||
self.to_add_out = ReplicatedLinear(self.inner_dim, query_dim, bias=out_bias)
|
||||
|
||||
self.rope = RotaryEmbedding(is_neox_style=False)
|
||||
self.attn = Attention(
|
||||
num_heads=heads,
|
||||
head_size=self.head_dim,
|
||||
@@ -106,6 +111,55 @@ class LongCatImageAttention(nn.Module):
|
||||
causal=False,
|
||||
)
|
||||
|
||||
def _sp_attention_with_rope(
|
||||
self,
|
||||
img_query: torch.Tensor,
|
||||
img_key: torch.Tensor,
|
||||
img_value: torch.Tensor,
|
||||
text_query: torch.Tensor,
|
||||
text_key: torch.Tensor,
|
||||
text_value: torch.Tensor,
|
||||
text_seq_len: int,
|
||||
image_rotary_emb: tuple[torch.Tensor, torch.Tensor] | None,
|
||||
) -> torch.Tensor:
|
||||
"""
|
||||
Apply RoPE separately to text and image Q/K, then run SP attention with joint tensors.
|
||||
|
||||
This is the common SP attention pattern used by both dual-stream (added_kv_proj_dim)
|
||||
and single-stream (no added_kv_proj_dim) blocks.
|
||||
|
||||
Args:
|
||||
img_query/key/value: Image Q/K/V tensors (chunked in SP mode)
|
||||
text_query/key/value: Text Q/K/V tensors (full, not chunked)
|
||||
text_seq_len: Length of text sequence for splitting RoPE
|
||||
image_rotary_emb: (freqs_cos, freqs_sin) containing [txt_pos, img_pos]
|
||||
|
||||
Returns:
|
||||
Attention output with shape (B, txt_len + img_len/SP, H, D)
|
||||
"""
|
||||
if image_rotary_emb is not None:
|
||||
freqs_cos, freqs_sin = image_rotary_emb
|
||||
txt_rotary_emb = (freqs_cos[:text_seq_len], freqs_sin[:text_seq_len])
|
||||
img_rotary_emb_split = (freqs_cos[text_seq_len:], freqs_sin[text_seq_len:])
|
||||
# Apply RoPE to image Q/K
|
||||
img_query = apply_rotary_emb(img_query, img_rotary_emb_split, sequence_dim=1)
|
||||
img_key = apply_rotary_emb(img_key, img_rotary_emb_split, sequence_dim=1)
|
||||
# Apply RoPE to text Q/K
|
||||
text_query = apply_rotary_emb(text_query, txt_rotary_emb, sequence_dim=1)
|
||||
text_key = apply_rotary_emb(text_key, txt_rotary_emb, sequence_dim=1)
|
||||
|
||||
return self.attn(
|
||||
img_query,
|
||||
img_key,
|
||||
img_value,
|
||||
AttentionMetadata(
|
||||
joint_query=text_query,
|
||||
joint_key=text_key,
|
||||
joint_value=text_value,
|
||||
joint_strategy="front",
|
||||
),
|
||||
)
|
||||
|
||||
def forward(
|
||||
self,
|
||||
hidden_states: torch.Tensor,
|
||||
@@ -113,6 +167,22 @@ class LongCatImageAttention(nn.Module):
|
||||
image_rotary_emb: torch.Tensor | None = None,
|
||||
**kwargs,
|
||||
) -> torch.Tensor:
|
||||
"""
|
||||
Forward pass with SP-aware joint attention.
|
||||
|
||||
Input shapes (in SP mode):
|
||||
- hidden_states: (B, img_seq_len // SP, D) - image hidden states (chunked)
|
||||
- encoder_hidden_states: (B, txt_seq_len, D) - text hidden states (full)
|
||||
|
||||
SP Mode (sequence_parallel_size > 1):
|
||||
- Image Q/K/V: processed with AllToAll or Ring communication
|
||||
- Text Q/K/V: passed as joint tensors, broadcasted to all ranks
|
||||
- Output: attention over (text + image) with proper SP handling
|
||||
|
||||
Non-SP Mode (sequence_parallel_size = 1):
|
||||
- Standard concatenation of text + image Q/K/V
|
||||
- Regular attention over the full sequence
|
||||
"""
|
||||
qkv, _ = self.to_qkv(hidden_states)
|
||||
|
||||
query, key, value = qkv.chunk(3, dim=-1)
|
||||
@@ -132,29 +202,85 @@ class LongCatImageAttention(nn.Module):
|
||||
encoder_key = encoder_key.unflatten(-1, (self.heads, -1))
|
||||
encoder_value = encoder_value.unflatten(-1, (self.heads, -1))
|
||||
|
||||
# Apply RMSNorm to text Q/K
|
||||
encoder_query = self.norm_added_q(encoder_query)
|
||||
encoder_key = self.norm_added_k(encoder_key)
|
||||
|
||||
query = torch.cat([encoder_query, query], dim=1)
|
||||
key = torch.cat([encoder_key, key], dim=1)
|
||||
value = torch.cat([encoder_value, value], dim=1)
|
||||
# Check if SP is enabled from forward context (set by LongCatImageTransformer2DModel)
|
||||
forward_ctx = get_forward_context()
|
||||
sp_size = forward_ctx.sequence_parallel_size
|
||||
use_sp_joint_attention = sp_size > 1 and not forward_ctx.split_text_embed_in_sp
|
||||
|
||||
if image_rotary_emb is not None:
|
||||
cos, sin = image_rotary_emb # [S, D/2]
|
||||
cos = cos.to(query.dtype)
|
||||
sin = sin.to(query.dtype)
|
||||
query = self.rope(query, cos, sin)
|
||||
key = self.rope(key, cos, sin)
|
||||
if use_sp_joint_attention:
|
||||
# SP Mode: Use common helper for RoPE + joint attention
|
||||
hidden_states = self._sp_attention_with_rope(
|
||||
img_query=query,
|
||||
img_key=key,
|
||||
img_value=value,
|
||||
text_query=encoder_query,
|
||||
text_key=encoder_key,
|
||||
text_value=encoder_value,
|
||||
text_seq_len=encoder_query.shape[1],
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
)
|
||||
else:
|
||||
# Non-SP Mode: Concat first, then apply RoPE to full sequence
|
||||
joint_query = torch.cat([encoder_query, query], dim=1)
|
||||
joint_key = torch.cat([encoder_key, key], dim=1)
|
||||
joint_value = torch.cat([encoder_value, value], dim=1)
|
||||
|
||||
hidden_states = self.attn(
|
||||
query,
|
||||
key,
|
||||
value,
|
||||
)
|
||||
if image_rotary_emb is not None:
|
||||
# Apply RoPE to full (text + image) sequence
|
||||
joint_query = apply_rotary_emb(joint_query, image_rotary_emb, sequence_dim=1)
|
||||
joint_key = apply_rotary_emb(joint_key, image_rotary_emb, sequence_dim=1)
|
||||
|
||||
hidden_states = self.attn(
|
||||
joint_query,
|
||||
joint_key,
|
||||
joint_value,
|
||||
)
|
||||
else:
|
||||
# No added_kv_proj_dim: single stream attention (e.g., from SingleTransformerBlock)
|
||||
# hidden_states is the combined (text + image) sequence
|
||||
# In SP mode, image part is chunked: (B, txt_len + img_len/SP, D)
|
||||
|
||||
# Check if SP is enabled and we have text_seq_len info
|
||||
forward_ctx = get_forward_context()
|
||||
sp_size = forward_ctx.sequence_parallel_size
|
||||
text_seq_len = kwargs.get("text_seq_len", None)
|
||||
use_sp_single_stream = sp_size > 1 and not forward_ctx.split_text_embed_in_sp and text_seq_len is not None
|
||||
|
||||
if use_sp_single_stream:
|
||||
# SP Mode for single-stream block:
|
||||
# Split QKV into text and image parts, then use common helper
|
||||
hidden_states = self._sp_attention_with_rope(
|
||||
img_query=query[:, text_seq_len:],
|
||||
img_key=key[:, text_seq_len:],
|
||||
img_value=value[:, text_seq_len:],
|
||||
text_query=query[:, :text_seq_len],
|
||||
text_key=key[:, :text_seq_len],
|
||||
text_value=value[:, :text_seq_len],
|
||||
text_seq_len=text_seq_len,
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
)
|
||||
else:
|
||||
# Non-SP Mode: standard path
|
||||
if image_rotary_emb is not None:
|
||||
query = apply_rotary_emb(query, image_rotary_emb, sequence_dim=1)
|
||||
key = apply_rotary_emb(key, image_rotary_emb, sequence_dim=1)
|
||||
|
||||
hidden_states = self.attn(
|
||||
query,
|
||||
key,
|
||||
value,
|
||||
)
|
||||
hidden_states = hidden_states.flatten(2, 3)
|
||||
hidden_states = hidden_states.to(query.dtype)
|
||||
|
||||
if encoder_hidden_states is not None:
|
||||
# Split output back into text and image portions
|
||||
# In SP mode: seq_len = txt_seq_len + img_seq_len // SP
|
||||
# In non-SP mode: seq_len = txt_seq_len + img_seq_len
|
||||
encoder_hidden_states, hidden_states = hidden_states.split_with_sizes(
|
||||
[encoder_hidden_states.shape[1], hidden_states.shape[1] - encoder_hidden_states.shape[1]], dim=1
|
||||
)
|
||||
@@ -268,15 +394,16 @@ class LongCatImagePosEmbed(nn.Module):
|
||||
is_npu = ids.device.type == "npu"
|
||||
freqs_dtype = torch.float32 if (is_mps or is_npu) else torch.float64
|
||||
for i in range(n_axes):
|
||||
freqs_cis = get_1d_rotary_pos_embed(
|
||||
cos, sin = get_1d_rotary_pos_embed(
|
||||
self.axes_dim[i],
|
||||
pos[:, i],
|
||||
theta=self.theta,
|
||||
use_real=False,
|
||||
repeat_interleave_real=True,
|
||||
use_real=True,
|
||||
freqs_dtype=freqs_dtype,
|
||||
)
|
||||
cos_out.append(freqs_cis.real)
|
||||
sin_out.append(freqs_cis.imag)
|
||||
cos_out.append(cos)
|
||||
sin_out.append(sin)
|
||||
freqs_cos = torch.cat(cos_out, dim=-1).to(ids.device)
|
||||
freqs_sin = torch.cat(sin_out, dim=-1).to(ids.device)
|
||||
return freqs_cos, freqs_sin
|
||||
@@ -297,6 +424,13 @@ class LongCatImageTimestepEmbeddings(nn.Module):
|
||||
|
||||
|
||||
class LongCatImageSingleTransformerBlock(nn.Module):
|
||||
"""
|
||||
Single-stream Transformer block for LongCat with SP (Sequence Parallelism) support.
|
||||
|
||||
SP handling is delegated to LongCatImageAttention via the text_seq_len parameter.
|
||||
This keeps the block logic clean and centralizes SP logic in the attention layer.
|
||||
"""
|
||||
|
||||
def __init__(self, dim: int, num_attention_heads: int, attention_head_dim: int, mlp_ratio: float = 4.0):
|
||||
super().__init__()
|
||||
self.mlp_hidden_dim = int(dim * mlp_ratio)
|
||||
@@ -306,6 +440,7 @@ class LongCatImageSingleTransformerBlock(nn.Module):
|
||||
self.act_mlp = nn.GELU(approximate="tanh")
|
||||
self.proj_out = nn.Linear(dim + self.mlp_hidden_dim, dim)
|
||||
|
||||
# SP handling is delegated to LongCatImageAttention via text_seq_len kwarg
|
||||
self.attn = LongCatImageAttention(
|
||||
query_dim=dim,
|
||||
dim_head=attention_head_dim,
|
||||
@@ -324,16 +459,28 @@ class LongCatImageSingleTransformerBlock(nn.Module):
|
||||
image_rotary_emb: tuple[torch.Tensor, torch.Tensor] | None = None,
|
||||
joint_attention_kwargs: dict[str, Any] | None = None,
|
||||
) -> tuple[torch.Tensor, torch.Tensor]:
|
||||
text_seq_len = encoder_hidden_states.shape[1]
|
||||
hidden_states = torch.cat([encoder_hidden_states, hidden_states], dim=1)
|
||||
"""
|
||||
Forward pass for SingleTransformerBlock with SP support.
|
||||
|
||||
residual = hidden_states
|
||||
norm_hidden_states, gate = self.norm(hidden_states, emb=temb)
|
||||
SP handling is delegated to LongCatImageAttention.forward via text_seq_len kwarg.
|
||||
This keeps the block logic clean and centralizes SP logic in the attention layer.
|
||||
"""
|
||||
text_seq_len = encoder_hidden_states.shape[1]
|
||||
|
||||
# Concatenate text and image
|
||||
# In SP mode: image is chunked (B, img_len/SP, D), text is full (B, txt_len, D)
|
||||
combined = torch.cat([encoder_hidden_states, hidden_states], dim=1)
|
||||
residual = combined
|
||||
norm_hidden_states, gate = self.norm(combined, emb=temb)
|
||||
mlp_hidden_states = self.act_mlp(self.proj_mlp(norm_hidden_states))
|
||||
|
||||
# Delegate SP handling to LongCatImageAttention by passing text_seq_len
|
||||
# LongCatImageAttention will detect SP mode and handle text/image splitting internally
|
||||
joint_attention_kwargs = joint_attention_kwargs or {}
|
||||
attn_output = self.attn(
|
||||
hidden_states=norm_hidden_states,
|
||||
image_rotary_emb=image_rotary_emb,
|
||||
text_seq_len=text_seq_len, # Pass text_seq_len for SP mode handling
|
||||
**joint_attention_kwargs,
|
||||
)
|
||||
|
||||
@@ -341,6 +488,7 @@ class LongCatImageSingleTransformerBlock(nn.Module):
|
||||
gate = gate.unsqueeze(1)
|
||||
hidden_states = gate * self.proj_out(hidden_states)
|
||||
hidden_states = residual + hidden_states
|
||||
|
||||
if hidden_states.dtype == torch.float16:
|
||||
hidden_states = hidden_states.clip(-65504, 65504)
|
||||
|
||||
@@ -351,6 +499,8 @@ class LongCatImageSingleTransformerBlock(nn.Module):
|
||||
class LongCatImageTransformer2DModel(nn.Module):
|
||||
"""
|
||||
The Transformer model introduced in Flux.
|
||||
|
||||
Supports Sequence Parallelism (Ulysses and Ring) when configured via OmniDiffusionConfig.
|
||||
"""
|
||||
|
||||
def __init__(
|
||||
@@ -371,6 +521,9 @@ class LongCatImageTransformer2DModel(nn.Module):
|
||||
self.inner_dim = num_attention_heads * attention_head_dim
|
||||
self.pooled_projection_dim = pooled_projection_dim
|
||||
|
||||
# Store parallel config for SP support
|
||||
self.parallel_config = od_config.parallel_config
|
||||
|
||||
self.pos_embed = LongCatImagePosEmbed(theta=10000, axes_dim=axes_dims_rope)
|
||||
|
||||
self.time_embed = LongCatImageTimestepEmbeddings(embedding_dim=self.inner_dim)
|
||||
@@ -418,6 +571,31 @@ class LongCatImageTransformer2DModel(nn.Module):
|
||||
guidance: torch.Tensor = None,
|
||||
return_dict: bool = True,
|
||||
) -> torch.FloatTensor | Transformer2DModelOutput:
|
||||
# Before: hidden_states shape = (B, img_seq_len, in_channels)
|
||||
# After: hidden_states shape = (B, img_seq_len // SP, in_channels)
|
||||
sp_size = self.parallel_config.sequence_parallel_size
|
||||
# Store SP size in forward context for sub-modules to access
|
||||
get_forward_context().sequence_parallel_size = sp_size
|
||||
if sp_size > 1:
|
||||
sp_world_size = get_sequence_parallel_world_size()
|
||||
sp_rank = get_sequence_parallel_rank()
|
||||
original_shape = hidden_states.shape
|
||||
hidden_states = torch.chunk(hidden_states, sp_world_size, dim=1)[sp_rank]
|
||||
# LongCat uses dual-stream (text + image) with joint attention
|
||||
# Text embeddings should be replicated across SP ranks for correctness
|
||||
get_forward_context().split_text_embed_in_sp = False
|
||||
# Debug log (only first forward)
|
||||
if not hasattr(self, "_sp_forward_logged"):
|
||||
self._sp_forward_logged = True
|
||||
logger.info(
|
||||
f"[LongCat Transformer] SP enabled: sp_size={sp_size}, world_size={sp_world_size}, "
|
||||
f"rank={sp_rank}, original_shape={original_shape}, chunked_shape={hidden_states.shape}"
|
||||
)
|
||||
else:
|
||||
if not hasattr(self, "_sp_forward_logged"):
|
||||
self._sp_forward_logged = True
|
||||
logger.info(f"[LongCat Transformer] SP disabled: sp_size={sp_size}")
|
||||
|
||||
hidden_states = self.x_embedder(hidden_states)
|
||||
|
||||
timestep = timestep.to(hidden_states.dtype) * 1000
|
||||
@@ -433,6 +611,39 @@ class LongCatImageTransformer2DModel(nn.Module):
|
||||
else:
|
||||
image_rotary_emb = self.pos_embed(ids)
|
||||
|
||||
# SP: Chunk RoPE embeddings along sequence dimension
|
||||
if self.parallel_config.sequence_parallel_size > 1:
|
||||
sp_world_size = get_sequence_parallel_world_size()
|
||||
sp_rank = get_sequence_parallel_rank()
|
||||
freqs_cos, freqs_sin = image_rotary_emb
|
||||
txt_len = txt_ids.shape[0]
|
||||
|
||||
# Split RoPE into text and image portions
|
||||
# txt_freqs: (txt_seq_len, head_dim) - keep full for all ranks
|
||||
# img_freqs: (img_seq_len, head_dim) -> (img_seq_len // SP, head_dim)
|
||||
txt_freqs_cos = freqs_cos[:txt_len]
|
||||
txt_freqs_sin = freqs_sin[:txt_len]
|
||||
img_freqs_cos = freqs_cos[txt_len:]
|
||||
img_freqs_sin = freqs_sin[txt_len:]
|
||||
|
||||
# Chunk image RoPE for each SP rank
|
||||
# img_freqs_cos: (img_seq_len // SP, head_dim)
|
||||
# img_freqs_sin: (img_seq_len // SP, head_dim)
|
||||
img_freqs_cos = torch.chunk(img_freqs_cos, sp_world_size, dim=0)[sp_rank]
|
||||
img_freqs_sin = torch.chunk(img_freqs_sin, sp_world_size, dim=0)[sp_rank]
|
||||
|
||||
# Optionally chunk text RoPE if split_text_embed_in_sp is True
|
||||
if get_forward_context().split_text_embed_in_sp:
|
||||
txt_freqs_cos = torch.chunk(txt_freqs_cos, sp_world_size, dim=0)[sp_rank]
|
||||
txt_freqs_sin = torch.chunk(txt_freqs_sin, sp_world_size, dim=0)[sp_rank]
|
||||
|
||||
# Reconstruct image_rotary_emb with chunked values
|
||||
# Final shape: (txt_seq_len + img_seq_len // SP, head_dim)
|
||||
image_rotary_emb = (
|
||||
torch.cat([txt_freqs_cos, img_freqs_cos], dim=0),
|
||||
torch.cat([txt_freqs_sin, img_freqs_sin], dim=0),
|
||||
)
|
||||
|
||||
for index_block, block in enumerate(self.transformer_blocks):
|
||||
if torch.is_grad_enabled() and self.gradient_checkpointing and self.use_checkpoint[index_block]:
|
||||
encoder_hidden_states, hidden_states = self._gradient_checkpointing_func(
|
||||
@@ -470,6 +681,10 @@ class LongCatImageTransformer2DModel(nn.Module):
|
||||
hidden_states = self.norm_out(hidden_states, temb)
|
||||
output = self.proj_out(hidden_states)
|
||||
|
||||
# SP: All-gather output to reconstruct full sequence
|
||||
if self.parallel_config.sequence_parallel_size > 1:
|
||||
output = get_sp_group().all_gather(output, dim=1)
|
||||
|
||||
if not return_dict:
|
||||
return (output,)
|
||||
|
||||
|
||||
@@ -28,6 +28,7 @@ from vllm.model_executor.models.utils import AutoWeightsLoader
|
||||
from vllm_omni.diffusion.data import DiffusionOutput, OmniDiffusionConfig
|
||||
from vllm_omni.diffusion.distributed.utils import get_local_device
|
||||
from vllm_omni.diffusion.model_loader.diffusers_loader import DiffusersPipelineLoader
|
||||
from vllm_omni.diffusion.models.interface import SupportImageInput
|
||||
from vllm_omni.diffusion.models.longcat_image.longcat_image_transformer import (
|
||||
LongCatImageTransformer2DModel,
|
||||
)
|
||||
@@ -196,7 +197,7 @@ def split_quotation(prompt, quote_pairs=None):
|
||||
return result
|
||||
|
||||
|
||||
class LongCatImageEditPipeline(nn.Module):
|
||||
class LongCatImageEditPipeline(nn.Module, SupportImageInput):
|
||||
def __init__(
|
||||
self,
|
||||
*,
|
||||
@@ -466,7 +467,7 @@ class LongCatImageEditPipeline(nn.Module):
|
||||
if height % (self.vae_scale_factor * 2) != 0 or width % (self.vae_scale_factor * 2) != 0:
|
||||
logger.warning(
|
||||
"`height` and `width` have to be divisible by "
|
||||
"{self.vae_scale_factor * 2} but are {height} and {width}. "
|
||||
f"{self.vae_scale_factor * 2} but are {height} and {width}. "
|
||||
"Dimensions will be resized accordingly"
|
||||
)
|
||||
|
||||
|
||||
@@ -365,6 +365,8 @@ class OvisImageTransformer2DModel(nn.Module):
|
||||
The dimensions to use for the rotary positional embeddings.
|
||||
"""
|
||||
|
||||
_repeated_blocks = ["OvisImageTransformerBlock", "OvisImageSingleTransformerBlock"]
|
||||
|
||||
def __init__(
|
||||
self,
|
||||
od_config: OmniDiffusionConfig,
|
||||
|
||||
@@ -328,7 +328,7 @@ class OvisImagePipeline(
|
||||
"Provide either `prompt` or `prompt_embeds`. Cannot leave both `prompt` and `prompt_embeds` undefined."
|
||||
)
|
||||
elif prompt is not None and (not isinstance(prompt, str) and not isinstance(prompt, list)):
|
||||
raise ValueError("`prompt` has to be of type `str` or `list[str]` but is {type(prompt)}")
|
||||
raise ValueError(f"`prompt` has to be of type `str` or `list[str]` but is {type(prompt)}")
|
||||
|
||||
if negative_prompt is not None and negative_prompt_embeds is not None:
|
||||
raise ValueError(
|
||||
|
||||
@@ -11,6 +11,7 @@ from typing import Any
|
||||
|
||||
import numpy as np
|
||||
import torch
|
||||
import torch.distributed
|
||||
from diffusers.image_processor import VaeImageProcessor
|
||||
from diffusers.models.autoencoders.autoencoder_kl_qwenimage import (
|
||||
AutoencoderKLQwenImage,
|
||||
@@ -24,12 +25,18 @@ from transformers import Qwen2_5_VLForConditionalGeneration, Qwen2Tokenizer
|
||||
from vllm.model_executor.models.utils import AutoWeightsLoader
|
||||
|
||||
from vllm_omni.diffusion.data import DiffusionOutput, OmniDiffusionConfig
|
||||
from vllm_omni.diffusion.distributed.parallel_state import (
|
||||
get_cfg_group,
|
||||
get_classifier_free_guidance_rank,
|
||||
get_classifier_free_guidance_world_size,
|
||||
)
|
||||
from vllm_omni.diffusion.distributed.utils import get_local_device
|
||||
from vllm_omni.diffusion.model_loader.diffusers_loader import DiffusersPipelineLoader
|
||||
from vllm_omni.diffusion.models.qwen_image.qwen_image_transformer import (
|
||||
QwenImageTransformer2DModel,
|
||||
)
|
||||
from vllm_omni.diffusion.request import OmniDiffusionRequest
|
||||
from vllm_omni.diffusion.utils.tf_utils import get_transformer_config_kwargs
|
||||
from vllm_omni.model_executor.model_loader.weight_utils import (
|
||||
download_weights_from_hf_specific,
|
||||
)
|
||||
@@ -243,6 +250,7 @@ class QwenImagePipeline(
|
||||
):
|
||||
super().__init__()
|
||||
self.od_config = od_config
|
||||
self.parallel_config = od_config.parallel_config
|
||||
self.weights_sources = [
|
||||
DiffusersPipelineLoader.ComponentSource(
|
||||
model_or_path=od_config.model,
|
||||
@@ -267,7 +275,8 @@ class QwenImagePipeline(
|
||||
self.vae = AutoencoderKLQwenImage.from_pretrained(model, subfolder="vae", local_files_only=local_files_only).to(
|
||||
self.device
|
||||
)
|
||||
self.transformer = QwenImageTransformer2DModel(od_config=od_config)
|
||||
transformer_kwargs = get_transformer_config_kwargs(od_config.tf_model_config, QwenImageTransformer2DModel)
|
||||
self.transformer = QwenImageTransformer2DModel(od_config=od_config, **transformer_kwargs)
|
||||
|
||||
self.tokenizer = Qwen2Tokenizer.from_pretrained(model, subfolder="tokenizer", local_files_only=local_files_only)
|
||||
|
||||
@@ -301,7 +310,7 @@ class QwenImagePipeline(
|
||||
if height % (self.vae_scale_factor * 2) != 0 or width % (self.vae_scale_factor * 2) != 0:
|
||||
logger.warning(
|
||||
f"`height` and `width` have to be divisible by {self.vae_scale_factor * 2} "
|
||||
"but are {height} and {width}. Dimensions will be resized accordingly"
|
||||
f"but are {height} and {width}. Dimensions will be resized accordingly"
|
||||
)
|
||||
|
||||
# if callback_on_step_end_tensor_inputs is not None and not all(
|
||||
@@ -551,38 +560,83 @@ class QwenImagePipeline(
|
||||
# Broadcast timestep to match batch size
|
||||
timestep = t.expand(latents.shape[0]).to(device=latents.device, dtype=latents.dtype)
|
||||
|
||||
# Forward pass for positive prompt (or unconditional if no CFG)
|
||||
# Enable CFG-parallel: rank0 computes positive, rank1 computes negative.
|
||||
cfg_parallel_ready = do_true_cfg and get_classifier_free_guidance_world_size() > 1
|
||||
|
||||
self.transformer.do_true_cfg = do_true_cfg
|
||||
noise_pred = self.transformer(
|
||||
hidden_states=latents,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=prompt_embeds_mask,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
# Forward pass for negative prompt (CFG)
|
||||
if do_true_cfg:
|
||||
neg_noise_pred = self.transformer(
|
||||
|
||||
if cfg_parallel_ready:
|
||||
cfg_group = get_cfg_group()
|
||||
cfg_rank = get_classifier_free_guidance_rank()
|
||||
|
||||
if cfg_rank == 0:
|
||||
local_pred = self.transformer(
|
||||
hidden_states=latents,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=prompt_embeds_mask,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
else:
|
||||
local_pred = self.transformer(
|
||||
hidden_states=latents,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=negative_prompt_embeds_mask,
|
||||
encoder_hidden_states=negative_prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=negative_txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
|
||||
gathered = cfg_group.all_gather(local_pred, separate_tensors=True)
|
||||
if cfg_rank == 0:
|
||||
noise_pred = gathered[0]
|
||||
neg_noise_pred = gathered[1]
|
||||
comb_pred = neg_noise_pred + true_cfg_scale * (noise_pred - neg_noise_pred)
|
||||
cond_norm = torch.norm(noise_pred, dim=-1, keepdim=True)
|
||||
noise_norm = torch.norm(comb_pred, dim=-1, keepdim=True)
|
||||
noise_pred = comb_pred * (cond_norm / noise_norm)
|
||||
latents = self.scheduler.step(noise_pred, t, latents, return_dict=False)[0]
|
||||
cfg_group.broadcast(latents, src=0)
|
||||
|
||||
else:
|
||||
# Forward pass for positive prompt (or unconditional if no CFG)
|
||||
noise_pred = self.transformer(
|
||||
hidden_states=latents,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=negative_prompt_embeds_mask,
|
||||
encoder_hidden_states=negative_prompt_embeds,
|
||||
encoder_hidden_states_mask=prompt_embeds_mask,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=negative_txt_seq_lens,
|
||||
txt_seq_lens=txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
comb_pred = neg_noise_pred + true_cfg_scale * (noise_pred - neg_noise_pred)
|
||||
cond_norm = torch.norm(noise_pred, dim=-1, keepdim=True)
|
||||
noise_norm = torch.norm(comb_pred, dim=-1, keepdim=True)
|
||||
noise_pred = comb_pred * (cond_norm / noise_norm)
|
||||
# compute the previous noisy sample x_t -> x_t-1
|
||||
latents = self.scheduler.step(noise_pred, t, latents, return_dict=False)[0]
|
||||
# Forward pass for negative prompt (CFG)
|
||||
if do_true_cfg:
|
||||
neg_noise_pred = self.transformer(
|
||||
hidden_states=latents,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=negative_prompt_embeds_mask,
|
||||
encoder_hidden_states=negative_prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=negative_txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
comb_pred = neg_noise_pred + true_cfg_scale * (noise_pred - neg_noise_pred)
|
||||
cond_norm = torch.norm(noise_pred, dim=-1, keepdim=True)
|
||||
noise_norm = torch.norm(comb_pred, dim=-1, keepdim=True)
|
||||
noise_pred = comb_pred * (cond_norm / noise_norm)
|
||||
# compute the previous noisy sample x_t -> x_t-1
|
||||
latents = self.scheduler.step(noise_pred, t, latents, return_dict=False)[0]
|
||||
return latents
|
||||
|
||||
def forward(
|
||||
|
||||
@@ -25,13 +25,20 @@ from transformers import Qwen2_5_VLForConditionalGeneration, Qwen2Tokenizer, Qwe
|
||||
from vllm.model_executor.models.utils import AutoWeightsLoader
|
||||
|
||||
from vllm_omni.diffusion.data import DiffusionOutput, OmniDiffusionConfig
|
||||
from vllm_omni.diffusion.distributed.parallel_state import (
|
||||
get_cfg_group,
|
||||
get_classifier_free_guidance_rank,
|
||||
get_classifier_free_guidance_world_size,
|
||||
)
|
||||
from vllm_omni.diffusion.distributed.utils import get_local_device
|
||||
from vllm_omni.diffusion.model_loader.diffusers_loader import DiffusersPipelineLoader
|
||||
from vllm_omni.diffusion.models.interface import SupportImageInput
|
||||
from vllm_omni.diffusion.models.qwen_image.pipeline_qwen_image import calculate_shift
|
||||
from vllm_omni.diffusion.models.qwen_image.qwen_image_transformer import (
|
||||
QwenImageTransformer2DModel,
|
||||
)
|
||||
from vllm_omni.diffusion.request import OmniDiffusionRequest
|
||||
from vllm_omni.diffusion.utils.tf_utils import get_transformer_config_kwargs
|
||||
from vllm_omni.model_executor.model_loader.weight_utils import (
|
||||
download_weights_from_hf_specific,
|
||||
)
|
||||
@@ -190,6 +197,7 @@ def retrieve_latents(
|
||||
|
||||
class QwenImageEditPipeline(
|
||||
nn.Module,
|
||||
SupportImageInput,
|
||||
):
|
||||
def __init__(
|
||||
self,
|
||||
@@ -224,7 +232,8 @@ class QwenImageEditPipeline(
|
||||
self.vae = AutoencoderKLQwenImage.from_pretrained(model, subfolder="vae", local_files_only=local_files_only).to(
|
||||
self.device
|
||||
)
|
||||
self.transformer = QwenImageTransformer2DModel(od_config=od_config)
|
||||
transformer_kwargs = get_transformer_config_kwargs(od_config.tf_model_config, QwenImageTransformer2DModel)
|
||||
self.transformer = QwenImageTransformer2DModel(od_config=od_config, **transformer_kwargs)
|
||||
self.tokenizer = Qwen2Tokenizer.from_pretrained(model, subfolder="tokenizer", local_files_only=local_files_only)
|
||||
self.processor = Qwen2VLProcessor.from_pretrained(
|
||||
model, subfolder="processor", local_files_only=local_files_only
|
||||
@@ -602,40 +611,85 @@ class QwenImageEditPipeline(
|
||||
latent_model_input = torch.cat([latents, image_latents], dim=1)
|
||||
|
||||
self.transformer.do_true_cfg = do_true_cfg # used in teacache hook
|
||||
# Forward pass for positive prompt (or unconditional if no CFG)
|
||||
noise_pred = self.transformer(
|
||||
hidden_states=latent_model_input,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=prompt_embeds_mask,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
noise_pred = noise_pred[:, : latents.size(1)]
|
||||
cfg_parallel_ready = do_true_cfg and get_classifier_free_guidance_world_size() > 1
|
||||
|
||||
# Forward pass for negative prompt (CFG)
|
||||
if do_true_cfg:
|
||||
neg_noise_pred = self.transformer(
|
||||
if cfg_parallel_ready:
|
||||
cfg_group = get_cfg_group()
|
||||
cfg_rank = get_classifier_free_guidance_rank()
|
||||
|
||||
if cfg_rank == 0:
|
||||
local_pred = self.transformer(
|
||||
hidden_states=latent_model_input,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=prompt_embeds_mask,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
else:
|
||||
local_pred = self.transformer(
|
||||
hidden_states=latent_model_input,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=negative_prompt_embeds_mask,
|
||||
encoder_hidden_states=negative_prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=negative_txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
|
||||
local_pred = local_pred[:, : latents.size(1)]
|
||||
|
||||
gathered = cfg_group.all_gather(local_pred, separate_tensors=True)
|
||||
if cfg_rank == 0:
|
||||
noise_pred = gathered[0]
|
||||
neg_noise_pred = gathered[1]
|
||||
comb_pred = neg_noise_pred + true_cfg_scale * (noise_pred - neg_noise_pred)
|
||||
cond_norm = torch.norm(noise_pred, dim=-1, keepdim=True)
|
||||
noise_norm = torch.norm(comb_pred, dim=-1, keepdim=True)
|
||||
noise_pred = comb_pred * (cond_norm / noise_norm)
|
||||
latents = self.scheduler.step(noise_pred, t, latents, return_dict=False)[0]
|
||||
cfg_group.broadcast(latents, src=0)
|
||||
|
||||
else:
|
||||
# Forward pass for positive prompt (or unconditional if no CFG)
|
||||
noise_pred = self.transformer(
|
||||
hidden_states=latent_model_input,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=negative_prompt_embeds_mask,
|
||||
encoder_hidden_states=negative_prompt_embeds,
|
||||
encoder_hidden_states_mask=prompt_embeds_mask,
|
||||
encoder_hidden_states=prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=negative_txt_seq_lens,
|
||||
txt_seq_lens=txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
neg_noise_pred = neg_noise_pred[:, : latents.size(1)]
|
||||
comb_pred = neg_noise_pred + true_cfg_scale * (noise_pred - neg_noise_pred)
|
||||
cond_norm = torch.norm(noise_pred, dim=-1, keepdim=True)
|
||||
noise_norm = torch.norm(comb_pred, dim=-1, keepdim=True)
|
||||
noise_pred = comb_pred * (cond_norm / noise_norm)
|
||||
# compute the previous noisy sample x_t -> x_t-1
|
||||
latents = self.scheduler.step(noise_pred, t, latents, return_dict=False)[0]
|
||||
noise_pred = noise_pred[:, : latents.size(1)]
|
||||
|
||||
# Forward pass for negative prompt (CFG)
|
||||
if do_true_cfg:
|
||||
neg_noise_pred = self.transformer(
|
||||
hidden_states=latent_model_input,
|
||||
timestep=timestep / 1000,
|
||||
guidance=guidance,
|
||||
encoder_hidden_states_mask=negative_prompt_embeds_mask,
|
||||
encoder_hidden_states=negative_prompt_embeds,
|
||||
img_shapes=img_shapes,
|
||||
txt_seq_lens=negative_txt_seq_lens,
|
||||
attention_kwargs=self.attention_kwargs,
|
||||
return_dict=False,
|
||||
)[0]
|
||||
neg_noise_pred = neg_noise_pred[:, : latents.size(1)]
|
||||
comb_pred = neg_noise_pred + true_cfg_scale * (noise_pred - neg_noise_pred)
|
||||
cond_norm = torch.norm(noise_pred, dim=-1, keepdim=True)
|
||||
noise_norm = torch.norm(comb_pred, dim=-1, keepdim=True)
|
||||
noise_pred = comb_pred * (cond_norm / noise_norm)
|
||||
# compute the previous noisy sample x_t -> x_t-1
|
||||
latents = self.scheduler.step(noise_pred, t, latents, return_dict=False)[0]
|
||||
return latents
|
||||
|
||||
def forward(
|
||||
|
||||
Loaded 100 of 147 files, more files were not shown because too many files have changed in this diff.
Show more
Reference in new issue
Block a user