# Architecture Overview
This document outlines the architecture of vLLM-Omni.
## Design goals
The primary goal of vLLM-Omni is to provide a fast and easy-to-use inference
and serving engine for omni-modality models. vLLM-Omni extends vLLM's
text-oriented autoregressive (AR) runtime with stage-based execution for
non-textual outputs and non-autoregressive model components.
The architecture is designed to:
* support text, image, audio, video, and action inputs and outputs;
* compose autoregressive, generation, and diffusion stages in one pipeline;
* reuse vLLM scheduling, cache, distributed-execution, and serving
primitives where they fit; and
* keep model topology, deployment placement, runtime lifecycle, transport,
and public API concerns in separate layers.
## Model execution topologies
vLLM-Omni is not limited to one model graph. A registered `PipelineConfig`
defines the stages and their relationships, while `DeployConfig` supplies the
placement and runtime choices for a particular deployment.
| Topology | Representative examples | Runtime shape |
| --- | --- | --- |
| AR plus downstream generation or diffusion | Qwen3-Omni, Qwen3-TTS, MiniCPM-o 4.5 | An AR stage produces text, codes, or conditioning for one or more downstream stages. |
| Diffusion-first generation | Qwen-Image, FLUX, HunyuanImage3, Cosmos3, Krea 2 | A diffusion stage owns denoising and may use an auxiliary text or multimodal encoder. |
| Joint multimodal generation | MiniMax H3, LTX-2 | A pipeline combines multiple model components to produce synchronized or multimodal artifacts such as video and audio. |
| Stateful or full-duplex interaction | MiniCPM-o 4.5 and experimental world-model paths | The runtime keeps session-scoped state and supports streaming, cancellation, or incremental input. |
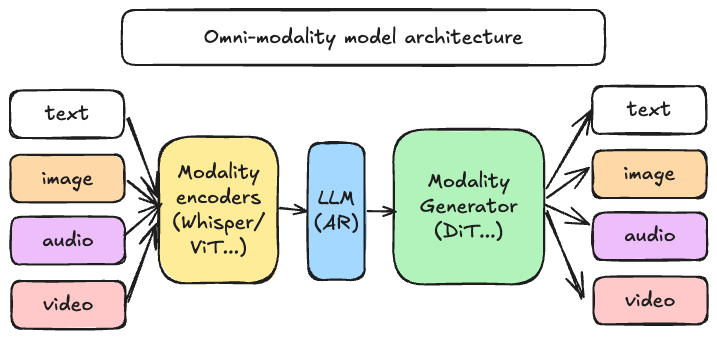
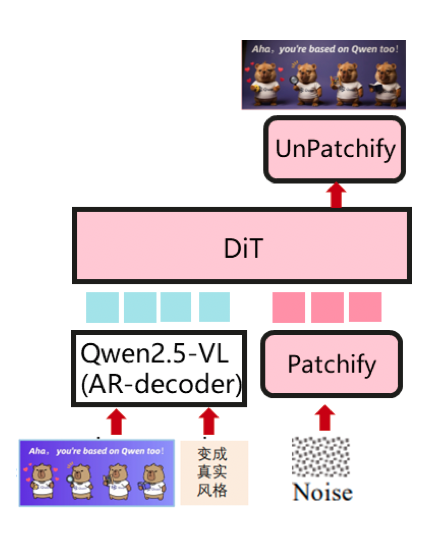
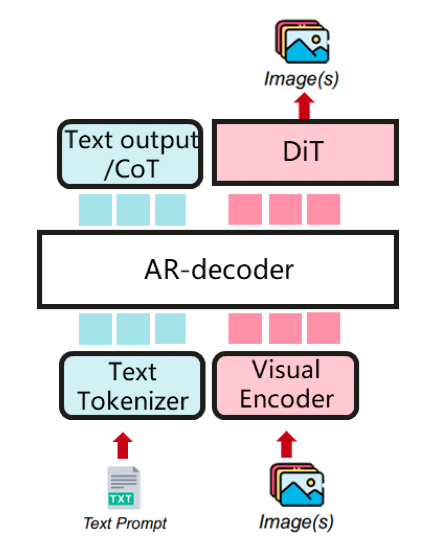
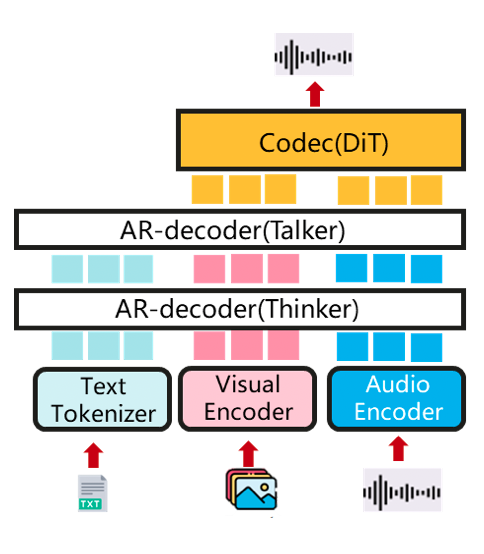
The following illustrations show common model-level arrangements. They are
examples of model topology, not constraints on the runtime.
### DiT as the main structure, with AR as an encoder
For example, Qwen-Image uses an AR or text-encoding component to condition a
diffusion transformer.
### AR as the main structure, with a diffusion generator
For example, BAGEL uses an AR model for multimodal understanding and text
reasoning, with a diffusion component for visual generation.
### AR and DiT in one multimodal pipeline
For example, Qwen-Omni combines multimodal encoders, an AR language model,
and a modality generator.
## System architecture
The runtime is organized around an engine, an orchestrator, stage lifecycle
management, and independent AR and diffusion stage implementations.
```mermaid
flowchart TB
entry["Entrypoints Omni / AsyncOmni / CLI / OpenAI-compatible APIs / duplex WebSocket"]
engine["AsyncOmniEngine engine composition root and background loop"]
orchestrator["Orchestrator request state, cross-stage routing, correlation, and output ordering"]
runtime["StageRuntime or DistStageRuntime placement, replicas, readiness, and lifecycle"]
clients["StagePool and stage clients StageEngineCoreClient / StageDiffusionClient"]
ar["AR stages vLLM engine, scheduler, worker, and model runner"]
diffusion["Diffusion stages DiffusionEngine, scheduler, executor, worker, and pipeline"]
connector["OmniConnector payload and KV transport plus synchronization"]
outputs["MultimodalPayload and OmniRequestOutput tensors, metadata, streaming chunks, and final artifacts"]
entry --> engine
engine --> orchestrator
engine --> runtime
runtime --> clients
clients --> ar
clients --> diffusion
ar <--> connector
diffusion <--> connector
ar --> outputs
diffusion --> outputs
outputs --> entry
```
### Key components
| Component | Responsibility |
| --- | --- |
| **Entrypoints** | Translate offline, CLI, OpenAI-compatible, and duplex requests into engine operations and render outputs back to public protocols. |
| **Configuration resolution** | Combines pipeline topology, deployment settings, model metadata, and user overrides into a validated control-plane configuration. |
| **AsyncOmniEngine** | Owns engine composition, the background event loop, stage initialization, request submission, and output collection. |
| **Orchestrator** | Owns cross-stage request state, stage-to-stage routing, companion tracking, correlation, cancellation, and output ordering. It does not own model selection or deployment placement. |
| **StageRuntime** | Expands logical stages into local or distributed replicas, starts stage clients and processes, and manages readiness, affinity, failure, and shutdown. |
| **AR runtime** | Extends vLLM's scheduler, KV-cache, worker, and model-runner path for omni-modality inputs and inter-stage outputs. |
| **Diffusion runtime** | Schedules and executes denoising workloads through diffusion executors, workers, pipelines, acceleration backends, and output materialization. |
| **OmniConnector** | Transports stage payloads and KV-cache data and provides synchronization. Connectors transport data; they do not choose the next logical stage. |
| **Multimodal outputs** | `MultimodalPayload` separates tensor content from metadata, while `OmniRequestOutput` carries pipeline and diffusion results through the common output path. |
## Configuration and runtime resolution
The control plane has five conceptual layers. Authoring inputs are resolved
once into a complete, transport-safe configuration before runtime processes are
started. This keeps stage topology and model capabilities distinct from
deployment placement and from process-local engine objects.
The figure shows only the primary hand-off object for each layer; the detailed
inputs, fields, and ownership rules are described below.
```mermaid
flowchart TB
layer1["Layer 1 · Authoring inputs PipelineConfig + DeployConfig"]
layer2["Layer 2 · Resolve once OmniConfigResolveRequest resolve_omni_config()"]
layer3["Layer 3 · Transport-safe control plane VllmOmniConfig"]
layer4["Layer 4 · Runtime launch planning StageRuntime"]
layer5["Layer 5 · Engine materialization VllmConfig / OmniDiffusionConfig"]
layer1 --> layer2 --> layer3 --> layer4 --> layer5
```
The resolver names in this diagram describe the intended single resolution
boundary. In the current implementation, the corresponding path is carried
out by `StageConfigFactory.create_from_model()` and
`VllmOmniConfig.from_pipeline_config()` in
[`vllm_omni/config`](https://github.com/vllm-project/vllm-omni/tree/main/vllm_omni/config).
The legacy `stage_args` YAML path remains only for models that have not yet
migrated to `PipelineConfig` and `DeployConfig`.
In the typed path, the common `VllmOmniStageConfig` slot in the
diagram is realized by `VllmOmniARStageConfig`,
`VllmOmniGenerationStageConfig`, or `VllmOmniDiffusionStageConfig`. The
request and engine-spec fields belong to the control-plane boundary; the
current implementation stores their equivalent projections in the structured
stage configuration and materializes backend-specific engine objects during
stage initialization.
The important ownership rules are:
1. `PipelineConfig` is the source of truth for stage topology, execution type,
model capabilities, and stage relationships.
2. `DeployConfig` describes placement, replicas, devices, connectors, and
deploy-time defaults; it does not redefine the model graph.
3. CLI and Python overrides are applied at the resolution boundary, with
per-stage overrides taking precedence over global values where supported.
4. `StageRuntime` owns launch planning and replica lifecycle. `ReplicaInitPlan`
is runtime-private state, not a user configuration object.
5. `VllmConfig` and the enriched `OmniDiffusionConfig` are materialized in the
process that owns the corresponding engine.
## Main features
The feature surface is grouped to match the
[feature design documents](index.md#feature-design-documents). This page
summarizes each feature's architectural role; the linked design document is
the source for configuration, compatibility, and implementation details.
### Runtime and stage execution
* **Disaggregated inference:** Logical stages can run in separate processes,
devices, or nodes while the orchestrator preserves their declared
relationships. `OmniConnector` implementations transfer stage data and
control-plane metadata. See [Disaggregated Inference](feature/disaggregated_inference.md).
* **Asynchronous stage and output execution:** [Async Chunk](feature/async_chunk.md)
forwards partial stage outputs as they become available. [Async Diffusion
Output](feature/async_diffusion_output.md) overlaps device-to-host output
packing with the next diffusion request, while [Async Omni Output
Materialization](feature/omni_async_output_materialization.md) moves
CPU-side payload construction off the AR decode critical path.
* **Automatic prefix caching:** [Automatic Prefix Caching in Omni Models](feature/prefix_caching.md)
reuses KV-cache-aligned stage outputs and multimodal tensors for requests
with common prefixes.
### Communication
* **OmniConnector transport:** The connector contract carries tensors, KV-cache
data, and transport metadata across stage boundaries. The available
implementations cover shared memory and multi-node Mooncake, Mori, and
Yuanrong transports; see [Disaggregated Inference](feature/disaggregated_inference.md)
for the connector choices and configuration model.
### Diffusion acceleration
* **Request and step batching:** [Diffusion Continuous Batching](feature/diffusion_continuous_batching.md)
defines request-batch and step-batch execution, scheduler admission, and the
common streaming output path.
* **Composable parallelism:** Diffusion stages can combine [CFG-Parallel](feature/cfg_parallel.md),
[Expert Parallel](feature/expert_parallel.md), [HSDP](feature/hsdp.md),
[Pipeline Parallel](feature/pipeline_parallel.md), [Sequence Parallel](feature/sequence_parallel.md),
[Tensor Parallel](feature/tensor_parallel.md), and [VAE Patch Parallelism](feature/vae_parallel.md)
according to the pipeline and hardware topology.
* **Attention and cache acceleration:** [Skip-Softmax](feature/skip_softmax.md),
[Cache-DiT](feature/cache_dit.md), and [TeaCache](feature/teacache.md)
provide backend and denoising-step optimizations without changing the
stage contract.
* **Quantization and memory efficiency:** [Quantization](feature/quantization.md)
resolves per-pipeline or per-component quantization configurations, while
[Distributed Layerwise Offload](feature/distributed_layerwise_offload.md)
streams diffusion blocks from host memory within the existing parallel
topology.
## Interfaces
The public interfaces map onto the same engine and stage boundaries:
```mermaid
flowchart LR
offline["Offline Python Omni.generate()"] --> engine["AsyncOmniEngine"]
online["OpenAI-compatible serving vllm serve ... --omni"] --> engine
duplex["Experimental duplex WebSocket /v1/duplex or realtime duplex"] --> engine
engine --> stages["Configured AR and diffusion stages"]
stages --> result["Streaming or final multimodal output"]
```
### Offline inference
The **Omni** class provides a Python interface for offline batched inference:
```python
from vllm_omni.entrypoints.omni import Omni
omni = Omni(model="Qwen/Qwen3-Omni-30B-A3B-Instruct")
om_inputs = {
"prompt": prompt,
"multi_modal_data": {
"video": video_frames,
"audio": audio_signal,
},
}
outputs = omni.generate(om_inputs, sampling_params_list)
```
### Online serving
The OpenAI-compatible server uses the same stage configuration and engine
boundaries:
```bash
vllm serve Qwen/Qwen3-Omni-30B-A3B-Instruct --omni --port 8091
```
For example, a Qwen3-Omni chat request can contain text, image, audio, or
video content and a `sampling_params_list` for its configured stages. See the
[Qwen3-Omni serving example](../user_guide/examples/online_serving/qwen3_omni.md)
and the [examples](https://github.com/vllm-project/vllm-omni/tree/main/examples)
for complete requests.
Some pipelines expose additional OpenAI-compatible endpoints, such as joint
video/audio generation. Endpoint support remains model-specific; consult the
relevant model guide before assuming that every OpenAI route applies to every
pipeline.