+
+
+### Key Components
+
+1. **OmniConnector**: Inter-stage data transport only
+ - Shared memory or other IPC mechanisms
+ - **Transport-only API**: `put(from_stage, to_stage, put_key, data)` and `get(from_stage, to_stage, get_key)` (optionally with timeout)
+ - **No request-specific state**: Connector does not track put_requests, get_requests, request_payload, finished_requests, or other request-bound metadata; it only performs put/get operations
+ - Chunk keys and request/chunk lifecycle are managed by **OmniChunkTransferAdapter**
+
+2. **Transfer Adapter Layer**: Extensible abstraction for managing data transfer via connectors
+ - **OmniTransferAdapterBase**: Base class with background **recv_loop** and **save_loop** threads;
+ - **OmniChunkTransferAdapter**: Chunk-specific implementation that owns the full chunk lifecycle when async_chunk is enabled
+ - **Chunk ID and key construction**: Builds keys like `{req_id}_{stage_id}_{chunk_id}` for put/get
+ - **Async get**: `load_async(request)` enqueues the request; background **recv_loop** polls the connector (non-blocking); when data is available, updates the request and marks it in `_finished_load_reqs`; scheduler calls `get_finished_requests()` to learn which requests have chunks ready
+ - **Async put**: `save_async(pooling_output, request)` invokes `custom_process_next_stage_input_func` in the main thread to build the payload, then enqueues a save task; background **save_loop** performs `connector.put()`; payload processing and chunk accumulation (e.g. code2wav chunk_size) remain in the main thread
+
+3. **Stage Input Processors**: Custom functions that process stage outputs into chunks for different models
+ - Receive **transfer_manager** (OmniChunkTransferAdapter)
+ - Qwen3-omni reference: `thinker2talker_async_chunk`, `talker2code2wav_async_chunk`
+
+4. **Schedulers**: Modified to handle chunk-based scheduling with async IO-compute overlap
+ - `OmniARScheduler`: For autoregressive stages
+ - `OmniGenerationScheduler`: For generation stages
+ - Both schedulers use **OmniChunkTransferAdapter** and **before/after** hooks around `super().schedule()`:
+ - **Before** `super().schedule()`: `process_pending_chunks(waiting, running)` moves requests waiting for chunks to `WAITING_FOR_CHUNK`, enqueues load tasks for background polling
+ - **After** `super().schedule()`: `restore_queues(waiting, running)` restores requests with ready chunks back to waiting/running, `postprocess_scheduler_output(scheduler_output)` attaches cached additional_information, clears chunk-ready flags
+ - **put_chunk** `save_async(pooler_output, request)`; **get_chunk** / **get_chunk_for_generation** `load_async(request)`
+
+5. **Model Runners**: Handle chunk processing
+ - `OmniGPUModelRunner`: Processes chunks in AR stages
+ - `GPUGenerationModelRunner`: Processes chunks in generation stages
+ - Uses `ubatch_slices` from `get_forward_context()` to track per-request sequence lengths in batched inference
+ - Reuses `ubatch_slices_padded` for code2wav batching to properly split batch outputs
+ - Handles list-type multimodal outputs: iterates through requests and assigns corresponding tensor to each
+ - Improved request state management: removes unscheduled and finished requests from input batch
+
+6. **Model Implementation**: Model-specific chunk handling
+ - `Qwen3OmniMoeForConditionalGeneration`: Main model with async_chunk support
+ - **Code2Wav stage batching**: Uses `ubatch_slices` to construct batched codec codes tensor `[batch_size, 16, max_seq_len]`
+ - **Batch output handling**: `generate_audio()` returns `list[torch.Tensor]`, one audio tensor per request
+ - **Multimodal outputs**: Returns list of audio tensors for batch processing instead of single concatenated tensor
+ - `Qwen3OmniCode2WavDecoder`: Audio generation model
+ - `chunked_decode()` and `chunked_decode_streaming()`: Return `list[torch.Tensor]` (one per request)
+ - Uses `ubatch_slices` to split batched waveform output into per-request audio chunks
+ - Each request gets correctly sized audio based on its code sequence length: `waveform[:, :, :code_seq_len * total_upsample]`
+
+7. **Request status**: `RequestStatus.WAITING_FOR_CHUNK` is added via patch (e.g. in `vllm_omni/patch.py`) so requests waiting for a chunk are not scheduled by the base vLLM scheduler until the chunk is ready.
+
+## Configuration
+
+Enable async_chunk in stage configuration YAML:
+
+```yaml
+async_chunk: true
+stage_args:
+ - stage_id: 0
+ engine_args:
+ custom_process_next_stage_input_func: vllm_omni.model_executor.stage_input_processors.qwen3_omni.thinker2talker_async_chunk
+ - stage_id: 1
+ engine_args:
+ custom_process_next_stage_input_func: vllm_omni.model_executor.stage_input_processors.qwen3_omni.talker2code2wav_async_chunk
+```
+
+### Stage Configuration
+
+- `async_chunk: bool`: Enable/disable async chunk mode
+- `custom_process_next_stage_input_func: str`: Path to custom chunk processing function; receives `(transfer_manager, pooling_output, request)`. For qwen3-omni: `thinker2talker_async_chunk`, `talker2code2wav_async_chunk`
+- `stage_connector_config: dict`: Connector configuration
+- `worker_type: str`: Model type, e.g. `"ar"` or `"generation"` (used by OmniChunkTransferAdapter for mode-specific payload handling)
+- `max_batch_size: int`: Maximum batch size for the stage
+
+
+### Connector Configuration
+
+```yaml
+connectors:
+ - from_stage: 0
+ to_stage: 1
+ spec:
+ name: SharedMemoryConnector
+ extra:
+ stage_id: 0
+```
+
+### Code2Wav Batch Configuration
+
+For optimal performance with async_chunk, the code2wav stage should be configured with batching:
+
+```yaml
+stage_args:
+ - stage_id: 2 # code2wav stage
+ runtime:
+ devices: "1"
+ max_batch_size: 64 # Enables batched audio generation
+ engine_args:
+ model_stage: code2wav
+```
+
+## Related Files
+
+- `vllm_omni/model_executor/stage_input_processors/qwen3_omni.py`: Chunk processing functions (receive `transfer_manager` as first param)
+- `vllm_omni/distributed/omni_connectors/transfer_adapter/base.py`: OmniTransferAdapterBase (recv_loop, save_loop, load_async, save_async)
+- `vllm_omni/distributed/omni_connectors/transfer_adapter/chunk_transfer_adapter.py`: OmniChunkTransferAdapter (process_pending_chunks, restore_queues, postprocess_scheduler_output)
+- `vllm_omni/distributed/omni_connectors/connectors/shm_connector.py`: SharedMemoryConnector (transport-only put/get)
+- `vllm_omni/core/sched/omni_ar_scheduler.py`: AR scheduler with chunk_transfer_adapter
+- `vllm_omni/core/sched/omni_generation_scheduler.py`: Generation scheduler with same async chunk pattern
+- `vllm_omni/worker/gpu_model_runner.py`: Model runner with chunk handling
+- `vllm_omni/worker/gpu_generation_model_runner.py`: Generation model runner with batch output handling and ubatch_slices support
+- `vllm_omni/model_executor/models/qwen3_omni/qwen3_omni.py`: Model implementation with code2wav batching
+- `vllm_omni/model_executor/models/qwen3_omni/qwen3_omni_code2wav.py`: Code2wav decoder with batch support
+- `vllm_omni/engine/arg_utils.py`: Configuration definitions (async_chunk, worker_type)
+- `vllm_omni/config/model.py`: Model config with async_chunk field
diff --git a/docs/source/architecture/async-chunk-architecture.png b/docs/source/architecture/async-chunk-architecture.png
new file mode 100644
index 000000000..249de53bf
Binary files /dev/null and b/docs/source/architecture/async-chunk-architecture.png differ
diff --git a/docs/source/architecture/qwen3-omni-async-chunk.png b/docs/source/architecture/qwen3-omni-async-chunk.png
new file mode 100644
index 000000000..b2d98b80f
Binary files /dev/null and b/docs/source/architecture/qwen3-omni-async-chunk.png differ
diff --git a/docs/source/architecture/qwen3-omni-non-async-chunk.png b/docs/source/architecture/qwen3-omni-non-async-chunk.png
new file mode 100644
index 000000000..da5610a11
Binary files /dev/null and b/docs/source/architecture/qwen3-omni-non-async-chunk.png differ
diff --git a/docs/source/performance/qwen3-omni_rtf_performance.png b/docs/source/performance/qwen3-omni_rtf_performance.png
new file mode 100644
index 000000000..5916c9420
Binary files /dev/null and b/docs/source/performance/qwen3-omni_rtf_performance.png differ
diff --git a/docs/source/performance/qwen3-omni_ttfp_performance.png b/docs/source/performance/qwen3-omni_ttfp_performance.png
new file mode 100644
index 000000000..f3d3de8c2
Binary files /dev/null and b/docs/source/performance/qwen3-omni_ttfp_performance.png differ
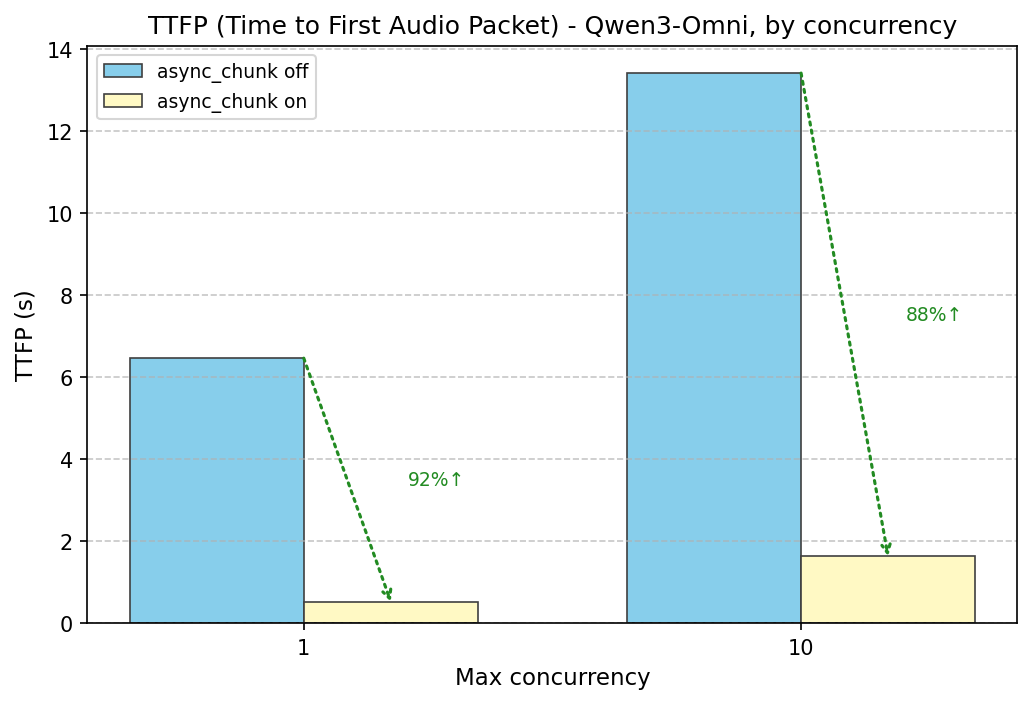 +
 +
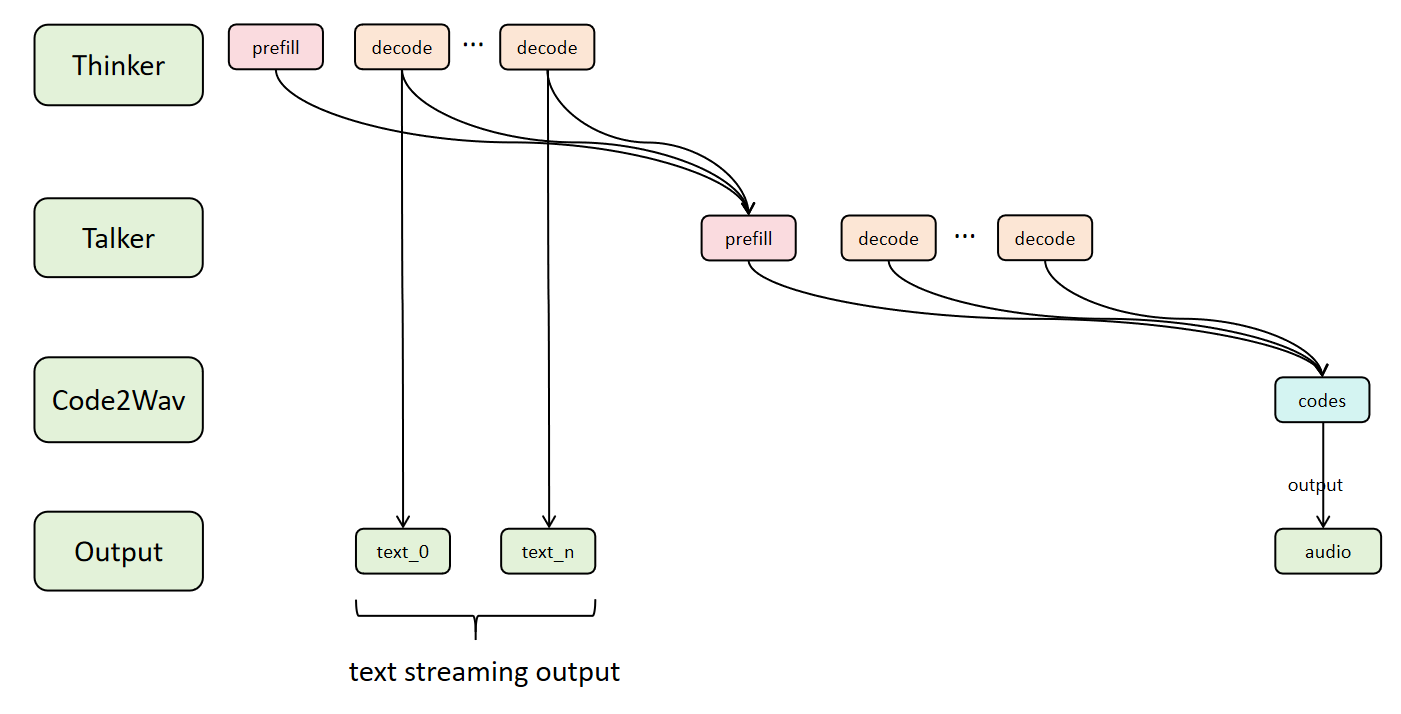 +
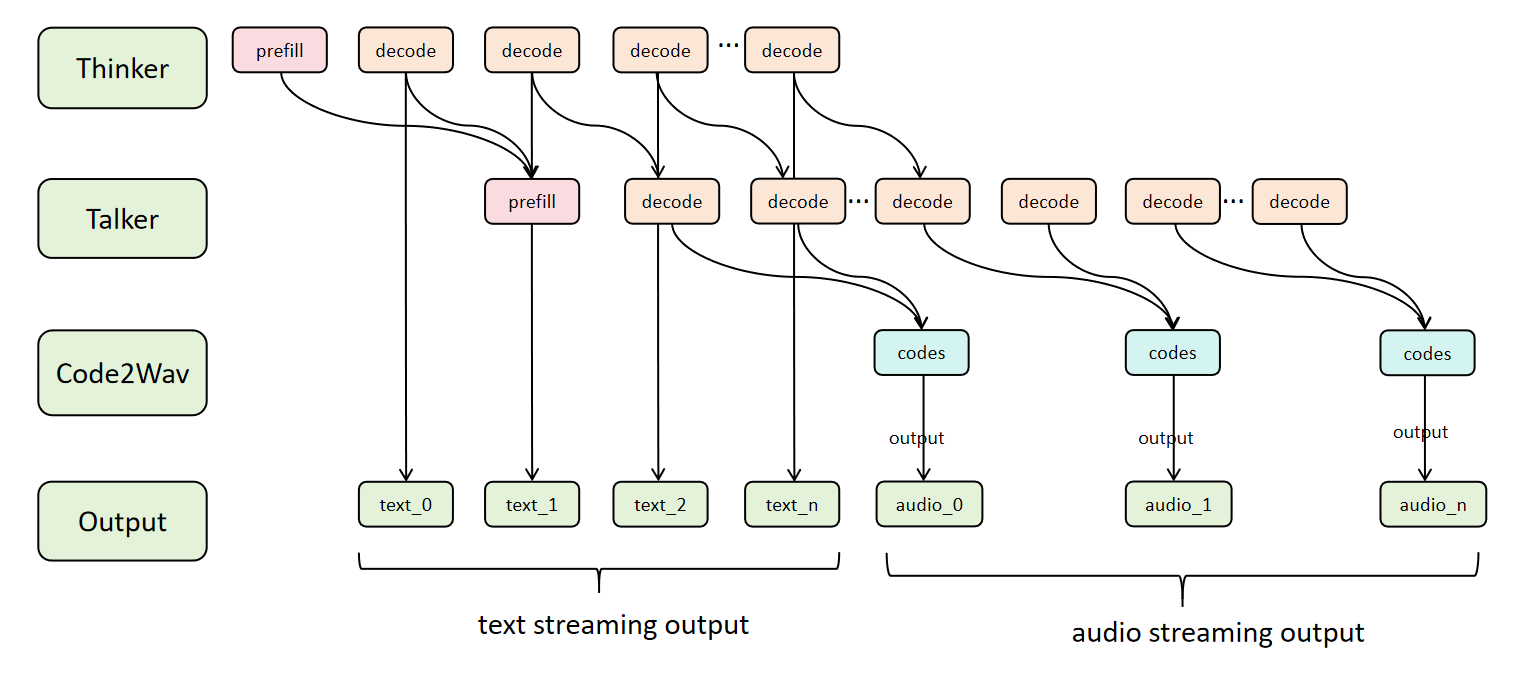 +
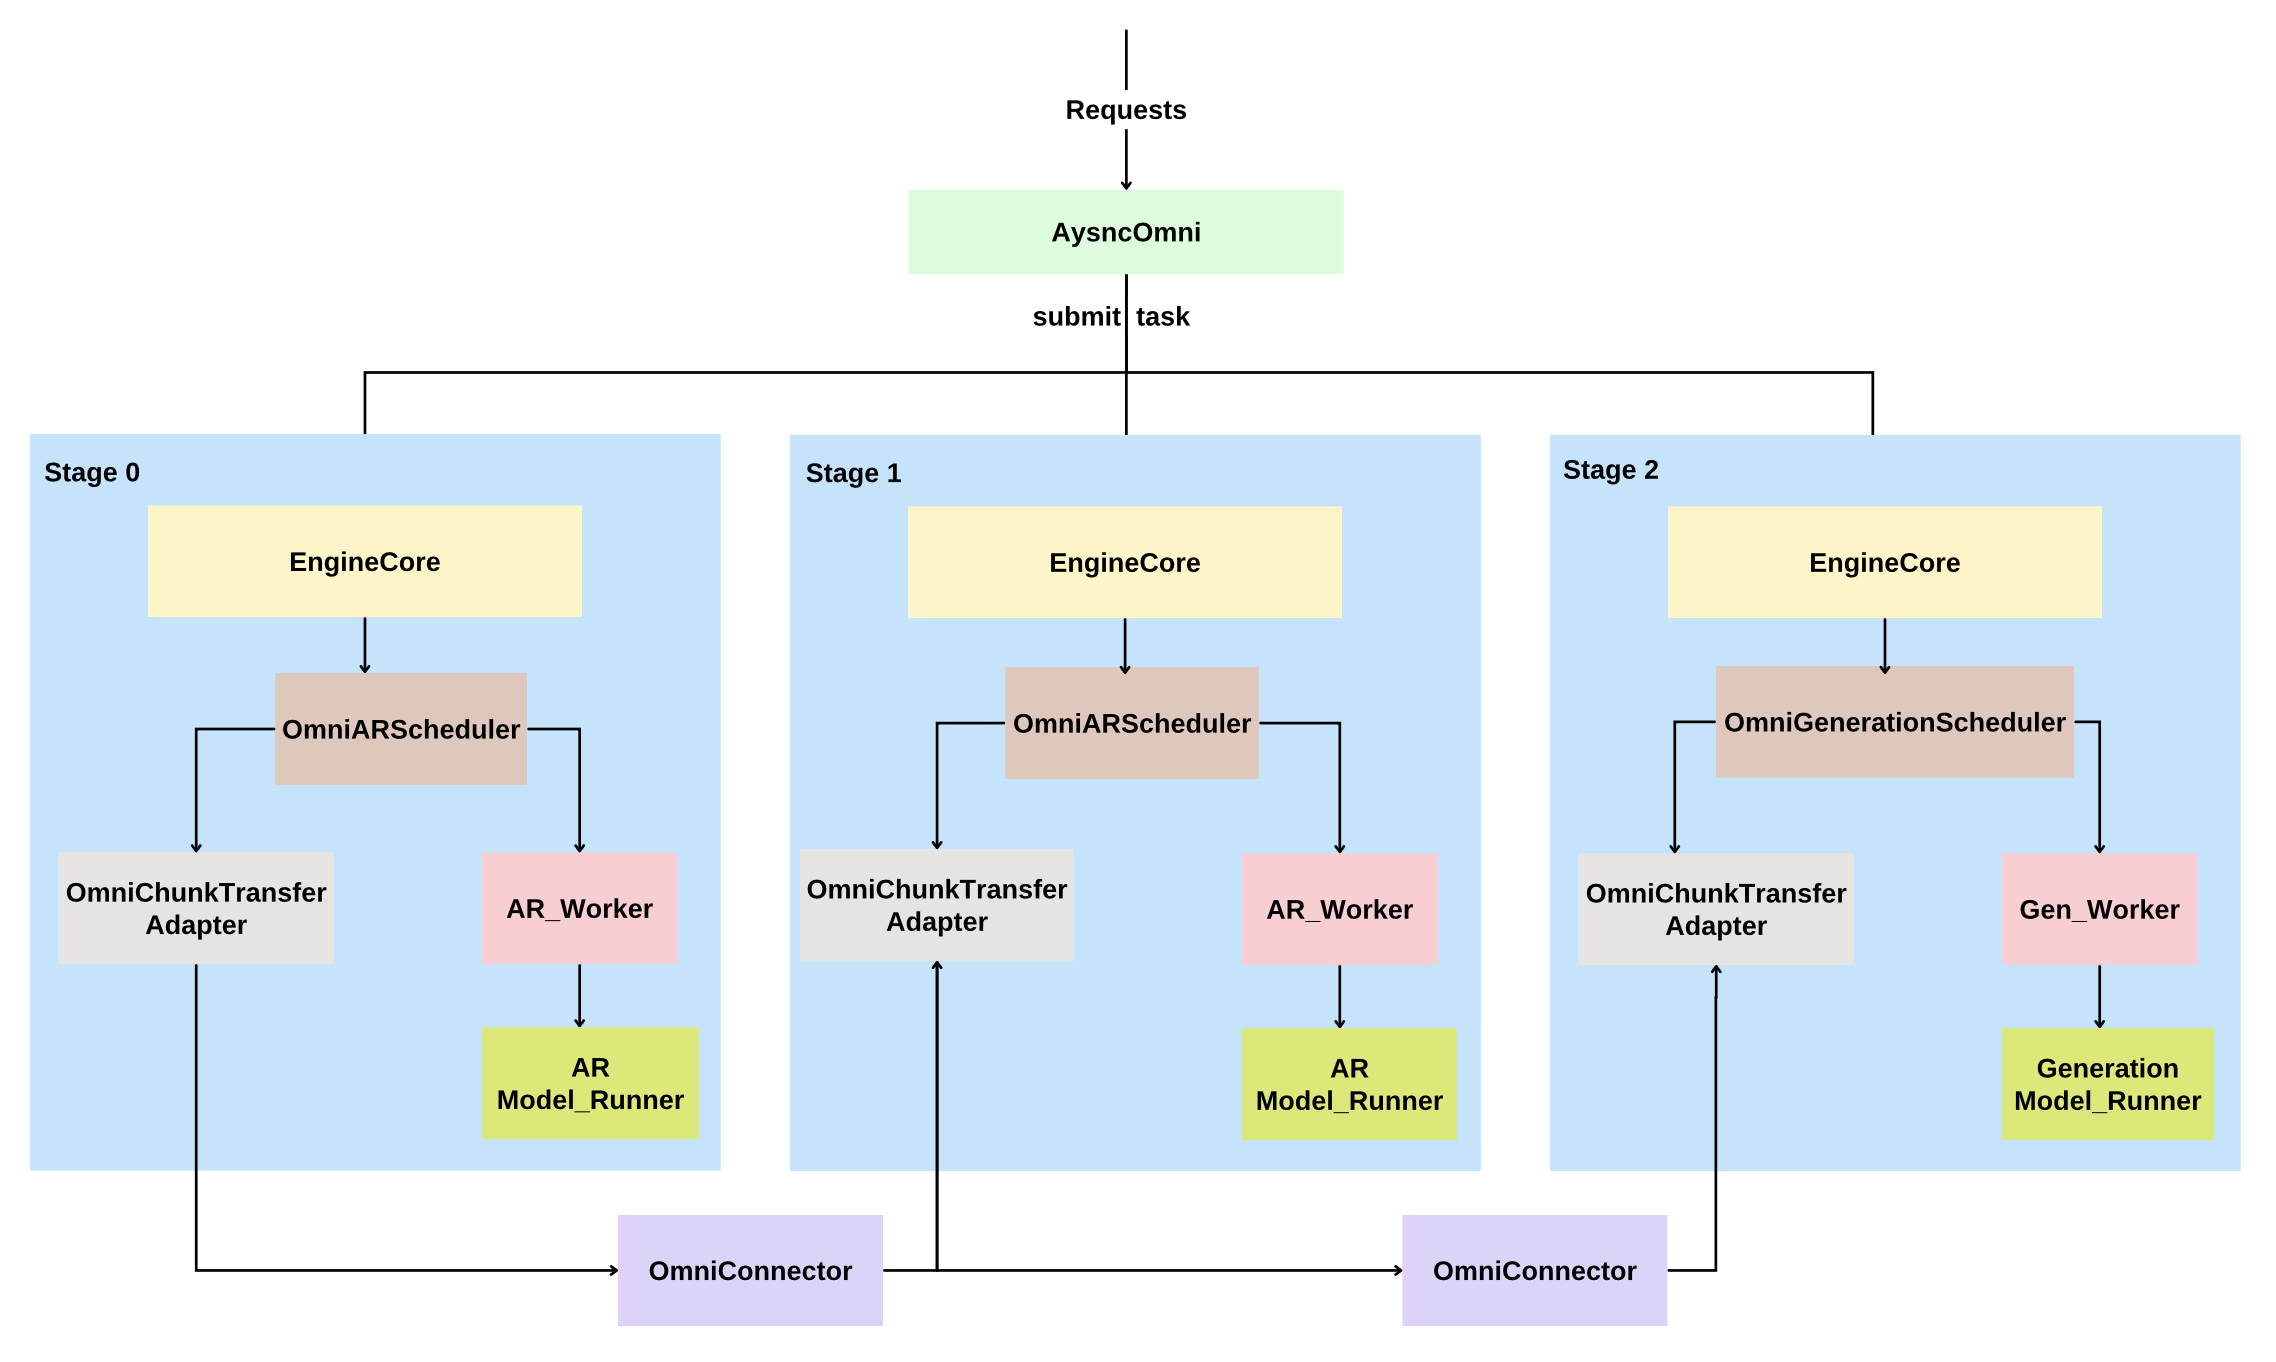 +