diff --git a/.github/workflows/build_wheel.yml b/.github/workflows/build_wheel.yml
index e84b399df..2d76c69b2 100644
--- a/.github/workflows/build_wheel.yml
+++ b/.github/workflows/build_wheel.yml
@@ -7,6 +7,7 @@ on:
paths-ignore:
- 'docs/**'
- 'examples/**'
+ - 'apps/**'
- '.github/**'
- '.buildkite/**'
- '**.md'
@@ -20,6 +21,7 @@ on:
paths-ignore:
- 'docs/**'
- 'examples/**'
+ - 'apps/**'
- '.github/**'
- '.buildkite/**'
- '*.yml'
diff --git a/.github/workflows/comfyui-publish.yml b/.github/workflows/comfyui-publish.yml
new file mode 100644
index 000000000..c282bcada
--- /dev/null
+++ b/.github/workflows/comfyui-publish.yml
@@ -0,0 +1,27 @@
+name: ComfyUI Integration -- Publish to Comfy registry
+on:
+ workflow_dispatch:
+ push:
+ tags:
+ - "*"
+ paths:
+ - "apps/ComfyUI-vLLM-Omni/**"
+
+permissions:
+ issues: write
+
+defaults:
+ run:
+ working-directory: apps/ComfyUI-vLLM-Omni
+
+jobs:
+ publish-node:
+ name: Publish Custom Node to registry
+ runs-on: ubuntu-latest
+ steps:
+ - name: ♻️ Check out code
+ uses: actions/checkout@v4
+ - name: 📦 Publish Custom Node
+ uses: Comfy-Org/publish-node-action@main
+ with:
+ personal_access_token: ${{ secrets.REGISTRY_ACCESS_TOKEN }}
diff --git a/.github/workflows/comfyui-validate.yml b/.github/workflows/comfyui-validate.yml
new file mode 100644
index 000000000..06b9b1f91
--- /dev/null
+++ b/.github/workflows/comfyui-validate.yml
@@ -0,0 +1,40 @@
+name: ComfyUI Integration -- Validate backwards compatibility
+
+on:
+ pull_request:
+ branches:
+ - master
+ - main
+ paths:
+ - "apps/ComfyUI-vLLM-Omni/**"
+
+defaults:
+ run:
+ working-directory: apps/ComfyUI-vLLM-Omni
+
+jobs:
+ check-base-path:
+ runs-on: ubuntu-latest
+ outputs:
+ exists: ${{ steps.check.outputs.exists }}
+ defaults:
+ run:
+ working-directory: .
+ steps:
+ - uses: actions/checkout@v4
+ with:
+ ref: ${{ github.event.pull_request.base.sha }}
+ fetch-depth: 1
+ - id: check
+ run: |
+ if [ -d "apps/ComfyUI-vLLM-Omni" ]; then
+ echo "exists=true" >> "$GITHUB_OUTPUT"
+ else
+ echo "exists=false" >> "$GITHUB_OUTPUT"
+ fi
+ validate:
+ needs: check-base-path
+ if: needs.check-base-path.outputs.exists == 'true'
+ runs-on: ubuntu-latest
+ steps:
+ - uses: comfy-org/node-diff@main
diff --git a/.gitignore b/.gitignore
index f7b771bc7..7b0a9c368 100644
--- a/.gitignore
+++ b/.gitignore
@@ -153,6 +153,14 @@ dmypy.json
# Cython debug symbols
cython_debug/
+# Claude
+CLAUDE.md
+.claude/
+
+# Codex
+AGENTS.md
+.codex/
+
# cursor
.cursor/
@@ -214,6 +222,7 @@ data/
datasets/
*.csv
*.json
+!apps/ComfyUI-vLLM-Omni/example_workflows/*.json
*.jsonl
*.parquet
diff --git a/apps/ComfyUI-vLLM-Omni/.gitignore b/apps/ComfyUI-vLLM-Omni/.gitignore
new file mode 100644
index 000000000..5704ad153
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/.gitignore
@@ -0,0 +1,115 @@
+# Byte-compiled / optimized / DLL files
+__pycache__/
+*.py[cod]
+*$py.class
+
+# OSX useful to ignore
+*.DS_Store
+.AppleDouble
+.LSOverride
+
+# Thumbnails
+._*
+
+# Files that might appear in the root of a volume
+.DocumentRevisions-V100
+.fseventsd
+.Spotlight-V100
+.TemporaryItems
+.Trashes
+.VolumeIcon.icns
+.com.apple.timemachine.donotpresent
+
+# Directories potentially created on remote AFP share
+.AppleDB
+.AppleDesktop
+Network Trash Folder
+Temporary Items
+.apdisk
+
+# C extensions
+*.so
+
+# Distribution / packaging
+.Python
+env/
+venv/
+build/
+develop-eggs/
+dist/
+downloads/
+eggs/
+.eggs/
+lib/
+lib64/
+parts/
+sdist/
+var/
+*.egg-info/
+.installed.cfg
+*.egg
+
+# PyInstaller
+# Usually these files are written by a python script from a template
+# before PyInstaller builds the exe, so as to inject date/other infos into it.
+*.manifest
+*.spec
+
+# Installer logs
+pip-log.txt
+pip-delete-this-directory.txt
+
+# Unit test / coverage reports
+htmlcov/
+.tox/
+.coverage
+.coverage.*
+.cache
+nosetests.xml
+coverage.xml
+*,cover
+.hypothesis/
+.pytest_cache/
+
+# Translations
+*.mo
+*.pot
+
+# Django stuff:
+*.log
+
+# Sphinx documentation
+docs/_build/
+
+# IntelliJ Idea
+.idea
+*.iml
+*.ipr
+*.iws
+
+# PyBuilder
+target/
+
+# Cookiecutter
+output/
+python_boilerplate/
+cookiecutter-pypackage-env/
+
+# vscode settings
+.history/
+*.code-workspace
+
+# Frontend extension
+node_modules/
+.env
+.env.local
+.env.development.local
+.env.test.local
+.env.production.local
+npm-debug.log*
+yarn-debug.log*
+yarn-error.log*
+node.zip
+.vscode/
+.claude/
+.codemate/
diff --git a/apps/ComfyUI-vLLM-Omni/LICENSE b/apps/ComfyUI-vLLM-Omni/LICENSE
new file mode 100644
index 000000000..b3c346397
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/LICENSE
@@ -0,0 +1,15 @@
+Apache Software License 2.0
+
+Copyright (c) 2026, Zeyu Huang
+
+Licensed under the Apache License, Version 2.0 (the "License");
+you may not use this file except in compliance with the License.
+You may obtain a copy of the License at
+
+http://www.apache.org/licenses/LICENSE-2.0
+
+Unless required by applicable law or agreed to in writing, software
+distributed under the License is distributed on an "AS IS" BASIS,
+WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied.
+See the License for the specific language governing permissions and
+limitations under the License.
diff --git a/apps/ComfyUI-vLLM-Omni/README.md b/apps/ComfyUI-vLLM-Omni/README.md
new file mode 100644
index 000000000..dd530174f
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/README.md
@@ -0,0 +1,170 @@
+# vLLM-Omni
+
+vLLM-Omni offers a ComfyUI integration on top of its online serving API.
+It can send model inference requests to either a locally running vLLM-Omni service or a remote one.
+
+## Requirement
+
+- Python 3.12 or above
+- [ComfyUI installed](https://docs.comfy.org/installation/system_requirements)
+- [vLLM-Omni installed](https://docs.vllm.ai/projects/vllm-omni/en/latest/getting_started/installation/) on either the same device or another device discoverable via the internet.
+- No need to install additional packages apart from those already required by ComfyUI.
+
+> [!TIP]
+> If you run both ComfyUI and vLLM-Omni on the same device, you can create separate virtual environments and use different Python versions for them.
+
+
+## Installation
+
+Copy this folder to the `custom_nodes` subfolder of your ComfyUI installation. Your directory should look like `ComfyUI/custom_nodes/ComfyUI-vLLM-Omni`.
+
+If you are running ComfyUI during copying, you should restart ComfyUI to load this extension.
+
+> [!TIP]
+> You can use utility websites such as https://download-directory.github.io/ to download a subdirectory of a repo. Also checkout community discussions (e.g., https://stackoverflow.com/questions/7106012/download-a-single-folder-or-directory-from-a-github-repository) for more info.
+
+On the device and virtual environment you run ComfyUI, launch ComfyUI with
+```bash
+cd ComfyUI
+
+# The regular way
+python main.py
+
+# If you are mainly using this node, launch it faster with
+python main.py --cpu
+```
+
+On the device and virtual environment you run vLLM-Omni, start a model service with
+```bash
+vllm serve The_Model_ID_to_Serve --omni --port 8000
+```
+
+Check **ComfyUI's sidebar -> Node Library**. There should be a new folder named **vLLM-Omni**.
+If no, check your shell running the ComfyUI process. There may be some error messages before the line `Import times for custom nodes:` and the line `To see the GUI go to: http://127.0.0.1:8188`.
+
+## Quickstart
+
+This extension offers the following nodes based on the output modalities (at **ComfyUI sidebar -> Node Library**):
+
+- **Generate Image** for text-to-image and image-to-image tasks
+- **Multimodality Comprehension** for multimodality-to-text and multimodality-to-audio tasks
+- **TTS** and **TTS Voice Clone** for TTS tasks
+
+This extension also offers example workflows (at **ComfyUI sidebar -> Templates -> vLLM-Omni**)
+
+> [!INFO]
+> The node UI and feature designs are intended to match vLLM-Omni online serving interfaces. It cannot offer more than what the interfaces support.
+
+To build a simple workflow yourself,
+
+- Drag a generation node onto the canvas.
+- Depending on your need, grab built-in multimedia file loader nodes, such as **image->Load Image**, **image->video->Load Video**, **audio->Load Audio**
+- Depending on your need, grab built-in multimedia file preview nodes, such as **image->Preview Image**, **image->video->Save Video**, **audio->Preview Audio**. For text output, you can install [ComfyUI-Custom-Scripts plugin](https://github.com/pythongosssss/ComfyUI-Custom-Scripts/) and grab its **utils->Show Text 🐍** node.
+- If you want to tune sampling parameters, grab corresponding nodes from **vLLM-Omni-> Sampling Params**.
+ - For multi-stage models, you can connect multiple **AR Sampling Params** and **Diffusion Sampling Params** nodes to a **Multi-Stage Sampling Params List** node, and connect this node to the generation node.
+ - For some multi-stage models like BAGEL, [only one stage's sampling parameters are exposed and tunable via vLLM-Omni's online serving API](https://docs.vllm.ai/projects/vllm-omni/en/latest/user_guide/examples/online_serving/bagel/). Thus, these models are treated as single-stage ones. Please check the vLLM-Omni documentation on how to correctly set each model's sampling parameters.
+ - For multi-stage models where all stages are either autoregression or diffusion, you can also connect only a single Sampling Params node, indicating that this set of sampling parameters will be used for all stages.
+
+**The following features are tested**:
+
+- Single-node workflows for
+ - Multimodal Comprehension (e.g., Qwen Omni, BAGEL)
+ - Text-to-Image Generation (e.g., Qwen-Image)
+ - Image-to-Image Generation (e.g., Qwen-Image-Edit)
+ - TTS (e.g., Qwen TTS, including VoiceDesign, VoiceClone, CustomVoice)
+
+**The following features are not currently tested**. They may work or break. You are welcomed to test it out and offer comments.
+
+- Multi-node workflow that connects multiple model services together.
+
+## Screenshots and Examples
+
+### Multimodal comprehension (e.g., Qwen Omni series, BAGEL)
+
+(Also available at **ComfyUI sidebar->Template->vLLM-Omni->vLLM-Omni Annotated Example**)
+
+
+
+
+
+
+
+
+> [!TIP]
+> Although this node enables all-modality input, you should check whether the specific model you host and request for supports the modalities you connect to the node.
+
+You can configure per-stage sampling parameters for multi-stage models.
+
+
+
+
+
+
+
+
+### Text-to-image and image-to-image generation (e.g., Z-Image-Turbo, Qwen-Image-Edit, BAGEL)
+
+(Also available at **ComfyUI sidebar->Template->vLLM-Omni->vLLM-Omni Image Generation**)
+
+
+
+
+
+
+
+
+> [!TIP]
+> The node automatically choose text-to-image or image-to-image API endpoints depending on whether you connect an image input or not.
+
+### TTS (e.g., Qwen TTS series)
+
+(Also available at **ComfyUI sidebar->Template->vLLM-Omni->vLLM-Omni TTS**)
+
+
+
+
+
+
+
+
+> [!TIP]
+> There is a dedicated node for VoiceClone tasks with reference audio input. Other simple text-to-speech tasks should use the regular TTS node.
+
+## Develop
+
+Follow the [development convention and rules of vLLM-Omni](https://docs.vllm.ai/projects/vllm-omni/en/latest/contributing/).
+
+## Limitation and Non-Goals
+
+- Single server mode only. No automatic load balancing or failover.
+- Features set is bounded to vLLM-Omni's online service capability, including
+ - The types of models supported in online mode,
+ - The types of sampling parameters supported in the online mode,
+ - The ways to send files (primarily through full-length base64 in JSON payload),
+ - Figuring out errors in the payload (such as unsupported fields by a specific model) if the endpoint does not explicitly return an error,
+ - (The lack of) Authentication
+ - (The lack of) Progress indicator
+
+## Support
+
+If you are new to ComfyUI, please check out [its documentation](https://docs.comfy.org/) for usage instructions.
+
+If you are new to vLLM-Omni, please also check out [its documentation](https://docs.vllm.ai/projects/vllm-omni/en/latest/) for usage instructions.
+
+Whenever you find an issue or problem, please
+
+- First find out if this is an upstream limitation of vLLM-Omni's online serving mode, by [checking their documentation](https://docs.vllm.ai/projects/vllm-omni/en/latest/examples/).
+- [Open an issue](https://github.com/vllm-project/vllm-omni/issues) that clearly describes this ComfyUI or online service problem.
+
+## Acknowledgements
+
+Features
+
+- https://github.com/dougbtv/comfyui-vllm-omni/ The official reference implementation for ComfyUI integration with vLLM-Omni's DALL-E compatible image generation API.
+- https://github.com/Comfy-Org/ComfyUI/tree/master/comfy_extras ComfyUI's built-in node implementations.
+
+UI/UX design references
+
+- https://github.com/sgl-project/sglang/pull/15271 SGLang Diffusion's official ComfyUI integration for image and video generation.
+- https://github.com/SXQBW/ComfyUI-Qwen-Omni A third party ComfyUI integration for Qwen Omni series.
+- https://github.com/flybirdxx/ComfyUI-Qwen-TTS https://github.com/DarioFT/ComfyUI-Qwen3-TTS Third party ComfyUI integrations for Qwen TTS series.
diff --git a/apps/ComfyUI-vLLM-Omni/__init__.py b/apps/ComfyUI-vLLM-Omni/__init__.py
new file mode 100644
index 000000000..ffb86ddb3
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/__init__.py
@@ -0,0 +1,52 @@
+"""Top-level package for comfyui_vllm_omni.""" # noqa: N999 # This is not a python library intended to be imported
+
+__all__ = [
+ "NODE_CLASS_MAPPINGS",
+ "NODE_DISPLAY_NAME_MAPPINGS",
+ "WEB_DIRECTORY",
+]
+
+__author__ = """Zeyu Huang"""
+__email__ = "11222265+fhfuih@users.noreply.github.com"
+__version__ = "0.0.1"
+
+from .comfyui_vllm_omni.nodes import (
+ VLLMOmniARSampling,
+ VLLMOmniComprehension,
+ VLLMOmniDiffusionSampling,
+ VLLMOmniGenerateImage,
+ VLLMOmniQwenTTSParams,
+ VLLMOmniSamplingParamsList,
+ VLLMOmniTTS,
+ VLLMOmniVoiceClone,
+)
+
+# A dictionary that contains all nodes you want to export with their names
+NODE_CLASS_MAPPINGS = {
+ # === Generation ===
+ "VLLMOmniGenerateImage": VLLMOmniGenerateImage,
+ "VLLMOmniComprehension": VLLMOmniComprehension,
+ "VLLMOmniTTS": VLLMOmniTTS,
+ "VLLMOmniVoiceClone": VLLMOmniVoiceClone,
+ # === Params ===
+ "VLLMOmniARSampling": VLLMOmniARSampling,
+ "VLLMOmniDiffusionSampling": VLLMOmniDiffusionSampling,
+ "VLLMOmniSamplingParamsList": VLLMOmniSamplingParamsList,
+ "VLLMOmniQwenTTSParams": VLLMOmniQwenTTSParams,
+}
+
+# A dictionary that contains the friendly/humanly readable titles for the nodes
+NODE_DISPLAY_NAME_MAPPINGS = {
+ # === Generation ===
+ "VLLMOmniGenerateImage": "Generate Image",
+ "VLLMOmniComprehension": "Multimodality Comprehension",
+ "VLLMOmniTTS": "TTS (Text to Speech)",
+ "VLLMOmniVoiceClone": "TTS Voice Cloning",
+ # === Params ===
+ "VLLMOmniARSampling": "AR Sampling Params",
+ "VLLMOmniDiffusionSampling": "Diffusion Sampling Params",
+ "VLLMOmniSamplingParamsList": "Multi-Stage Sampling Params List",
+ "VLLMOmniQwenTTSParams": "Qwen TTS Params",
+}
+
+WEB_DIRECTORY = "./web"
diff --git a/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/__init__.py b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/__init__.py
new file mode 100644
index 000000000..ebc9c5a59
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/__init__.py
@@ -0,0 +1 @@
+# noqa: N999 # This is not a python library intended to be imported
diff --git a/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/nodes.py b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/nodes.py
new file mode 100644
index 000000000..ebc2822df
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/nodes.py
@@ -0,0 +1,569 @@
+from typing import Literal, cast
+
+import torch
+from comfy_api.input import AudioInput, VideoInput
+
+from .utils.api_client import VLLMOmniClient
+from .utils.logger import get_logger
+from .utils.models import lookup_model_spec
+from .utils.types import AudioFormat
+from .utils.validators import (
+ add_sampling_parameters_to_stage,
+ validate_model_and_sampling_params_types,
+)
+
+logger = get_logger(__name__)
+
+
+class _VLLMOmniGenerateBase:
+ """Base class for vLLM-Omni generation nodes with shared functionality."""
+
+ CATEGORY = "vLLM-Omni"
+
+ @classmethod
+ def VALIDATE_INPUTS(cls, url, model) -> str | Literal[True]:
+ """
+ Can only validate this model's own input. Cannot check inputs from other nodes.
+ See: https://docs.comfy.org/custom-nodes/backend/server_overview#validate_inputs
+ """
+ if not url:
+ return "URL must not be empty"
+ if not model:
+ return "Model must not be empty"
+ return True
+
+
+class VLLMOmniGenerateImage(_VLLMOmniGenerateBase):
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "url": ("STRING", {"default": "http://localhost:8000/v1"}),
+ "model": ("STRING", {"default": "Tongyi-MAI/Z-Image-Turbo"}),
+ "prompt": ("STRING", {"multiline": True}),
+ "negative_prompt": ("STRING", {"multiline": True, "default": ""}),
+ "width": ("INT", {"default": 512, "min": 64, "max": 2048}),
+ "height": ("INT", {"default": 512, "min": 64, "max": 2048}),
+ },
+ "optional": {
+ "image": ("IMAGE",),
+ "mask": ("MASK",),
+ # "video": ("VIDEO",),
+ # "audio": ("AUDIO",),
+ "sampling_params": ("SAMPLING_PARAMS",),
+ },
+ }
+
+ RETURN_TYPES = ("IMAGE",)
+ RETURN_NAMES = ("image",)
+ FUNCTION = "generate"
+
+ async def generate(
+ self,
+ url: str,
+ model: str,
+ prompt: str,
+ width: int,
+ height: int,
+ negative_prompt: str | None = None,
+ image: torch.Tensor | None = None,
+ mask: torch.Tensor | None = None,
+ audio: AudioInput | None = None, # Hidden & unused
+ video: VideoInput | None = None, # Hidden & unused
+ sampling_params: dict | list[dict] | None = None,
+ **kwargs,
+ ):
+ logger.info("Uncaught kwargs: %s", kwargs)
+ logger.debug("Got sampling params: %s", sampling_params)
+ validate_model_and_sampling_params_types(model, sampling_params)
+ if image is None and mask is not None:
+ raise ValueError("Mask input provided without an image input.")
+
+ client = VLLMOmniClient(url)
+
+ spec, pattern = lookup_model_spec(model)
+ is_bagel = pattern is not None and "bagel" in pattern.lower()
+
+ # Prefer DALL-E compatible API for simple (one-stage) diffusion models
+ if (spec is None or spec["stages"] == ["diffusion"]) and not is_bagel:
+ sampling_params = cast(dict | None, sampling_params)
+ if audio is None and image is None and video is None:
+ # No multimodal input --- use DALL-E image generation
+ logger.info("Using DALL-E image generation endpoint")
+ output = await client.generate_image(
+ model=model,
+ prompt=prompt,
+ width=width,
+ height=height,
+ negative_prompt=negative_prompt,
+ sampling_params=sampling_params,
+ )
+ return (output,)
+ elif image is not None and audio is None and video is None:
+ # Image and text input --- use DALL-E image edit
+ logger.info("Using DALL-E image edit endpoint")
+ output = await client.edit_image(
+ model=model,
+ prompt=prompt,
+ image=image,
+ width=width,
+ height=height,
+ negative_prompt=negative_prompt,
+ mask=mask,
+ sampling_params=sampling_params,
+ )
+ return (output,)
+
+ logger.info("Using chat completion endpoint")
+ sampling_params = add_sampling_parameters_to_stage(
+ model, sampling_params, "diffusion", width=width, height=height
+ )
+ logger.debug("Edited sampling params: %s", sampling_params)
+
+ output = await client.generate_image_chat_completion(
+ model=model,
+ prompt=prompt,
+ negative_prompt=negative_prompt,
+ image=image,
+ audio=audio,
+ video=video,
+ sampling_params=sampling_params,
+ )
+
+ return (output,)
+
+
+class VLLMOmniComprehension(_VLLMOmniGenerateBase):
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "url": ("STRING", {"default": "http://localhost:8000/v1"}),
+ "model": ("STRING", {"default": "Qwen/Qwen2.5-Omni-7B"}),
+ "prompt": ("STRING", {"multiline": True}),
+ "output_text": ("BOOLEAN", {"default": True}),
+ "output_audio": ("BOOLEAN", {"default": True}),
+ "use_audio_in_video": ("BOOLEAN", {"default": True}),
+ },
+ "optional": {
+ "image": ("IMAGE",),
+ "video": ("VIDEO",),
+ "audio": ("AUDIO",),
+ "sampling_params": ("SAMPLING_PARAMS",),
+ },
+ }
+
+ RETURN_TYPES = ("STRING", "AUDIO")
+ RETURN_NAMES = ("text_response", "audio_response")
+ FUNCTION = "generate"
+
+ @classmethod
+ def VALIDATE_INPUTS(cls, url, model, output_text, output_audio) -> str | Literal[True]: # type: ignore[reportIncompatibleMethodOverride]
+ super_validation = super().VALIDATE_INPUTS(url, model)
+ if isinstance(super_validation, str):
+ return super_validation
+ if not output_text and not output_audio:
+ return "At least one of output_text or output_audio must be True."
+ return True
+
+ async def generate(
+ self,
+ url: str,
+ model: str,
+ prompt: str,
+ image: torch.Tensor | None = None,
+ audio: AudioInput | None = None,
+ video: VideoInput | None = None,
+ sampling_params: dict | list[dict] | None = None,
+ output_text: bool = True,
+ output_audio: bool = True,
+ use_audio_in_video: bool = True,
+ **kwargs,
+ ) -> tuple[str, AudioInput]:
+ logger.info("Uncaught kwargs: %s", kwargs)
+ logger.debug("Got sampling params: %s", sampling_params)
+ validate_model_and_sampling_params_types(model, sampling_params)
+
+ client = VLLMOmniClient(url)
+ spec, pattern = lookup_model_spec(model)
+ is_bagel = pattern is not None and "bagel" in pattern.lower()
+
+ if is_bagel:
+ # A lot of special handlings here...
+ if output_audio:
+ raise ValueError("BAGEL models do not support audio output.")
+ if audio is not None or video is not None:
+ raise ValueError("BAGEL models do not support audio or video input.")
+ (
+ text_response,
+ _,
+ ) = await client.generate_comprehension_chat_completion(
+ model=model,
+ prompt=prompt,
+ image=image,
+ audio=None,
+ video=None,
+ sampling_params=sampling_params,
+ modalities=["text"],
+ )
+ else:
+ modalities = []
+ if output_text:
+ modalities.append("text")
+ if output_audio:
+ modalities.append("audio")
+
+ if use_audio_in_video and video is not None:
+ use_audio_in_video = True
+ else:
+ use_audio_in_video = False
+
+ (
+ text_response,
+ audio,
+ ) = await client.generate_comprehension_chat_completion(
+ model=model,
+ prompt=prompt,
+ image=image,
+ audio=audio,
+ video=video,
+ sampling_params=sampling_params,
+ modalities=modalities,
+ # == extra kwargs ==
+ mm_processor_kwargs={"use_audio_in_video": use_audio_in_video},
+ )
+
+ if text_response is None:
+ text_response = ""
+ if audio is None:
+ channels = 1
+ duration = 1
+ sample_rate = 44100
+ num_samples = int(round(duration * sample_rate))
+ waveform = torch.zeros((1, channels, num_samples), dtype=torch.float32)
+ audio = {"waveform": waveform, "sample_rate": sample_rate}
+
+ return (text_response, audio)
+
+
+class VLLMOmniTTS(_VLLMOmniGenerateBase):
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "url": ("STRING", {"default": "http://localhost:8000/v1"}),
+ "model": (
+ "STRING",
+ {"default": "Qwen/Qwen3-TTS-12Hz-1.7B-CustomVoice"},
+ ),
+ "input": ("STRING", {"multiline": True}),
+ "voice": ("STRING", {"default": "Vivian"}),
+ "response_format": (["mp3", "opus", "aac", "flac", "wav", "pcm"],),
+ "speed": (
+ "FLOAT",
+ {"default": 1.0, "min": 0.25, "max": 4.0, "step": 0.01},
+ ),
+ },
+ "optional": {
+ "model_specific_params": ("TTS_PARAMS",),
+ },
+ }
+
+ RETURN_TYPES = ("AUDIO",)
+ RETURN_NAMES = ("audio",)
+ FUNCTION = "generate"
+
+ async def generate(
+ self,
+ url: str,
+ model: str,
+ input: str,
+ voice: str,
+ response_format: AudioFormat,
+ speed: float,
+ model_specific_params: dict | None,
+ **kwargs,
+ ) -> tuple[AudioInput]:
+ logger.info("Got extra kwargs in TTS: %s", kwargs)
+
+ is_qwen_tts = "qwen3-tts" in model.lower()
+ extra_params_type = None if model_specific_params is None else model_specific_params["type"]
+ if not is_qwen_tts and extra_params_type == "qwen-tts":
+ raise ValueError(
+ "You have provided Qwen-specific TTS params."
+ "However, the model appears to not be a Qwen TTS model (no 'Qwen3-TTS' in model name)."
+ )
+
+ combined_params = {**kwargs, **(model_specific_params or {})}
+ combined_params.pop("type", None) # Internal fields in model_specific_params
+
+ client = VLLMOmniClient(url)
+
+ audio = await client.generate_speech(
+ model=model,
+ input=input,
+ voice=voice,
+ response_format=response_format,
+ speed=speed,
+ **combined_params,
+ )
+ return (audio,)
+
+
+class VLLMOmniVoiceClone(_VLLMOmniGenerateBase):
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "url": ("STRING", {"default": "http://localhost:8000/v1"}),
+ "model": ("STRING", {"default": "Qwen/Qwen3-TTS-12Hz-1.7B-Base"}),
+ "input": ("STRING", {"multiline": True}),
+ "voice": ("STRING", {"default": "Vivian"}),
+ "response_format": (["mp3", "opus", "aac", "flac", "wav", "pcm"],),
+ "speed": (
+ "FLOAT",
+ {"default": 1.0, "min": 0.25, "max": 4.0, "step": 0.01},
+ ),
+ "ref_audio": ("AUDIO",),
+ "ref_text": ("STRING", {"multiline": True}),
+ "x_vector_only_mode": ("BOOLEAN", {"default": False}),
+ },
+ "optional": {
+ "model_specific_params": ("TTS_PARAMS",),
+ },
+ }
+
+ RETURN_TYPES = ("AUDIO",)
+ RETURN_NAMES = ("audio",)
+ FUNCTION = "generate"
+
+ async def generate(
+ self,
+ url: str,
+ model: str,
+ input: str,
+ voice: str,
+ response_format: AudioFormat,
+ speed: float,
+ ref_audio: AudioInput,
+ ref_text: str,
+ x_vector_only_mode: bool,
+ model_specific_params: dict | None,
+ **kwargs,
+ ):
+ is_qwen_tts = "qwen3-tts" in model.lower()
+ extra_params_type = None if model_specific_params is None else model_specific_params["type"]
+ if not is_qwen_tts and extra_params_type == "qwen-tts":
+ raise ValueError(
+ "You have provided Qwen-specific TTS params."
+ "However, the model appears to not be a Qwen TTS model (no 'Qwen3-TTS' in model name)."
+ )
+
+ combined_params = {
+ "ref_audio": ref_audio,
+ "ref_text": ref_text,
+ "x_vector_only_mode": x_vector_only_mode,
+ **kwargs,
+ **(model_specific_params or {}),
+ }
+ combined_params.pop("type", None) # Internal fields in model_specific_params
+
+ client = VLLMOmniClient(url)
+
+ audio = await client.generate_speech(
+ model=model,
+ input=input,
+ voice=voice,
+ response_format=response_format,
+ speed=speed,
+ **combined_params,
+ )
+ return (audio,)
+
+
+class VLLMOmniARSampling:
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "max_tokens": ("INT", {"default": 100, "min": 1, "max": 10000}),
+ "temperature": (
+ "FLOAT",
+ {"default": 1.0, "min": 0.0, "max": 2.0, "step": 0.01},
+ ),
+ "top_p": (
+ "FLOAT",
+ {"default": 1.0, "min": 0.0, "max": 1.0, "step": 0.01},
+ ),
+ "repetition_penalty": (
+ "FLOAT",
+ {"default": 1.0, "min": 0.0, "max": 5.0, "step": 0.01},
+ ),
+ # === Put seed at last. ===
+ # Whenever a field named "seed" is present, ComfyUI adds another field called "control after generate"
+ "seed": (
+ "INT",
+ {
+ "default": -1,
+ "min": -1,
+ "step": 1,
+ "tooltip": "-1 means to not provide a seed.",
+ },
+ ),
+ }
+ }
+
+ RETURN_TYPES = ("SAMPLING_PARAMS",)
+ RETURN_NAMES = ("AR sampling params",)
+ FUNCTION = "get_params"
+ CATEGORY = "vLLM-Omni/Sampling Params"
+
+ def get_params(self, seed, **kwargs):
+ params = {
+ "type": "autoregression", # for internal use, removed before sending the request
+ **kwargs,
+ }
+ if seed >= 0:
+ params["seed"] = seed
+ return (params,)
+
+
+class VLLMOmniDiffusionSampling:
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "n": (
+ "INT",
+ {
+ "default": 1,
+ "min": 0,
+ "max": 10,
+ "step": 1,
+ "tooltip": "Number of images to generate",
+ },
+ ),
+ "num_inference_steps": (
+ "INT",
+ {
+ "default": 50,
+ "min": 1,
+ "max": 1000,
+ "tooltip": "Number of denoising steps (higher = better quality, slower).",
+ },
+ ),
+ "guidance_scale": (
+ "FLOAT",
+ {
+ "default": 7.5,
+ "min": 0.0,
+ "max": 20.0,
+ "step": 0.1,
+ "tooltip": "Classifier-free guidance scale (higher = more prompt adherence).",
+ },
+ ),
+ "true_cfg_scale": (
+ "FLOAT",
+ {
+ "default": 1.0,
+ "min": 0.0,
+ "max": 20.0,
+ "step": 0.5,
+ "tooltip": "True CFG scale for advanced control (model-specific).",
+ },
+ ),
+ "vae_use_slicing": (
+ "BOOLEAN",
+ {
+ "default": False,
+ "tooltip": "Enable VAE slicing for reduced memory usage (slight quality trade-off)",
+ },
+ ),
+ # === Put seed at last. ===
+ # Whenever a field named "seed" is present, ComfyUI adds another field called "control after generate"
+ "seed": (
+ "INT",
+ {
+ "default": -1,
+ "min": -1,
+ "step": 1,
+ "tooltip": "-1 means to not provide a seed.",
+ },
+ ),
+ }
+ }
+
+ RETURN_TYPES = ("SAMPLING_PARAMS",)
+ RETURN_NAMES = ("diffusion sampling params",)
+ FUNCTION = "get_params"
+ CATEGORY = "vLLM-Omni/Sampling Params"
+
+ def get_params(self, seed, **kwargs):
+ params = {
+ "type": "diffusion", # for internal use, removed before sending the request
+ **kwargs,
+ }
+ if seed >= 0:
+ params["seed"] = seed
+ return (params,)
+
+
+class VLLMOmniSamplingParamsList:
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "param1": ("SAMPLING_PARAMS",),
+ },
+ "optional": {
+ "param2": ("SAMPLING_PARAMS",),
+ "param3": ("SAMPLING_PARAMS",),
+ },
+ }
+
+ RETURN_TYPES = ("SAMPLING_PARAMS",)
+ RETURN_NAMES = ("param list",)
+ FUNCTION = "aggregate"
+ CATEGORY = "vLLM-Omni/Sampling Params"
+
+ def aggregate(self, param1: dict, param2: dict | None = None, param3: dict | None = None):
+ for i, p in enumerate((param1, param2, param3)):
+ if isinstance(p, list):
+ raise ValueError(
+ f"Input {i} is a Multi-Stage Sampling Params List. "
+ f"Expected a single sampling parameters node (either AR or Diffusion)."
+ )
+
+ params = [param1]
+ if param2 is not None:
+ params.append(param2)
+ if param3 is not None:
+ params.append(param3)
+ return (params,)
+
+
+class VLLMOmniQwenTTSParams:
+ @classmethod
+ def INPUT_TYPES(cls):
+ return {
+ "required": {
+ "task_type": (
+ ["CustomVoice", "VoiceDesign", "Base"],
+ {"default": "CustomVoice"},
+ ),
+ "language": (
+ ["Auto", "Chinese", "English", "Japanese", "Korean"],
+ {"default": "Auto"},
+ ),
+ "instructions": ("STRING", {"multiline": True}),
+ "max_new_tokens": ("INT", {"default": 2048, "min": 1}),
+ }
+ }
+
+ RETURN_TYPES = ("TTS_PARAMS",)
+ RETURN_NAMES = ("Qwen TTS params",)
+ FUNCTION = "get_params"
+ CATEGORY = "vLLM-Omni/TTS Params"
+
+ def get_params(self, **kwargs):
+ return ({"type": "qwen-tts", **kwargs},)
diff --git a/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/api_client.py b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/api_client.py
new file mode 100644
index 000000000..c5372641f
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/api_client.py
@@ -0,0 +1,473 @@
+"""
+An high-level API client adapter that forwards ComfyUI inputs to vLLM-Omni's REST API,
+and transforms the API responses back to ComfyUI formats.
+
+The image generation part is derived from dougbtv/comfyui-vllm-omni by Doug (@dougbtv).
+Original source at https://github.com/dougbtv/comfyui-vllm-omni, distributed under the MIT License.
+"""
+
+from typing import Any
+
+import aiohttp
+import av.error
+import torch
+from comfy_api.input import AudioInput, VideoInput
+
+from .format import (
+ audio_to_base64,
+ base64_to_audio,
+ base64_to_image_tensor,
+ bytes_to_audio,
+ image_tensor_to_base64,
+ image_tensor_to_png_bytes,
+ video_to_base64,
+)
+from .logger import get_logger, pretty_printer
+from .models import lookup_model_spec
+from .types import AudioFormat
+
+logger = get_logger(__name__)
+
+
+class VLLMOmniClient:
+ def __init__(self, base_url: str, timeout: float = 300.0):
+ self.base_url = base_url
+ self.timeout = aiohttp.ClientTimeout(total=timeout)
+
+ async def generate_image(
+ self,
+ *,
+ model: str,
+ prompt: str,
+ width: int,
+ height: int,
+ negative_prompt: str | None = None,
+ sampling_params: dict | None = None,
+ ) -> torch.Tensor:
+ """Run text-to-image generation via DALLE API"""
+ await self._check_model_exist(model)
+
+ size = f"{width}x{height}"
+ payload = {
+ "model": model,
+ "prompt": prompt,
+ "size": size,
+ "response_format": "b64_json",
+ }
+ if negative_prompt:
+ payload["negative_prompt"] = negative_prompt
+ if sampling_params is not None:
+ # Only select specific sampling params
+ for k in (
+ "n",
+ "num_inference_steps",
+ "guidance_scale",
+ "true_cfg_scale",
+ "vae_use_slicing",
+ ):
+ if k in sampling_params and sampling_params[k] is not None:
+ payload[k] = sampling_params[k]
+ logger.debug("img gen payload: %s", payload)
+
+ url = self.base_url + "/images/generations"
+ async with aiohttp.ClientSession(timeout=self.timeout) as session:
+ try:
+ async with session.post(
+ url,
+ json=payload,
+ headers={"Content-Type": "application/json"},
+ ) as response:
+ if not response.ok:
+ error_text = await response.text()
+ raise (ValueError if response.status < 500 else RuntimeError)(
+ f"vLLM-Omni API returned status {response.status}: {error_text}"
+ )
+
+ try:
+ data = await response.json()
+ except aiohttp.ContentTypeError as e:
+ raise RuntimeError(f"Invalid JSON response from vLLM-Omni: {e}")
+ if "data" not in data:
+ raise RuntimeError("API response missing 'data' field - expected OpenAI DALL-E format")
+ if not data["data"]:
+ raise RuntimeError("API returned empty data array")
+
+ image_tensors = []
+ for idx, img in enumerate(data["data"]):
+ if "b64_json" not in img:
+ raise RuntimeError(f"API returned image #{idx} without 'b64_json' field")
+ base64_str = img["b64_json"]
+ tensor = base64_to_image_tensor(base64_str)
+ image_tensors.append(tensor)
+ logger.debug("Image #%d has shape %s", idx, tensor.shape)
+
+ batch_tensor = torch.stack(image_tensors, dim=0)
+ logger.debug("batch_tensor output has shape: %s", batch_tensor.shape)
+ return batch_tensor
+
+ except aiohttp.ClientError as e:
+ raise RuntimeError(f"Network error connecting to vLLM-Omni at {url}: {e}")
+
+ async def edit_image(
+ self,
+ *,
+ model: str,
+ prompt: str,
+ image: torch.Tensor,
+ width: int,
+ height: int,
+ negative_prompt: str | None = None,
+ mask: torch.Tensor | None = None,
+ sampling_params: dict | None = None,
+ ) -> torch.Tensor:
+ """Run image editing via DALLE API"""
+ await self._check_model_exist(model)
+
+ size = f"{width}x{height}"
+ image_filename = "image.png" # Required for multipart form
+ form = aiohttp.FormData()
+ form.add_field("model", model)
+ form.add_field(
+ "image",
+ image_tensor_to_png_bytes(image, image_filename),
+ filename=image_filename,
+ content_type="image/png",
+ )
+ form.add_field("prompt", prompt)
+ form.add_field("size", size)
+ if negative_prompt:
+ form.add_field("negative_prompt", negative_prompt)
+ if sampling_params is not None:
+ # Only select specific sampling params
+ for k in ("n", "num_inference_steps", "guidance_scale", "true_cfg_scale"):
+ if k in sampling_params and sampling_params[k] is not None:
+ form.add_field(k, str(sampling_params[k]))
+ if mask is not None:
+ mask_filename = "mask.png"
+ form.add_field(
+ "mask",
+ image_tensor_to_png_bytes(mask, mask_filename),
+ filename=mask_filename,
+ content_type="image/png",
+ )
+
+ url = self.base_url + "/images/edits"
+ async with aiohttp.ClientSession(timeout=self.timeout) as session:
+ try:
+ async with session.post(url, data=form) as response:
+ if not response.ok:
+ error_text = await response.text()
+ raise (ValueError if response.status < 500 else RuntimeError)(
+ f"vLLM-Omni API returned status {response.status}: {error_text}"
+ )
+
+ try:
+ data = await response.json()
+ except aiohttp.ContentTypeError as e:
+ raise RuntimeError(f"Invalid JSON response from vLLM-Omni: {e}")
+
+ if "data" not in data:
+ raise RuntimeError("API response missing 'data' field - expected OpenAI DALL-E format")
+ if not data["data"]:
+ raise RuntimeError("API returned empty data array")
+
+ image_tensors = []
+ for idx, img in enumerate(data["data"]):
+ if "b64_json" not in img:
+ raise RuntimeError(f"API returned image #{idx} without 'b64_json' field")
+ base64_str = img["b64_json"]
+ tensor = base64_to_image_tensor(base64_str)
+ image_tensors.append(tensor)
+
+ return torch.stack(image_tensors, dim=0)
+
+ except aiohttp.ClientError as e:
+ raise RuntimeError(f"Network error connecting to vLLM-Omni at {url}: {e}")
+
+ async def generate_image_chat_completion(
+ self,
+ *,
+ model: str,
+ prompt: str,
+ negative_prompt: str | None = None,
+ image: torch.Tensor | None = None,
+ audio: AudioInput | None = None,
+ video: VideoInput | None = None,
+ sampling_params: dict | list[dict] | None = None,
+ ) -> torch.Tensor:
+ payload = VLLMOmniClient._prepare_chat_completion_messages(
+ model=model,
+ prompt=prompt,
+ negative_prompt=negative_prompt,
+ image=image,
+ audio=audio,
+ video=video,
+ sampling_params=sampling_params,
+ modalities=["image"],
+ )
+ choices = await self._generate_base_chat_completion(model, payload)
+
+ image_tensors = []
+ for idx, img_content in enumerate(choices[0]["message"]["content"]):
+ base64_str = img_content.get("image_url", {}).get("url", "")
+ if not base64_str:
+ raise RuntimeError(f"API returned image #{idx} without image url")
+ tensor = base64_to_image_tensor(base64_str)
+ image_tensors.append(tensor)
+
+ return torch.stack(image_tensors, dim=0)
+
+ async def generate_comprehension_chat_completion(
+ self,
+ *,
+ model: str,
+ prompt: str,
+ image: torch.Tensor | None = None,
+ audio: AudioInput | None = None,
+ video: VideoInput | None = None,
+ sampling_params: dict | list[dict] | None = None,
+ modalities: list[str] = ["text", "audio"],
+ **extra_body,
+ ) -> tuple[str | None, AudioInput | None]:
+ # Response may contain two choices: one with text, one with audio
+ payload = VLLMOmniClient._prepare_chat_completion_messages(
+ model=model,
+ prompt=prompt,
+ negative_prompt=None,
+ image=image,
+ audio=audio,
+ video=video,
+ sampling_params=sampling_params,
+ modalities=modalities,
+ **extra_body,
+ )
+
+ choices = await self._generate_base_chat_completion(model, payload)
+ text_response = None
+ audio_base64 = None
+ for choice in choices:
+ try:
+ text_response = choice["message"]["content"]
+ except (KeyError, TypeError):
+ # Either this case (text response) or the audio response case will be hit. Checking None's later.
+ pass
+ try:
+ audio_base64 = choice["message"]["audio"]["data"]
+ except (KeyError, TypeError):
+ # Either this case (text response) or the audio response case will be hit. Checking None's later.
+ pass
+ if audio_base64 is None and text_response is None:
+ raise RuntimeError(
+ "API response missing both '.message.audio' and 'message.content' fields."
+ f"The choices object is {choices}"
+ )
+ if audio_base64 is not None:
+ audio = base64_to_audio(audio_base64)
+ logger.debug(
+ "audio sample rate %d, audio shape %s, duration in second %f",
+ audio["sample_rate"],
+ audio["waveform"].shape,
+ audio["waveform"].shape[2] / audio["sample_rate"],
+ )
+ else:
+ audio = None
+ return text_response, audio
+
+ async def generate_speech(
+ self,
+ *,
+ model: str,
+ input: str,
+ voice: str,
+ response_format: AudioFormat,
+ speed: float,
+ **extra_params,
+ ) -> AudioInput:
+ await self._check_model_exist(model)
+
+ ref_audio: AudioInput | None = extra_params.pop("ref_audio", None)
+
+ payload = {
+ "model": model,
+ "input": input,
+ "voice": voice,
+ "response_format": response_format,
+ "speed": speed,
+ **extra_params,
+ }
+
+ if ref_audio is not None:
+ audio_base64 = audio_to_base64(ref_audio)
+ payload["ref_audio"] = audio_base64
+
+ logger.debug("Omni TTS payload: %s", pretty_printer.pformat(payload))
+
+ url = self.base_url + "/audio/speech"
+ async with aiohttp.ClientSession(timeout=self.timeout) as session:
+ try:
+ async with session.post(
+ url,
+ json=payload,
+ headers={"Content-Type": "application/json"},
+ ) as response:
+ if not response.ok:
+ error_text = await response.text()
+ raise (ValueError if response.status < 500 else RuntimeError)(
+ f"vLLM-Omni API returned status {response.status}: {error_text}"
+ )
+
+ try:
+ audio_bytes = await response.read()
+ except aiohttp.ContentTypeError as e:
+ raise RuntimeError(f"Invalid JSON response from vLLM-Omni: {e}")
+
+ try:
+ audio = bytes_to_audio(audio_bytes)
+ except av.error.InvalidDataError as e:
+ raise ValueError(
+ f"Invalid audio data received from vLLM-Omni: {e}"
+ "Check if you have input unsupported arguments (such as 'voice')"
+ )
+ return audio
+
+ except aiohttp.ClientError as e:
+ raise RuntimeError(f"Network error connecting to vLLM-Omni at {url}: {e}")
+
+ async def _generate_base_chat_completion(self, model: str, payload: dict[str, Any]) -> list[dict[str, Any]]:
+ logger.debug("Omni payload: %s", pretty_printer.pformat(payload))
+ await self._check_model_exist(model)
+
+ url = self.base_url + "/chat/completions"
+ async with aiohttp.ClientSession(timeout=self.timeout) as session:
+ try:
+ async with session.post(
+ url,
+ json=payload,
+ headers={"Content-Type": "application/json"},
+ ) as response:
+ if not response.ok:
+ error_text = await response.text()
+ raise (ValueError if response.status < 500 else RuntimeError)(
+ f"vLLM-Omni API returned status {response.status}: {error_text}"
+ )
+
+ try:
+ data = await response.json()
+ except aiohttp.ContentTypeError as e:
+ raise RuntimeError(f"Invalid JSON response from vLLM-Omni: {e}")
+
+ logger.debug(
+ "chat completion response: %s",
+ pretty_printer.pformat(data),
+ )
+
+ try:
+ return data["choices"]
+ except (KeyError, TypeError):
+ raise RuntimeError("Invalid JSON response from vLLM-Omni: missing 'choices' field")
+
+ except aiohttp.ClientError as e:
+ raise RuntimeError(f"Network error connecting to vLLM-Omni at {self.base_url}: {e}")
+
+ async def _check_model_exist(self, model: str):
+ url = self.base_url + "/models"
+ async with aiohttp.ClientSession(timeout=self.timeout) as session:
+ try:
+ async with session.get(
+ url,
+ headers={"Content-Type": "application/json"},
+ ) as response:
+ if not response.ok:
+ error_text = await response.text()
+ raise (ValueError if response.status < 500 else RuntimeError)(
+ f"vLLM-Omni API returned status {response.status} "
+ f"when getting hosted model list: {error_text}"
+ )
+
+ try:
+ data = await response.json()
+ except aiohttp.ContentTypeError as e:
+ raise RuntimeError(f"Invalid JSON response when getting hosted model list from vLLM-Omni: {e}")
+
+ except aiohttp.ClientError as e:
+ raise RuntimeError(f"Network error connecting to vLLM-Omni at {self.base_url}: {e}")
+ try:
+ model_list = data["data"]
+ model_found = next((True for m in model_list if m["id"] == model), False)
+ except (KeyError, TypeError):
+ raise RuntimeError(f"Invalid JSON response of the hosted model list: {data}")
+
+ if not model_found:
+ raise ValueError(f"Model {model} not served at {self.base_url}.")
+
+ @staticmethod
+ def _prepare_chat_completion_messages(
+ *,
+ model: str,
+ prompt: str,
+ negative_prompt: str | None,
+ image: torch.Tensor | None = None,
+ audio: AudioInput | None = None,
+ video: VideoInput | None = None,
+ sampling_params: dict | list[dict] | None = None,
+ modalities: list[str] | None = None, # diffusion don't have this field
+ **extra_body,
+ ):
+ message_content: list[dict] = [{"type": "text", "text": prompt}]
+ if image is not None:
+ message_content.append(
+ {
+ "type": "image_url",
+ "image_url": {"url": image_tensor_to_base64(image)},
+ }
+ )
+ if audio is not None:
+ message_content.append({"type": "audio_url", "audio_url": {"url": audio_to_base64(audio)}})
+ if video is not None:
+ message_content.append({"type": "video_url", "video_url": {"url": video_to_base64(video)}})
+ messages = [{"role": "user", "content": message_content}]
+
+ combined_extra_body: dict[str, Any] = {}
+ if sampling_params is not None:
+ spec, _ = lookup_model_spec(model)
+ is_single_sampling_param = isinstance(sampling_params, dict) or len(sampling_params) == 1
+
+ # Exclude internal key
+ if isinstance(sampling_params, dict):
+ sampling_params = {k: v for k, v in sampling_params.items() if k != "type"}
+ else:
+ sampling_params = [{k: v for k, v in sp.items() if k != "type"} for sp in sampling_params]
+
+ if (spec is None and is_single_sampling_param) or (spec is not None and spec["stages"] == ["diffusion"]):
+ # Diffusion format: extra_body directly contains sampling params.
+ # Validation should have taken care of matching sampling params' types.
+ # * Use this mode if the model is a simple one-stage diffusion model.
+ # * Fallback to this mode if model is not registered and a single sampling param is provided.
+ sampling_params = sampling_params if isinstance(sampling_params, dict) else sampling_params[0]
+ combined_extra_body: dict[str, Any] = {**sampling_params}
+ if "n" in combined_extra_body:
+ combined_extra_body["num_outputs_per_prompt"] = combined_extra_body["n"]
+ del combined_extra_body["n"]
+ else:
+ # Use AR style payload, extra_body has a sampling_params_list field
+ combined_extra_body: dict[str, Any] = {"sampling_params_list": sampling_params}
+
+ if negative_prompt:
+ combined_extra_body["negative_prompt"] = negative_prompt
+
+ if extra_body:
+ combined_extra_body.update(extra_body)
+
+ payload: dict[str, Any] = {"messages": messages, "model": model}
+ if combined_extra_body:
+ payload["extra_body"] = combined_extra_body
+ if modalities:
+ payload["modalities"] = modalities
+
+ spec, _ = lookup_model_spec(model)
+ if spec:
+ preprocessor = spec.get("payload_preprocessor", None)
+ if preprocessor is not None:
+ payload = preprocessor(payload)
+
+ return payload
diff --git a/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/format.py b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/format.py
new file mode 100644
index 000000000..0ddf86f9c
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/format.py
@@ -0,0 +1,230 @@
+"""Image/tensor format helpers.
+
+The image generation part is derived from dougbtv/comfyui-vllm-omni by Doug (@dougbtv).
+Original source at https://github.com/dougbtv/comfyui-vllm-omni, distributed under the MIT License.
+"""
+
+import base64
+import mimetypes
+from io import BytesIO
+
+import av
+import numpy as np
+import torch
+from comfy_api.input import AudioInput, VideoInput
+from comfy_extras import nodes_audio
+from PIL import Image
+
+from .logger import get_logger
+
+logger = get_logger(__name__)
+
+
+def base64_to_image_tensor(base64_str: str, mode: str = "RGB") -> torch.Tensor:
+ """
+ Convert base64-encoded image to ComfyUI image tensor.
+
+ Args:
+ base64_str: Base64-encoded image string
+ mode: PIL image mode (default RGB for transparency support)
+
+ Returns:
+ torch.Tensor with shape (1, H, W, C) in float32 [0, 1] range
+
+ Raises:
+ ValueError: If base64 string is invalid or image cannot be decoded
+ """
+ if base64_str.startswith("data:image"):
+ _, base64_str = base64_str.split(",", 1)
+
+ try:
+ # Decode base64 to bytes
+ image_bytes = base64.b64decode(base64_str)
+ except Exception as e:
+ raise ValueError(f"Invalid base64 string: {e}")
+
+ # Create BytesIO object for PIL
+ image_bytesio = BytesIO(image_bytes)
+
+ # Open with PIL and convert to desired mode
+ try:
+ pil_image = Image.open(image_bytesio)
+ pil_image = pil_image.convert(mode)
+ except Exception as e:
+ raise RuntimeError(f"Failed to open image: {e}")
+
+ image_array = np.asarray(pil_image).astype(np.float32) / 255.0
+ image_tensor = torch.from_numpy(image_array)
+ return image_tensor
+
+
+def image_tensor_to_png_bytes(tensor: torch.Tensor, filename: str = "image.png") -> BytesIO:
+ """
+ Convert ComfyUI image tensor to PNG BytesIO for multipart upload.
+
+ This function converts a ComfyUI IMAGE tensor to a PNG-encoded BytesIO object
+ suitable for multipart/form-data upload. The BytesIO object has its .name
+ attribute set, which is required by aiohttp for file uploads.
+
+ Args:
+ tensor: ComfyUI IMAGE tensor with shape (B, H, W, C), dtype float32, range [0, 1]
+ filename: Name attribute to set on BytesIO (default: "image.png")
+
+ Returns:
+ BytesIO object containing PNG-encoded image with .name attribute set
+
+ Raises:
+ ValueError: If tensor format is invalid (not 4D, wrong dtype, etc.)
+ """
+ if tensor.ndim != 4:
+ raise ValueError(f"Expected 4D tensor with shape (B, H, W, C), got {tensor.ndim}D tensor")
+
+ image_tensor = tensor[0] # Shape: (H, W, C)
+ image_np = (image_tensor.cpu().numpy() * 255.0).astype(np.uint8)
+ pil_image = Image.fromarray(image_np)
+
+ # Save to BytesIO as image file
+ img_bytes = BytesIO()
+ # Set name attribute (required for multipart upload and mimetype detection)
+ img_bytes.name = filename
+ try:
+ pil_image.save(img_bytes)
+ except Exception as e:
+ raise RuntimeError(f"Failed to save image as file: {e}")
+
+ # Reset position to beginning
+ img_bytes.seek(0)
+
+ return img_bytes
+
+
+def image_tensor_to_base64(tensor: torch.Tensor, filename: str = "image.png") -> str:
+ """
+ Convert ComfyUI image tensor to base64-encoded image string.
+
+ Args:
+ tensor: ComfyUI IMAGE tensor with shape (B, H, W, C), dtype float32, range [0, 1]
+ filename: Name attribute to set on BytesIO (default: "image.png")
+ format: File format of the output image file buffer (default: "PNG")
+
+ Returns:
+ Base64-encoded image string
+
+ Raises:
+ ValueError: If tensor format is invalid (not 4D, wrong dtype, etc.)
+ """
+ img_bytes = image_tensor_to_png_bytes(tensor, filename)
+ img_bytes.seek(0)
+ byte_data = img_bytes.read()
+ base64_str = base64.b64encode(byte_data).decode("utf-8")
+ mime_type = mimetypes.guess_type(filename)[0] or "application/octet-stream"
+ return f"data:{mime_type};base64,{base64_str}"
+
+
+def video_to_bytes(video: VideoInput, filename: str = "video.mp4") -> BytesIO:
+ output_buffer = BytesIO()
+ output_buffer.name = filename
+ video.save_to(output_buffer)
+ output_buffer.seek(0)
+ return output_buffer
+
+
+def video_to_base64(video: VideoInput, filename: str = "video.mp4") -> str:
+ video_buffer = video_to_bytes(video, filename)
+ video_buffer.seek(0)
+ byte_data = video_buffer.read()
+ base64_str = base64.b64encode(byte_data).decode("utf-8")
+ mime_type = mimetypes.guess_type(filename)[0] or "application/octet-stream"
+ return f"data:{mime_type};base64,{base64_str}"
+
+
+def audio_to_bytes(audio: AudioInput, filename: str = "audio.mp3", quality: str = "128k") -> BytesIO:
+ waveform = audio["waveform"][0] # Shape: (C, T)
+ sample_rate = audio["sample_rate"]
+ format = filename.rsplit(".", maxsplit=1)[1]
+ layout = "mono" if waveform.shape[0] == 1 else "stereo"
+
+ output_buffer = BytesIO()
+ output_buffer.name = filename
+ output_container = av.open(output_buffer, mode="w", format=format)
+ if format == "opus":
+ out_stream = output_container.add_stream("libopus", rate=sample_rate, layout=layout)
+ if quality == "64k":
+ out_stream.bit_rate = 64000 # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ elif quality == "96k":
+ out_stream.bit_rate = 96000 # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ elif quality == "128k":
+ out_stream.bit_rate = 128000 # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ elif quality == "192k":
+ out_stream.bit_rate = 192000 # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ elif quality == "320k":
+ out_stream.bit_rate = 320000 # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ elif format == "mp3":
+ out_stream = output_container.add_stream("libmp3lame", rate=sample_rate, layout=layout)
+ if quality == "V0":
+ out_stream.codec_context.qscale = 1 # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ elif quality == "128k":
+ out_stream.bit_rate = 128000 # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ elif quality == "320k":
+ out_stream.bit_rate = 320000 # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ else: # format == "flac":
+ out_stream = output_container.add_stream("flac", rate=sample_rate, layout=layout)
+
+ frame = av.AudioFrame.from_ndarray(
+ waveform.movedim(0, 1).reshape(1, -1).float().numpy(),
+ format="flt",
+ layout=layout,
+ )
+ frame.sample_rate = sample_rate
+ frame.pts = 0
+ output_container.mux(out_stream.encode(frame)) # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ # Flush encoder
+ output_container.mux(out_stream.encode(None)) # type: ignore # copy from ComfyUI comfy_api/latest/_ui.py
+ output_container.close()
+ output_buffer.seek(0)
+
+ return output_buffer
+
+
+def audio_to_base64(audio: AudioInput, filename: str = "audio.mp3", quality: str = "128k") -> str:
+ audio_buffer = audio_to_bytes(audio, filename, quality)
+ audio_buffer.seek(0)
+ byte_data = audio_buffer.read()
+ base64_str = base64.b64encode(byte_data).decode("utf-8")
+ mime_type = mimetypes.guess_type(filename)[0] or "application/octet-stream"
+ return f"data:{mime_type};base64,{base64_str}"
+
+
+def bytes_to_audio(audio_bytes: bytes) -> AudioInput:
+ """
+ Convert audio bytes to ComfyUI audio tensor.
+
+ Args:
+ audio_bytes: Audio file bytes
+ Returns:
+ torch.Tensor with shape (B, C, T) in float32 range [-1, 1]
+ """
+ audio_buffer = BytesIO(audio_bytes)
+ waveform, sample_rate = nodes_audio.load(audio_buffer) # type: ignore # Although expect string argument, it calls av.open underneath, which supports BytesIO (file-like)
+ return {"waveform": waveform.unsqueeze(0), "sample_rate": sample_rate}
+
+
+def base64_to_audio(base64_str: str) -> AudioInput:
+ """
+ Convert base64-encoded audio to ComfyUI audio tensor.
+
+ Args:
+ base64_str: Base64-encoded audio string
+ Returns:
+ torch.Tensor with shape (B, C, T) in float32 range [-1, 1]
+ """
+ if base64_str.startswith("data:audio"):
+ _, base64_str = base64_str.split(",", 1)
+
+ try:
+ # Decode base64 to bytes
+ audio_bytes = base64.b64decode(base64_str)
+ except Exception as e:
+ raise ValueError(f"Invalid base64 string: {e}")
+
+ return bytes_to_audio(audio_bytes)
diff --git a/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/logger.py b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/logger.py
new file mode 100644
index 000000000..cad640f4d
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/logger.py
@@ -0,0 +1,125 @@
+"""Centralized logger configuration for vLLM-Omni ComfyUI."""
+
+import logging
+import pprint
+import sys
+from typing import Any
+
+
+def get_logger(name: str) -> logging.Logger:
+ """
+ Get or create a logger with proper formatting.
+
+ Args:
+ name: Logger name (typically __name__ of the calling module)
+
+ Returns:
+ Configured logger instance
+ """
+ logger = logging.getLogger(name)
+
+ # Only configure if not already configured
+ if not logger.handlers:
+ logger.setLevel(logging.DEBUG)
+
+ # Create console handler
+ handler = logging.StreamHandler(sys.stdout)
+ handler.setLevel(logging.INFO)
+
+ # Create formatter
+ formatter = logging.Formatter(
+ fmt="(ComfyUI-vLLM-Omni) [%(levelname)s] %(asctime)s [%(filename)s:%(lineno)s] %(message)s",
+ datefmt="%Y-%m-%d %H:%M:%S",
+ )
+ handler.setFormatter(formatter)
+
+ # Add handler to logger
+ logger.addHandler(handler)
+
+ # Prevent propagation to root logger
+ logger.propagate = False
+
+ return logger
+
+
+class OmitBase64PrettyPrinter(pprint.PrettyPrinter):
+ """
+ A PrettyPrinter that redacts specific field names with '...'
+ wherever they appear in nested structures.
+ """
+
+ def __init__(self, *args, **kwargs):
+ super().__init__(*args, **kwargs)
+
+ def _format(self, obj: Any, stream, indent: int, allowance: int, context, level: int) -> None:
+ # Check if this is a dict with redacted keys
+ if isinstance(obj, dict):
+ # Create a copy with redacted values
+ display_obj = {}
+ for key, value in obj.items():
+ if key == "data" or key == "url":
+ if value.startswith("data:"):
+ base64_header = value.split(",", 1)[0]
+ display_obj[key] = f"{base64_header},***"
+ elif value.startswith("http://") or value.startswith("https://"):
+ display_obj[key] = value
+ elif len(value) > 10:
+ display_obj[key] = f"{value[:10]}***"
+ else:
+ display_obj[key] = value
+ else:
+ display_obj[key] = value
+ obj = display_obj
+
+ # Handle list/tuple/set containing dicts that might have redacted keys
+ # (pprint will recursively call _format on nested items, so this
+ # handles arbitrary nesting automatically)
+
+ super()._format(obj, stream, indent, allowance, context, level)
+
+
+pretty_printer = OmitBase64PrettyPrinter()
+
+
+# ========== PPrint EXAMPLES ==========
+
+if __name__ == "__main__":
+ data = {
+ "messages": [
+ {
+ "role": "system",
+ "content": (
+ "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group,"
+ "capable of perceiving auditory and visual inputs, as well as generating text and speech."
+ ),
+ },
+ {
+ "role": "user",
+ "content": [
+ {
+ "type": "text",
+ "text": "What sound is it, and what is the drawing about?",
+ },
+ {
+ "type": "text",
+ "text": "What sound is it, and what is the drawing about?",
+ },
+ {
+ "type": "image_url",
+ "image_url": {"url": "data:image/png;base64,iVBORw0KGgoAAAANSUhEUgAAAwAAAA"},
+ },
+ {
+ "type": "audio_url",
+ "audio_url": {"url": "data:audio/mpeg;base64,SUQzBAAAAAAAIlRTU0UAAAAOAAADT="},
+ },
+ ],
+ },
+ ],
+ "extra_body": {"mm_processor_kwargs": {"use_audio_in_video": False}},
+ "modalities": ["text"],
+ }
+
+ # Create printer that redacts 'password' and 'token' fields
+
+ print("\nRedactingPrettyPrinter (hides secrets):")
+ pretty_printer.pprint(data)
diff --git a/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/models.py b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/models.py
new file mode 100644
index 000000000..83bf64fe7
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/models.py
@@ -0,0 +1,119 @@
+import re
+
+from .types import Modality, ModelMode, Spec
+
+
+def _bagel_payload_preprocessor(payload: dict) -> dict:
+ try:
+ for message in payload["messages"]:
+ for content in message["content"]:
+ if content["type"] == "text":
+ content["text"] = "<|im_start|>" + content["text"] + "<|im_end|>"
+ except (KeyError, TypeError):
+ raise RuntimeError("Internal Error: malformatted BAGEL payload")
+ extra_body = payload.pop("extra_body", {})
+ return {**payload, **extra_body}
+
+
+def _qwen25_payload_preprocessor(payload: dict) -> dict:
+ if payload["messages"][0]["role"] != "system":
+ payload["messages"] = [
+ {
+ "role": "system",
+ "content": (
+ "You are Qwen, a virtual human developed by the Qwen Team, Alibaba Group,"
+ "capable of perceiving auditory and visual inputs, as well as generating text and speech."
+ ),
+ },
+ *payload["messages"],
+ ]
+ return payload
+
+
+_MODEL_PIPELINE_SPECS: dict[str, Spec] = {
+ r"BAGEL-7B-MoT": {
+ "stages": [
+ "diffusion" # The vLLM-Omni interface treats it as a single-stage diffusion model
+ ],
+ "modes": [
+ {
+ "mode": ModelMode.COMPREHENSION,
+ "input_modalities": [Modality.TEXT, Modality.IMAGE],
+ }
+ ],
+ "payload_preprocessor": _bagel_payload_preprocessor,
+ },
+ r"Qwen2.5-Omni*": {
+ "stages": ["autoregression", "autoregression", "autoregression"],
+ "payload_preprocessor": _qwen25_payload_preprocessor,
+ "modes": [
+ {
+ "mode": ModelMode.COMPREHENSION,
+ "input_modalities": [
+ Modality.TEXT,
+ Modality.IMAGE,
+ Modality.VIDEO,
+ Modality.AUDIO,
+ ],
+ }
+ ],
+ },
+ r"Qwen3-Omni*": {
+ "stages": ["autoregression", "autoregression", "autoregression"],
+ "modes": [
+ {
+ "mode": ModelMode.COMPREHENSION,
+ "input_modalities": [
+ Modality.TEXT,
+ Modality.IMAGE,
+ Modality.VIDEO,
+ Modality.AUDIO,
+ ],
+ }
+ ],
+ },
+}
+# Convert dict keys to regex patterns
+MODEL_PIPELINE_SPECS: dict[re.Pattern, Spec] = {}
+for k, v in _MODEL_PIPELINE_SPECS.items():
+ MODEL_PIPELINE_SPECS[re.compile(k)] = v
+del _MODEL_PIPELINE_SPECS
+
+
+def lookup_model_spec(model: str) -> tuple[Spec | None, str | None]:
+ try:
+ last_component = model.rstrip("/").rsplit("/", 1)[-1]
+ except IndexError:
+ last_component = model
+ for pattern, spec in MODEL_PIPELINE_SPECS.items():
+ if pattern.search(last_component):
+ return spec, pattern.pattern
+ return None, None
+
+
+# ============== DEMONSTRATION ==============
+
+if __name__ == "__main__":
+ test_paths = [
+ "Qwen/Qwen2.5-Omni-7B",
+ "MyModels/Qwen2.5-Omni-3B",
+ "/root/home/Qwen2.5-Omni-7B",
+ "Qwen/Qwen3-Omni",
+ "Qwen/Qwen3-Omni-30B-A3B-Instruct",
+ "Custom/Path/UnknownModel-Instruct",
+ "Not/Matching/Anything",
+ ]
+
+ test_payload = {"messages": [{"role": "user", "content": "prompt"}]}
+
+ print("Testing registry lookups:\n")
+ for path in test_paths:
+ spec, _ = lookup_model_spec(path)
+ if spec:
+ if preprocessor := spec.get("payload_preprocessor"):
+ result = preprocessor(test_payload)
+ print(f"✓ {path:<40} → {result}")
+ else:
+ print(f"✓ {path:<40} → No preprocessor")
+ else:
+ print(f"✗ {path:<40} → No match")
diff --git a/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/types.py b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/types.py
new file mode 100644
index 000000000..29be9648c
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/types.py
@@ -0,0 +1,39 @@
+from collections.abc import Callable
+from enum import Enum, auto
+from typing import (
+ Any,
+ Literal,
+ NotRequired,
+ TypeAlias,
+ TypedDict,
+)
+
+AudioFormat: TypeAlias = Literal["mp3", "opus", "aac", "flac", "wav", "pcm"]
+
+
+class ModelMode(Enum):
+ IMAGE_GENERATION = auto()
+ VIDEO_GENERATION = auto()
+ AUDIO_GENERATION = auto()
+ COMPREHENSION = auto()
+
+
+class Modality(Enum):
+ TEXT = auto() # maybe not useful. Prompt is always required
+ IMAGE = auto()
+ VIDEO = auto()
+ AUDIO = auto()
+
+
+class ModelModeSpec(TypedDict):
+ mode: ModelMode
+ input_modalities: list[Modality]
+
+
+PayloadPreprocessor: TypeAlias = Callable[[dict[str, Any]], dict[str, Any]]
+
+
+class Spec(TypedDict):
+ stages: list[Literal["diffusion", "autoregression"]]
+ modes: list[ModelModeSpec]
+ payload_preprocessor: NotRequired[PayloadPreprocessor]
diff --git a/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/validators.py b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/validators.py
new file mode 100644
index 000000000..f1af7b2e9
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/comfyui_vllm_omni/utils/validators.py
@@ -0,0 +1,84 @@
+from .logger import get_logger
+from .models import lookup_model_spec
+
+logger = get_logger(__name__)
+
+
+def validate_model_and_sampling_params_types(
+ model_name: str,
+ sampling_param_list: dict | list[dict] | None = None,
+):
+ # Check if model name exists
+ if not model_name:
+ raise ValueError("Model name must not be empty.")
+
+ # Skip if no spec or no sampling params
+ pipeline_spec, _ = lookup_model_spec(model_name)
+ if pipeline_spec is None:
+ logger.info("skipping sampling params check because spec is not found")
+ return
+ if sampling_param_list is None:
+ return
+
+ # Check the number of stages and their data types
+ stages = pipeline_spec["stages"]
+ if isinstance(sampling_param_list, list):
+ # Check that the lengths match
+ if len(stages) != len(sampling_param_list):
+ raise ValueError(
+ f"Sampling parameter list length {len(sampling_param_list)} does not match "
+ f"number of stages {len(stages)} for model {model_name}."
+ )
+ # Check that each stage's type match
+ for i, sp in enumerate(sampling_param_list):
+ if "type" not in sp:
+ raise RuntimeError("Internal error: unknown sampling parameter type")
+ if sp["type"] != stages[i]:
+ raise ValueError(
+ f"Sampling parameter type ({sp['type']}) does not match "
+ f"stage type ({stages[i]}) at index {i} for model {model_name}."
+ )
+ elif isinstance(sampling_param_list, dict):
+ if "type" not in sampling_param_list:
+ raise RuntimeError("Internal error: unknown sampling parameter type")
+ # Check that the provided single sampling param matches all stages
+ elif any(stage != sampling_param_list["type"] for stage in stages):
+ raise ValueError(
+ f"When passing a single sampling parameter node, all stages of the model must match "
+ f"the provided sampling parameter's type. "
+ f"However, the stages of model {model_name} are: {stages}. "
+ f"The provided sampling parameter is {sampling_param_list['type']}"
+ )
+
+
+def add_sampling_parameters_to_stage(
+ model_name: str,
+ sampling_param_list: dict | list[dict] | None,
+ stage_type: str,
+ /,
+ **params_to_add,
+) -> dict | list[dict]:
+ """
+ Given a model's name and the sampling parameter list to query this model,
+ add arbitrary additional parameters to the sampling parameters of all stages of the given type.
+ """
+ pipeline_spec, _ = lookup_model_spec(model_name)
+ if not pipeline_spec:
+ logger.warning(
+ f"Since the model {model_name} is not in our list, we cannot ensure if "
+ f"the fields ({tuple(params_to_add.keys())}) are added to the correct stage's sampling params. "
+ f"We will do it heuristically."
+ )
+ pipeline_spec = {"stages": ["diffusion"]}
+
+ stages = pipeline_spec["stages"]
+ if isinstance(sampling_param_list, dict):
+ sampling_param_list.update(params_to_add)
+ elif sampling_param_list is None:
+ sampling_param_list = params_to_add.copy()
+ else:
+ for i, stage in enumerate(stages):
+ if stage == stage_type:
+ sampling_param_list[i].update(params_to_add)
+
+ return sampling_param_list
diff --git a/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-comprehension.jpg b/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-comprehension.jpg
new file mode 100644
index 000000000..f2f6c8de1
Binary files /dev/null and b/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-comprehension.jpg differ
diff --git a/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-image-generation.jpg b/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-image-generation.jpg
new file mode 100644
index 000000000..5aec26e8c
Binary files /dev/null and b/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-image-generation.jpg differ
diff --git a/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-multi-stage.jpg b/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-multi-stage.jpg
new file mode 100644
index 000000000..54eb91b9e
Binary files /dev/null and b/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-multi-stage.jpg differ
diff --git a/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-tts.jpg b/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-tts.jpg
new file mode 100644
index 000000000..f446de2a0
Binary files /dev/null and b/apps/ComfyUI-vLLM-Omni/docs/images/comfyui-tts.jpg differ
diff --git a/apps/ComfyUI-vLLM-Omni/example_workflows/vLLM-Omni Annotated Example.json b/apps/ComfyUI-vLLM-Omni/example_workflows/vLLM-Omni Annotated Example.json
new file mode 100644
index 000000000..16657df0e
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/example_workflows/vLLM-Omni Annotated Example.json
@@ -0,0 +1 @@
+{"id":"1c99f525-0a37-45ba-a28a-7df7c3af66b4","revision":0,"last_node_id":12,"last_link_id":14,"nodes":[{"id":1,"type":"VLLMOmniComprehension","pos":[1191.2177053682556,144.66829928181377],"size":[400,268],"flags":{},"order":8,"mode":0,"inputs":[{"localized_name":"image","name":"image","shape":7,"type":"IMAGE","link":1},{"localized_name":"video","name":"video","shape":7,"type":"VIDEO","link":2},{"localized_name":"audio","name":"audio","shape":7,"type":"AUDIO","link":3},{"localized_name":"sampling_params","name":"sampling_params","shape":7,"type":"SAMPLING_PARAMS","link":14},{"localized_name":"url","name":"url","type":"STRING","widget":{"name":"url"},"link":null},{"localized_name":"model","name":"model","type":"STRING","widget":{"name":"model"},"link":null},{"localized_name":"prompt","name":"prompt","type":"STRING","widget":{"name":"prompt"},"link":null},{"localized_name":"output_text","name":"output_text","type":"BOOLEAN","widget":{"name":"output_text"},"link":null},{"localized_name":"output_audio","name":"output_audio","type":"BOOLEAN","widget":{"name":"output_audio"},"link":null},{"localized_name":"use_audio_in_video","name":"use_audio_in_video","type":"BOOLEAN","widget":{"name":"use_audio_in_video"},"link":null}],"outputs":[{"localized_name":"text_response","name":"text_response","type":"STRING","links":[8]},{"localized_name":"audio_response","name":"audio_response","type":"AUDIO","links":[9]}],"properties":{"Node name for S&R":"VLLMOmniComprehension"},"widgets_values":["http://localhost:8000/v1","Qwen/Qwen2.5-Omni-7B","",true,true,true]},{"id":3,"type":"LoadVideo","pos":[729.5984141255855,-198.631920454299],"size":[282.798828125,233.0743408203125],"flags":{},"order":0,"mode":0,"inputs":[{"localized_name":"file","name":"file","type":"COMBO","widget":{"name":"file"},"link":null},{"localized_name":"choose file to upload","name":"upload","type":"IMAGEUPLOAD","widget":{"name":"upload"},"link":null}],"outputs":[{"localized_name":"VIDEO","name":"VIDEO","type":"VIDEO","links":[2]}],"properties":{"Node name for S&R":"LoadVideo"},"widgets_values":["draw.mp4","image"]},{"id":4,"type":"LoadAudio","pos":[729.8037086965753,99.86963519703949],"size":[282.798828125,136],"flags":{},"order":1,"mode":0,"inputs":[{"localized_name":"audio","name":"audio","type":"COMBO","widget":{"name":"audio"},"link":null},{"localized_name":"audioUI","name":"audioUI","type":"AUDIO_UI","widget":{"name":"audioUI"},"link":null},{"localized_name":"choose file to upload","name":"upload","type":"AUDIOUPLOAD","widget":{"name":"upload"},"link":null}],"outputs":[{"localized_name":"AUDIO","name":"AUDIO","type":"AUDIO","links":[3]}],"properties":{"Node name for S&R":"LoadAudio"},"widgets_values":["Megan-Fox.mp3",null,null]},{"id":5,"type":"VLLMOmniARSampling","pos":[510.3517536642828,658.073751009259],"size":[270,178],"flags":{},"order":2,"mode":0,"inputs":[{"localized_name":"max_tokens","name":"max_tokens","type":"INT","widget":{"name":"max_tokens"},"link":null},{"localized_name":"temperature","name":"temperature","type":"FLOAT","widget":{"name":"temperature"},"link":null},{"localized_name":"top_p","name":"top_p","type":"FLOAT","widget":{"name":"top_p"},"link":null},{"localized_name":"repetition_penalty","name":"repetition_penalty","type":"FLOAT","widget":{"name":"repetition_penalty"},"link":null},{"localized_name":"seed","name":"seed","type":"INT","widget":{"name":"seed"},"link":null}],"outputs":[{"localized_name":"AR sampling params","name":"AR sampling params","type":"SAMPLING_PARAMS","links":[12]}],"properties":{"Node name for S&R":"VLLMOmniARSampling"},"widgets_values":[100,1,1,1,-1,"randomize"]},{"id":7,"type":"VLLMOmniARSampling","pos":[503.33235181647115,419.34158016181806],"size":[270,178],"flags":{},"order":3,"mode":0,"inputs":[{"localized_name":"max_tokens","name":"max_tokens","type":"INT","widget":{"name":"max_tokens"},"link":null},{"localized_name":"temperature","name":"temperature","type":"FLOAT","widget":{"name":"temperature"},"link":null},{"localized_name":"top_p","name":"top_p","type":"FLOAT","widget":{"name":"top_p"},"link":null},{"localized_name":"repetition_penalty","name":"repetition_penalty","type":"FLOAT","widget":{"name":"repetition_penalty"},"link":null},{"localized_name":"seed","name":"seed","type":"INT","widget":{"name":"seed"},"link":null}],"outputs":[{"localized_name":"AR sampling params","name":"AR sampling params","type":"SAMPLING_PARAMS","links":[5,13]}],"properties":{"Node name for S&R":"VLLMOmniARSampling"},"widgets_values":[100,1,1,1,-1,"randomize"]},{"id":8,"type":"VLLMOmniSamplingParamsList","pos":[820.6056617389042,426.38372037182273],"size":[263.066015625,66],"flags":{},"order":7,"mode":0,"inputs":[{"localized_name":"param1","name":"param1","type":"SAMPLING_PARAMS","link":5},{"localized_name":"param2","name":"param2","shape":7,"type":"SAMPLING_PARAMS","link":12},{"localized_name":"param3","name":"param3","shape":7,"type":"SAMPLING_PARAMS","link":13}],"outputs":[{"localized_name":"param list","name":"param list","type":"SAMPLING_PARAMS","links":[14]}],"properties":{"Node name for S&R":"VLLMOmniSamplingParamsList"},"widgets_values":[]},{"id":11,"type":"MarkdownNote","pos":[826.2328280438272,569.1890318701705],"size":[333.8220435590464,261.63596728060656],"flags":{},"order":4,"mode":0,"inputs":[],"outputs":[],"title":"Note: Sampling Parameters","properties":{},"widgets_values":["## Sampling Parameter Types\n\nThere are two types of sampling parameters: one for autoregression and one for diffusion.\nYou should ensure that you have chosen the correct type of sampling parameters for the model you request.\n\n## Stages & Shorthand\n\nFor multi-stage models such as Qwen Omni, you can either\n- connect one sampling parameter node, which is applied to all stages.\n- connect exactly the same number of sampling parameter nodes to a \"Multi-Stage Sampling Parameter List\" node, then connect this node to the primary request node.\n\nNote that this shorthand is intended to stay consistent with the [online serving API](https://docs.vllm.ai/projects/vllm-omni/en/latest/user_guide/examples/online_serving/qwen2_5_omni/)"],"color":"#432","bgcolor":"#000"},{"id":12,"type":"MarkdownNote","pos":[378.9866207003777,152.59550252215752],"size":[319.7287574247016,107.15904081906785],"flags":{},"order":6,"mode":0,"inputs":[],"outputs":[],"title":"Note: Input","properties":{},"widgets_values":["Note that not all models support every modality as input. For example, `ByteDance-Seed/BAGEL-7B-MoT` in Multimodality Comprehension mode only support text and image input.\n\nYou should ensure that the input are supported by the model. You can check the corresponding [online serving documentation](https://docs.vllm.ai/projects/vllm-omni/en/latest/user_guide/examples/online_serving/bagel/) for confirmation."],"color":"#432","bgcolor":"#000"},{"id":2,"type":"LoadImage","pos":[394.4674804308822,-207.6987397548834],"size":[282.798828125,314],"flags":{},"order":5,"mode":0,"inputs":[{"localized_name":"image","name":"image","type":"COMBO","widget":{"name":"image"},"link":null},{"localized_name":"choose file to upload","name":"upload","type":"IMAGEUPLOAD","widget":{"name":"upload"},"link":null}],"outputs":[{"localized_name":"IMAGE","name":"IMAGE","type":"IMAGE","links":[1]},{"localized_name":"MASK","name":"MASK","type":"MASK","links":null}],"properties":{"Node name for S&R":"LoadImage"},"widgets_values":["example.png","image"]},{"id":10,"type":"PreviewAudio","pos":[1664.548345556043,297.5921292054054],"size":[270,88],"flags":{},"order":10,"mode":0,"inputs":[{"localized_name":"audio","name":"audio","type":"AUDIO","link":9},{"localized_name":"audioUI","name":"audioUI","type":"AUDIO_UI","widget":{"name":"audioUI"},"link":null}],"outputs":[],"properties":{"Node name for S&R":"PreviewAudio"},"widgets_values":[]},{"id":9,"type":"ShowText|pysssss","pos":[1649.2506875091847,66.22823888292349],"size":[318.7188464232943,173.38502269972975],"flags":{},"order":9,"mode":0,"inputs":[{"localized_name":"text","name":"text","type":"STRING","link":8}],"outputs":[{"localized_name":"STRING","name":"STRING","shape":6,"type":"STRING","links":null}],"properties":{"Node name for S&R":"ShowText|pysssss"},"widgets_values":[]}],"links":[[1,2,0,1,0,"IMAGE"],[2,3,0,1,1,"VIDEO"],[3,4,0,1,2,"AUDIO"],[5,7,0,8,0,"SAMPLING_PARAMS"],[8,1,0,9,0,"STRING"],[9,1,1,10,0,"AUDIO"],[12,5,0,8,1,"SAMPLING_PARAMS"],[13,7,0,8,2,"SAMPLING_PARAMS"],[14,8,0,1,3,"SAMPLING_PARAMS"]],"groups":[{"id":1,"title":"Sampling Parameters","bounding":[480.1649301181556,341.08402513937995,692.4113568972277,510.48648853403665],"color":"#3f789e","font_size":24,"flags":{}},{"id":2,"title":"Input","bounding":[344.2364817813528,-287.5850484183313,704.8832238768634,559.5124009832894],"color":"#3f789e","font_size":24,"flags":{}}],"config":{},"extra":{"workflowRendererVersion":"LG","ds":{"scale":0.9478575057427204,"offset":[33.81037136029557,307.1974296197726]}},"version":0.4}
diff --git a/apps/ComfyUI-vLLM-Omni/example_workflows/vLLM-Omni Image Generation.json b/apps/ComfyUI-vLLM-Omni/example_workflows/vLLM-Omni Image Generation.json
new file mode 100644
index 000000000..d1495bc94
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/example_workflows/vLLM-Omni Image Generation.json
@@ -0,0 +1 @@
+{"id":"91f75acc-8040-40f6-865a-2e8a7cfd6672","revision":0,"last_node_id":11,"last_link_id":23,"nodes":[{"id":3,"type":"PreviewImage","pos":[1281.8455167767304,-69.02638461454333],"size":[305.6628685610174,307.0336884172169],"flags":{},"order":4,"mode":0,"inputs":[{"localized_name":"images","name":"images","type":"IMAGE","link":22}],"outputs":[],"properties":{"Node name for S&R":"PreviewImage"},"widgets_values":[]},{"id":11,"type":"VLLMOmniGenerateImage","pos":[816.0962515873642,-137.51112584854445],"size":[400,278],"flags":{},"order":3,"mode":0,"inputs":[{"localized_name":"image","name":"image","shape":7,"type":"IMAGE","link":21},{"localized_name":"mask","name":"mask","shape":7,"type":"MASK","link":null},{"localized_name":"sampling_params","name":"sampling_params","shape":7,"type":"SAMPLING_PARAMS","link":23},{"localized_name":"url","name":"url","type":"STRING","widget":{"name":"url"},"link":null},{"localized_name":"model","name":"model","type":"STRING","widget":{"name":"model"},"link":null},{"localized_name":"prompt","name":"prompt","type":"STRING","widget":{"name":"prompt"},"link":null},{"localized_name":"negative_prompt","name":"negative_prompt","type":"STRING","widget":{"name":"negative_prompt"},"link":null},{"localized_name":"width","name":"width","type":"INT","widget":{"name":"width"},"link":null},{"localized_name":"height","name":"height","type":"INT","widget":{"name":"height"},"link":null}],"outputs":[{"localized_name":"image","name":"image","type":"IMAGE","links":[22]}],"properties":{"Node name for S&R":"VLLMOmniGenerateImage"},"widgets_values":["http://localhost:8000/v1","Qwen/Qwen-Image-Edit","Put this figure in a realistic mountain view","",512,512]},{"id":8,"type":"VLLMOmniDiffusionSampling","pos":[478.59266934006774,183.67711984955648],"size":[284.205078125,202],"flags":{},"order":0,"mode":0,"inputs":[{"localized_name":"n","name":"n","type":"INT","widget":{"name":"n"},"link":null},{"localized_name":"num_inference_steps","name":"num_inference_steps","type":"INT","widget":{"name":"num_inference_steps"},"link":null},{"localized_name":"guidance_scale","name":"guidance_scale","type":"FLOAT","widget":{"name":"guidance_scale"},"link":null},{"localized_name":"true_cfg_scale","name":"true_cfg_scale","type":"FLOAT","widget":{"name":"true_cfg_scale"},"link":null},{"localized_name":"vae_use_slicing","name":"vae_use_slicing","type":"BOOLEAN","widget":{"name":"vae_use_slicing"},"link":null},{"localized_name":"seed","name":"seed","type":"INT","widget":{"name":"seed"},"link":null}],"outputs":[{"localized_name":"diffusion sampling params","name":"diffusion sampling params","type":"SAMPLING_PARAMS","links":[23]}],"properties":{"Node name for S&R":"VLLMOmniDiffusionSampling"},"widgets_values":[4,50,1,1,false,42,"fixed"]},{"id":10,"type":"MarkdownNote","pos":[227.99306819575278,-231.24143306069843],"size":[240.3326478922474,136.3505820791881],"flags":{},"order":2,"mode":0,"inputs":[],"outputs":[],"title":"Note: Task and Input","properties":{},"widgets_values":["vLLM-Omni nodes are categorized based on the output modality. The \"Generate Image\" node supports both text-to-image generation or image-to-image generation (a.k.a. image editing). The node will route to the correct endpoint depending on whether an input image is present or not."],"color":"#432","bgcolor":"#000"},{"id":4,"type":"LoadImage","pos":[496.31859627609606,-229.71277089860084],"size":[270,314],"flags":{},"order":1,"mode":0,"inputs":[{"localized_name":"image","name":"image","type":"COMBO","widget":{"name":"image"},"link":null},{"localized_name":"choose file to upload","name":"upload","type":"IMAGEUPLOAD","widget":{"name":"upload"},"link":null}],"outputs":[{"localized_name":"IMAGE","name":"IMAGE","type":"IMAGE","links":[21]},{"localized_name":"MASK","name":"MASK","type":"MASK","links":null}],"properties":{"Node name for S&R":"LoadImage"},"widgets_values":["example.png","image"]}],"links":[[21,4,0,11,0,"IMAGE"],[22,11,0,3,0,"IMAGE"],[23,8,0,11,2,"SAMPLING_PARAMS"]],"groups":[{"id":1,"title":"Input","bounding":[213.1706010087147,-313.20095750667554,560.8246471437027,407.4246532472182],"color":"#3f789e","font_size":24,"flags":{}}],"config":{},"extra":{"workflowRendererVersion":"LG","ds":{"scale":1.1469075819486894,"offset":[276.8427259980847,549.4885226647582]}},"version":0.4}
diff --git a/apps/ComfyUI-vLLM-Omni/example_workflows/vLLM-Omni TTS.json b/apps/ComfyUI-vLLM-Omni/example_workflows/vLLM-Omni TTS.json
new file mode 100644
index 000000000..761e8d147
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/example_workflows/vLLM-Omni TTS.json
@@ -0,0 +1 @@
+{"id":"c0a11241-f0e6-4f5c-8488-b3d344a9df3d","revision":0,"last_node_id":7,"last_link_id":3,"nodes":[{"id":4,"type":"PreviewAudio","pos":[690.1759063763212,226.76444957981545],"size":[270,88],"flags":{},"order":5,"mode":0,"inputs":[{"localized_name":"audio","name":"audio","type":"AUDIO","link":2},{"localized_name":"audioUI","name":"audioUI","type":"AUDIO_UI","widget":{"name":"audioUI"},"link":null}],"outputs":[],"properties":{"Node name for S&R":"PreviewAudio"},"widgets_values":[]},{"id":5,"type":"LoadAudio","pos":[-83.61093919682321,103.80510898465587],"size":[282.798828125,136],"flags":{},"order":0,"mode":0,"inputs":[{"localized_name":"audio","name":"audio","type":"COMBO","widget":{"name":"audio"},"link":null},{"localized_name":"audioUI","name":"audioUI","type":"AUDIO_UI","widget":{"name":"audioUI"},"link":null},{"localized_name":"choose file to upload","name":"upload","type":"AUDIOUPLOAD","widget":{"name":"upload"},"link":null}],"outputs":[{"localized_name":"AUDIO","name":"AUDIO","type":"AUDIO","links":[3]}],"properties":{"Node name for S&R":"LoadAudio"},"widgets_values":["Megan-Fox.mp3",null,null]},{"id":3,"type":"VLLMOmniVoiceClone","pos":[248.63466280064262,168.13112893706375],"size":[400,306],"flags":{},"order":4,"mode":0,"inputs":[{"localized_name":"ref_audio","name":"ref_audio","type":"AUDIO","link":3},{"localized_name":"model_specific_params","name":"model_specific_params","shape":7,"type":"TTS_PARAMS","link":1},{"localized_name":"url","name":"url","type":"STRING","widget":{"name":"url"},"link":null},{"localized_name":"model","name":"model","type":"STRING","widget":{"name":"model"},"link":null},{"localized_name":"input","name":"input","type":"STRING","widget":{"name":"input"},"link":null},{"localized_name":"voice","name":"voice","type":"STRING","widget":{"name":"voice"},"link":null},{"localized_name":"response_format","name":"response_format","type":"COMBO","widget":{"name":"response_format"},"link":null},{"localized_name":"speed","name":"speed","type":"FLOAT","widget":{"name":"speed"},"link":null},{"localized_name":"ref_text","name":"ref_text","type":"STRING","widget":{"name":"ref_text"},"link":null},{"localized_name":"x_vector_only_mode","name":"x_vector_only_mode","type":"BOOLEAN","widget":{"name":"x_vector_only_mode"},"link":null}],"outputs":[{"localized_name":"audio","name":"audio","type":"AUDIO","links":[2]}],"properties":{"Node name for S&R":"VLLMOmniVoiceClone"},"widgets_values":["http://localhost:8000/v1","Qwen/Qwen3-TTS-12Hz-1.7B-Base","Someone just spilled a cup of coffee on my jacket this morning in the subway. Now I have to wear this stained jacket for a whole day!","","mp3",1,"",true]},{"id":6,"type":"MarkdownNote","pos":[255.52667408769662,27.26842775454861],"size":[381.58204108637847,88],"flags":{},"order":2,"mode":0,"inputs":[],"outputs":[],"title":"Note: TTS Nodes","properties":{},"widgets_values":["Apart from the Voice Cloning node, there is also another TTS node for simple text-to-speech tasks (without extra inputs for reference audio)."],"color":"#432","bgcolor":"#000"},{"id":7,"type":"MarkdownNote","pos":[-196.99453003423977,598.3693693727904],"size":[382.4539509209102,88],"flags":{},"order":3,"mode":0,"inputs":[],"outputs":[],"title":"Note: Model-Specific Parameters","properties":{},"widgets_values":["TTS models often require some tailor-made parameters. If you need to customize these parameters, grab one that matches the model you are requesting from \"TTS Params\" subfolder."],"color":"#432","bgcolor":"#000"},{"id":2,"type":"VLLMOmniQwenTTSParams","pos":[-207.8925310560497,342.7942867650348],"size":[400,200],"flags":{},"order":1,"mode":0,"inputs":[{"localized_name":"task_type","name":"task_type","type":"COMBO","widget":{"name":"task_type"},"link":null},{"localized_name":"language","name":"language","type":"COMBO","widget":{"name":"language"},"link":null},{"localized_name":"instructions","name":"instructions","type":"STRING","widget":{"name":"instructions"},"link":null},{"localized_name":"max_new_tokens","name":"max_new_tokens","type":"INT","widget":{"name":"max_new_tokens"},"link":null}],"outputs":[{"localized_name":"Qwen TTS params","name":"Qwen TTS params","type":"TTS_PARAMS","links":[1]}],"properties":{"Node name for S&R":"VLLMOmniQwenTTSParams"},"widgets_values":["Base","Auto","Super angry",2048]}],"links":[[1,2,0,3,1,"TTS_PARAMS"],[2,3,0,4,0,"AUDIO"],[3,5,0,3,0,"AUDIO"]],"groups":[{"id":1,"title":"Model-Specific Parameters","bounding":[-228.38328407738007,264.42790274716276,443.9887293164586,439.6853171248897],"color":"#3f789e","font_size":24,"flags":{}}],"config":{},"extra":{"workflowRendererVersion":"LG","ds":{"scale":1.1469075819486911,"offset":[898.8819468322333,258.7179979718389]}},"version":0.4}
diff --git a/apps/ComfyUI-vLLM-Omni/web/main.js b/apps/ComfyUI-vLLM-Omni/web/main.js
new file mode 100644
index 000000000..da99b2539
--- /dev/null
+++ b/apps/ComfyUI-vLLM-Omni/web/main.js
@@ -0,0 +1,21 @@
+/**
+ * @file This file is intended to add dynamic fields to vLLM-Omni nodes
+ * based on widget (in-node form fields) and input (connection link) values and changes.
+ * However, this functionality is currently disabled/commented out.
+ * Because it introduces too much complexity,
+ * and it may even conflict with the current backend (Python) validation for unknown reasons (pending ComfyUI upstream fixes).
+ */
+
+import { app } from "../../scripts/app.js";
+app.registerExtension({
+ name: "vllm.vllm_omni",
+ async beforeRegisterNodeDef(nodeType, nodeData, app) {
+ if (!nodeData.name.startsWith("VLLMOmni")) {
+ return
+ }
+ // Stub frontend plugin for now
+ },
+ async setup() {
+ console.info("vLLM-Omni Setup complete!")
+ },
+})
diff --git a/docs/.nav.yml b/docs/.nav.yml
index 41754c9c7..adf7321d7 100644
--- a/docs/.nav.yml
+++ b/docs/.nav.yml
@@ -44,6 +44,7 @@ nav:
- Cache-DiT: user_guide/diffusion/cache_dit_acceleration.md
- Parallelism Acceleration: user_guide/diffusion/parallelism_acceleration.md
- CPU Offloading: user_guide/diffusion/cpu_offload_diffusion.md
+ - ComfyUI: features/comfyui.md
- Developer Guide:
- General:
- contributing/README.md
diff --git a/docs/features/comfyui.md b/docs/features/comfyui.md
new file mode 100644
index 000000000..3b7a9551e
--- /dev/null
+++ b/docs/features/comfyui.md
@@ -0,0 +1,70 @@
+# vLLM-Omni ComfyUI Integration
+
+vLLM-Omni offers a ComfyUI integration on top of its online serving API.
+It can send model inference requests to either a locally running vLLM-Omni service or a remote one.
+
+## Requirement
+
+- Python 3.12 or above
+- [ComfyUI installed](https://docs.comfy.org/installation/system_requirements)
+- [vLLM-Omni installed](https://docs.vllm.ai/projects/vllm-omni/en/latest/getting_started/installation/) on either the same device or another device discoverable via the internet.
+- No need to install additional packages apart from those already required by ComfyUI.
+
+!!! tip
+ If you run both ComfyUI and vLLM-Omni on the same device, you can create separate virtual environments and use different Python versions for them.
+
+
+## Installation
+
+Copy the `apps/ComfyUI-vLLM-Omni` folder to the `custom_nodes` subfolder of your ComfyUI installation. Your directory should look like `ComfyUI/custom_nodes/ComfyUI-vLLM-Omni`.
+
+If you are running ComfyUI during copying, you should restart ComfyUI to load this extension.
+
+!!! tip
+ You can use utility websites such as https://download-directory.github.io/ to download a subdirectory of a repo. Also checkout community discussions (e.g., https://stackoverflow.com/questions/7106012/download-a-single-folder-or-directory-from-a-github-repository) for more info.
+
+On the device and virtual environment you run ComfyUI, launch ComfyUI with
+```bash
+cd ComfyUI
+
+# The regular way
+python main.py
+
+# If you are mainly using this node, launch it faster with
+python main.py --cpu
+```
+
+On the device and virtual environment you run vLLM-Omni, start a model service with
+```bash
+vllm serve The_Model_ID_to_Serve --omni --port 8000
+```
+
+Check **ComfyUI's sidebar -> Node Library**. There should be a new folder named **vLLM-Omni**.
+If no, check your shell running the ComfyUI process. There may be some error messages before the line `Import times for custom nodes:` and the line `To see the GUI go to: http://127.0.0.1:8188`.
+
+## Quickstart
+
+This extension offers the following nodes based on the output modalities:
+
+- **Generate Image** for text-to-image and image-to-image tasks
+- **Multimodality Comprehension** for multimodality-to-text and multimodality-to-audio tasks
+- **TTS** and **TTS Voice Clone** for TTS tasks
+
+This extension also offers example workflows (at **ComfyUI sidebar -> Templates -> vLLM-Omni**)
+
+!!! info
+ The node UI and feature designs are intended to match vLLM-Omni online serving interfaces. It cannot offer more than what the interfaces support.
+
+To build a simple workflow yourself,
+
+- Drag a generation node onto the canvas.
+- Depending on your need, grab built-in multimedia file loader nodes, such as **image->Load Image**, **image->video->Load Video**, **audio->Load Audio**
+- Depending on your need, grab built-in multimedia file preview nodes, such as **image->Preview Image**, **image->video->Save Video**, **audio->Preview Audio**. For text output, you can install [ComfyUI-Custom-Scripts plugin](https://github.com/pythongosssss/ComfyUI-Custom-Scripts/) and grab its **utils->Show Text 🐍** node.
+- If you want to tune sampling parameters, grab corresponding nodes from **vLLM-Omni-> Sampling Params**.
+ - For multi-stage models, you can connect multiple **AR Sampling Params** and **Diffusion Sampling Params** nodes to a **Multi-Stage Sampling Params List** node, and connect this node to the generation node.
+ - For some multi-stage models like BAGEL, [only one stage's sampling parameters are exposed and tunable via vLLM-Omni's online serving API](https://docs.vllm.ai/projects/vllm-omni/en/latest/user_guide/examples/online_serving/bagel/). Thus, these models are treated as single-stage ones. Please check the vLLM-Omni documentation on how to correctly set each model's sampling parameters.
+ - For multi-stage models where all stages are either autoregression or diffusion, you can also connect only a single Sampling Params node, indicating that this set of sampling parameters will be used for all stages.
+
+## Examples & Screenshots
+
+Please read the [ComfyUI integration's README](https://github.com/vllm-project/vllm-omni/tree/main/apps/ComfyUI-vLLM-Omni) for more info.
 +
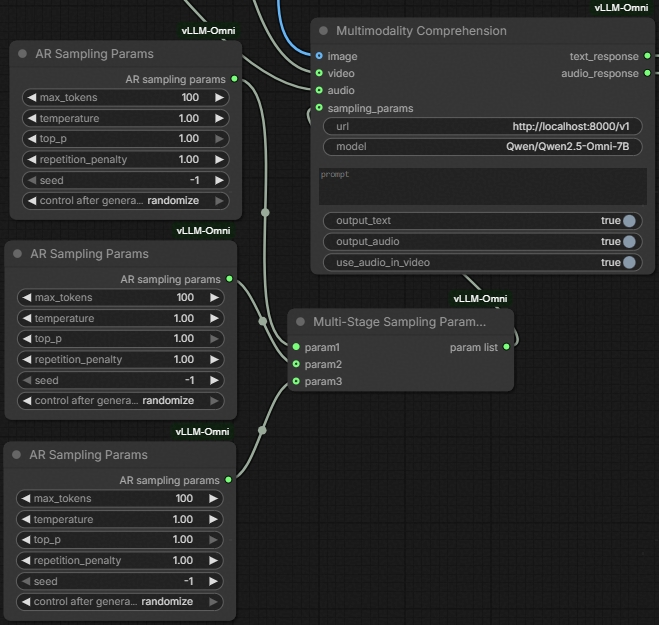 +
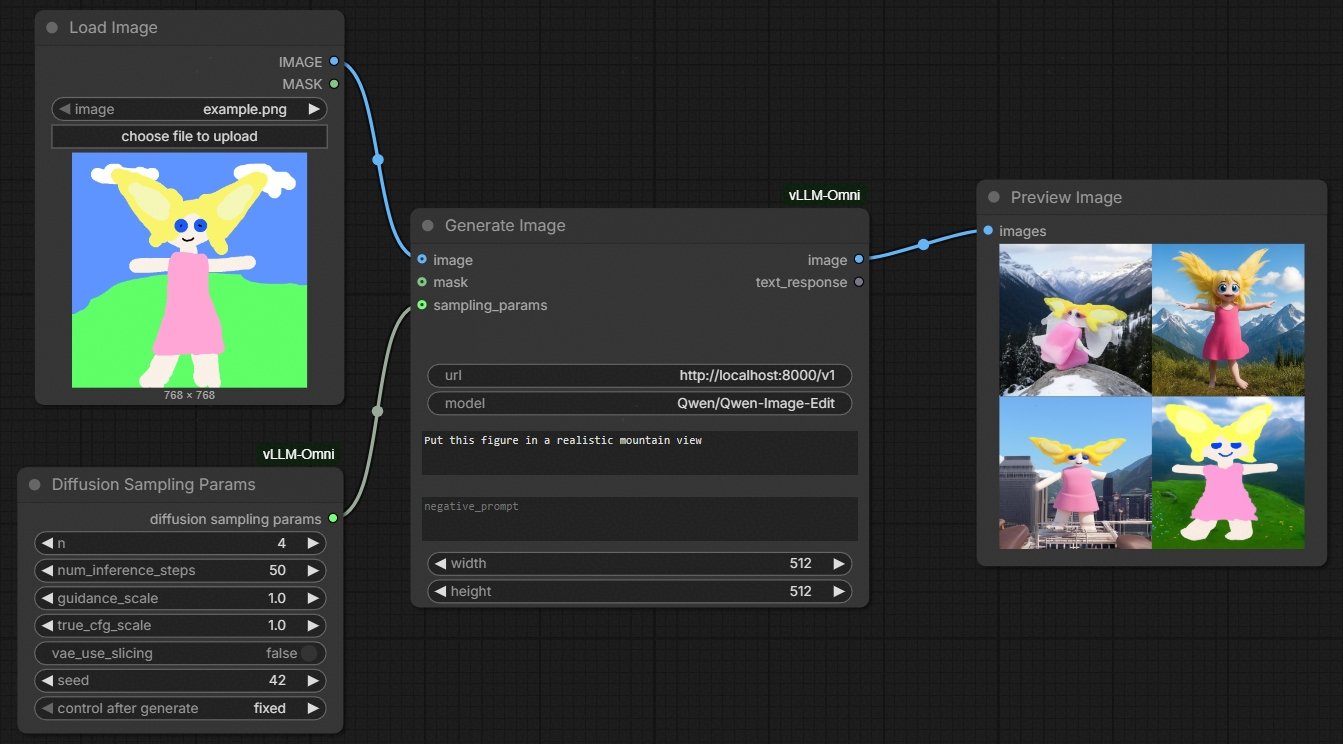 +
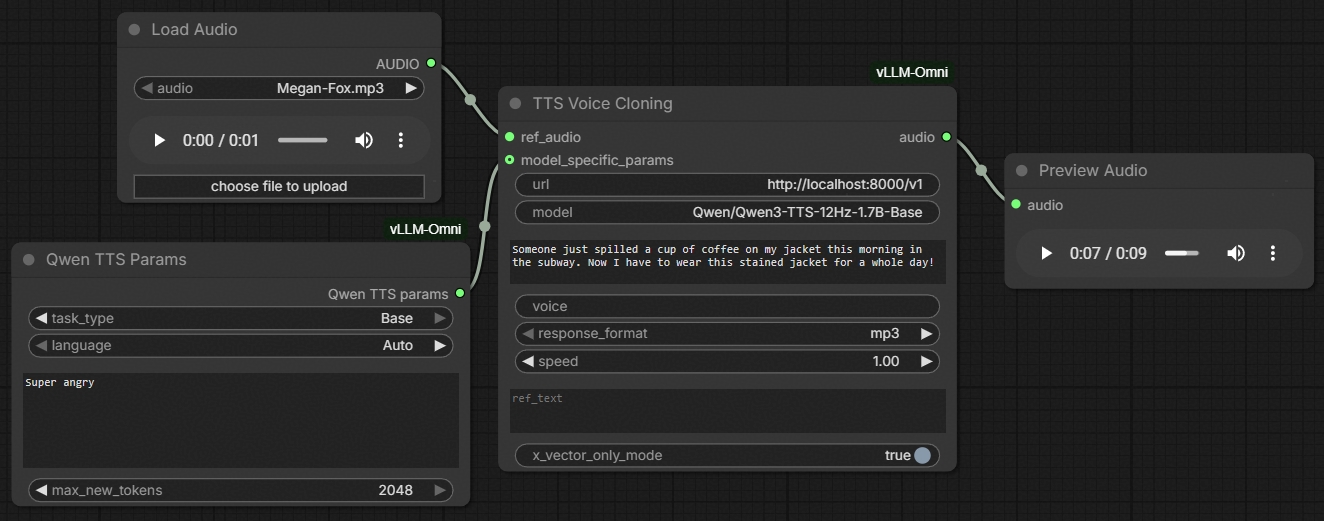 +