- [2026/08] [VeRL-Omni](https://github.com/verl-project/verl-omni) `v0.2.0` is released: faster diffusion RL powered by vLLM-Omni (request-level/step-wise batching with FA3), rebuilt Qwen3-Omni multimodal training (DPO & GSPO), plus LTX-2.3, Qwen-Image-Edit support and more. See the [release notes](https://github.com/verl-project/verl-omni/releases/tag/v0.2.0).
- [2026/08] We released [0.26.0](https://github.com/vllm-project/vllm-omni/releases/tag/v0.26.0) - aligned with the vLLM 0.26 release line, featuring [MiniMax H3](recipes/MiniMaxAI/MiniMax-H3.md) joint video/audio generation, an experimental full-duplex realtime runtime for [MiniCPM-o 4.5](recipes/OpenBMB/MiniCPM-o-4_5.md), distributed layerwise diffusion offload, and broader model, hardware, streaming, TTS, and quantization support.
- [2026/07] We released [0.24.0](https://github.com/vllm-project/vllm-omni/releases/tag/v0.24.0) - aligned with the vLLM 0.24 release line, expanding production-ready coverage across TTS, speech, diffusion, image/video generation, and robot-policy serving, with major Omni stage runtime refactoring, diffusion request-level batching, async output materialization, quantization/cache/memory improvements, and broad CUDA/ROCm/XPU/NPU support.
- [2026/06] Starting with [0.14.0](https://github.com/vllm-project/vllm-omni/releases/tag/v0.14.0), vLLM-Omni publishes a stable release aligned with every even-numbered upstream vLLM minor version. [0.16.0](https://github.com/vllm-project/vllm-omni/releases/tag/v0.16.0), [0.18.0](https://github.com/vllm-project/vllm-omni/releases/tag/v0.18.0), [0.20.0](https://github.com/vllm-project/vllm-omni/releases/tag/v0.20.0), and [0.22.0](https://github.com/vllm-project/vllm-omni/releases/tag/v0.22.0) continued this cadence, expanding omni and world-model support with [NVIDIA Cosmos3](recipes/cosmos3/Cosmos3-Nano.md) and DreamZero, adding models such as MiniCPM-o 4.5, MOSS-TTS, and Lance, and advancing TTS, diffusion, distributed execution, quantization, RL integration through [VeRL-Omni](https://github.com/verl-project/verl-omni), and CUDA/ROCm/MUSA/NPU/XPU coverage.
- [2025/11] vLLM community officially released [vllm-project/vllm-omni](https://github.com/vllm-project/vllm-omni) in order to support omni-modality models serving.
[vLLM](https://github.com/vllm-project/vllm) was originally designed to support large language models for text-based autoregressive generation tasks. vLLM-Omni is a framework that extends its support for omni-modality model inference and serving:
Feel free to ask questions, provide feedbacks and discuss with fellow users of vLLM-Omni in `#sig-omni` slack channel at [slack.vllm.ai](https://slack.vllm.ai) or vLLM user forum at [discuss.vllm.ai](https://discuss.vllm.ai).
[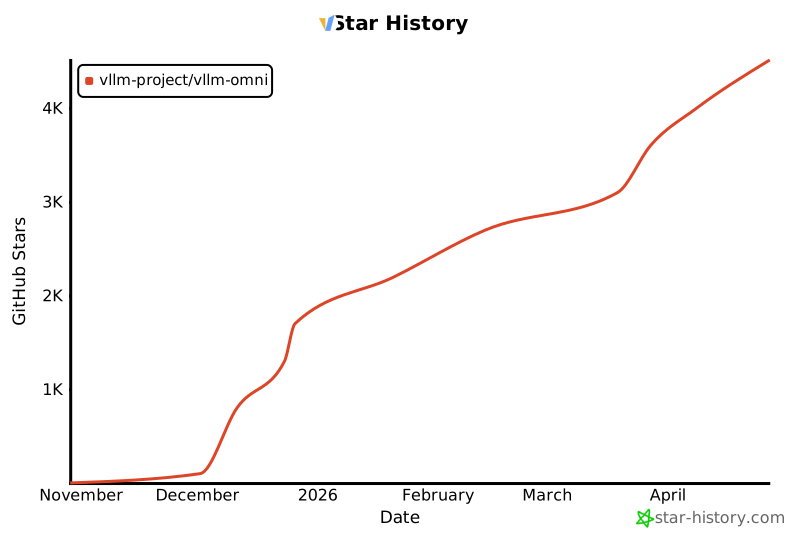](https://www.star-history.com/#vllm-project/vllm-omni&type=date&legend=top-left)
