2025-11-24 14:28:25 +08:00
<p align="center">
<picture>
2025-12-01 09:37:29 -08:00
<source media="(prefers-color-scheme: dark)" src="https://raw.githubusercontent.com/vllm-project/vllm-omni/refs/heads/main/docs/source/logos/vllm-omni-logo.png">
<img alt="vllm-omni" src="https://raw.githubusercontent.com/vllm-project/vllm-omni/refs/heads/main/docs/source/logos/vllm-omni-logo.png" width=55%>
2025-11-24 14:28:25 +08:00
</picture>
</p>
<h3 align="center">
Easy, fast, and cheap omni-modality model serving for everyone
</h3>
2025-09-11 14:32:51 +08:00
2025-11-24 14:28:25 +08:00
<p align="center">
2026-01-15 22:22:16 +08:00
| <a href="https://vllm-omni.readthedocs.io/en/latest/"><b>Documentation</b></a> | <a href="https://discuss.vllm.ai"><b>User Forum</b></a> | <a href="https://slack.vllm.ai"><b>Developer Slack</b></a> | <a href="docs/assets/WeChat.jpg"><b>WeChat</b></a> |
2025-11-24 14:28:25 +08:00
</p>
2025-09-16 16:17:10 +08:00
2025-11-24 14:28:25 +08:00
---
2025-09-16 16:17:10 +08:00
2025-11-24 14:28:25 +08:00
*Latest News* 🔥
2026-01-09 13:30:17 +08:00
- [2026/01] We released [0.12.0rc1 ](https://github.com/vllm-project/vllm-omni/releases/tag/v0.12.0rc1 ) - a major RC milestone focused on maturing the diffusion stack, strengthening OpenAI-compatible serving, expanding omni-model coverage, and improving stability across platforms (GPU/NPU/ROCm), please check our latest [design ](https://docs.google.com/presentation/d/1qv4qMW1rKAqDREMXiUDLIgqqHQe7TDPj/edit?usp=sharing&ouid=110473603432222024453&rtpof=true&sd=true ).
2025-11-24 14:28:25 +08:00
- [2025/11] vLLM community officially released [vllm-project/vllm-omni ](https://github.com/vllm-project/vllm-omni ) in order to support omni-modality models serving.
2025-09-16 16:17:10 +08:00
2025-11-24 14:28:25 +08:00
---
2025-09-16 16:17:10 +08:00
2025-11-24 14:28:25 +08:00
## About
2025-09-16 16:17:10 +08:00
2025-11-29 04:42:39 -08:00
[vLLM ](https://github.com/vllm-project/vllm ) was originally designed to support large language models for text-based autoregressive generation tasks. vLLM-Omni is a framework that extends its support for omni-modality model inference and serving:
2025-09-16 16:17:10 +08:00
2025-11-24 14:28:25 +08:00
- **Omni-modality**: Text, image, video, and audio data processing
- **Non-autoregressive Architectures**: extend the AR support of vLLM to Diffusion Transformers (DiT) and other parallel generation models
- **Heterogeneous outputs**: from traditional text generation to multimodal outputs
2025-09-16 16:17:10 +08:00
2025-11-24 14:28:25 +08:00
<p align="center">
<picture>
2025-12-01 09:37:29 -08:00
<img alt="vllm-omni" src="https://raw.githubusercontent.com/vllm-project/vllm-omni/refs/heads/main/docs/source/architecture/omni-modality-model-architecture.png" width=55%>
2025-11-24 14:28:25 +08:00
</picture>
</p>
2025-09-16 16:17:10 +08:00
2025-11-29 04:42:39 -08:00
vLLM-Omni is fast with:
2025-09-16 16:17:10 +08:00
2025-11-29 04:42:39 -08:00
- State-of-the-art AR support by leveraging efficient KV cache management from vLLM
- Pipelined stage execution overlapping for high throughput performance
- Fully disaggregation based on OmniConnector and dynamic resource allocation across stages
2025-09-16 16:17:10 +08:00
2025-11-29 04:42:39 -08:00
vLLM-Omni is flexible and easy to use with:
2025-09-16 16:17:10 +08:00
2025-11-29 04:42:39 -08:00
- Heterogeneous pipeline abstraction to manage complex model workflows
2025-11-24 14:28:25 +08:00
- Seamless integration with popular Hugging Face models
- Tensor, pipeline, data and expert parallelism support for distributed inference
- Streaming outputs
- OpenAI-compatible API server
2025-09-16 16:17:10 +08:00
2025-11-29 04:42:39 -08:00
vLLM-Omni seamlessly supports most popular open-source models on HuggingFace, including:
2025-11-24 14:28:25 +08:00
2025-11-29 04:42:39 -08:00
- Omni-modality models (e.g. Qwen-Omni)
- Multi-modality generation models (e.g. Qwen-Image)
2025-11-24 14:28:25 +08:00
## Getting Started
2025-11-28 11:03:52 +08:00
Visit our [documentation ](https://vllm-omni.readthedocs.io/en/latest/ ) to learn more.
2025-11-24 14:28:25 +08:00
2025-11-28 11:03:52 +08:00
- [Installation ](https://vllm-omni.readthedocs.io/en/latest/getting_started/installation/ )
- [Quickstart ](https://vllm-omni.readthedocs.io/en/latest/getting_started/quickstart/ )
- [List of Supported Models ](https://vllm-omni.readthedocs.io/en/latest/models/supported_models/ )
2025-09-26 15:47:55 +08:00
2025-11-24 14:28:25 +08:00
## Contributing
2025-09-26 15:47:55 +08:00
2025-11-24 14:28:25 +08:00
We welcome and value any contributions and collaborations.
2025-11-29 04:42:39 -08:00
Please check out [Contributing to vLLM-Omni ](https://vllm-omni.readthedocs.io/en/latest/contributing/ ) for how to get involved.
2025-11-24 14:28:25 +08:00
2025-12-01 00:25:44 -08:00
## Join the Community
Feel free to ask questions, provide feedbacks and discuss with fellow users of vLLM-Omni in `#sig-omni` slack channel at [slack.vllm.ai ](https://slack.vllm.ai ) or vLLM user forum at [discuss.vllm.ai ](https://discuss.vllm.ai ).
2025-11-24 14:28:25 +08:00
2026-01-15 22:22:16 +08:00
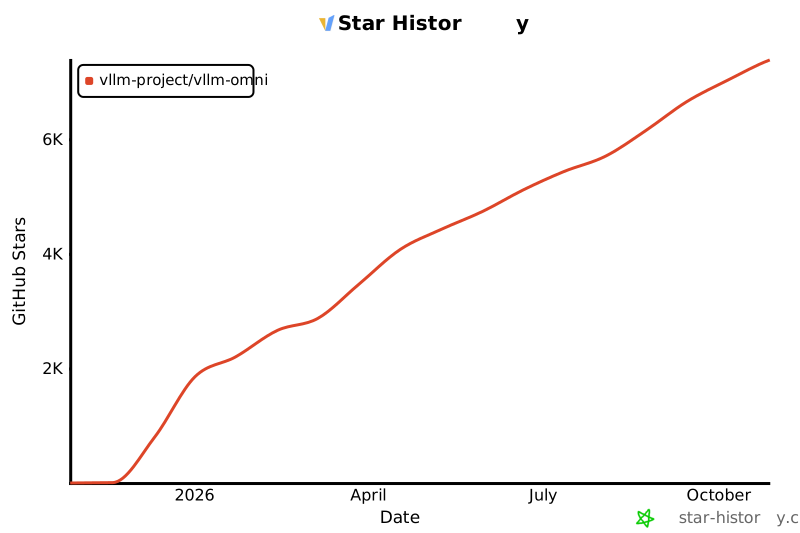
## Star History
[](https://www.star-history.com/#vllm -project/vllm-omni&type=date&legend=top-left)
2025-11-24 14:28:25 +08:00
## License
Apache License 2.0, as found in the [LICENSE ](./LICENSE ) file.
